build(ariadne): vendor serde crates
This commit was merged in pull request #15.
This commit is contained in:

100
Cargo.lock
generated
100
Cargo.lock
generated
@@ -5,7 +5,107 @@ version = 4
|
|||||||
[[package]]
|
[[package]]
|
||||||
name = "ariadne"
|
name = "ariadne"
|
||||||
version = "0.1.0"
|
version = "0.1.0"
|
||||||
|
dependencies = [
|
||||||
|
"serde",
|
||||||
|
"serde_json",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "itoa"
|
||||||
|
version = "1.0.18"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "8f42a60cbdf9a97f5d2305f08a87dc4e09308d1276d28c869c684d7777685682"
|
||||||
|
|
||||||
[[package]]
|
[[package]]
|
||||||
name = "machoke"
|
name = "machoke"
|
||||||
version = "0.1.0"
|
version = "0.1.0"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "memchr"
|
||||||
|
version = "2.8.3"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "cf8baf1c55e62ffcace7a9f06f4bd9cd3f0c4beb022d3b367256b91b87513d98"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "proc-macro2"
|
||||||
|
version = "1.0.107"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "985e7ec9bb745e6ce6535b544d84d6cd6f7ad8bd711c398938ae983b91a766d9"
|
||||||
|
dependencies = [
|
||||||
|
"unicode-ident",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "quote"
|
||||||
|
version = "1.0.47"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "1fbf4db142a473a8d80c26bbf18454ed458bf8d26c8219c331daecfdbd079001"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde"
|
||||||
|
version = "1.0.229"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "4148590afebada386688f18773da617792bf2ef03ffc1e4cbd2b1d45b023e0ba"
|
||||||
|
dependencies = [
|
||||||
|
"serde_core",
|
||||||
|
"serde_derive",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde_core"
|
||||||
|
version = "1.0.229"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "67dca2c9c51e58a4791a4b1ed58308b39c64224d349a935ab5039aa360942a48"
|
||||||
|
dependencies = [
|
||||||
|
"serde_derive",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde_derive"
|
||||||
|
version = "1.0.229"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e7a5d71263a5a7d47b41f6b3f06ba276f10cc18b0931f1799f710578e2309348"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
"quote",
|
||||||
|
"syn",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde_json"
|
||||||
|
version = "1.0.151"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "c841b55ecdae098c80dcae9cf767f6f8a0c2cdb3416bbef72181df4d0fe73f14"
|
||||||
|
dependencies = [
|
||||||
|
"itoa",
|
||||||
|
"memchr",
|
||||||
|
"serde",
|
||||||
|
"serde_core",
|
||||||
|
"zmij",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "syn"
|
||||||
|
version = "3.0.5"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "12df2e0110f65b775f769bb17ef989067a1d931b2eb822bd4346631eeada89f9"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
"quote",
|
||||||
|
"unicode-ident",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "unicode-ident"
|
||||||
|
version = "1.0.24"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e6e4313cd5fcd3dad5cafa179702e2b244f760991f45397d14d4ebf38247da75"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "zmij"
|
||||||
|
version = "1.0.23"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "29666d0abbfad1e3dc4dcf6144730dd3a3ab225bbbdac83319345b1b44ccfc1b"
|
||||||
|
|||||||
@@ -4,3 +4,5 @@ version = "0.1.0"
|
|||||||
edition = "2024"
|
edition = "2024"
|
||||||
|
|
||||||
[dependencies]
|
[dependencies]
|
||||||
|
serde = { version = "1.0", features = ["derive"] }
|
||||||
|
serde_json = "1.0"
|
||||||
|
|||||||
25
third_party/crates/BUILD.bazel
vendored
25
third_party/crates/BUILD.bazel
vendored
@@ -29,3 +29,28 @@ filegroup(
|
|||||||
allow_empty = True,
|
allow_empty = True,
|
||||||
),
|
),
|
||||||
)
|
)
|
||||||
|
|
||||||
|
# Workspace Member Dependencies
|
||||||
|
alias(
|
||||||
|
name = "serde-1.0.229",
|
||||||
|
actual = "//third_party/crates/serde-1.0.229:serde",
|
||||||
|
tags = ["manual"],
|
||||||
|
)
|
||||||
|
|
||||||
|
alias(
|
||||||
|
name = "serde",
|
||||||
|
actual = "//third_party/crates/serde-1.0.229:serde",
|
||||||
|
tags = ["manual"],
|
||||||
|
)
|
||||||
|
|
||||||
|
alias(
|
||||||
|
name = "serde_json-1.0.151",
|
||||||
|
actual = "//third_party/crates/serde_json-1.0.151:serde_json",
|
||||||
|
tags = ["manual"],
|
||||||
|
)
|
||||||
|
|
||||||
|
alias(
|
||||||
|
name = "serde_json",
|
||||||
|
actual = "//third_party/crates/serde_json-1.0.151:serde_json",
|
||||||
|
tags = ["manual"],
|
||||||
|
)
|
||||||
|
|||||||
32
third_party/crates/crates.bzl
vendored
32
third_party/crates/crates.bzl
vendored
@@ -310,65 +310,96 @@ def aliases(
|
|||||||
###############################################################################
|
###############################################################################
|
||||||
|
|
||||||
_CRATE_EDITIONS = {
|
_CRATE_EDITIONS = {
|
||||||
|
"src/ariadne": "2024",
|
||||||
"src/machoke": "2024",
|
"src/machoke": "2024",
|
||||||
}
|
}
|
||||||
|
|
||||||
_NORMAL_DEPENDENCIES = {
|
_NORMAL_DEPENDENCIES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
_COMMON_CONDITION: {
|
||||||
|
"serde": Label("//third_party/crates/serde-1.0.229:serde"),
|
||||||
|
"serde_json": Label("//third_party/crates/serde_json-1.0.151:serde_json"),
|
||||||
|
},
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_NORMAL_ALIASES = {
|
_NORMAL_ALIASES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
_COMMON_CONDITION: {
|
||||||
|
},
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_NORMAL_DEV_DEPENDENCIES = {
|
_NORMAL_DEV_DEPENDENCIES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_NORMAL_DEV_ALIASES = {
|
_NORMAL_DEV_ALIASES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_PROC_MACRO_DEPENDENCIES = {
|
_PROC_MACRO_DEPENDENCIES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_PROC_MACRO_ALIASES = {
|
_PROC_MACRO_ALIASES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_PROC_MACRO_DEV_DEPENDENCIES = {
|
_PROC_MACRO_DEV_DEPENDENCIES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_PROC_MACRO_DEV_ALIASES = {
|
_PROC_MACRO_DEV_ALIASES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_BUILD_DEPENDENCIES = {
|
_BUILD_DEPENDENCIES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_BUILD_ALIASES = {
|
_BUILD_ALIASES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_BUILD_PROC_MACRO_DEPENDENCIES = {
|
_BUILD_PROC_MACRO_DEPENDENCIES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
|
|
||||||
_BUILD_PROC_MACRO_ALIASES = {
|
_BUILD_PROC_MACRO_ALIASES = {
|
||||||
|
"src/ariadne": {
|
||||||
|
},
|
||||||
"src/machoke": {
|
"src/machoke": {
|
||||||
},
|
},
|
||||||
}
|
}
|
||||||
@@ -390,6 +421,7 @@ _CONDITIONS = {
|
|||||||
"arm-unknown-linux-musleabi": ["@rules_rust//rust/platform:arm-unknown-linux-musleabi"],
|
"arm-unknown-linux-musleabi": ["@rules_rust//rust/platform:arm-unknown-linux-musleabi"],
|
||||||
"armv7-linux-androideabi": ["@rules_rust//rust/platform:armv7-linux-androideabi"],
|
"armv7-linux-androideabi": ["@rules_rust//rust/platform:armv7-linux-androideabi"],
|
||||||
"armv7-unknown-linux-gnueabi": ["@rules_rust//rust/platform:armv7-unknown-linux-gnueabi"],
|
"armv7-unknown-linux-gnueabi": ["@rules_rust//rust/platform:armv7-unknown-linux-gnueabi"],
|
||||||
|
"cfg(any())": [],
|
||||||
"i686-apple-darwin": ["@rules_rust//rust/platform:i686-apple-darwin"],
|
"i686-apple-darwin": ["@rules_rust//rust/platform:i686-apple-darwin"],
|
||||||
"i686-linux-android": ["@rules_rust//rust/platform:i686-linux-android"],
|
"i686-linux-android": ["@rules_rust//rust/platform:i686-linux-android"],
|
||||||
"i686-pc-windows-msvc": ["@rules_rust//rust/platform:i686-pc-windows-msvc"],
|
"i686-pc-windows-msvc": ["@rules_rust//rust/platform:i686-pc-windows-msvc"],
|
||||||
|
|||||||
1
third_party/crates/itoa-1.0.18/.cargo-checksum.json
vendored
Normal file
1
third_party/crates/itoa-1.0.18/.cargo-checksum.json
vendored
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"$comment":"This file only protects against accidental modifications. It is not a security mechanism and does not protect against malicious changes.","files":{".cargo_vcs_info.json":"e0165305f3b22a9ab4217a121f85379aa56c2675caa7afedc0a7468fc187600b",".github/FUNDING.yml":"b017158736b3c9751a2d21edfce7fe61c8954e2fced8da8dd3013c2f3e295bd9",".github/workflows/ci.yml":"89c4f60223daf03217ea7c1e8879135b11d2554bd1e57dd9eff5c02f1adc7909","Cargo.lock":"1cd64090b8e883963bb08d91e6968cc1e83ffdba4f4b2f47651ce9d351a8a947","Cargo.toml":"894c215e4e7e973b556b0e9627bf9b6a719a043fac9b5af9838660816392a09f","Cargo.toml.orig":"44ca1ae5d9b48743305b57f3367051289512037e7836b8b3693b68d48dec0483","LICENSE-APACHE":"62c7a1e35f56406896d7aa7ca52d0cc0d272ac022b5d2796e7d6905db8a3636a","LICENSE-MIT":"23f18e03dc49df91622fe2a76176497404e46ced8a715d9d2b67a7446571cca3","README.md":"1305bd79675db0194915d9bc91bd0b3cf9487bc1126e05bf46b48ab43edce44b","benches/bench.rs":"29a0bdb973848007d681e571c57487e21e1bfb7aed5980c2190dba354498b154","src/lib.rs":"e962338e1886873aa7c3399ec89aa5378ccbfed712b9690f043628079390a34f","src/u128_ext.rs":"498cc94f13805e551248fd82f47cc318f51d953a5002a9f8698858cd12fbae3c","tests/test.rs":"b22f8a8ed89edcbb4140b74f5edd7f2adf3cb0e363990dd6010cd6ebe0dc36b7"},"package":"8f42a60cbdf9a97f5d2305f08a87dc4e09308d1276d28c869c684d7777685682"}
|
||||||
6
third_party/crates/itoa-1.0.18/.cargo_vcs_info.json
vendored
Normal file
6
third_party/crates/itoa-1.0.18/.cargo_vcs_info.json
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
{
|
||||||
|
"git": {
|
||||||
|
"sha1": "af77385d0daf4d0e949e81f2588be2e44f69f086"
|
||||||
|
},
|
||||||
|
"path_in_vcs": ""
|
||||||
|
}
|
||||||
1
third_party/crates/itoa-1.0.18/.github/FUNDING.yml
vendored
Normal file
1
third_party/crates/itoa-1.0.18/.github/FUNDING.yml
vendored
Normal file
@@ -0,0 +1 @@
|
|||||||
|
github: dtolnay
|
||||||
126
third_party/crates/itoa-1.0.18/.github/workflows/ci.yml
vendored
Normal file
126
third_party/crates/itoa-1.0.18/.github/workflows/ci.yml
vendored
Normal file
@@ -0,0 +1,126 @@
|
|||||||
|
name: CI
|
||||||
|
|
||||||
|
on:
|
||||||
|
push:
|
||||||
|
pull_request:
|
||||||
|
workflow_dispatch:
|
||||||
|
schedule: [cron: "40 1 * * *"]
|
||||||
|
|
||||||
|
permissions:
|
||||||
|
contents: read
|
||||||
|
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: -Dwarnings
|
||||||
|
|
||||||
|
jobs:
|
||||||
|
pre_ci:
|
||||||
|
uses: dtolnay/.github/.github/workflows/pre_ci.yml@master
|
||||||
|
|
||||||
|
test:
|
||||||
|
name: Rust ${{matrix.rust}}
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
strategy:
|
||||||
|
fail-fast: false
|
||||||
|
matrix:
|
||||||
|
rust: [nightly, beta, stable, 1.86.0]
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@master
|
||||||
|
with:
|
||||||
|
toolchain: ${{matrix.rust}}
|
||||||
|
- name: Enable type layout randomization
|
||||||
|
run: echo RUSTFLAGS=${RUSTFLAGS}\ -Zrandomize-layout >> $GITHUB_ENV
|
||||||
|
if: matrix.rust == 'nightly'
|
||||||
|
- run: cargo build
|
||||||
|
- run: cargo test
|
||||||
|
- run: cargo test --release
|
||||||
|
- run: cargo build --no-default-features
|
||||||
|
- run: cargo test --tests --no-default-features
|
||||||
|
- run: cargo test --tests --no-default-features --release
|
||||||
|
- run: cargo build --tests --features no-panic --release
|
||||||
|
if: matrix.rust == 'nightly'
|
||||||
|
- run: cargo bench --no-run
|
||||||
|
if: matrix.rust == 'nightly'
|
||||||
|
- uses: actions/upload-artifact@v6
|
||||||
|
if: matrix.rust == 'nightly' && always()
|
||||||
|
with:
|
||||||
|
name: Cargo.lock
|
||||||
|
path: Cargo.lock
|
||||||
|
continue-on-error: true
|
||||||
|
|
||||||
|
msrv:
|
||||||
|
name: Rust 1.68.0
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@1.68
|
||||||
|
- run: cargo build
|
||||||
|
- run: cargo build --no-default-features
|
||||||
|
|
||||||
|
doc:
|
||||||
|
name: Documentation
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
env:
|
||||||
|
RUSTDOCFLAGS: -Dwarnings
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
- uses: dtolnay/install@cargo-docs-rs
|
||||||
|
- run: cargo docs-rs
|
||||||
|
|
||||||
|
miri:
|
||||||
|
name: Miri
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@miri
|
||||||
|
- run: cargo miri setup
|
||||||
|
- run: cargo miri test
|
||||||
|
env:
|
||||||
|
MIRIFLAGS: -Zmiri-strict-provenance
|
||||||
|
|
||||||
|
clippy:
|
||||||
|
name: Clippy
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
if: github.event_name != 'pull_request'
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@clippy
|
||||||
|
- run: cargo clippy --tests --benches -- -Dclippy::all -Dclippy::pedantic
|
||||||
|
|
||||||
|
fuzz:
|
||||||
|
name: Fuzz
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
- uses: dtolnay/install@cargo-fuzz
|
||||||
|
- run: cargo fuzz check
|
||||||
|
|
||||||
|
outdated:
|
||||||
|
name: Outdated
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
if: github.event_name != 'pull_request'
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v6
|
||||||
|
- uses: dtolnay/rust-toolchain@stable
|
||||||
|
- uses: dtolnay/install@cargo-outdated
|
||||||
|
- run: cargo outdated --workspace --exit-code 1
|
||||||
|
- run: cargo outdated --manifest-path fuzz/Cargo.toml --exit-code 1
|
||||||
110
third_party/crates/itoa-1.0.18/BUILD.bazel
vendored
Normal file
110
third_party/crates/itoa-1.0.18/BUILD.bazel
vendored
Normal file
@@ -0,0 +1,110 @@
|
|||||||
|
###############################################################################
|
||||||
|
# @generated
|
||||||
|
# DO NOT MODIFY: This file is auto-generated by a crate_universe tool. To
|
||||||
|
# regenerate this file, run the following:
|
||||||
|
#
|
||||||
|
# bazel run @@//third_party:vendor_crates
|
||||||
|
###############################################################################
|
||||||
|
|
||||||
|
load("@rules_rust//cargo:defs.bzl", "cargo_toml_env_vars")
|
||||||
|
load("@rules_rust//rust:defs.bzl", "rust_library")
|
||||||
|
|
||||||
|
package(default_visibility = ["//visibility:public"])
|
||||||
|
|
||||||
|
cargo_toml_env_vars(
|
||||||
|
name = "cargo_toml_env_vars",
|
||||||
|
src = "Cargo.toml",
|
||||||
|
)
|
||||||
|
|
||||||
|
rust_library(
|
||||||
|
name = "itoa",
|
||||||
|
srcs = glob(
|
||||||
|
include = ["**/*.rs"],
|
||||||
|
allow_empty = False,
|
||||||
|
),
|
||||||
|
compile_data = glob(
|
||||||
|
include = ["**"],
|
||||||
|
allow_empty = True,
|
||||||
|
exclude = [
|
||||||
|
"**/* *",
|
||||||
|
".tmp_git_root/**/*",
|
||||||
|
"BUILD",
|
||||||
|
"BUILD.bazel",
|
||||||
|
"WORKSPACE",
|
||||||
|
"WORKSPACE.bazel",
|
||||||
|
],
|
||||||
|
),
|
||||||
|
crate_root = "src/lib.rs",
|
||||||
|
edition = "2021",
|
||||||
|
rustc_env_files = [
|
||||||
|
":cargo_toml_env_vars",
|
||||||
|
],
|
||||||
|
rustc_flags = [
|
||||||
|
"--cap-lints=allow",
|
||||||
|
],
|
||||||
|
tags = [
|
||||||
|
"cargo-bazel",
|
||||||
|
"crate-name=itoa",
|
||||||
|
"manual",
|
||||||
|
"noclippy",
|
||||||
|
"norustfmt",
|
||||||
|
],
|
||||||
|
target_compatible_with = select({
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios-macabi": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios-sim": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-fuchsia": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-nixos-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-none": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-nto-qnx710": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-uefi": [],
|
||||||
|
"@rules_rust//rust/platform:arm-unknown-linux-gnueabi": [],
|
||||||
|
"@rules_rust//rust/platform:arm-unknown-linux-musleabi": [],
|
||||||
|
"@rules_rust//rust/platform:armv7-linux-androideabi": [],
|
||||||
|
"@rules_rust//rust/platform:armv7-unknown-linux-gnueabi": [],
|
||||||
|
"@rules_rust//rust/platform:i686-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:i686-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:i686-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:i686-unknown-freebsd": [],
|
||||||
|
"@rules_rust//rust/platform:i686-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:loongarch64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:mips-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:powerpc-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:riscv32imac-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:riscv32imc-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:riscv64gc-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:riscv64gc-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:s390x-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-netbsd": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-openbsd": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv6m-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7em-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7em-none-eabihf": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7m-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv8m.main-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv8m.main-none-eabihf": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-unknown-emscripten": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-unknown-unknown": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip1": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip1-threads": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip2": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-ios": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-ios-macabi": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-freebsd": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-fuchsia": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-nixos-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-none": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-uefi": [],
|
||||||
|
"//conditions:default": ["@platforms//:incompatible"],
|
||||||
|
}),
|
||||||
|
version = "1.0.18",
|
||||||
|
)
|
||||||
460
third_party/crates/itoa-1.0.18/Cargo.lock
generated
vendored
Normal file
460
third_party/crates/itoa-1.0.18/Cargo.lock
generated
vendored
Normal file
@@ -0,0 +1,460 @@
|
|||||||
|
# This file is automatically @generated by Cargo.
|
||||||
|
# It is not intended for manual editing.
|
||||||
|
version = 3
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "aho-corasick"
|
||||||
|
version = "1.1.4"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "ddd31a130427c27518df266943a5308ed92d4b226cc639f5a8f1002816174301"
|
||||||
|
dependencies = [
|
||||||
|
"memchr",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "alloca"
|
||||||
|
version = "0.4.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e5a7d05ea6aea7e9e64d25b9156ba2fee3fdd659e34e41063cd2fc7cd020d7f4"
|
||||||
|
dependencies = [
|
||||||
|
"cc",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "anes"
|
||||||
|
version = "0.1.6"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "4b46cbb362ab8752921c97e041f5e366ee6297bd428a31275b9fcf1e380f7299"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "anstyle"
|
||||||
|
version = "1.0.14"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "940b3a0ca603d1eade50a4846a2afffd5ef57a9feac2c0e2ec2e14f9ead76000"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "autocfg"
|
||||||
|
version = "1.5.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "c08606f8c3cbf4ce6ec8e28fb0014a2c086708fe954eaa885384a6165172e7e8"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "cast"
|
||||||
|
version = "0.3.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "37b2a672a2cb129a2e41c10b1224bb368f9f37a2b16b612598138befd7b37eb5"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "cc"
|
||||||
|
version = "1.2.57"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "7a0dd1ca384932ff3641c8718a02769f1698e7563dc6974ffd03346116310423"
|
||||||
|
dependencies = [
|
||||||
|
"find-msvc-tools",
|
||||||
|
"shlex",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "cfg-if"
|
||||||
|
version = "1.0.4"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "9330f8b2ff13f34540b44e946ef35111825727b38d33286ef986142615121801"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "ciborium"
|
||||||
|
version = "0.2.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "42e69ffd6f0917f5c029256a24d0161db17cea3997d185db0d35926308770f0e"
|
||||||
|
dependencies = [
|
||||||
|
"ciborium-io",
|
||||||
|
"ciborium-ll",
|
||||||
|
"serde",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "ciborium-io"
|
||||||
|
version = "0.2.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "05afea1e0a06c9be33d539b876f1ce3692f4afea2cb41f740e7743225ed1c757"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "ciborium-ll"
|
||||||
|
version = "0.2.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "57663b653d948a338bfb3eeba9bb2fd5fcfaecb9e199e87e1eda4d9e8b240fd9"
|
||||||
|
dependencies = [
|
||||||
|
"ciborium-io",
|
||||||
|
"half",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "clap"
|
||||||
|
version = "4.6.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "b193af5b67834b676abd72466a96c1024e6a6ad978a1f484bd90b85c94041351"
|
||||||
|
dependencies = [
|
||||||
|
"clap_builder",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "clap_builder"
|
||||||
|
version = "4.6.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "714a53001bf66416adb0e2ef5ac857140e7dc3a0c48fb28b2f10762fc4b5069f"
|
||||||
|
dependencies = [
|
||||||
|
"anstyle",
|
||||||
|
"clap_lex",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "clap_lex"
|
||||||
|
version = "1.1.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "c8d4a3bb8b1e0c1050499d1815f5ab16d04f0959b233085fb31653fbfc9d98f9"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "criterion"
|
||||||
|
version = "0.8.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "950046b2aa2492f9a536f5f4f9a3de7b9e2476e575e05bd6c333371add4d98f3"
|
||||||
|
dependencies = [
|
||||||
|
"alloca",
|
||||||
|
"anes",
|
||||||
|
"cast",
|
||||||
|
"ciborium",
|
||||||
|
"clap",
|
||||||
|
"criterion-plot",
|
||||||
|
"itertools",
|
||||||
|
"num-traits",
|
||||||
|
"oorandom",
|
||||||
|
"page_size",
|
||||||
|
"regex",
|
||||||
|
"serde",
|
||||||
|
"serde_json",
|
||||||
|
"tinytemplate",
|
||||||
|
"walkdir",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "criterion-plot"
|
||||||
|
version = "0.8.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "d8d80a2f4f5b554395e47b5d8305bc3d27813bacb73493eb1001e8f76dae29ea"
|
||||||
|
dependencies = [
|
||||||
|
"cast",
|
||||||
|
"itertools",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "crunchy"
|
||||||
|
version = "0.2.4"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "460fbee9c2c2f33933d720630a6a0bac33ba7053db5344fac858d4b8952d77d5"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "either"
|
||||||
|
version = "1.15.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "48c757948c5ede0e46177b7add2e67155f70e33c07fea8284df6576da70b3719"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "find-msvc-tools"
|
||||||
|
version = "0.1.9"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "5baebc0774151f905a1a2cc41989300b1e6fbb29aff0ceffa1064fdd3088d582"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "half"
|
||||||
|
version = "2.7.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "6ea2d84b969582b4b1864a92dc5d27cd2b77b622a8d79306834f1be5ba20d84b"
|
||||||
|
dependencies = [
|
||||||
|
"cfg-if",
|
||||||
|
"crunchy",
|
||||||
|
"zerocopy",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "itertools"
|
||||||
|
version = "0.13.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "413ee7dfc52ee1a4949ceeb7dbc8a33f2d6c088194d9f922fb8318faf1f01186"
|
||||||
|
dependencies = [
|
||||||
|
"either",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "itoa"
|
||||||
|
version = "1.0.17"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "92ecc6618181def0457392ccd0ee51198e065e016d1d527a7ac1b6dc7c1f09d2"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "itoa"
|
||||||
|
version = "1.0.18"
|
||||||
|
dependencies = [
|
||||||
|
"criterion",
|
||||||
|
"no-panic",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "libc"
|
||||||
|
version = "0.2.183"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "b5b646652bf6661599e1da8901b3b9522896f01e736bad5f723fe7a3a27f899d"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "memchr"
|
||||||
|
version = "2.8.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "f8ca58f447f06ed17d5fc4043ce1b10dd205e060fb3ce5b979b8ed8e59ff3f79"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "no-panic"
|
||||||
|
version = "0.1.36"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "f967505aabc8af5752d098c34146544a43684817cdba8f9725b292530cabbf53"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
"quote",
|
||||||
|
"syn",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "num-traits"
|
||||||
|
version = "0.2.19"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "071dfc062690e90b734c0b2273ce72ad0ffa95f0c74596bc250dcfd960262841"
|
||||||
|
dependencies = [
|
||||||
|
"autocfg",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "oorandom"
|
||||||
|
version = "11.1.5"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "d6790f58c7ff633d8771f42965289203411a5e5c68388703c06e14f24770b41e"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "page_size"
|
||||||
|
version = "0.6.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "30d5b2194ed13191c1999ae0704b7839fb18384fa22e49b57eeaa97d79ce40da"
|
||||||
|
dependencies = [
|
||||||
|
"libc",
|
||||||
|
"winapi",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "proc-macro2"
|
||||||
|
version = "1.0.106"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "8fd00f0bb2e90d81d1044c2b32617f68fcb9fa3bb7640c23e9c748e53fb30934"
|
||||||
|
dependencies = [
|
||||||
|
"unicode-ident",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "quote"
|
||||||
|
version = "1.0.45"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "41f2619966050689382d2b44f664f4bc593e129785a36d6ee376ddf37259b924"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "regex"
|
||||||
|
version = "1.12.3"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e10754a14b9137dd7b1e3e5b0493cc9171fdd105e0ab477f51b72e7f3ac0e276"
|
||||||
|
dependencies = [
|
||||||
|
"aho-corasick",
|
||||||
|
"memchr",
|
||||||
|
"regex-automata",
|
||||||
|
"regex-syntax",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "regex-automata"
|
||||||
|
version = "0.4.14"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "6e1dd4122fc1595e8162618945476892eefca7b88c52820e74af6262213cae8f"
|
||||||
|
dependencies = [
|
||||||
|
"aho-corasick",
|
||||||
|
"memchr",
|
||||||
|
"regex-syntax",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "regex-syntax"
|
||||||
|
version = "0.8.10"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "dc897dd8d9e8bd1ed8cdad82b5966c3e0ecae09fb1907d58efaa013543185d0a"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "same-file"
|
||||||
|
version = "1.0.6"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "93fc1dc3aaa9bfed95e02e6eadabb4baf7e3078b0bd1b4d7b6b0b68378900502"
|
||||||
|
dependencies = [
|
||||||
|
"winapi-util",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde"
|
||||||
|
version = "1.0.228"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "9a8e94ea7f378bd32cbbd37198a4a91436180c5bb472411e48b5ec2e2124ae9e"
|
||||||
|
dependencies = [
|
||||||
|
"serde_core",
|
||||||
|
"serde_derive",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde_core"
|
||||||
|
version = "1.0.228"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "41d385c7d4ca58e59fc732af25c3983b67ac852c1a25000afe1175de458b67ad"
|
||||||
|
dependencies = [
|
||||||
|
"serde_derive",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde_derive"
|
||||||
|
version = "1.0.228"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "d540f220d3187173da220f885ab66608367b6574e925011a9353e4badda91d79"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
"quote",
|
||||||
|
"syn",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "serde_json"
|
||||||
|
version = "1.0.149"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "83fc039473c5595ace860d8c4fafa220ff474b3fc6bfdb4293327f1a37e94d86"
|
||||||
|
dependencies = [
|
||||||
|
"itoa 1.0.17",
|
||||||
|
"memchr",
|
||||||
|
"serde",
|
||||||
|
"serde_core",
|
||||||
|
"zmij",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "shlex"
|
||||||
|
version = "1.3.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "0fda2ff0d084019ba4d7c6f371c95d8fd75ce3524c3cb8fb653a3023f6323e64"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "syn"
|
||||||
|
version = "2.0.117"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e665b8803e7b1d2a727f4023456bbbbe74da67099c585258af0ad9c5013b9b99"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
"quote",
|
||||||
|
"unicode-ident",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "tinytemplate"
|
||||||
|
version = "1.2.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "be4d6b5f19ff7664e8c98d03e2139cb510db9b0a60b55f8e8709b689d939b6bc"
|
||||||
|
dependencies = [
|
||||||
|
"serde",
|
||||||
|
"serde_json",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "unicode-ident"
|
||||||
|
version = "1.0.24"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e6e4313cd5fcd3dad5cafa179702e2b244f760991f45397d14d4ebf38247da75"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "walkdir"
|
||||||
|
version = "2.5.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "29790946404f91d9c5d06f9874efddea1dc06c5efe94541a7d6863108e3a5e4b"
|
||||||
|
dependencies = [
|
||||||
|
"same-file",
|
||||||
|
"winapi-util",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "winapi"
|
||||||
|
version = "0.3.9"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "5c839a674fcd7a98952e593242ea400abe93992746761e38641405d28b00f419"
|
||||||
|
dependencies = [
|
||||||
|
"winapi-i686-pc-windows-gnu",
|
||||||
|
"winapi-x86_64-pc-windows-gnu",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "winapi-i686-pc-windows-gnu"
|
||||||
|
version = "0.4.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "ac3b87c63620426dd9b991e5ce0329eff545bccbbb34f3be09ff6fb6ab51b7b6"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "winapi-util"
|
||||||
|
version = "0.1.11"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "c2a7b1c03c876122aa43f3020e6c3c3ee5c05081c9a00739faf7503aeba10d22"
|
||||||
|
dependencies = [
|
||||||
|
"windows-sys",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "winapi-x86_64-pc-windows-gnu"
|
||||||
|
version = "0.4.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "712e227841d057c1ee1cd2fb22fa7e5a5461ae8e48fa2ca79ec42cfc1931183f"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "windows-link"
|
||||||
|
version = "0.2.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "f0805222e57f7521d6a62e36fa9163bc891acd422f971defe97d64e70d0a4fe5"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "windows-sys"
|
||||||
|
version = "0.61.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "ae137229bcbd6cdf0f7b80a31df61766145077ddf49416a728b02cb3921ff3fc"
|
||||||
|
dependencies = [
|
||||||
|
"windows-link",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "zerocopy"
|
||||||
|
version = "0.8.47"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "efbb2a062be311f2ba113ce66f697a4dc589f85e78a4aea276200804cea0ed87"
|
||||||
|
dependencies = [
|
||||||
|
"zerocopy-derive",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "zerocopy-derive"
|
||||||
|
version = "0.8.47"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "0e8bc7269b54418e7aeeef514aa68f8690b8c0489a06b0136e5f57c4c5ccab89"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2",
|
||||||
|
"quote",
|
||||||
|
"syn",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "zmij"
|
||||||
|
version = "1.0.21"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "b8848ee67ecc8aedbaf3e4122217aff892639231befc6a1b58d29fff4c2cabaa"
|
||||||
66
third_party/crates/itoa-1.0.18/Cargo.toml
vendored
Normal file
66
third_party/crates/itoa-1.0.18/Cargo.toml
vendored
Normal file
@@ -0,0 +1,66 @@
|
|||||||
|
# THIS FILE IS AUTOMATICALLY GENERATED BY CARGO
|
||||||
|
#
|
||||||
|
# When uploading crates to the registry Cargo will automatically
|
||||||
|
# "normalize" Cargo.toml files for maximal compatibility
|
||||||
|
# with all versions of Cargo and also rewrite `path` dependencies
|
||||||
|
# to registry (e.g., crates.io) dependencies.
|
||||||
|
#
|
||||||
|
# If you are reading this file be aware that the original Cargo.toml
|
||||||
|
# will likely look very different (and much more reasonable).
|
||||||
|
# See Cargo.toml.orig for the original contents.
|
||||||
|
|
||||||
|
[package]
|
||||||
|
edition = "2021"
|
||||||
|
rust-version = "1.68"
|
||||||
|
name = "itoa"
|
||||||
|
version = "1.0.18"
|
||||||
|
authors = ["David Tolnay <dtolnay@gmail.com>"]
|
||||||
|
build = false
|
||||||
|
exclude = ["*.png"]
|
||||||
|
autolib = false
|
||||||
|
autobins = false
|
||||||
|
autoexamples = false
|
||||||
|
autotests = false
|
||||||
|
autobenches = false
|
||||||
|
description = "Fast integer primitive to string conversion"
|
||||||
|
documentation = "https://docs.rs/itoa"
|
||||||
|
readme = "README.md"
|
||||||
|
keywords = ["integer"]
|
||||||
|
categories = [
|
||||||
|
"value-formatting",
|
||||||
|
"no-std",
|
||||||
|
"no-std::no-alloc",
|
||||||
|
]
|
||||||
|
license = "MIT OR Apache-2.0"
|
||||||
|
repository = "https://github.com/dtolnay/itoa"
|
||||||
|
|
||||||
|
[package.metadata.docs.rs]
|
||||||
|
targets = ["x86_64-unknown-linux-gnu"]
|
||||||
|
rustdoc-args = [
|
||||||
|
"--generate-link-to-definition",
|
||||||
|
"--generate-macro-expansion",
|
||||||
|
"--extern-html-root-url=core=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=alloc=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=std=https://doc.rust-lang.org",
|
||||||
|
]
|
||||||
|
|
||||||
|
[lib]
|
||||||
|
name = "itoa"
|
||||||
|
path = "src/lib.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "test"
|
||||||
|
path = "tests/test.rs"
|
||||||
|
|
||||||
|
[[bench]]
|
||||||
|
name = "bench"
|
||||||
|
path = "benches/bench.rs"
|
||||||
|
harness = false
|
||||||
|
|
||||||
|
[dependencies.no-panic]
|
||||||
|
version = "0.1"
|
||||||
|
optional = true
|
||||||
|
|
||||||
|
[target."cfg(not(miri))".dev-dependencies.criterion]
|
||||||
|
version = "0.8"
|
||||||
|
default-features = false
|
||||||
33
third_party/crates/itoa-1.0.18/Cargo.toml.orig
generated
vendored
Normal file
33
third_party/crates/itoa-1.0.18/Cargo.toml.orig
generated
vendored
Normal file
@@ -0,0 +1,33 @@
|
|||||||
|
[package]
|
||||||
|
name = "itoa"
|
||||||
|
version = "1.0.18"
|
||||||
|
authors = ["David Tolnay <dtolnay@gmail.com>"]
|
||||||
|
categories = ["value-formatting", "no-std", "no-std::no-alloc"]
|
||||||
|
description = "Fast integer primitive to string conversion"
|
||||||
|
documentation = "https://docs.rs/itoa"
|
||||||
|
edition = "2021"
|
||||||
|
exclude = ["*.png"]
|
||||||
|
keywords = ["integer"]
|
||||||
|
license = "MIT OR Apache-2.0"
|
||||||
|
repository = "https://github.com/dtolnay/itoa"
|
||||||
|
rust-version = "1.68"
|
||||||
|
|
||||||
|
[dependencies]
|
||||||
|
no-panic = { version = "0.1", optional = true }
|
||||||
|
|
||||||
|
[target.'cfg(not(miri))'.dev-dependencies]
|
||||||
|
criterion = { version = "0.8", default-features = false }
|
||||||
|
|
||||||
|
[[bench]]
|
||||||
|
name = "bench"
|
||||||
|
harness = false
|
||||||
|
|
||||||
|
[package.metadata.docs.rs]
|
||||||
|
targets = ["x86_64-unknown-linux-gnu"]
|
||||||
|
rustdoc-args = [
|
||||||
|
"--generate-link-to-definition",
|
||||||
|
"--generate-macro-expansion",
|
||||||
|
"--extern-html-root-url=core=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=alloc=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=std=https://doc.rust-lang.org",
|
||||||
|
]
|
||||||
176
third_party/crates/itoa-1.0.18/LICENSE-APACHE
vendored
Normal file
176
third_party/crates/itoa-1.0.18/LICENSE-APACHE
vendored
Normal file
@@ -0,0 +1,176 @@
|
|||||||
|
Apache License
|
||||||
|
Version 2.0, January 2004
|
||||||
|
http://www.apache.org/licenses/
|
||||||
|
|
||||||
|
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||||
|
|
||||||
|
1. Definitions.
|
||||||
|
|
||||||
|
"License" shall mean the terms and conditions for use, reproduction,
|
||||||
|
and distribution as defined by Sections 1 through 9 of this document.
|
||||||
|
|
||||||
|
"Licensor" shall mean the copyright owner or entity authorized by
|
||||||
|
the copyright owner that is granting the License.
|
||||||
|
|
||||||
|
"Legal Entity" shall mean the union of the acting entity and all
|
||||||
|
other entities that control, are controlled by, or are under common
|
||||||
|
control with that entity. For the purposes of this definition,
|
||||||
|
"control" means (i) the power, direct or indirect, to cause the
|
||||||
|
direction or management of such entity, whether by contract or
|
||||||
|
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||||
|
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||||
|
|
||||||
|
"You" (or "Your") shall mean an individual or Legal Entity
|
||||||
|
exercising permissions granted by this License.
|
||||||
|
|
||||||
|
"Source" form shall mean the preferred form for making modifications,
|
||||||
|
including but not limited to software source code, documentation
|
||||||
|
source, and configuration files.
|
||||||
|
|
||||||
|
"Object" form shall mean any form resulting from mechanical
|
||||||
|
transformation or translation of a Source form, including but
|
||||||
|
not limited to compiled object code, generated documentation,
|
||||||
|
and conversions to other media types.
|
||||||
|
|
||||||
|
"Work" shall mean the work of authorship, whether in Source or
|
||||||
|
Object form, made available under the License, as indicated by a
|
||||||
|
copyright notice that is included in or attached to the work
|
||||||
|
(an example is provided in the Appendix below).
|
||||||
|
|
||||||
|
"Derivative Works" shall mean any work, whether in Source or Object
|
||||||
|
form, that is based on (or derived from) the Work and for which the
|
||||||
|
editorial revisions, annotations, elaborations, or other modifications
|
||||||
|
represent, as a whole, an original work of authorship. For the purposes
|
||||||
|
of this License, Derivative Works shall not include works that remain
|
||||||
|
separable from, or merely link (or bind by name) to the interfaces of,
|
||||||
|
the Work and Derivative Works thereof.
|
||||||
|
|
||||||
|
"Contribution" shall mean any work of authorship, including
|
||||||
|
the original version of the Work and any modifications or additions
|
||||||
|
to that Work or Derivative Works thereof, that is intentionally
|
||||||
|
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||||
|
or by an individual or Legal Entity authorized to submit on behalf of
|
||||||
|
the copyright owner. For the purposes of this definition, "submitted"
|
||||||
|
means any form of electronic, verbal, or written communication sent
|
||||||
|
to the Licensor or its representatives, including but not limited to
|
||||||
|
communication on electronic mailing lists, source code control systems,
|
||||||
|
and issue tracking systems that are managed by, or on behalf of, the
|
||||||
|
Licensor for the purpose of discussing and improving the Work, but
|
||||||
|
excluding communication that is conspicuously marked or otherwise
|
||||||
|
designated in writing by the copyright owner as "Not a Contribution."
|
||||||
|
|
||||||
|
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||||
|
on behalf of whom a Contribution has been received by Licensor and
|
||||||
|
subsequently incorporated within the Work.
|
||||||
|
|
||||||
|
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||||
|
this License, each Contributor hereby grants to You a perpetual,
|
||||||
|
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||||
|
copyright license to reproduce, prepare Derivative Works of,
|
||||||
|
publicly display, publicly perform, sublicense, and distribute the
|
||||||
|
Work and such Derivative Works in Source or Object form.
|
||||||
|
|
||||||
|
3. Grant of Patent License. Subject to the terms and conditions of
|
||||||
|
this License, each Contributor hereby grants to You a perpetual,
|
||||||
|
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||||
|
(except as stated in this section) patent license to make, have made,
|
||||||
|
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||||
|
where such license applies only to those patent claims licensable
|
||||||
|
by such Contributor that are necessarily infringed by their
|
||||||
|
Contribution(s) alone or by combination of their Contribution(s)
|
||||||
|
with the Work to which such Contribution(s) was submitted. If You
|
||||||
|
institute patent litigation against any entity (including a
|
||||||
|
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||||
|
or a Contribution incorporated within the Work constitutes direct
|
||||||
|
or contributory patent infringement, then any patent licenses
|
||||||
|
granted to You under this License for that Work shall terminate
|
||||||
|
as of the date such litigation is filed.
|
||||||
|
|
||||||
|
4. Redistribution. You may reproduce and distribute copies of the
|
||||||
|
Work or Derivative Works thereof in any medium, with or without
|
||||||
|
modifications, and in Source or Object form, provided that You
|
||||||
|
meet the following conditions:
|
||||||
|
|
||||||
|
(a) You must give any other recipients of the Work or
|
||||||
|
Derivative Works a copy of this License; and
|
||||||
|
|
||||||
|
(b) You must cause any modified files to carry prominent notices
|
||||||
|
stating that You changed the files; and
|
||||||
|
|
||||||
|
(c) You must retain, in the Source form of any Derivative Works
|
||||||
|
that You distribute, all copyright, patent, trademark, and
|
||||||
|
attribution notices from the Source form of the Work,
|
||||||
|
excluding those notices that do not pertain to any part of
|
||||||
|
the Derivative Works; and
|
||||||
|
|
||||||
|
(d) If the Work includes a "NOTICE" text file as part of its
|
||||||
|
distribution, then any Derivative Works that You distribute must
|
||||||
|
include a readable copy of the attribution notices contained
|
||||||
|
within such NOTICE file, excluding those notices that do not
|
||||||
|
pertain to any part of the Derivative Works, in at least one
|
||||||
|
of the following places: within a NOTICE text file distributed
|
||||||
|
as part of the Derivative Works; within the Source form or
|
||||||
|
documentation, if provided along with the Derivative Works; or,
|
||||||
|
within a display generated by the Derivative Works, if and
|
||||||
|
wherever such third-party notices normally appear. The contents
|
||||||
|
of the NOTICE file are for informational purposes only and
|
||||||
|
do not modify the License. You may add Your own attribution
|
||||||
|
notices within Derivative Works that You distribute, alongside
|
||||||
|
or as an addendum to the NOTICE text from the Work, provided
|
||||||
|
that such additional attribution notices cannot be construed
|
||||||
|
as modifying the License.
|
||||||
|
|
||||||
|
You may add Your own copyright statement to Your modifications and
|
||||||
|
may provide additional or different license terms and conditions
|
||||||
|
for use, reproduction, or distribution of Your modifications, or
|
||||||
|
for any such Derivative Works as a whole, provided Your use,
|
||||||
|
reproduction, and distribution of the Work otherwise complies with
|
||||||
|
the conditions stated in this License.
|
||||||
|
|
||||||
|
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||||
|
any Contribution intentionally submitted for inclusion in the Work
|
||||||
|
by You to the Licensor shall be under the terms and conditions of
|
||||||
|
this License, without any additional terms or conditions.
|
||||||
|
Notwithstanding the above, nothing herein shall supersede or modify
|
||||||
|
the terms of any separate license agreement you may have executed
|
||||||
|
with Licensor regarding such Contributions.
|
||||||
|
|
||||||
|
6. Trademarks. This License does not grant permission to use the trade
|
||||||
|
names, trademarks, service marks, or product names of the Licensor,
|
||||||
|
except as required for reasonable and customary use in describing the
|
||||||
|
origin of the Work and reproducing the content of the NOTICE file.
|
||||||
|
|
||||||
|
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||||
|
agreed to in writing, Licensor provides the Work (and each
|
||||||
|
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||||
|
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||||
|
implied, including, without limitation, any warranties or conditions
|
||||||
|
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||||
|
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||||
|
appropriateness of using or redistributing the Work and assume any
|
||||||
|
risks associated with Your exercise of permissions under this License.
|
||||||
|
|
||||||
|
8. Limitation of Liability. In no event and under no legal theory,
|
||||||
|
whether in tort (including negligence), contract, or otherwise,
|
||||||
|
unless required by applicable law (such as deliberate and grossly
|
||||||
|
negligent acts) or agreed to in writing, shall any Contributor be
|
||||||
|
liable to You for damages, including any direct, indirect, special,
|
||||||
|
incidental, or consequential damages of any character arising as a
|
||||||
|
result of this License or out of the use or inability to use the
|
||||||
|
Work (including but not limited to damages for loss of goodwill,
|
||||||
|
work stoppage, computer failure or malfunction, or any and all
|
||||||
|
other commercial damages or losses), even if such Contributor
|
||||||
|
has been advised of the possibility of such damages.
|
||||||
|
|
||||||
|
9. Accepting Warranty or Additional Liability. While redistributing
|
||||||
|
the Work or Derivative Works thereof, You may choose to offer,
|
||||||
|
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||||
|
or other liability obligations and/or rights consistent with this
|
||||||
|
License. However, in accepting such obligations, You may act only
|
||||||
|
on Your own behalf and on Your sole responsibility, not on behalf
|
||||||
|
of any other Contributor, and only if You agree to indemnify,
|
||||||
|
defend, and hold each Contributor harmless for any liability
|
||||||
|
incurred by, or claims asserted against, such Contributor by reason
|
||||||
|
of your accepting any such warranty or additional liability.
|
||||||
|
|
||||||
|
END OF TERMS AND CONDITIONS
|
||||||
23
third_party/crates/itoa-1.0.18/LICENSE-MIT
vendored
Normal file
23
third_party/crates/itoa-1.0.18/LICENSE-MIT
vendored
Normal file
@@ -0,0 +1,23 @@
|
|||||||
|
Permission is hereby granted, free of charge, to any
|
||||||
|
person obtaining a copy of this software and associated
|
||||||
|
documentation files (the "Software"), to deal in the
|
||||||
|
Software without restriction, including without
|
||||||
|
limitation the rights to use, copy, modify, merge,
|
||||||
|
publish, distribute, sublicense, and/or sell copies of
|
||||||
|
the Software, and to permit persons to whom the Software
|
||||||
|
is furnished to do so, subject to the following
|
||||||
|
conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice
|
||||||
|
shall be included in all copies or substantial portions
|
||||||
|
of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF
|
||||||
|
ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED
|
||||||
|
TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A
|
||||||
|
PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT
|
||||||
|
SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION
|
||||||
|
OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR
|
||||||
|
IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER
|
||||||
|
DEALINGS IN THE SOFTWARE.
|
||||||
65
third_party/crates/itoa-1.0.18/README.md
vendored
Normal file
65
third_party/crates/itoa-1.0.18/README.md
vendored
Normal file
@@ -0,0 +1,65 @@
|
|||||||
|
itoa
|
||||||
|
====
|
||||||
|
|
||||||
|
[<img alt="github" src="https://img.shields.io/badge/github-dtolnay/itoa-8da0cb?style=for-the-badge&labelColor=555555&logo=github" height="20">](https://github.com/dtolnay/itoa)
|
||||||
|
[<img alt="crates.io" src="https://img.shields.io/crates/v/itoa.svg?style=for-the-badge&color=fc8d62&logo=rust" height="20">](https://crates.io/crates/itoa)
|
||||||
|
[<img alt="docs.rs" src="https://img.shields.io/badge/docs.rs-itoa-66c2a5?style=for-the-badge&labelColor=555555&logo=docs.rs" height="20">](https://docs.rs/itoa)
|
||||||
|
[<img alt="build status" src="https://img.shields.io/github/actions/workflow/status/dtolnay/itoa/ci.yml?branch=master&style=for-the-badge" height="20">](https://github.com/dtolnay/itoa/actions?query=branch%3Amaster)
|
||||||
|
|
||||||
|
This crate provides a fast conversion of integer primitives to decimal strings.
|
||||||
|
The implementation comes straight from [libcore] but avoids the performance
|
||||||
|
penalty of going through [`core::fmt::Formatter`].
|
||||||
|
|
||||||
|
See also [`zmij`] for printing floating point primitives.
|
||||||
|
|
||||||
|
[libcore]: https://github.com/rust-lang/rust/blob/1.92.0/library/core/src/fmt/num.rs#L190-L253
|
||||||
|
[`core::fmt::Formatter`]: https://doc.rust-lang.org/std/fmt/struct.Formatter.html
|
||||||
|
[`zmij`]: https://github.com/dtolnay/zmij
|
||||||
|
|
||||||
|
```toml
|
||||||
|
[dependencies]
|
||||||
|
itoa = "1.0"
|
||||||
|
```
|
||||||
|
|
||||||
|
<br>
|
||||||
|
|
||||||
|
## Example
|
||||||
|
|
||||||
|
```rust
|
||||||
|
fn main() {
|
||||||
|
let mut buffer = itoa::Buffer::new();
|
||||||
|
let printed = buffer.format(128u64);
|
||||||
|
assert_eq!(printed, "128");
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
<br>
|
||||||
|
|
||||||
|
## Performance
|
||||||
|
|
||||||
|
The [itoa-benchmark] compares this library and other Rust integer formatting
|
||||||
|
implementations across a range of integer sizes. The vertical axis in this chart
|
||||||
|
shows nanoseconds taken by a single execution of
|
||||||
|
`itoa::Buffer::new().format(value)` so a lower result indicates a faster
|
||||||
|
library.
|
||||||
|
|
||||||
|
[itoa-benchmark]: https://github.com/dtolnay/itoa-benchmark
|
||||||
|
|
||||||
|
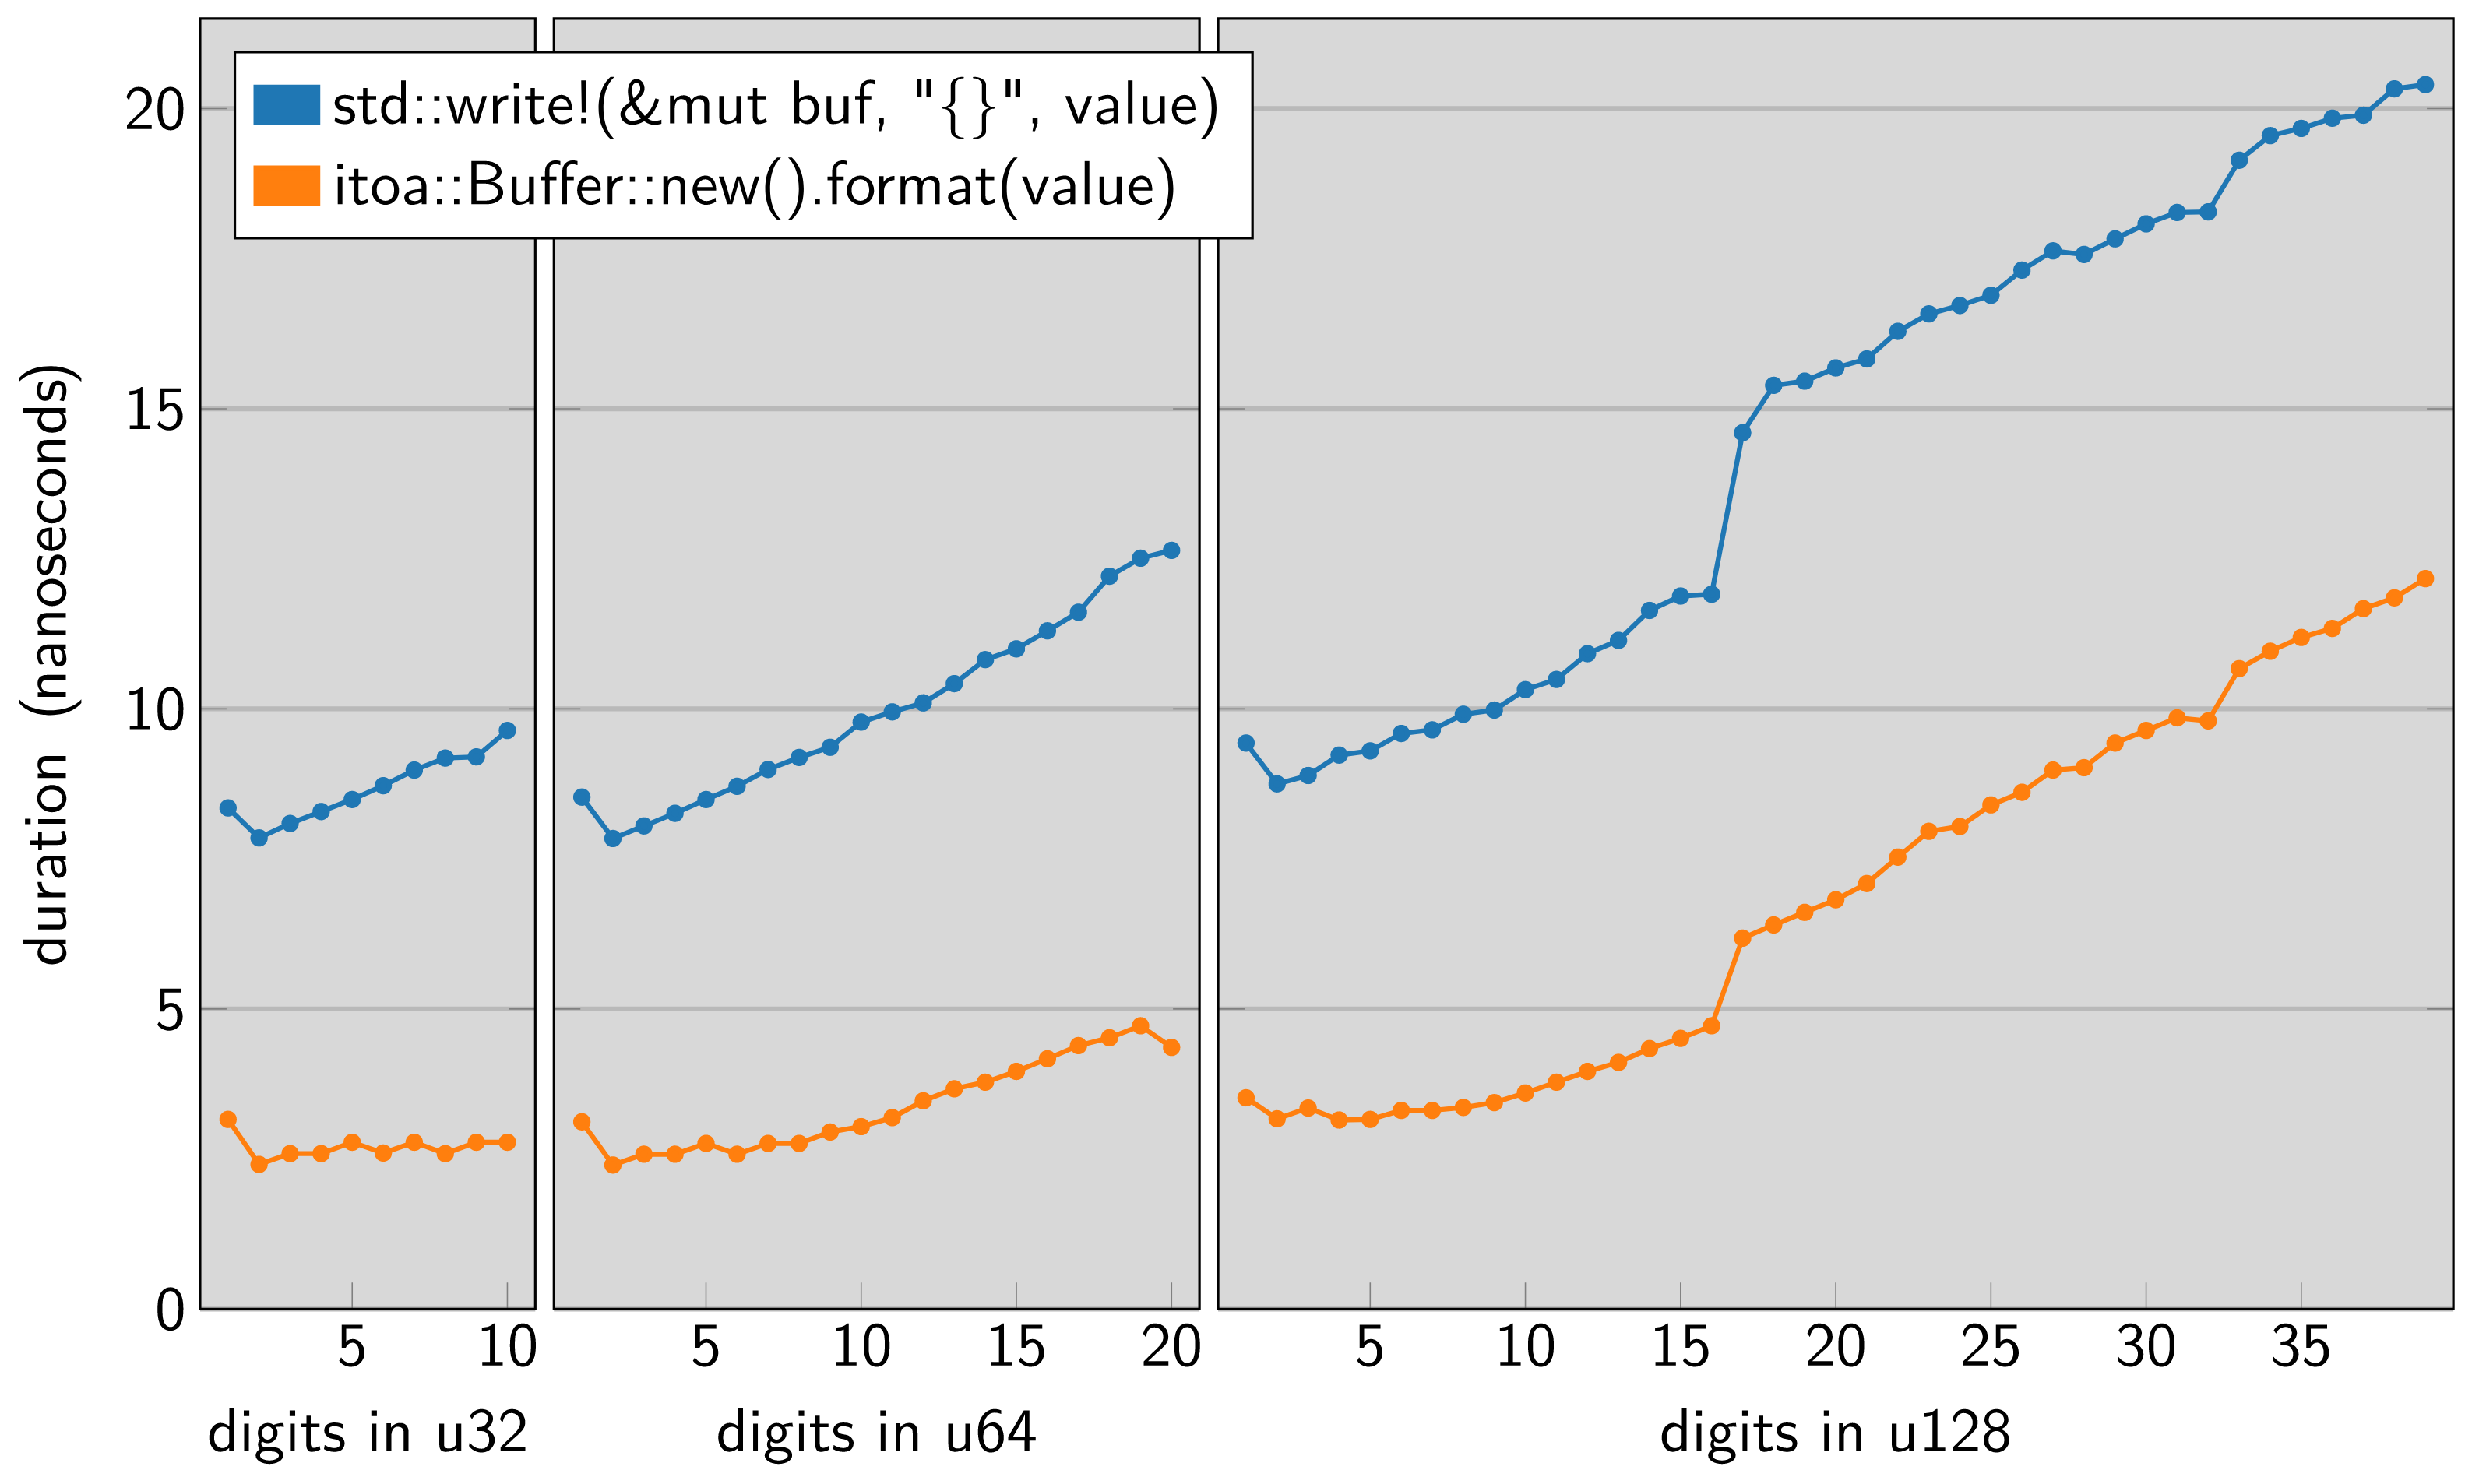
|
||||||
|
|
||||||
|
<br>
|
||||||
|
|
||||||
|
#### License
|
||||||
|
|
||||||
|
<sup>
|
||||||
|
Licensed under either of <a href="LICENSE-APACHE">Apache License, Version
|
||||||
|
2.0</a> or <a href="LICENSE-MIT">MIT license</a> at your option.
|
||||||
|
</sup>
|
||||||
|
|
||||||
|
<br>
|
||||||
|
|
||||||
|
<sub>
|
||||||
|
Unless you explicitly state otherwise, any contribution intentionally submitted
|
||||||
|
for inclusion in this crate by you, as defined in the Apache-2.0 license, shall
|
||||||
|
be dual licensed as above, without any additional terms or conditions.
|
||||||
|
</sub>
|
||||||
41
third_party/crates/itoa-1.0.18/benches/bench.rs
vendored
Normal file
41
third_party/crates/itoa-1.0.18/benches/bench.rs
vendored
Normal file
@@ -0,0 +1,41 @@
|
|||||||
|
use criterion::{criterion_group, criterion_main, Criterion};
|
||||||
|
use std::fmt::Display;
|
||||||
|
use std::hint;
|
||||||
|
use std::io::Write;
|
||||||
|
|
||||||
|
fn do_bench(c: &mut Criterion, group_name: &str, int: impl itoa::Integer + Display) {
|
||||||
|
let mut group = c.benchmark_group(group_name);
|
||||||
|
group.bench_function("itoa", |b| {
|
||||||
|
let mut buf = itoa::Buffer::new();
|
||||||
|
b.iter(move || {
|
||||||
|
let int = hint::black_box(int);
|
||||||
|
let formatted = buf.format(int);
|
||||||
|
hint::black_box(formatted);
|
||||||
|
});
|
||||||
|
});
|
||||||
|
group.bench_function("std::fmt", |b| {
|
||||||
|
let mut buf = Vec::with_capacity(20);
|
||||||
|
b.iter(|| {
|
||||||
|
buf.clear();
|
||||||
|
let int = hint::black_box(int);
|
||||||
|
write!(&mut buf, "{int}").unwrap();
|
||||||
|
hint::black_box(buf.as_slice());
|
||||||
|
});
|
||||||
|
});
|
||||||
|
group.finish();
|
||||||
|
}
|
||||||
|
|
||||||
|
fn bench(c: &mut Criterion) {
|
||||||
|
do_bench(c, "u64[0]", 0u64);
|
||||||
|
do_bench(c, "u64[half]", u64::from(u32::MAX));
|
||||||
|
do_bench(c, "u64[max]", u64::MAX);
|
||||||
|
|
||||||
|
do_bench(c, "i16[0]", 0i16);
|
||||||
|
do_bench(c, "i16[min]", i16::MIN);
|
||||||
|
|
||||||
|
do_bench(c, "u128[0]", 0u128);
|
||||||
|
do_bench(c, "u128[max]", u128::MAX);
|
||||||
|
}
|
||||||
|
|
||||||
|
criterion_group!(benches, bench);
|
||||||
|
criterion_main!(benches);
|
||||||
466
third_party/crates/itoa-1.0.18/src/lib.rs
vendored
Normal file
466
third_party/crates/itoa-1.0.18/src/lib.rs
vendored
Normal file
@@ -0,0 +1,466 @@
|
|||||||
|
//! [![github]](https://github.com/dtolnay/itoa) [![crates-io]](https://crates.io/crates/itoa) [![docs-rs]](https://docs.rs/itoa)
|
||||||
|
//!
|
||||||
|
//! [github]: https://img.shields.io/badge/github-8da0cb?style=for-the-badge&labelColor=555555&logo=github
|
||||||
|
//! [crates-io]: https://img.shields.io/badge/crates.io-fc8d62?style=for-the-badge&labelColor=555555&logo=rust
|
||||||
|
//! [docs-rs]: https://img.shields.io/badge/docs.rs-66c2a5?style=for-the-badge&labelColor=555555&logo=docs.rs
|
||||||
|
//!
|
||||||
|
//! <br>
|
||||||
|
//!
|
||||||
|
//! This crate provides a fast conversion of integer primitives to decimal
|
||||||
|
//! strings. The implementation comes straight from [libcore] but avoids the
|
||||||
|
//! performance penalty of going through [`core::fmt::Formatter`].
|
||||||
|
//!
|
||||||
|
//! See also [`zmij`] for printing floating point primitives.
|
||||||
|
//!
|
||||||
|
//! [libcore]: https://github.com/rust-lang/rust/blob/1.92.0/library/core/src/fmt/num.rs#L190-L253
|
||||||
|
//! [`zmij`]: https://github.com/dtolnay/zmij
|
||||||
|
//!
|
||||||
|
//! # Example
|
||||||
|
//!
|
||||||
|
//! ```
|
||||||
|
//! fn main() {
|
||||||
|
//! let mut buffer = itoa::Buffer::new();
|
||||||
|
//! let printed = buffer.format(128u64);
|
||||||
|
//! assert_eq!(printed, "128");
|
||||||
|
//! }
|
||||||
|
//! ```
|
||||||
|
//!
|
||||||
|
//! # Performance
|
||||||
|
//!
|
||||||
|
//! The [itoa-benchmark] compares this library and other Rust integer formatting
|
||||||
|
//! implementations across a range of integer sizes. The vertical axis in this
|
||||||
|
//! chart shows nanoseconds taken by a single execution of
|
||||||
|
//! `itoa::Buffer::new().format(value)` so a lower result indicates a faster
|
||||||
|
//! library.
|
||||||
|
//!
|
||||||
|
//! [itoa-benchmark]: https://github.com/dtolnay/itoa-benchmark
|
||||||
|
//!
|
||||||
|
//! 
|
||||||
|
|
||||||
|
#![doc(html_root_url = "https://docs.rs/itoa/1.0.18")]
|
||||||
|
#![no_std]
|
||||||
|
#![allow(
|
||||||
|
clippy::cast_lossless,
|
||||||
|
clippy::cast_possible_truncation,
|
||||||
|
clippy::cast_sign_loss,
|
||||||
|
clippy::expl_impl_clone_on_copy,
|
||||||
|
clippy::identity_op,
|
||||||
|
clippy::items_after_statements,
|
||||||
|
clippy::must_use_candidate,
|
||||||
|
clippy::needless_doctest_main,
|
||||||
|
clippy::unreadable_literal
|
||||||
|
)]
|
||||||
|
|
||||||
|
mod u128_ext;
|
||||||
|
|
||||||
|
use core::hint;
|
||||||
|
use core::mem::{self, MaybeUninit};
|
||||||
|
use core::str;
|
||||||
|
#[cfg(feature = "no-panic")]
|
||||||
|
use no_panic::no_panic;
|
||||||
|
|
||||||
|
/// A correctly sized stack allocation for the formatted integer to be written
|
||||||
|
/// into.
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// let mut buffer = itoa::Buffer::new();
|
||||||
|
/// let printed = buffer.format(1234);
|
||||||
|
/// assert_eq!(printed, "1234");
|
||||||
|
/// ```
|
||||||
|
pub struct Buffer {
|
||||||
|
bytes: [MaybeUninit<u8>; i128::MAX_STR_LEN],
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Default for Buffer {
|
||||||
|
#[inline]
|
||||||
|
fn default() -> Buffer {
|
||||||
|
Buffer::new()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Copy for Buffer {}
|
||||||
|
|
||||||
|
#[allow(clippy::non_canonical_clone_impl)]
|
||||||
|
impl Clone for Buffer {
|
||||||
|
#[inline]
|
||||||
|
fn clone(&self) -> Self {
|
||||||
|
Buffer::new()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Buffer {
|
||||||
|
/// This is a cheap operation; you don't need to worry about reusing buffers
|
||||||
|
/// for efficiency.
|
||||||
|
#[inline]
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
pub fn new() -> Buffer {
|
||||||
|
let bytes = [MaybeUninit::<u8>::uninit(); i128::MAX_STR_LEN];
|
||||||
|
Buffer { bytes }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Print an integer into this buffer and return a reference to its string
|
||||||
|
/// representation within the buffer.
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
pub fn format<I: Integer>(&mut self, i: I) -> &str {
|
||||||
|
let buf_ptr = self.bytes.as_mut_ptr().cast::<I::Buffer>();
|
||||||
|
let string = i.write(unsafe { &mut *buf_ptr });
|
||||||
|
if string.len() > I::MAX_STR_LEN {
|
||||||
|
unsafe { hint::unreachable_unchecked() };
|
||||||
|
}
|
||||||
|
string
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// An integer that can be written into an [`itoa::Buffer`][Buffer].
|
||||||
|
///
|
||||||
|
/// This trait is sealed and cannot be implemented for types outside of itoa.
|
||||||
|
pub trait Integer: private::Sealed {
|
||||||
|
/// The maximum length of string that formatting an integer of this type can
|
||||||
|
/// produce on the current target platform.
|
||||||
|
const MAX_STR_LEN: usize;
|
||||||
|
}
|
||||||
|
|
||||||
|
// Seal to prevent downstream implementations of the Integer trait.
|
||||||
|
mod private {
|
||||||
|
#[doc(hidden)]
|
||||||
|
pub trait Sealed: Copy {
|
||||||
|
#[doc(hidden)]
|
||||||
|
type Buffer: 'static;
|
||||||
|
fn write(self, buf: &mut Self::Buffer) -> &str;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! impl_Integer {
|
||||||
|
($Signed:ident, $Unsigned:ident) => {
|
||||||
|
const _: () = {
|
||||||
|
assert!($Signed::MIN < 0, "need signed");
|
||||||
|
assert!($Unsigned::MIN == 0, "need unsigned");
|
||||||
|
assert!($Signed::BITS == $Unsigned::BITS, "need counterparts");
|
||||||
|
};
|
||||||
|
|
||||||
|
impl Integer for $Unsigned {
|
||||||
|
const MAX_STR_LEN: usize = $Unsigned::MAX.ilog10() as usize + 1;
|
||||||
|
}
|
||||||
|
|
||||||
|
impl private::Sealed for $Unsigned {
|
||||||
|
type Buffer = [MaybeUninit<u8>; Self::MAX_STR_LEN];
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn write(self, buf: &mut Self::Buffer) -> &str {
|
||||||
|
let offset = Unsigned::fmt(self, buf);
|
||||||
|
// SAFETY: Starting from `offset`, all elements of the slice have been set.
|
||||||
|
unsafe { slice_buffer_to_str(buf, offset) }
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Integer for $Signed {
|
||||||
|
const MAX_STR_LEN: usize = $Signed::MAX.ilog10() as usize + 2;
|
||||||
|
}
|
||||||
|
|
||||||
|
impl private::Sealed for $Signed {
|
||||||
|
type Buffer = [MaybeUninit<u8>; Self::MAX_STR_LEN];
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn write(self, buf: &mut Self::Buffer) -> &str {
|
||||||
|
let mut offset = Self::MAX_STR_LEN - $Unsigned::MAX_STR_LEN;
|
||||||
|
offset += Unsigned::fmt(
|
||||||
|
self.unsigned_abs(),
|
||||||
|
(&mut buf[offset..]).try_into().unwrap(),
|
||||||
|
);
|
||||||
|
if self < 0 {
|
||||||
|
offset -= 1;
|
||||||
|
buf[offset].write(b'-');
|
||||||
|
}
|
||||||
|
// SAFETY: Starting from `offset`, all elements of the slice have been set.
|
||||||
|
unsafe { slice_buffer_to_str(buf, offset) }
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
impl_Integer!(i8, u8);
|
||||||
|
impl_Integer!(i16, u16);
|
||||||
|
impl_Integer!(i32, u32);
|
||||||
|
impl_Integer!(i64, u64);
|
||||||
|
impl_Integer!(i128, u128);
|
||||||
|
|
||||||
|
macro_rules! impl_Integer_size {
|
||||||
|
($t:ty as $primitive:ident #[cfg(target_pointer_width = $width:literal)]) => {
|
||||||
|
#[cfg(target_pointer_width = $width)]
|
||||||
|
impl Integer for $t {
|
||||||
|
const MAX_STR_LEN: usize = <$primitive as Integer>::MAX_STR_LEN;
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(target_pointer_width = $width)]
|
||||||
|
impl private::Sealed for $t {
|
||||||
|
type Buffer = <$primitive as private::Sealed>::Buffer;
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn write(self, buf: &mut Self::Buffer) -> &str {
|
||||||
|
(self as $primitive).write(buf)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
impl_Integer_size!(isize as i16 #[cfg(target_pointer_width = "16")]);
|
||||||
|
impl_Integer_size!(usize as u16 #[cfg(target_pointer_width = "16")]);
|
||||||
|
impl_Integer_size!(isize as i32 #[cfg(target_pointer_width = "32")]);
|
||||||
|
impl_Integer_size!(usize as u32 #[cfg(target_pointer_width = "32")]);
|
||||||
|
impl_Integer_size!(isize as i64 #[cfg(target_pointer_width = "64")]);
|
||||||
|
impl_Integer_size!(usize as u64 #[cfg(target_pointer_width = "64")]);
|
||||||
|
|
||||||
|
#[repr(C, align(2))]
|
||||||
|
struct DecimalPairs([u8; 200]);
|
||||||
|
|
||||||
|
// The string of all two-digit numbers in range 00..99 is used as a lookup table.
|
||||||
|
static DECIMAL_PAIRS: DecimalPairs = DecimalPairs(
|
||||||
|
*b"0001020304050607080910111213141516171819\
|
||||||
|
2021222324252627282930313233343536373839\
|
||||||
|
4041424344454647484950515253545556575859\
|
||||||
|
6061626364656667686970717273747576777879\
|
||||||
|
8081828384858687888990919293949596979899",
|
||||||
|
);
|
||||||
|
|
||||||
|
// Returns {value / 100, value % 100} correct for values of up to 4 digits.
|
||||||
|
fn divmod100(value: u32) -> (u32, u32) {
|
||||||
|
debug_assert!(value < 10_000);
|
||||||
|
const EXP: u32 = 19; // 19 is faster or equal to 12 even for 3 digits.
|
||||||
|
const SIG: u32 = (1 << EXP) / 100 + 1;
|
||||||
|
let div = (value * SIG) >> EXP; // value / 100
|
||||||
|
(div, value - div * 100)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// This function converts a slice of ascii characters into a `&str` starting
|
||||||
|
/// from `offset`.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// `buf` content starting from `offset` index MUST BE initialized and MUST BE
|
||||||
|
/// ascii characters.
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
unsafe fn slice_buffer_to_str(buf: &[MaybeUninit<u8>], offset: usize) -> &str {
|
||||||
|
// SAFETY: `offset` is always included between 0 and `buf`'s length.
|
||||||
|
let written = unsafe { buf.get_unchecked(offset..) };
|
||||||
|
// SAFETY: (`assume_init_ref`) All buf content since offset is set.
|
||||||
|
// SAFETY: (`from_utf8_unchecked`) Writes use ASCII from the lookup table exclusively.
|
||||||
|
unsafe { str::from_utf8_unchecked(&*(written as *const [MaybeUninit<u8>] as *const [u8])) }
|
||||||
|
}
|
||||||
|
|
||||||
|
trait Unsigned: Integer {
|
||||||
|
fn fmt(self, buf: &mut Self::Buffer) -> usize;
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! impl_Unsigned {
|
||||||
|
($Unsigned:ident) => {
|
||||||
|
impl Unsigned for $Unsigned {
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn fmt(self, buf: &mut Self::Buffer) -> usize {
|
||||||
|
// Count the number of bytes in buf that are not initialized.
|
||||||
|
let mut offset = buf.len();
|
||||||
|
// Consume the least-significant decimals from a working copy.
|
||||||
|
let mut remain = self;
|
||||||
|
|
||||||
|
// Format per four digits from the lookup table.
|
||||||
|
// Four digits need a 16-bit $Unsigned or wider.
|
||||||
|
while mem::size_of::<Self>() > 1
|
||||||
|
&& remain
|
||||||
|
> 999
|
||||||
|
.try_into()
|
||||||
|
.expect("branch is not hit for types that cannot fit 999 (u8)")
|
||||||
|
{
|
||||||
|
offset -= 4;
|
||||||
|
|
||||||
|
// pull two pairs
|
||||||
|
let scale: Self = 1_00_00
|
||||||
|
.try_into()
|
||||||
|
.expect("branch is not hit for types that cannot fit 1E4 (u8)");
|
||||||
|
let quad = remain % scale;
|
||||||
|
remain /= scale;
|
||||||
|
let (pair1, pair2) = divmod100(quad as u32);
|
||||||
|
unsafe {
|
||||||
|
buf[offset + 0]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 0));
|
||||||
|
buf[offset + 1]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 1));
|
||||||
|
buf[offset + 2]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 0));
|
||||||
|
buf[offset + 3]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 1));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Format per two digits from the lookup table.
|
||||||
|
if remain > 9 {
|
||||||
|
offset -= 2;
|
||||||
|
|
||||||
|
let (last, pair) = divmod100(remain as u32);
|
||||||
|
remain = last as Self;
|
||||||
|
unsafe {
|
||||||
|
buf[offset + 0]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair as usize * 2 + 0));
|
||||||
|
buf[offset + 1]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair as usize * 2 + 1));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Format the last remaining digit, if any.
|
||||||
|
if remain != 0 || self == 0 {
|
||||||
|
offset -= 1;
|
||||||
|
|
||||||
|
// Either the compiler sees that remain < 10, or it prevents
|
||||||
|
// a boundary check up next.
|
||||||
|
let last = remain as u8 & 15;
|
||||||
|
buf[offset].write(b'0' + last);
|
||||||
|
// not used: remain = 0;
|
||||||
|
}
|
||||||
|
|
||||||
|
offset
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
impl_Unsigned!(u8);
|
||||||
|
impl_Unsigned!(u16);
|
||||||
|
impl_Unsigned!(u32);
|
||||||
|
impl_Unsigned!(u64);
|
||||||
|
|
||||||
|
impl Unsigned for u128 {
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn fmt(self, buf: &mut Self::Buffer) -> usize {
|
||||||
|
// Optimize common-case zero, which would also need special treatment due to
|
||||||
|
// its "leading" zero.
|
||||||
|
if self == 0 {
|
||||||
|
let offset = buf.len() - 1;
|
||||||
|
buf[offset].write(b'0');
|
||||||
|
return offset;
|
||||||
|
}
|
||||||
|
// Take the 16 least-significant decimals.
|
||||||
|
let (quot_1e16, mod_1e16) = div_rem_1e16(self);
|
||||||
|
let (mut remain, mut offset) = if quot_1e16 == 0 {
|
||||||
|
(mod_1e16, u128::MAX_STR_LEN)
|
||||||
|
} else {
|
||||||
|
// Write digits at buf[23..39].
|
||||||
|
enc_16lsd::<{ u128::MAX_STR_LEN - 16 }>(buf, mod_1e16);
|
||||||
|
|
||||||
|
// Take another 16 decimals.
|
||||||
|
let (quot2, mod2) = div_rem_1e16(quot_1e16);
|
||||||
|
if quot2 == 0 {
|
||||||
|
(mod2, u128::MAX_STR_LEN - 16)
|
||||||
|
} else {
|
||||||
|
// Write digits at buf[7..23].
|
||||||
|
enc_16lsd::<{ u128::MAX_STR_LEN - 32 }>(buf, mod2);
|
||||||
|
// Quot2 has at most 7 decimals remaining after two 1e16 divisions.
|
||||||
|
(quot2 as u64, u128::MAX_STR_LEN - 32)
|
||||||
|
}
|
||||||
|
};
|
||||||
|
|
||||||
|
// Format per four digits from the lookup table.
|
||||||
|
while remain > 999 {
|
||||||
|
offset -= 4;
|
||||||
|
|
||||||
|
// pull two pairs
|
||||||
|
let quad = remain % 1_00_00;
|
||||||
|
remain /= 1_00_00;
|
||||||
|
let (pair1, pair2) = divmod100(quad as u32);
|
||||||
|
unsafe {
|
||||||
|
buf[offset + 0].write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 0));
|
||||||
|
buf[offset + 1].write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 1));
|
||||||
|
buf[offset + 2].write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 0));
|
||||||
|
buf[offset + 3].write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 1));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Format per two digits from the lookup table.
|
||||||
|
if remain > 9 {
|
||||||
|
offset -= 2;
|
||||||
|
|
||||||
|
let (last, pair) = divmod100(remain as u32);
|
||||||
|
remain = last as u64;
|
||||||
|
unsafe {
|
||||||
|
buf[offset + 0].write(*DECIMAL_PAIRS.0.get_unchecked(pair as usize * 2 + 0));
|
||||||
|
buf[offset + 1].write(*DECIMAL_PAIRS.0.get_unchecked(pair as usize * 2 + 1));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Format the last remaining digit, if any.
|
||||||
|
if remain != 0 {
|
||||||
|
offset -= 1;
|
||||||
|
|
||||||
|
// Either the compiler sees that remain < 10, or it prevents
|
||||||
|
// a boundary check up next.
|
||||||
|
let last = remain as u8 & 15;
|
||||||
|
buf[offset].write(b'0' + last);
|
||||||
|
// not used: remain = 0;
|
||||||
|
}
|
||||||
|
offset
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Encodes the 16 least-significant decimals of n into `buf[OFFSET..OFFSET + 16]`.
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn enc_16lsd<const OFFSET: usize>(buf: &mut [MaybeUninit<u8>], n: u64) {
|
||||||
|
// Consume the least-significant decimals from a working copy.
|
||||||
|
let mut remain = n;
|
||||||
|
|
||||||
|
// Format per four digits from the lookup table.
|
||||||
|
for quad_index in (1..4).rev() {
|
||||||
|
// pull two pairs
|
||||||
|
let quad = remain % 1_00_00;
|
||||||
|
remain /= 1_00_00;
|
||||||
|
let (pair1, pair2) = divmod100(quad as u32);
|
||||||
|
unsafe {
|
||||||
|
buf[quad_index * 4 + OFFSET + 0]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 0));
|
||||||
|
buf[quad_index * 4 + OFFSET + 1]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 1));
|
||||||
|
buf[quad_index * 4 + OFFSET + 2]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 0));
|
||||||
|
buf[quad_index * 4 + OFFSET + 3]
|
||||||
|
.write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 1));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// final two pairs
|
||||||
|
let (pair1, pair2) = divmod100(remain as u32);
|
||||||
|
unsafe {
|
||||||
|
buf[OFFSET + 0].write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 0));
|
||||||
|
buf[OFFSET + 1].write(*DECIMAL_PAIRS.0.get_unchecked(pair1 as usize * 2 + 1));
|
||||||
|
buf[OFFSET + 2].write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 0));
|
||||||
|
buf[OFFSET + 3].write(*DECIMAL_PAIRS.0.get_unchecked(pair2 as usize * 2 + 1));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Euclidean division plus remainder with constant 1E16 basically consumes 16
|
||||||
|
// decimals from n.
|
||||||
|
//
|
||||||
|
// The integer division algorithm is based on the following paper:
|
||||||
|
//
|
||||||
|
// T. Granlund and P. Montgomery, “Division by Invariant Integers Using Multiplication”
|
||||||
|
// in Proc. of the SIGPLAN94 Conference on Programming Language Design and
|
||||||
|
// Implementation, 1994, pp. 61–72
|
||||||
|
//
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
fn div_rem_1e16(n: u128) -> (u128, u64) {
|
||||||
|
const D: u128 = 1_0000_0000_0000_0000;
|
||||||
|
// The check inlines well with the caller flow.
|
||||||
|
if n < D {
|
||||||
|
return (0, n as u64);
|
||||||
|
}
|
||||||
|
|
||||||
|
// These constant values are computed with the CHOOSE_MULTIPLIER procedure
|
||||||
|
// from the Granlund & Montgomery paper, using N=128, prec=128 and d=1E16.
|
||||||
|
const M_HIGH: u128 = 76624777043294442917917351357515459181;
|
||||||
|
const SH_POST: u8 = 51;
|
||||||
|
|
||||||
|
// n.widening_mul(M_HIGH).1 >> SH_POST
|
||||||
|
let quot = u128_ext::mulhi(n, M_HIGH) >> SH_POST;
|
||||||
|
let rem = n - quot * D;
|
||||||
|
(quot, rem as u64)
|
||||||
|
}
|
||||||
22
third_party/crates/itoa-1.0.18/src/u128_ext.rs
vendored
Normal file
22
third_party/crates/itoa-1.0.18/src/u128_ext.rs
vendored
Normal file
@@ -0,0 +1,22 @@
|
|||||||
|
#[cfg(feature = "no-panic")]
|
||||||
|
use no_panic::no_panic;
|
||||||
|
|
||||||
|
/// Multiply unsigned 128 bit integers, return upper 128 bits of the result
|
||||||
|
#[inline]
|
||||||
|
#[cfg_attr(feature = "no-panic", no_panic)]
|
||||||
|
pub(crate) fn mulhi(x: u128, y: u128) -> u128 {
|
||||||
|
let x_lo = x as u64;
|
||||||
|
let x_hi = (x >> 64) as u64;
|
||||||
|
let y_lo = y as u64;
|
||||||
|
let y_hi = (y >> 64) as u64;
|
||||||
|
|
||||||
|
// handle possibility of overflow
|
||||||
|
let carry = (u128::from(x_lo) * u128::from(y_lo)) >> 64;
|
||||||
|
let m = u128::from(x_lo) * u128::from(y_hi) + carry;
|
||||||
|
let high1 = m >> 64;
|
||||||
|
|
||||||
|
let m_lo = m as u64;
|
||||||
|
let high2 = (u128::from(x_hi) * u128::from(y_lo) + u128::from(m_lo)) >> 64;
|
||||||
|
|
||||||
|
u128::from(x_hi) * u128::from(y_hi) + high1 + high2
|
||||||
|
}
|
||||||
45
third_party/crates/itoa-1.0.18/tests/test.rs
vendored
Normal file
45
third_party/crates/itoa-1.0.18/tests/test.rs
vendored
Normal file
@@ -0,0 +1,45 @@
|
|||||||
|
#![allow(non_snake_case)]
|
||||||
|
|
||||||
|
macro_rules! test {
|
||||||
|
($($name:ident($value:expr, $expected:expr))*) => {
|
||||||
|
$(
|
||||||
|
#[test]
|
||||||
|
fn $name() {
|
||||||
|
let mut buffer = itoa::Buffer::new();
|
||||||
|
let s = buffer.format($value);
|
||||||
|
assert_eq!(s, $expected);
|
||||||
|
}
|
||||||
|
)*
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
test! {
|
||||||
|
test_u64_0(0u64, "0")
|
||||||
|
test_u64_half(u64::from(u32::MAX), "4294967295")
|
||||||
|
test_u64_max(u64::MAX, "18446744073709551615")
|
||||||
|
test_i64_min(i64::MIN, "-9223372036854775808")
|
||||||
|
|
||||||
|
test_i16_0(0i16, "0")
|
||||||
|
test_i16_min(i16::MIN, "-32768")
|
||||||
|
|
||||||
|
test_u128_0(0u128, "0")
|
||||||
|
test_u128_max(u128::MAX, "340282366920938463463374607431768211455")
|
||||||
|
test_i128_min(i128::MIN, "-170141183460469231731687303715884105728")
|
||||||
|
test_i128_max(i128::MAX, "170141183460469231731687303715884105727")
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn test_max_str_len() {
|
||||||
|
use itoa::Integer as _;
|
||||||
|
|
||||||
|
assert_eq!(i8::MAX_STR_LEN, 4);
|
||||||
|
assert_eq!(u8::MAX_STR_LEN, 3);
|
||||||
|
assert_eq!(i16::MAX_STR_LEN, 6);
|
||||||
|
assert_eq!(u16::MAX_STR_LEN, 5);
|
||||||
|
assert_eq!(i32::MAX_STR_LEN, 11);
|
||||||
|
assert_eq!(u32::MAX_STR_LEN, 10);
|
||||||
|
assert_eq!(i64::MAX_STR_LEN, 20);
|
||||||
|
assert_eq!(u64::MAX_STR_LEN, 20);
|
||||||
|
assert_eq!(i128::MAX_STR_LEN, 40);
|
||||||
|
assert_eq!(u128::MAX_STR_LEN, 39);
|
||||||
|
}
|
||||||
1
third_party/crates/memchr-2.8.3/.cargo-checksum.json
vendored
Normal file
1
third_party/crates/memchr-2.8.3/.cargo-checksum.json
vendored
Normal file
File diff suppressed because one or more lines are too long
6
third_party/crates/memchr-2.8.3/.cargo_vcs_info.json
vendored
Normal file
6
third_party/crates/memchr-2.8.3/.cargo_vcs_info.json
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
{
|
||||||
|
"git": {
|
||||||
|
"sha1": "5fdb40c054e1fff359a2f7bdf7f87a13b34b465d"
|
||||||
|
},
|
||||||
|
"path_in_vcs": ""
|
||||||
|
}
|
||||||
1
third_party/crates/memchr-2.8.3/.ignore
vendored
Normal file
1
third_party/crates/memchr-2.8.3/.ignore
vendored
Normal file
@@ -0,0 +1 @@
|
|||||||
|
!.github
|
||||||
16
third_party/crates/memchr-2.8.3/.vim/coc-settings.json
vendored
Normal file
16
third_party/crates/memchr-2.8.3/.vim/coc-settings.json
vendored
Normal file
@@ -0,0 +1,16 @@
|
|||||||
|
{
|
||||||
|
"rust-analyzer.cargo.allFeatures": false,
|
||||||
|
"rust-analyzer.linkedProjects": [
|
||||||
|
"benchmarks/engines/libc/Cargo.toml",
|
||||||
|
"benchmarks/engines/rust-bytecount/Cargo.toml",
|
||||||
|
"benchmarks/engines/rust-jetscii/Cargo.toml",
|
||||||
|
"benchmarks/engines/rust-memchr/Cargo.toml",
|
||||||
|
"benchmarks/engines/rust-memchrold/Cargo.toml",
|
||||||
|
"benchmarks/engines/rust-sliceslice/Cargo.toml",
|
||||||
|
"benchmarks/engines/rust-std/Cargo.toml",
|
||||||
|
"benchmarks/engines/stringzilla/Cargo.toml",
|
||||||
|
"benchmarks/shared/Cargo.toml",
|
||||||
|
"fuzz/Cargo.toml",
|
||||||
|
"Cargo.toml"
|
||||||
|
]
|
||||||
|
}
|
||||||
38
third_party/crates/memchr-2.8.3/AI_POLICY.md
vendored
Normal file
38
third_party/crates/memchr-2.8.3/AI_POLICY.md
vendored
Normal file
@@ -0,0 +1,38 @@
|
|||||||
|
# AI Policy
|
||||||
|
|
||||||
|
Using AI (i.e., LLMs) as tools for coding is welcome. A high bar is held for
|
||||||
|
all contributions to this project. Moreover, the project maintainers remain
|
||||||
|
responsible for any code that is published as part of a release. Contributors
|
||||||
|
are expected to be responsible for any code they publish.
|
||||||
|
|
||||||
|
**AI should not be used to generate comments when communicating with
|
||||||
|
maintainers**. Comments are expected to be written by humans. Comments that are
|
||||||
|
believed to be written by AI may be hidden without notice.
|
||||||
|
|
||||||
|
If you are opening an issue, you should be able to describe the problem in your
|
||||||
|
own words.
|
||||||
|
|
||||||
|
If you are opening a pull request, you are expected to be able to explain the
|
||||||
|
proposed changes in your own words. This includes the pull request body and
|
||||||
|
responses to questions. **Do not copy responses from the AI when replying to
|
||||||
|
questions from maintainers.**
|
||||||
|
|
||||||
|
This project requires a human in the loop who understands the work produced
|
||||||
|
by AI. **Autonomous agents are not allowed to be used for contributing to our
|
||||||
|
projects**. Pull requests that appear in violation of this will be closed,
|
||||||
|
perhaps without notice.
|
||||||
|
|
||||||
|
If you wish to include context from an interaction with AI in your comments, it
|
||||||
|
must be in a quote block (e.g., using `>`) and disclosed as such. It must be
|
||||||
|
accompanied by human commentary explaining the relevance and implications of
|
||||||
|
the context. Do not share long snippets.
|
||||||
|
|
||||||
|
AI is useful when communicating as a non-native English speaker. If you are
|
||||||
|
using AI to edit your comments for this purpose, please take the time to ensure
|
||||||
|
it reflects your own voice and ideas. If using AI for translation, we recommend
|
||||||
|
writing in your native language and including the AI translation in a quote
|
||||||
|
block.
|
||||||
|
|
||||||
|
This policy was adapted from [uv's AI policy].
|
||||||
|
|
||||||
|
[uv's AI policy]: https://github.com/astral-sh/.github/blob/c5187e200db51bfe11d56e13053d29bd3793fdd8/AI_POLICY.md
|
||||||
114
third_party/crates/memchr-2.8.3/BUILD.bazel
vendored
Normal file
114
third_party/crates/memchr-2.8.3/BUILD.bazel
vendored
Normal file
@@ -0,0 +1,114 @@
|
|||||||
|
###############################################################################
|
||||||
|
# @generated
|
||||||
|
# DO NOT MODIFY: This file is auto-generated by a crate_universe tool. To
|
||||||
|
# regenerate this file, run the following:
|
||||||
|
#
|
||||||
|
# bazel run @@//third_party:vendor_crates
|
||||||
|
###############################################################################
|
||||||
|
|
||||||
|
load("@rules_rust//cargo:defs.bzl", "cargo_toml_env_vars")
|
||||||
|
load("@rules_rust//rust:defs.bzl", "rust_library")
|
||||||
|
|
||||||
|
package(default_visibility = ["//visibility:public"])
|
||||||
|
|
||||||
|
cargo_toml_env_vars(
|
||||||
|
name = "cargo_toml_env_vars",
|
||||||
|
src = "Cargo.toml",
|
||||||
|
)
|
||||||
|
|
||||||
|
rust_library(
|
||||||
|
name = "memchr",
|
||||||
|
srcs = glob(
|
||||||
|
include = ["**/*.rs"],
|
||||||
|
allow_empty = False,
|
||||||
|
),
|
||||||
|
compile_data = glob(
|
||||||
|
include = ["**"],
|
||||||
|
allow_empty = True,
|
||||||
|
exclude = [
|
||||||
|
"**/* *",
|
||||||
|
".tmp_git_root/**/*",
|
||||||
|
"BUILD",
|
||||||
|
"BUILD.bazel",
|
||||||
|
"WORKSPACE",
|
||||||
|
"WORKSPACE.bazel",
|
||||||
|
],
|
||||||
|
),
|
||||||
|
crate_features = [
|
||||||
|
"alloc",
|
||||||
|
"std",
|
||||||
|
],
|
||||||
|
crate_root = "src/lib.rs",
|
||||||
|
edition = "2021",
|
||||||
|
rustc_env_files = [
|
||||||
|
":cargo_toml_env_vars",
|
||||||
|
],
|
||||||
|
rustc_flags = [
|
||||||
|
"--cap-lints=allow",
|
||||||
|
],
|
||||||
|
tags = [
|
||||||
|
"cargo-bazel",
|
||||||
|
"crate-name=memchr",
|
||||||
|
"manual",
|
||||||
|
"noclippy",
|
||||||
|
"norustfmt",
|
||||||
|
],
|
||||||
|
target_compatible_with = select({
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios-macabi": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios-sim": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-fuchsia": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-nixos-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-none": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-nto-qnx710": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-uefi": [],
|
||||||
|
"@rules_rust//rust/platform:arm-unknown-linux-gnueabi": [],
|
||||||
|
"@rules_rust//rust/platform:arm-unknown-linux-musleabi": [],
|
||||||
|
"@rules_rust//rust/platform:armv7-linux-androideabi": [],
|
||||||
|
"@rules_rust//rust/platform:armv7-unknown-linux-gnueabi": [],
|
||||||
|
"@rules_rust//rust/platform:i686-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:i686-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:i686-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:i686-unknown-freebsd": [],
|
||||||
|
"@rules_rust//rust/platform:i686-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:loongarch64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:mips-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:powerpc-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:riscv32imac-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:riscv32imc-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:riscv64gc-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:riscv64gc-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:s390x-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-netbsd": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-openbsd": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv6m-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7em-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7em-none-eabihf": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7m-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv8m.main-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv8m.main-none-eabihf": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-unknown-emscripten": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-unknown-unknown": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip1": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip1-threads": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip2": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-ios": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-ios-macabi": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-freebsd": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-fuchsia": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-nixos-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-none": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-uefi": [],
|
||||||
|
"//conditions:default": ["@platforms//:incompatible"],
|
||||||
|
}),
|
||||||
|
version = "2.8.3",
|
||||||
|
)
|
||||||
8
third_party/crates/memchr-2.8.3/CONTRIBUTING.md
vendored
Normal file
8
third_party/crates/memchr-2.8.3/CONTRIBUTING.md
vendored
Normal file
@@ -0,0 +1,8 @@
|
|||||||
|
# Contributing
|
||||||
|
|
||||||
|
## Use of AI
|
||||||
|
|
||||||
|
All use of AI in contributions must follow the
|
||||||
|
[AI Policy](https://github.com/BurntSushi/jiff/blob/master/AI_POLICY.md).
|
||||||
|
|
||||||
|
Contributions not following the AI Policy will be closed.
|
||||||
3
third_party/crates/memchr-2.8.3/COPYING
vendored
Normal file
3
third_party/crates/memchr-2.8.3/COPYING
vendored
Normal file
@@ -0,0 +1,3 @@
|
|||||||
|
This project is dual-licensed under the Unlicense and MIT licenses.
|
||||||
|
|
||||||
|
You may use this code under the terms of either license.
|
||||||
80
third_party/crates/memchr-2.8.3/Cargo.lock
generated
vendored
Normal file
80
third_party/crates/memchr-2.8.3/Cargo.lock
generated
vendored
Normal file
@@ -0,0 +1,80 @@
|
|||||||
|
# This file is automatically @generated by Cargo.
|
||||||
|
# It is not intended for manual editing.
|
||||||
|
version = 3
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "cfg-if"
|
||||||
|
version = "1.0.3"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "2fd1289c04a9ea8cb22300a459a72a385d7c73d3259e2ed7dcb2af674838cfa9"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "getrandom"
|
||||||
|
version = "0.2.16"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "335ff9f135e4384c8150d6f27c6daed433577f86b4750418338c01a1a2528592"
|
||||||
|
dependencies = [
|
||||||
|
"cfg-if",
|
||||||
|
"libc",
|
||||||
|
"wasi",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "libc"
|
||||||
|
version = "0.2.176"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "58f929b4d672ea937a23a1ab494143d968337a5f47e56d0815df1e0890ddf174"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "log"
|
||||||
|
version = "0.4.28"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "34080505efa8e45a4b816c349525ebe327ceaa8559756f0356cba97ef3bf7432"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "memchr"
|
||||||
|
version = "2.8.3"
|
||||||
|
dependencies = [
|
||||||
|
"log",
|
||||||
|
"quickcheck",
|
||||||
|
"rustc-std-workspace-core",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "quickcheck"
|
||||||
|
version = "1.0.3"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "588f6378e4dd99458b60ec275b4477add41ce4fa9f64dcba6f15adccb19b50d6"
|
||||||
|
dependencies = [
|
||||||
|
"rand",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rand"
|
||||||
|
version = "0.8.5"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "34af8d1a0e25924bc5b7c43c079c942339d8f0a8b57c39049bef581b46327404"
|
||||||
|
dependencies = [
|
||||||
|
"rand_core",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rand_core"
|
||||||
|
version = "0.6.4"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "ec0be4795e2f6a28069bec0b5ff3e2ac9bafc99e6a9a7dc3547996c5c816922c"
|
||||||
|
dependencies = [
|
||||||
|
"getrandom",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rustc-std-workspace-core"
|
||||||
|
version = "1.0.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "aa9c45b374136f52f2d6311062c7146bff20fec063c3f5d46a410bd937746955"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "wasi"
|
||||||
|
version = "0.11.1+wasi-snapshot-preview1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "ccf3ec651a847eb01de73ccad15eb7d99f80485de043efb2f370cd654f4ea44b"
|
||||||
89
third_party/crates/memchr-2.8.3/Cargo.toml
vendored
Normal file
89
third_party/crates/memchr-2.8.3/Cargo.toml
vendored
Normal file
@@ -0,0 +1,89 @@
|
|||||||
|
# THIS FILE IS AUTOMATICALLY GENERATED BY CARGO
|
||||||
|
#
|
||||||
|
# When uploading crates to the registry Cargo will automatically
|
||||||
|
# "normalize" Cargo.toml files for maximal compatibility
|
||||||
|
# with all versions of Cargo and also rewrite `path` dependencies
|
||||||
|
# to registry (e.g., crates.io) dependencies.
|
||||||
|
#
|
||||||
|
# If you are reading this file be aware that the original Cargo.toml
|
||||||
|
# will likely look very different (and much more reasonable).
|
||||||
|
# See Cargo.toml.orig for the original contents.
|
||||||
|
|
||||||
|
[package]
|
||||||
|
edition = "2021"
|
||||||
|
rust-version = "1.61"
|
||||||
|
name = "memchr"
|
||||||
|
version = "2.8.3"
|
||||||
|
authors = [
|
||||||
|
"Andrew Gallant <jamslam@gmail.com>",
|
||||||
|
"bluss",
|
||||||
|
]
|
||||||
|
build = false
|
||||||
|
exclude = [
|
||||||
|
"/.github",
|
||||||
|
"/benchmarks",
|
||||||
|
"/fuzz",
|
||||||
|
"/scripts",
|
||||||
|
"/tmp",
|
||||||
|
]
|
||||||
|
autolib = false
|
||||||
|
autobins = false
|
||||||
|
autoexamples = false
|
||||||
|
autotests = false
|
||||||
|
autobenches = false
|
||||||
|
description = """
|
||||||
|
Provides extremely fast (uses SIMD on x86_64, aarch64 and wasm32) routines for
|
||||||
|
1, 2 or 3 byte search and single substring search.
|
||||||
|
"""
|
||||||
|
homepage = "https://github.com/BurntSushi/memchr"
|
||||||
|
documentation = "https://docs.rs/memchr/"
|
||||||
|
readme = "README.md"
|
||||||
|
keywords = [
|
||||||
|
"memchr",
|
||||||
|
"memmem",
|
||||||
|
"substring",
|
||||||
|
"find",
|
||||||
|
"search",
|
||||||
|
]
|
||||||
|
license = "Unlicense OR MIT"
|
||||||
|
repository = "https://github.com/BurntSushi/memchr"
|
||||||
|
|
||||||
|
[package.metadata.docs.rs]
|
||||||
|
rustdoc-args = ["--generate-link-to-definition"]
|
||||||
|
|
||||||
|
[features]
|
||||||
|
alloc = []
|
||||||
|
default = ["std"]
|
||||||
|
libc = []
|
||||||
|
logging = ["dep:log"]
|
||||||
|
rustc-dep-of-std = ["core"]
|
||||||
|
std = ["alloc"]
|
||||||
|
use_std = ["std"]
|
||||||
|
|
||||||
|
[lib]
|
||||||
|
name = "memchr"
|
||||||
|
path = "src/lib.rs"
|
||||||
|
bench = false
|
||||||
|
|
||||||
|
[dependencies.core]
|
||||||
|
version = "1.0.0"
|
||||||
|
optional = true
|
||||||
|
package = "rustc-std-workspace-core"
|
||||||
|
|
||||||
|
[dependencies.log]
|
||||||
|
version = "0.4.20"
|
||||||
|
optional = true
|
||||||
|
|
||||||
|
[dev-dependencies.quickcheck]
|
||||||
|
version = "1.0.3"
|
||||||
|
default-features = false
|
||||||
|
|
||||||
|
[profile.bench]
|
||||||
|
debug = 2
|
||||||
|
|
||||||
|
[profile.release]
|
||||||
|
debug = 2
|
||||||
|
|
||||||
|
[profile.test]
|
||||||
|
opt-level = 3
|
||||||
|
debug = 2
|
||||||
78
third_party/crates/memchr-2.8.3/Cargo.toml.orig
generated
vendored
Normal file
78
third_party/crates/memchr-2.8.3/Cargo.toml.orig
generated
vendored
Normal file
@@ -0,0 +1,78 @@
|
|||||||
|
[package]
|
||||||
|
name = "memchr"
|
||||||
|
version = "2.8.3" #:version
|
||||||
|
authors = ["Andrew Gallant <jamslam@gmail.com>", "bluss"]
|
||||||
|
description = """
|
||||||
|
Provides extremely fast (uses SIMD on x86_64, aarch64 and wasm32) routines for
|
||||||
|
1, 2 or 3 byte search and single substring search.
|
||||||
|
"""
|
||||||
|
documentation = "https://docs.rs/memchr/"
|
||||||
|
homepage = "https://github.com/BurntSushi/memchr"
|
||||||
|
repository = "https://github.com/BurntSushi/memchr"
|
||||||
|
readme = "README.md"
|
||||||
|
keywords = ["memchr", "memmem", "substring", "find", "search"]
|
||||||
|
license = "Unlicense OR MIT"
|
||||||
|
exclude = ["/.github", "/benchmarks", "/fuzz", "/scripts", "/tmp"]
|
||||||
|
edition = "2021"
|
||||||
|
rust-version = "1.61"
|
||||||
|
|
||||||
|
[lib]
|
||||||
|
name = "memchr"
|
||||||
|
bench = false
|
||||||
|
|
||||||
|
[features]
|
||||||
|
default = ["std"]
|
||||||
|
|
||||||
|
# The 'std' feature permits the memchr crate to use the standard library. This
|
||||||
|
# permits this crate to use runtime CPU feature detection to automatically
|
||||||
|
# accelerate searching via vector instructions. Without the standard library,
|
||||||
|
# this automatic detection is not possible.
|
||||||
|
std = ["alloc"]
|
||||||
|
|
||||||
|
# The 'alloc' feature enables some APIs that require allocation, such as
|
||||||
|
# 'Finder::into_owned'. Note that this feature does not enable runtime CPU
|
||||||
|
# feature detection. That still requires 'std'.
|
||||||
|
alloc = []
|
||||||
|
|
||||||
|
# When enabled (it's disabled by default), the `log` crate will be used to
|
||||||
|
# emit a spattering of log messages. For the most part, the log messages are
|
||||||
|
# meant to indicate what strategies are being employed. For example, whether
|
||||||
|
# a vector or a scalar algorithm is used for substring search. This can be
|
||||||
|
# useful when debugging performance problems.
|
||||||
|
#
|
||||||
|
# This is disabled by default.
|
||||||
|
logging = ["dep:log"]
|
||||||
|
|
||||||
|
# The 'use_std' feature is DEPRECATED. It will be removed in memchr 3. Until
|
||||||
|
# then, it is alias for the 'std' feature.
|
||||||
|
use_std = ["std"]
|
||||||
|
|
||||||
|
# The 'libc' feature has been DEPRECATED and no longer has any effect.
|
||||||
|
libc = []
|
||||||
|
|
||||||
|
# Internal feature, only used when building as part of libstd, not part of the
|
||||||
|
# stable interface of this crate.
|
||||||
|
rustc-dep-of-std = ['core']
|
||||||
|
|
||||||
|
[dependencies]
|
||||||
|
# Only used when the `logging` feature is enabled (disabled by default).
|
||||||
|
log = { version = "0.4.20", optional = true }
|
||||||
|
# Internal feature, only used when building as part of libstd, not part of the
|
||||||
|
# stable interface of this crate.
|
||||||
|
core = { version = '1.0.0', optional = true, package = 'rustc-std-workspace-core' }
|
||||||
|
|
||||||
|
[dev-dependencies]
|
||||||
|
quickcheck = { version = "1.0.3", default-features = false }
|
||||||
|
|
||||||
|
[profile.release]
|
||||||
|
debug = true
|
||||||
|
|
||||||
|
[profile.bench]
|
||||||
|
debug = true
|
||||||
|
|
||||||
|
[profile.test]
|
||||||
|
opt-level = 3
|
||||||
|
debug = true
|
||||||
|
|
||||||
|
[package.metadata.docs.rs]
|
||||||
|
rustdoc-args = ["--generate-link-to-definition"]
|
||||||
21
third_party/crates/memchr-2.8.3/LICENSE-MIT
vendored
Normal file
21
third_party/crates/memchr-2.8.3/LICENSE-MIT
vendored
Normal file
@@ -0,0 +1,21 @@
|
|||||||
|
The MIT License (MIT)
|
||||||
|
|
||||||
|
Copyright (c) 2015 Andrew Gallant
|
||||||
|
|
||||||
|
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||||
|
of this software and associated documentation files (the "Software"), to deal
|
||||||
|
in the Software without restriction, including without limitation the rights
|
||||||
|
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||||
|
copies of the Software, and to permit persons to whom the Software is
|
||||||
|
furnished to do so, subject to the following conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice shall be included in
|
||||||
|
all copies or substantial portions of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||||
|
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||||
|
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||||
|
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||||
|
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||||
|
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN
|
||||||
|
THE SOFTWARE.
|
||||||
196
third_party/crates/memchr-2.8.3/README.md
vendored
Normal file
196
third_party/crates/memchr-2.8.3/README.md
vendored
Normal file
@@ -0,0 +1,196 @@
|
|||||||
|
memchr
|
||||||
|
======
|
||||||
|
This library provides heavily optimized routines for string search primitives.
|
||||||
|
|
||||||
|
[](https://github.com/BurntSushi/memchr/actions)
|
||||||
|
[](https://crates.io/crates/memchr)
|
||||||
|
|
||||||
|
Dual-licensed under MIT or the [UNLICENSE](https://unlicense.org/).
|
||||||
|
|
||||||
|
|
||||||
|
### Documentation
|
||||||
|
|
||||||
|
[https://docs.rs/memchr](https://docs.rs/memchr)
|
||||||
|
|
||||||
|
|
||||||
|
### Overview
|
||||||
|
|
||||||
|
* The top-level module provides routines for searching for 1, 2 or 3 bytes
|
||||||
|
in the forward or reverse direction. When searching for more than one byte,
|
||||||
|
positions are considered a match if the byte at that position matches any
|
||||||
|
of the bytes.
|
||||||
|
* The `memmem` sub-module provides forward and reverse substring search
|
||||||
|
routines.
|
||||||
|
|
||||||
|
In all such cases, routines operate on `&[u8]` without regard to encoding. This
|
||||||
|
is exactly what you want when searching either UTF-8 or arbitrary bytes.
|
||||||
|
|
||||||
|
### Compiling without the standard library
|
||||||
|
|
||||||
|
memchr links to the standard library by default, but you can disable the
|
||||||
|
`std` feature if you want to use it in a `#![no_std]` crate:
|
||||||
|
|
||||||
|
```toml
|
||||||
|
[dependencies]
|
||||||
|
memchr = { version = "2", default-features = false }
|
||||||
|
```
|
||||||
|
|
||||||
|
On `x86_64` platforms, when the `std` feature is disabled, the SSE2 accelerated
|
||||||
|
implementations will be used. When `std` is enabled, AVX2 accelerated
|
||||||
|
implementations will be used if the CPU is determined to support it at runtime.
|
||||||
|
|
||||||
|
SIMD accelerated routines are also available on the `wasm32` and `aarch64`
|
||||||
|
targets. The `std` feature is not required to use them.
|
||||||
|
|
||||||
|
When a SIMD version is not available, then this crate falls back to
|
||||||
|
[SWAR](https://en.wikipedia.org/wiki/SWAR) techniques.
|
||||||
|
|
||||||
|
### Minimum Rust version policy
|
||||||
|
|
||||||
|
This crate's minimum supported `rustc` version is `1.61.0`.
|
||||||
|
|
||||||
|
The current policy is that the minimum Rust version required to use this crate
|
||||||
|
can be increased in minor version updates. For example, if `crate 1.0` requires
|
||||||
|
Rust 1.20.0, then `crate 1.0.z` for all values of `z` will also require Rust
|
||||||
|
1.20.0 or newer. However, `crate 1.y` for `y > 0` may require a newer minimum
|
||||||
|
version of Rust.
|
||||||
|
|
||||||
|
In general, this crate will be conservative with respect to the minimum
|
||||||
|
supported version of Rust.
|
||||||
|
|
||||||
|
|
||||||
|
### Testing strategy
|
||||||
|
|
||||||
|
Given the complexity of the code in this crate, along with the pervasive use
|
||||||
|
of `unsafe`, this crate has an extensive testing strategy. It combines multiple
|
||||||
|
approaches:
|
||||||
|
|
||||||
|
* Hand-written tests.
|
||||||
|
* Exhaustive-style testing meant to exercise all possible branching and offset
|
||||||
|
calculations.
|
||||||
|
* Property based testing through [`quickcheck`](https://github.com/BurntSushi/quickcheck).
|
||||||
|
* Fuzz testing through [`cargo fuzz`](https://github.com/rust-fuzz/cargo-fuzz).
|
||||||
|
* A huge suite of benchmarks that are also run as tests. Benchmarks always
|
||||||
|
confirm that the expected result occurs.
|
||||||
|
|
||||||
|
Improvements to the testing infrastructure are very welcome.
|
||||||
|
|
||||||
|
|
||||||
|
### Algorithms used
|
||||||
|
|
||||||
|
At time of writing, this crate's implementation of substring search actually
|
||||||
|
has a few different algorithms to choose from depending on the situation.
|
||||||
|
|
||||||
|
* For very small haystacks,
|
||||||
|
[Rabin-Karp](https://en.wikipedia.org/wiki/Rabin%E2%80%93Karp_algorithm)
|
||||||
|
is used to reduce latency. Rabin-Karp has very small overhead and can often
|
||||||
|
complete before other searchers have even been constructed.
|
||||||
|
* For small needles, a variant of the
|
||||||
|
["Generic SIMD"](http://0x80.pl/articles/simd-strfind.html#algorithm-1-generic-simd)
|
||||||
|
algorithm is used. Instead of using the first and last bytes, a heuristic is
|
||||||
|
used to select bytes based on a background distribution of byte frequencies.
|
||||||
|
* In all other cases,
|
||||||
|
[Two-Way](https://en.wikipedia.org/wiki/Two-way_string-matching_algorithm)
|
||||||
|
is used. If possible, a prefilter based on the "Generic SIMD" algorithm
|
||||||
|
linked above is used to find candidates quickly. A dynamic heuristic is used
|
||||||
|
to detect if the prefilter is ineffective, and if so, disables it.
|
||||||
|
|
||||||
|
|
||||||
|
### Why is the standard library's substring search so much slower?
|
||||||
|
|
||||||
|
We'll start by establishing what the difference in performance actually
|
||||||
|
is. There are two relevant benchmark classes to consider: `prebuilt` and
|
||||||
|
`oneshot`. The `prebuilt` benchmarks are designed to measure---to the extent
|
||||||
|
possible---search time only. That is, the benchmark first starts by building a
|
||||||
|
searcher and then only tracking the time for _using_ the searcher:
|
||||||
|
|
||||||
|
```
|
||||||
|
$ rebar rank benchmarks/record/x86_64/2023-08-26.csv --intersection -e memchr/memmem/prebuilt -e std/memmem/prebuilt
|
||||||
|
Engine Version Geometric mean of speed ratios Benchmark count
|
||||||
|
------ ------- ------------------------------ ---------------
|
||||||
|
rust/memchr/memmem/prebuilt 2.5.0 1.03 53
|
||||||
|
rust/std/memmem/prebuilt 1.73.0-nightly 180dffba1 6.50 53
|
||||||
|
```
|
||||||
|
|
||||||
|
Conversely, the `oneshot` benchmark class measures the time it takes to both
|
||||||
|
build the searcher _and_ use it:
|
||||||
|
|
||||||
|
```
|
||||||
|
$ rebar rank benchmarks/record/x86_64/2023-08-26.csv --intersection -e memchr/memmem/oneshot -e std/memmem/oneshot
|
||||||
|
Engine Version Geometric mean of speed ratios Benchmark count
|
||||||
|
------ ------- ------------------------------ ---------------
|
||||||
|
rust/memchr/memmem/oneshot 2.5.0 1.04 53
|
||||||
|
rust/std/memmem/oneshot 1.73.0-nightly 180dffba1 5.26 53
|
||||||
|
```
|
||||||
|
|
||||||
|
**NOTE:** Replace `rebar rank` with `rebar cmp` in the above commands to
|
||||||
|
explore the specific benchmarks and their differences.
|
||||||
|
|
||||||
|
So in both cases, this crate is quite a bit faster over a broad sampling of
|
||||||
|
benchmarks regardless of whether you measure only search time or search time
|
||||||
|
plus construction time. The difference is a little smaller when you include
|
||||||
|
construction time in your measurements.
|
||||||
|
|
||||||
|
These two different types of benchmark classes make for a nice segue into
|
||||||
|
one reason why the standard library's substring search can be slower: API
|
||||||
|
design. In the standard library, the only APIs available to you require
|
||||||
|
one to re-construct the searcher for every search. While you can benefit
|
||||||
|
from building a searcher once and iterating over all matches in a single
|
||||||
|
string, you cannot reuse that searcher to search other strings. This might
|
||||||
|
come up when, for example, searching a file one line at a time. You'll need
|
||||||
|
to re-build the searcher for every line searched, and this can [really
|
||||||
|
matter][burntsushi-bstr-blog].
|
||||||
|
|
||||||
|
**NOTE:** The `prebuilt` benchmark for the standard library can't actually
|
||||||
|
avoid measuring searcher construction at some level, because there is no API
|
||||||
|
for it. Instead, the benchmark consists of building the searcher once and then
|
||||||
|
finding all matches in a single string via an iterator. This tends to
|
||||||
|
approximate a benchmark where searcher construction isn't measured, but it
|
||||||
|
isn't perfect. While this means the comparison is not strictly
|
||||||
|
apples-to-apples, it does reflect what is maximally possible with the standard
|
||||||
|
library, and thus reflects the best that one could do in a real world scenario.
|
||||||
|
|
||||||
|
While there is more to the story than just API design here, it's important to
|
||||||
|
point out that even if the standard library's substring search were a precise
|
||||||
|
clone of this crate internally, it would still be at a disadvantage in some
|
||||||
|
workloads because of its API. (The same also applies to C's standard library
|
||||||
|
`memmem` function. There is no way to amortize construction of the searcher.
|
||||||
|
You need to pay for it on every call.)
|
||||||
|
|
||||||
|
The other reason for the difference in performance is that
|
||||||
|
the standard library has trouble using SIMD. In particular, substring search
|
||||||
|
is implemented in the `core` library, where platform specific code generally
|
||||||
|
can't exist. That's an issue because in order to utilize SIMD beyond SSE2
|
||||||
|
while maintaining portable binaries, one needs to use [dynamic CPU feature
|
||||||
|
detection][dynamic-cpu], and that in turn requires platform specific code.
|
||||||
|
While there is [an RFC for enabling target feature detection in
|
||||||
|
`core`][core-feature], it doesn't yet exist.
|
||||||
|
|
||||||
|
The bottom line here is that `core`'s substring search implementation is
|
||||||
|
limited to making use of SSE2, but not AVX.
|
||||||
|
|
||||||
|
Still though, this crate does accelerate substring search even when only SSE2
|
||||||
|
is available. The standard library could therefore adopt the techniques in this
|
||||||
|
crate just for SSE2. The reason why that hasn't happened yet isn't totally
|
||||||
|
clear to me. It likely needs a champion to push it through. The standard
|
||||||
|
library tends to be more conservative in these things. With that said, the
|
||||||
|
standard library does use some [SSE2 acceleration on `x86-64`][std-sse2] added
|
||||||
|
in [this PR][std-sse2-pr]. However, at the time of writing, it is only used
|
||||||
|
for short needles and doesn't use the frequency based heuristics found in this
|
||||||
|
crate.
|
||||||
|
|
||||||
|
**NOTE:** Another thing worth mentioning is that the standard library's
|
||||||
|
substring search routine requires that both the needle and haystack have type
|
||||||
|
`&str`. Unless you can assume that your data is valid UTF-8, building a `&str`
|
||||||
|
will come with the overhead of UTF-8 validation. This may in turn result in
|
||||||
|
overall slower searching depending on your workload. In contrast, the `memchr`
|
||||||
|
crate permits both the needle and the haystack to have type `&[u8]`, where
|
||||||
|
`&[u8]` can be created from a `&str` with zero cost. Therefore, the substring
|
||||||
|
search in this crate is strictly more flexible than what the standard library
|
||||||
|
provides.
|
||||||
|
|
||||||
|
[burntsushi-bstr-blog]: https://blog.burntsushi.net/bstr/#motivation-based-on-performance
|
||||||
|
[dynamic-cpu]: https://doc.rust-lang.org/std/arch/index.html#dynamic-cpu-feature-detection
|
||||||
|
[core-feature]: https://github.com/rust-lang/rfcs/pull/3469
|
||||||
|
[std-sse2]: https://github.com/rust-lang/rust/blob/bf9229a2e366b4c311f059014a4aa08af16de5d8/library/core/src/str/pattern.rs#L1719-L1857
|
||||||
|
[std-sse2-pr]: https://github.com/rust-lang/rust/pull/103779
|
||||||
24
third_party/crates/memchr-2.8.3/UNLICENSE
vendored
Normal file
24
third_party/crates/memchr-2.8.3/UNLICENSE
vendored
Normal file
@@ -0,0 +1,24 @@
|
|||||||
|
This is free and unencumbered software released into the public domain.
|
||||||
|
|
||||||
|
Anyone is free to copy, modify, publish, use, compile, sell, or
|
||||||
|
distribute this software, either in source code form or as a compiled
|
||||||
|
binary, for any purpose, commercial or non-commercial, and by any
|
||||||
|
means.
|
||||||
|
|
||||||
|
In jurisdictions that recognize copyright laws, the author or authors
|
||||||
|
of this software dedicate any and all copyright interest in the
|
||||||
|
software to the public domain. We make this dedication for the benefit
|
||||||
|
of the public at large and to the detriment of our heirs and
|
||||||
|
successors. We intend this dedication to be an overt act of
|
||||||
|
relinquishment in perpetuity of all present and future rights to this
|
||||||
|
software under copyright law.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND,
|
||||||
|
EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF
|
||||||
|
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT.
|
||||||
|
IN NO EVENT SHALL THE AUTHORS BE LIABLE FOR ANY CLAIM, DAMAGES OR
|
||||||
|
OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE,
|
||||||
|
ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR
|
||||||
|
OTHER DEALINGS IN THE SOFTWARE.
|
||||||
|
|
||||||
|
For more information, please refer to <http://unlicense.org/>
|
||||||
2
third_party/crates/memchr-2.8.3/rustfmt.toml
vendored
Normal file
2
third_party/crates/memchr-2.8.3/rustfmt.toml
vendored
Normal file
@@ -0,0 +1,2 @@
|
|||||||
|
max_width = 79
|
||||||
|
use_small_heuristics = "max"
|
||||||
137
third_party/crates/memchr-2.8.3/src/arch/aarch64/memchr.rs
vendored
Normal file
137
third_party/crates/memchr-2.8.3/src/arch/aarch64/memchr.rs
vendored
Normal file
@@ -0,0 +1,137 @@
|
|||||||
|
/*!
|
||||||
|
Wrapper routines for `memchr` and friends.
|
||||||
|
|
||||||
|
These routines choose the best implementation at compile time. (This is
|
||||||
|
different from `x86_64` because it is expected that `neon` is almost always
|
||||||
|
available for `aarch64` targets.)
|
||||||
|
*/
|
||||||
|
|
||||||
|
macro_rules! defraw {
|
||||||
|
($ty:ident, $find:ident, $start:ident, $end:ident, $($needles:ident),+) => {{
|
||||||
|
#[cfg(target_feature = "neon")]
|
||||||
|
{
|
||||||
|
use crate::arch::aarch64::neon::memchr::$ty;
|
||||||
|
|
||||||
|
debug!("chose neon for {}", stringify!($ty));
|
||||||
|
debug_assert!($ty::is_available());
|
||||||
|
// SAFETY: We know that wasm memchr is always available whenever
|
||||||
|
// code is compiled for `aarch64` with the `neon` target feature
|
||||||
|
// enabled.
|
||||||
|
$ty::new_unchecked($($needles),+).$find($start, $end)
|
||||||
|
}
|
||||||
|
#[cfg(not(target_feature = "neon"))]
|
||||||
|
{
|
||||||
|
use crate::arch::all::memchr::$ty;
|
||||||
|
|
||||||
|
debug!(
|
||||||
|
"no neon feature available, using fallback for {}",
|
||||||
|
stringify!($ty),
|
||||||
|
);
|
||||||
|
$ty::new($($needles),+).$find($start, $end)
|
||||||
|
}
|
||||||
|
}}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(One, find_raw, start, end, n1)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(One, rfind_raw, start, end, n1)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr2_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Two, find_raw, start, end, n1, n2)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr2_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Two, rfind_raw, start, end, n1, n2)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr3_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Three, find_raw, start, end, n1, n2, n3)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr3_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Three, rfind_raw, start, end, n1, n2, n3)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Count all matching bytes, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::count_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn count_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> usize {
|
||||||
|
defraw!(One, count_raw, start, end, n1)
|
||||||
|
}
|
||||||
7
third_party/crates/memchr-2.8.3/src/arch/aarch64/mod.rs
vendored
Normal file
7
third_party/crates/memchr-2.8.3/src/arch/aarch64/mod.rs
vendored
Normal file
@@ -0,0 +1,7 @@
|
|||||||
|
/*!
|
||||||
|
Vector algorithms for the `aarch64` target.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod neon;
|
||||||
|
|
||||||
|
pub(crate) mod memchr;
|
||||||
1031
third_party/crates/memchr-2.8.3/src/arch/aarch64/neon/memchr.rs
vendored
Normal file
1031
third_party/crates/memchr-2.8.3/src/arch/aarch64/neon/memchr.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
6
third_party/crates/memchr-2.8.3/src/arch/aarch64/neon/mod.rs
vendored
Normal file
6
third_party/crates/memchr-2.8.3/src/arch/aarch64/neon/mod.rs
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
/*!
|
||||||
|
Algorithms for the `aarch64` target using 128-bit vectors via NEON.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod memchr;
|
||||||
|
pub mod packedpair;
|
||||||
236
third_party/crates/memchr-2.8.3/src/arch/aarch64/neon/packedpair.rs
vendored
Normal file
236
third_party/crates/memchr-2.8.3/src/arch/aarch64/neon/packedpair.rs
vendored
Normal file
@@ -0,0 +1,236 @@
|
|||||||
|
/*!
|
||||||
|
A 128-bit vector implementation of the "packed pair" SIMD algorithm.
|
||||||
|
|
||||||
|
The "packed pair" algorithm is based on the [generic SIMD] algorithm. The main
|
||||||
|
difference is that it (by default) uses a background distribution of byte
|
||||||
|
frequencies to heuristically select the pair of bytes to search for.
|
||||||
|
|
||||||
|
[generic SIMD]: http://0x80.pl/articles/simd-strfind.html#first-and-last
|
||||||
|
*/
|
||||||
|
|
||||||
|
use core::arch::aarch64::uint8x16_t;
|
||||||
|
|
||||||
|
use crate::arch::{all::packedpair::Pair, generic::packedpair};
|
||||||
|
|
||||||
|
/// A "packed pair" finder that uses 128-bit vector operations.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power
|
||||||
|
/// for indicating an overall match of a needle. Depending on whether
|
||||||
|
/// `Finder::find` or `Finder::find_prefilter` is used, it reports offsets
|
||||||
|
/// where the needle matches or could match. In the prefilter case, candidates
|
||||||
|
/// are reported whenever the [`Pair`] of bytes given matches.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Finder(packedpair::Finder<uint8x16_t>);
|
||||||
|
|
||||||
|
/// A "packed pair" finder that uses 128-bit vector operations.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power
|
||||||
|
/// for indicating an overall match of a needle. Depending on whether
|
||||||
|
/// `Finder::find` or `Finder::find_prefilter` is used, it reports offsets
|
||||||
|
/// where the needle matches or could match. In the prefilter case, candidates
|
||||||
|
/// are reported whenever the [`Pair`] of bytes given matches.
|
||||||
|
impl Finder {
|
||||||
|
/// Create a new pair searcher. The searcher returned can either report
|
||||||
|
/// exact matches of `needle` or act as a prefilter and report candidate
|
||||||
|
/// positions of `needle`.
|
||||||
|
///
|
||||||
|
/// If neon is unavailable in the current environment or if a [`Pair`]
|
||||||
|
/// could not be constructed from the needle given, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Finder> {
|
||||||
|
Finder::with_pair(needle, Pair::new(needle)?)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new "packed pair" finder using the pair of bytes given.
|
||||||
|
///
|
||||||
|
/// This constructor permits callers to control precisely which pair of
|
||||||
|
/// bytes is used as a predicate.
|
||||||
|
///
|
||||||
|
/// If neon is unavailable in the current environment, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_pair(needle: &[u8], pair: Pair) -> Option<Finder> {
|
||||||
|
if Finder::is_available() {
|
||||||
|
// SAFETY: we check that NEON is available above. We are also
|
||||||
|
// guaranteed to have needle.len() > 1 because we have a valid
|
||||||
|
// Pair.
|
||||||
|
unsafe { Some(Finder::with_pair_impl(needle, pair)) }
|
||||||
|
} else {
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new `Finder` specific to neon vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same as the safety for `packedpair::Finder::new`, and callers must also
|
||||||
|
/// ensure that neon is available.
|
||||||
|
#[target_feature(enable = "neon")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn with_pair_impl(needle: &[u8], pair: Pair) -> Finder {
|
||||||
|
let finder = packedpair::Finder::<uint8x16_t>::new(needle, pair);
|
||||||
|
Finder(finder)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns true when this implementation is available in the current
|
||||||
|
/// environment.
|
||||||
|
///
|
||||||
|
/// When this is true, it is guaranteed that [`Finder::with_pair`] will
|
||||||
|
/// return a `Some` value. Similarly, when it is false, it is guaranteed
|
||||||
|
/// that `Finder::with_pair` will return a `None` value. Notice that this
|
||||||
|
/// does not guarantee that [`Finder::new`] will return a `Finder`. Namely,
|
||||||
|
/// even when `Finder::is_available` is true, it is not guaranteed that a
|
||||||
|
/// valid [`Pair`] can be found from the needle given.
|
||||||
|
///
|
||||||
|
/// Note also that for the lifetime of a single program, if this returns
|
||||||
|
/// true then it will always return true.
|
||||||
|
#[inline]
|
||||||
|
pub fn is_available() -> bool {
|
||||||
|
#[cfg(target_feature = "neon")]
|
||||||
|
{
|
||||||
|
true
|
||||||
|
}
|
||||||
|
#[cfg(not(target_feature = "neon"))]
|
||||||
|
{
|
||||||
|
false
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using neon vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: Building a `Finder` means it's safe to call 'neon' routines.
|
||||||
|
unsafe { self.find_impl(haystack, needle) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using neon vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find_prefilter(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: Building a `Finder` means it's safe to call 'neon' routines.
|
||||||
|
unsafe { self.find_prefilter_impl(haystack) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using neon vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `neon` routines.)
|
||||||
|
#[target_feature(enable = "neon")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn find_impl(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
self.0.find(haystack, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a prefilter search using neon vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `neon` routines.)
|
||||||
|
#[target_feature(enable = "neon")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn find_prefilter_impl(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
self.0.find_prefilter(haystack)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the pair of offsets (into the needle) used to check as a
|
||||||
|
/// predicate before confirming whether a needle exists at a particular
|
||||||
|
/// position.
|
||||||
|
#[inline]
|
||||||
|
pub fn pair(&self) -> &Pair {
|
||||||
|
self.0.pair()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the minimum haystack length that this `Finder` can search.
|
||||||
|
///
|
||||||
|
/// Using a haystack with length smaller than this in a search will result
|
||||||
|
/// in a panic. The reason for this restriction is that this finder is
|
||||||
|
/// meant to be a low-level component that is part of a larger substring
|
||||||
|
/// strategy. In that sense, it avoids trying to handle all cases and
|
||||||
|
/// instead only handles the cases that it can handle very well.
|
||||||
|
#[inline]
|
||||||
|
pub fn min_haystack_len(&self) -> usize {
|
||||||
|
self.0.min_haystack_len()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
fn find(haystack: &[u8], needle: &[u8]) -> Option<Option<usize>> {
|
||||||
|
let f = Finder::new(needle)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(find);
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_substring() {
|
||||||
|
crate::tests::substring::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair_prefilter() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find_prefilter(haystack))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
}
|
||||||
1022
third_party/crates/memchr-2.8.3/src/arch/all/memchr.rs
vendored
Normal file
1022
third_party/crates/memchr-2.8.3/src/arch/all/memchr.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
234
third_party/crates/memchr-2.8.3/src/arch/all/mod.rs
vendored
Normal file
234
third_party/crates/memchr-2.8.3/src/arch/all/mod.rs
vendored
Normal file
@@ -0,0 +1,234 @@
|
|||||||
|
/*!
|
||||||
|
Contains architecture independent routines.
|
||||||
|
|
||||||
|
These routines are often used as a "fallback" implementation when the more
|
||||||
|
specialized architecture dependent routines are unavailable.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod memchr;
|
||||||
|
pub mod packedpair;
|
||||||
|
pub mod rabinkarp;
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
pub mod shiftor;
|
||||||
|
pub mod twoway;
|
||||||
|
|
||||||
|
/// Returns true if and only if `needle` is a prefix of `haystack`.
|
||||||
|
///
|
||||||
|
/// This uses a latency optimized variant of `memcmp` internally which *might*
|
||||||
|
/// make this faster for very short strings.
|
||||||
|
///
|
||||||
|
/// # Inlining
|
||||||
|
///
|
||||||
|
/// This routine is marked `inline(always)`. If you want to call this function
|
||||||
|
/// in a way that is not always inlined, you'll need to wrap a call to it in
|
||||||
|
/// another function that is marked as `inline(never)` or just `inline`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub fn is_prefix(haystack: &[u8], needle: &[u8]) -> bool {
|
||||||
|
needle.len() <= haystack.len()
|
||||||
|
&& is_equal(&haystack[..needle.len()], needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns true if and only if `needle` is a suffix of `haystack`.
|
||||||
|
///
|
||||||
|
/// This uses a latency optimized variant of `memcmp` internally which *might*
|
||||||
|
/// make this faster for very short strings.
|
||||||
|
///
|
||||||
|
/// # Inlining
|
||||||
|
///
|
||||||
|
/// This routine is marked `inline(always)`. If you want to call this function
|
||||||
|
/// in a way that is not always inlined, you'll need to wrap a call to it in
|
||||||
|
/// another function that is marked as `inline(never)` or just `inline`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub fn is_suffix(haystack: &[u8], needle: &[u8]) -> bool {
|
||||||
|
needle.len() <= haystack.len()
|
||||||
|
&& is_equal(&haystack[haystack.len() - needle.len()..], needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Compare corresponding bytes in `x` and `y` for equality.
|
||||||
|
///
|
||||||
|
/// That is, this returns true if and only if `x.len() == y.len()` and
|
||||||
|
/// `x[i] == y[i]` for all `0 <= i < x.len()`.
|
||||||
|
///
|
||||||
|
/// # Inlining
|
||||||
|
///
|
||||||
|
/// This routine is marked `inline(always)`. If you want to call this function
|
||||||
|
/// in a way that is not always inlined, you'll need to wrap a call to it in
|
||||||
|
/// another function that is marked as `inline(never)` or just `inline`.
|
||||||
|
///
|
||||||
|
/// # Motivation
|
||||||
|
///
|
||||||
|
/// Why not use slice equality instead? Well, slice equality usually results in
|
||||||
|
/// a call out to the current platform's `libc` which might not be inlineable
|
||||||
|
/// or have other overhead. This routine isn't guaranteed to be a win, but it
|
||||||
|
/// might be in some cases.
|
||||||
|
#[inline(always)]
|
||||||
|
pub fn is_equal(x: &[u8], y: &[u8]) -> bool {
|
||||||
|
if x.len() != y.len() {
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
// SAFETY: Our pointers are derived directly from borrowed slices which
|
||||||
|
// uphold all of our safety guarantees except for length. We account for
|
||||||
|
// length with the check above.
|
||||||
|
unsafe { is_equal_raw(x.as_ptr(), y.as_ptr(), x.len()) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Compare `n` bytes at the given pointers for equality.
|
||||||
|
///
|
||||||
|
/// This returns true if and only if `*x.add(i) == *y.add(i)` for all
|
||||||
|
/// `0 <= i < n`.
|
||||||
|
///
|
||||||
|
/// # Inlining
|
||||||
|
///
|
||||||
|
/// This routine is marked `inline(always)`. If you want to call this function
|
||||||
|
/// in a way that is not always inlined, you'll need to wrap a call to it in
|
||||||
|
/// another function that is marked as `inline(never)` or just `inline`.
|
||||||
|
///
|
||||||
|
/// # Motivation
|
||||||
|
///
|
||||||
|
/// Why not use slice equality instead? Well, slice equality usually results in
|
||||||
|
/// a call out to the current platform's `libc` which might not be inlineable
|
||||||
|
/// or have other overhead. This routine isn't guaranteed to be a win, but it
|
||||||
|
/// might be in some cases.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// * Both `x` and `y` must be valid for reads of up to `n` bytes.
|
||||||
|
/// * Both `x` and `y` must point to an initialized value.
|
||||||
|
/// * Both `x` and `y` must each point to an allocated object and
|
||||||
|
/// must either be in bounds or at most one byte past the end of the
|
||||||
|
/// allocated object. `x` and `y` do not need to point to the same allocated
|
||||||
|
/// object, but they may.
|
||||||
|
/// * Both `x` and `y` must be _derived from_ a pointer to their respective
|
||||||
|
/// allocated objects.
|
||||||
|
/// * The distance between `x` and `x+n` must not overflow `isize`. Similarly
|
||||||
|
/// for `y` and `y+n`.
|
||||||
|
/// * The distance being in bounds must not rely on "wrapping around" the
|
||||||
|
/// address space.
|
||||||
|
#[inline(always)]
|
||||||
|
pub unsafe fn is_equal_raw(
|
||||||
|
mut x: *const u8,
|
||||||
|
mut y: *const u8,
|
||||||
|
mut n: usize,
|
||||||
|
) -> bool {
|
||||||
|
// When we have 4 or more bytes to compare, then proceed in chunks of 4 at
|
||||||
|
// a time using unaligned loads.
|
||||||
|
//
|
||||||
|
// Also, why do 4 byte loads instead of, say, 8 byte loads? The reason is
|
||||||
|
// that this particular version of memcmp is likely to be called with tiny
|
||||||
|
// needles. That means that if we do 8 byte loads, then a higher proportion
|
||||||
|
// of memcmp calls will use the slower variant above. With that said, this
|
||||||
|
// is a hypothesis and is only loosely supported by benchmarks. There's
|
||||||
|
// likely some improvement that could be made here. The main thing here
|
||||||
|
// though is to optimize for latency, not throughput.
|
||||||
|
|
||||||
|
// SAFETY: The caller is responsible for ensuring the pointers we get are
|
||||||
|
// valid and readable for at least `n` bytes. We also do unaligned loads,
|
||||||
|
// so there's no need to ensure we're aligned. (This is justified by this
|
||||||
|
// routine being specifically for short strings.)
|
||||||
|
while n >= 4 {
|
||||||
|
let vx = x.cast::<u32>().read_unaligned();
|
||||||
|
let vy = y.cast::<u32>().read_unaligned();
|
||||||
|
if vx != vy {
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
x = x.add(4);
|
||||||
|
y = y.add(4);
|
||||||
|
n -= 4;
|
||||||
|
}
|
||||||
|
// If we don't have enough bytes to do 4-byte at a time loads, then
|
||||||
|
// do partial loads. Note that I used to have a byte-at-a-time
|
||||||
|
// loop here and that turned out to be quite a bit slower for the
|
||||||
|
// memmem/pathological/defeat-simple-vector-alphabet benchmark.
|
||||||
|
if n >= 2 {
|
||||||
|
let vx = x.cast::<u16>().read_unaligned();
|
||||||
|
let vy = y.cast::<u16>().read_unaligned();
|
||||||
|
if vx != vy {
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
x = x.add(2);
|
||||||
|
y = y.add(2);
|
||||||
|
n -= 2;
|
||||||
|
}
|
||||||
|
if n > 0 {
|
||||||
|
if x.read() != y.read() {
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
true
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn equals_different_lengths() {
|
||||||
|
assert!(!is_equal(b"", b"a"));
|
||||||
|
assert!(!is_equal(b"a", b""));
|
||||||
|
assert!(!is_equal(b"ab", b"a"));
|
||||||
|
assert!(!is_equal(b"a", b"ab"));
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn equals_mismatch() {
|
||||||
|
let one_mismatch = [
|
||||||
|
(&b"a"[..], &b"x"[..]),
|
||||||
|
(&b"ab"[..], &b"ax"[..]),
|
||||||
|
(&b"abc"[..], &b"abx"[..]),
|
||||||
|
(&b"abcd"[..], &b"abcx"[..]),
|
||||||
|
(&b"abcde"[..], &b"abcdx"[..]),
|
||||||
|
(&b"abcdef"[..], &b"abcdex"[..]),
|
||||||
|
(&b"abcdefg"[..], &b"abcdefx"[..]),
|
||||||
|
(&b"abcdefgh"[..], &b"abcdefgx"[..]),
|
||||||
|
(&b"abcdefghi"[..], &b"abcdefghx"[..]),
|
||||||
|
(&b"abcdefghij"[..], &b"abcdefghix"[..]),
|
||||||
|
(&b"abcdefghijk"[..], &b"abcdefghijx"[..]),
|
||||||
|
(&b"abcdefghijkl"[..], &b"abcdefghijkx"[..]),
|
||||||
|
(&b"abcdefghijklm"[..], &b"abcdefghijklx"[..]),
|
||||||
|
(&b"abcdefghijklmn"[..], &b"abcdefghijklmx"[..]),
|
||||||
|
];
|
||||||
|
for (x, y) in one_mismatch {
|
||||||
|
assert_eq!(x.len(), y.len(), "lengths should match");
|
||||||
|
assert!(!is_equal(x, y));
|
||||||
|
assert!(!is_equal(y, x));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn equals_yes() {
|
||||||
|
assert!(is_equal(b"", b""));
|
||||||
|
assert!(is_equal(b"a", b"a"));
|
||||||
|
assert!(is_equal(b"ab", b"ab"));
|
||||||
|
assert!(is_equal(b"abc", b"abc"));
|
||||||
|
assert!(is_equal(b"abcd", b"abcd"));
|
||||||
|
assert!(is_equal(b"abcde", b"abcde"));
|
||||||
|
assert!(is_equal(b"abcdef", b"abcdef"));
|
||||||
|
assert!(is_equal(b"abcdefg", b"abcdefg"));
|
||||||
|
assert!(is_equal(b"abcdefgh", b"abcdefgh"));
|
||||||
|
assert!(is_equal(b"abcdefghi", b"abcdefghi"));
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn prefix() {
|
||||||
|
assert!(is_prefix(b"", b""));
|
||||||
|
assert!(is_prefix(b"a", b""));
|
||||||
|
assert!(is_prefix(b"ab", b""));
|
||||||
|
assert!(is_prefix(b"foo", b"foo"));
|
||||||
|
assert!(is_prefix(b"foobar", b"foo"));
|
||||||
|
|
||||||
|
assert!(!is_prefix(b"foo", b"fob"));
|
||||||
|
assert!(!is_prefix(b"foobar", b"fob"));
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn suffix() {
|
||||||
|
assert!(is_suffix(b"", b""));
|
||||||
|
assert!(is_suffix(b"a", b""));
|
||||||
|
assert!(is_suffix(b"ab", b""));
|
||||||
|
assert!(is_suffix(b"foo", b"foo"));
|
||||||
|
assert!(is_suffix(b"foobar", b"bar"));
|
||||||
|
|
||||||
|
assert!(!is_suffix(b"foo", b"goo"));
|
||||||
|
assert!(!is_suffix(b"foobar", b"gar"));
|
||||||
|
}
|
||||||
|
}
|
||||||
258
third_party/crates/memchr-2.8.3/src/arch/all/packedpair/default_rank.rs
vendored
Normal file
258
third_party/crates/memchr-2.8.3/src/arch/all/packedpair/default_rank.rs
vendored
Normal file
@@ -0,0 +1,258 @@
|
|||||||
|
pub(crate) const RANK: [u8; 256] = [
|
||||||
|
55, // '\x00'
|
||||||
|
52, // '\x01'
|
||||||
|
51, // '\x02'
|
||||||
|
50, // '\x03'
|
||||||
|
49, // '\x04'
|
||||||
|
48, // '\x05'
|
||||||
|
47, // '\x06'
|
||||||
|
46, // '\x07'
|
||||||
|
45, // '\x08'
|
||||||
|
103, // '\t'
|
||||||
|
242, // '\n'
|
||||||
|
66, // '\x0b'
|
||||||
|
67, // '\x0c'
|
||||||
|
229, // '\r'
|
||||||
|
44, // '\x0e'
|
||||||
|
43, // '\x0f'
|
||||||
|
42, // '\x10'
|
||||||
|
41, // '\x11'
|
||||||
|
40, // '\x12'
|
||||||
|
39, // '\x13'
|
||||||
|
38, // '\x14'
|
||||||
|
37, // '\x15'
|
||||||
|
36, // '\x16'
|
||||||
|
35, // '\x17'
|
||||||
|
34, // '\x18'
|
||||||
|
33, // '\x19'
|
||||||
|
56, // '\x1a'
|
||||||
|
32, // '\x1b'
|
||||||
|
31, // '\x1c'
|
||||||
|
30, // '\x1d'
|
||||||
|
29, // '\x1e'
|
||||||
|
28, // '\x1f'
|
||||||
|
255, // ' '
|
||||||
|
148, // '!'
|
||||||
|
164, // '"'
|
||||||
|
149, // '#'
|
||||||
|
136, // '$'
|
||||||
|
160, // '%'
|
||||||
|
155, // '&'
|
||||||
|
173, // "'"
|
||||||
|
221, // '('
|
||||||
|
222, // ')'
|
||||||
|
134, // '*'
|
||||||
|
122, // '+'
|
||||||
|
232, // ','
|
||||||
|
202, // '-'
|
||||||
|
215, // '.'
|
||||||
|
224, // '/'
|
||||||
|
208, // '0'
|
||||||
|
220, // '1'
|
||||||
|
204, // '2'
|
||||||
|
187, // '3'
|
||||||
|
183, // '4'
|
||||||
|
179, // '5'
|
||||||
|
177, // '6'
|
||||||
|
168, // '7'
|
||||||
|
178, // '8'
|
||||||
|
200, // '9'
|
||||||
|
226, // ':'
|
||||||
|
195, // ';'
|
||||||
|
154, // '<'
|
||||||
|
184, // '='
|
||||||
|
174, // '>'
|
||||||
|
126, // '?'
|
||||||
|
120, // '@'
|
||||||
|
191, // 'A'
|
||||||
|
157, // 'B'
|
||||||
|
194, // 'C'
|
||||||
|
170, // 'D'
|
||||||
|
189, // 'E'
|
||||||
|
162, // 'F'
|
||||||
|
161, // 'G'
|
||||||
|
150, // 'H'
|
||||||
|
193, // 'I'
|
||||||
|
142, // 'J'
|
||||||
|
137, // 'K'
|
||||||
|
171, // 'L'
|
||||||
|
176, // 'M'
|
||||||
|
185, // 'N'
|
||||||
|
167, // 'O'
|
||||||
|
186, // 'P'
|
||||||
|
112, // 'Q'
|
||||||
|
175, // 'R'
|
||||||
|
192, // 'S'
|
||||||
|
188, // 'T'
|
||||||
|
156, // 'U'
|
||||||
|
140, // 'V'
|
||||||
|
143, // 'W'
|
||||||
|
123, // 'X'
|
||||||
|
133, // 'Y'
|
||||||
|
128, // 'Z'
|
||||||
|
147, // '['
|
||||||
|
138, // '\\'
|
||||||
|
146, // ']'
|
||||||
|
114, // '^'
|
||||||
|
223, // '_'
|
||||||
|
151, // '`'
|
||||||
|
249, // 'a'
|
||||||
|
216, // 'b'
|
||||||
|
238, // 'c'
|
||||||
|
236, // 'd'
|
||||||
|
253, // 'e'
|
||||||
|
227, // 'f'
|
||||||
|
218, // 'g'
|
||||||
|
230, // 'h'
|
||||||
|
247, // 'i'
|
||||||
|
135, // 'j'
|
||||||
|
180, // 'k'
|
||||||
|
241, // 'l'
|
||||||
|
233, // 'm'
|
||||||
|
246, // 'n'
|
||||||
|
244, // 'o'
|
||||||
|
231, // 'p'
|
||||||
|
139, // 'q'
|
||||||
|
245, // 'r'
|
||||||
|
243, // 's'
|
||||||
|
251, // 't'
|
||||||
|
235, // 'u'
|
||||||
|
201, // 'v'
|
||||||
|
196, // 'w'
|
||||||
|
240, // 'x'
|
||||||
|
214, // 'y'
|
||||||
|
152, // 'z'
|
||||||
|
182, // '{'
|
||||||
|
205, // '|'
|
||||||
|
181, // '}'
|
||||||
|
127, // '~'
|
||||||
|
27, // '\x7f'
|
||||||
|
212, // '\x80'
|
||||||
|
211, // '\x81'
|
||||||
|
210, // '\x82'
|
||||||
|
213, // '\x83'
|
||||||
|
228, // '\x84'
|
||||||
|
197, // '\x85'
|
||||||
|
169, // '\x86'
|
||||||
|
159, // '\x87'
|
||||||
|
131, // '\x88'
|
||||||
|
172, // '\x89'
|
||||||
|
105, // '\x8a'
|
||||||
|
80, // '\x8b'
|
||||||
|
98, // '\x8c'
|
||||||
|
96, // '\x8d'
|
||||||
|
97, // '\x8e'
|
||||||
|
81, // '\x8f'
|
||||||
|
207, // '\x90'
|
||||||
|
145, // '\x91'
|
||||||
|
116, // '\x92'
|
||||||
|
115, // '\x93'
|
||||||
|
144, // '\x94'
|
||||||
|
130, // '\x95'
|
||||||
|
153, // '\x96'
|
||||||
|
121, // '\x97'
|
||||||
|
107, // '\x98'
|
||||||
|
132, // '\x99'
|
||||||
|
109, // '\x9a'
|
||||||
|
110, // '\x9b'
|
||||||
|
124, // '\x9c'
|
||||||
|
111, // '\x9d'
|
||||||
|
82, // '\x9e'
|
||||||
|
108, // '\x9f'
|
||||||
|
118, // '\xa0'
|
||||||
|
141, // '¡'
|
||||||
|
113, // '¢'
|
||||||
|
129, // '£'
|
||||||
|
119, // '¤'
|
||||||
|
125, // '¥'
|
||||||
|
165, // '¦'
|
||||||
|
117, // '§'
|
||||||
|
92, // '¨'
|
||||||
|
106, // '©'
|
||||||
|
83, // 'ª'
|
||||||
|
72, // '«'
|
||||||
|
99, // '¬'
|
||||||
|
93, // '\xad'
|
||||||
|
65, // '®'
|
||||||
|
79, // '¯'
|
||||||
|
166, // '°'
|
||||||
|
237, // '±'
|
||||||
|
163, // '²'
|
||||||
|
199, // '³'
|
||||||
|
190, // '´'
|
||||||
|
225, // 'µ'
|
||||||
|
209, // '¶'
|
||||||
|
203, // '·'
|
||||||
|
198, // '¸'
|
||||||
|
217, // '¹'
|
||||||
|
219, // 'º'
|
||||||
|
206, // '»'
|
||||||
|
234, // '¼'
|
||||||
|
248, // '½'
|
||||||
|
158, // '¾'
|
||||||
|
239, // '¿'
|
||||||
|
255, // 'À'
|
||||||
|
255, // 'Á'
|
||||||
|
255, // 'Â'
|
||||||
|
255, // 'Ã'
|
||||||
|
255, // 'Ä'
|
||||||
|
255, // 'Å'
|
||||||
|
255, // 'Æ'
|
||||||
|
255, // 'Ç'
|
||||||
|
255, // 'È'
|
||||||
|
255, // 'É'
|
||||||
|
255, // 'Ê'
|
||||||
|
255, // 'Ë'
|
||||||
|
255, // 'Ì'
|
||||||
|
255, // 'Í'
|
||||||
|
255, // 'Î'
|
||||||
|
255, // 'Ï'
|
||||||
|
255, // 'Ð'
|
||||||
|
255, // 'Ñ'
|
||||||
|
255, // 'Ò'
|
||||||
|
255, // 'Ó'
|
||||||
|
255, // 'Ô'
|
||||||
|
255, // 'Õ'
|
||||||
|
255, // 'Ö'
|
||||||
|
255, // '×'
|
||||||
|
255, // 'Ø'
|
||||||
|
255, // 'Ù'
|
||||||
|
255, // 'Ú'
|
||||||
|
255, // 'Û'
|
||||||
|
255, // 'Ü'
|
||||||
|
255, // 'Ý'
|
||||||
|
255, // 'Þ'
|
||||||
|
255, // 'ß'
|
||||||
|
255, // 'à'
|
||||||
|
255, // 'á'
|
||||||
|
255, // 'â'
|
||||||
|
255, // 'ã'
|
||||||
|
255, // 'ä'
|
||||||
|
255, // 'å'
|
||||||
|
255, // 'æ'
|
||||||
|
255, // 'ç'
|
||||||
|
255, // 'è'
|
||||||
|
255, // 'é'
|
||||||
|
255, // 'ê'
|
||||||
|
255, // 'ë'
|
||||||
|
255, // 'ì'
|
||||||
|
255, // 'í'
|
||||||
|
255, // 'î'
|
||||||
|
255, // 'ï'
|
||||||
|
255, // 'ð'
|
||||||
|
255, // 'ñ'
|
||||||
|
255, // 'ò'
|
||||||
|
255, // 'ó'
|
||||||
|
255, // 'ô'
|
||||||
|
255, // 'õ'
|
||||||
|
255, // 'ö'
|
||||||
|
255, // '÷'
|
||||||
|
255, // 'ø'
|
||||||
|
255, // 'ù'
|
||||||
|
255, // 'ú'
|
||||||
|
255, // 'û'
|
||||||
|
255, // 'ü'
|
||||||
|
255, // 'ý'
|
||||||
|
255, // 'þ'
|
||||||
|
255, // 'ÿ'
|
||||||
|
];
|
||||||
359
third_party/crates/memchr-2.8.3/src/arch/all/packedpair/mod.rs
vendored
Normal file
359
third_party/crates/memchr-2.8.3/src/arch/all/packedpair/mod.rs
vendored
Normal file
@@ -0,0 +1,359 @@
|
|||||||
|
/*!
|
||||||
|
Provides an architecture independent implementation of the "packed pair"
|
||||||
|
algorithm.
|
||||||
|
|
||||||
|
The "packed pair" algorithm is based on the [generic SIMD] algorithm. The main
|
||||||
|
difference is that it (by default) uses a background distribution of byte
|
||||||
|
frequencies to heuristically select the pair of bytes to search for. Note that
|
||||||
|
this module provides an architecture independent version that doesn't do as
|
||||||
|
good of a job keeping the search for candidates inside a SIMD hot path. It
|
||||||
|
however can be good enough in many circumstances.
|
||||||
|
|
||||||
|
[generic SIMD]: http://0x80.pl/articles/simd-strfind.html#first-and-last
|
||||||
|
*/
|
||||||
|
|
||||||
|
use crate::memchr;
|
||||||
|
|
||||||
|
mod default_rank;
|
||||||
|
|
||||||
|
/// An architecture independent "packed pair" finder.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power for
|
||||||
|
/// indicating an overall match of a needle. At search time, it reports offsets
|
||||||
|
/// where the needle could match based on whether the pair of bytes it chose
|
||||||
|
/// match.
|
||||||
|
///
|
||||||
|
/// This is architecture independent because it utilizes `memchr` to find the
|
||||||
|
/// occurrence of one of the bytes in the pair, and then checks whether the
|
||||||
|
/// second byte matches. If it does, in the case of [`Finder::find_prefilter`],
|
||||||
|
/// the location at which the needle could match is returned.
|
||||||
|
///
|
||||||
|
/// It is generally preferred to use architecture specific routines for a
|
||||||
|
/// "packed pair" prefilter, but this can be a useful fallback when the
|
||||||
|
/// architecture independent routines are unavailable.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Finder {
|
||||||
|
pair: Pair,
|
||||||
|
byte1: u8,
|
||||||
|
byte2: u8,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
/// Create a new prefilter that reports possible locations where the given
|
||||||
|
/// needle matches.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Finder> {
|
||||||
|
Finder::with_pair(needle, Pair::new(needle)?)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new prefilter using the pair given.
|
||||||
|
///
|
||||||
|
/// If the prefilter could not be constructed, then `None` is returned.
|
||||||
|
///
|
||||||
|
/// This constructor permits callers to control precisely which pair of
|
||||||
|
/// bytes is used as a predicate.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_pair(needle: &[u8], pair: Pair) -> Option<Finder> {
|
||||||
|
let byte1 = needle[usize::from(pair.index1())];
|
||||||
|
let byte2 = needle[usize::from(pair.index2())];
|
||||||
|
// Currently this can never fail so we could just return a Finder,
|
||||||
|
// but it's conceivable this could change.
|
||||||
|
Some(Finder { pair, byte1, byte2 })
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run this finder on the given haystack as a prefilter.
|
||||||
|
///
|
||||||
|
/// If a candidate match is found, then an offset where the needle *could*
|
||||||
|
/// begin in the haystack is returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn find_prefilter(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
let mut i = 0;
|
||||||
|
let index1 = usize::from(self.pair.index1());
|
||||||
|
let index2 = usize::from(self.pair.index2());
|
||||||
|
loop {
|
||||||
|
// Use a fast vectorized implementation to skip to the next
|
||||||
|
// occurrence of the rarest byte (heuristically chosen) in the
|
||||||
|
// needle.
|
||||||
|
i += memchr(self.byte1, &haystack[i..])?;
|
||||||
|
let found = i;
|
||||||
|
i += 1;
|
||||||
|
|
||||||
|
// If we can't align our first byte match with the haystack, then a
|
||||||
|
// match is impossible.
|
||||||
|
let aligned1 = match found.checked_sub(index1) {
|
||||||
|
None => continue,
|
||||||
|
Some(aligned1) => aligned1,
|
||||||
|
};
|
||||||
|
|
||||||
|
// Now align the second byte match with the haystack. A mismatch
|
||||||
|
// means that a match is impossible.
|
||||||
|
let aligned2 = match aligned1.checked_add(index2) {
|
||||||
|
None => continue,
|
||||||
|
Some(aligned_index2) => aligned_index2,
|
||||||
|
};
|
||||||
|
if haystack.get(aligned2).map_or(true, |&b| b != self.byte2) {
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
|
||||||
|
// We've done what we can. There might be a match here.
|
||||||
|
return Some(aligned1);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the pair of offsets (into the needle) used to check as a
|
||||||
|
/// predicate before confirming whether a needle exists at a particular
|
||||||
|
/// position.
|
||||||
|
#[inline]
|
||||||
|
pub fn pair(&self) -> &Pair {
|
||||||
|
&self.pair
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A pair of byte offsets into a needle to use as a predicate.
|
||||||
|
///
|
||||||
|
/// This pair is used as a predicate to quickly filter out positions in a
|
||||||
|
/// haystack in which a needle cannot match. In some cases, this pair can even
|
||||||
|
/// be used in vector algorithms such that the vector algorithm only switches
|
||||||
|
/// over to scalar code once this pair has been found.
|
||||||
|
///
|
||||||
|
/// A pair of offsets can be used in both substring search implementations and
|
||||||
|
/// in prefilters. The former will report matches of a needle in a haystack
|
||||||
|
/// where as the latter will only report possible matches of a needle.
|
||||||
|
///
|
||||||
|
/// The offsets are limited each to a maximum of 255 to keep memory usage low.
|
||||||
|
/// Moreover, it's rarely advantageous to create a predicate using offsets
|
||||||
|
/// greater than 255 anyway.
|
||||||
|
///
|
||||||
|
/// The only guarantee enforced on the pair of offsets is that they are not
|
||||||
|
/// equivalent. It is not necessarily the case that `index1 < index2` for
|
||||||
|
/// example. By convention, `index1` corresponds to the byte in the needle
|
||||||
|
/// that is believed to be most the predictive. Note also that because of the
|
||||||
|
/// requirement that the indices be both valid for the needle used to build
|
||||||
|
/// the pair and not equal, it follows that a pair can only be constructed for
|
||||||
|
/// needles with length at least 2.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Pair {
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Pair {
|
||||||
|
/// Create a new pair of offsets from the given needle.
|
||||||
|
///
|
||||||
|
/// If a pair could not be created (for example, if the needle is too
|
||||||
|
/// short), then `None` is returned.
|
||||||
|
///
|
||||||
|
/// This chooses the pair in the needle that is believed to be as
|
||||||
|
/// predictive of an overall match of the needle as possible.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Pair> {
|
||||||
|
Pair::with_ranker(needle, DefaultFrequencyRank)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new pair of offsets from the given needle and ranker.
|
||||||
|
///
|
||||||
|
/// This permits the caller to choose a background frequency distribution
|
||||||
|
/// with which bytes are selected. The idea is to select a pair of bytes
|
||||||
|
/// that is believed to strongly predict a match in the haystack. This
|
||||||
|
/// usually means selecting bytes that occur rarely in a haystack.
|
||||||
|
///
|
||||||
|
/// If a pair could not be created (for example, if the needle is too
|
||||||
|
/// short), then `None` is returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_ranker<R: HeuristicFrequencyRank>(
|
||||||
|
needle: &[u8],
|
||||||
|
ranker: R,
|
||||||
|
) -> Option<Pair> {
|
||||||
|
if needle.len() <= 1 {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
// Find the rarest two bytes. We make them distinct indices by
|
||||||
|
// construction. (The actual byte value may be the same in degenerate
|
||||||
|
// cases, but that's OK.)
|
||||||
|
let (mut rare1, mut index1) = (needle[0], 0);
|
||||||
|
let (mut rare2, mut index2) = (needle[1], 1);
|
||||||
|
if ranker.rank(rare2) < ranker.rank(rare1) {
|
||||||
|
core::mem::swap(&mut rare1, &mut rare2);
|
||||||
|
core::mem::swap(&mut index1, &mut index2);
|
||||||
|
}
|
||||||
|
let max = usize::from(core::u8::MAX);
|
||||||
|
for (i, &b) in needle.iter().enumerate().take(max).skip(2) {
|
||||||
|
if ranker.rank(b) < ranker.rank(rare1) {
|
||||||
|
rare2 = rare1;
|
||||||
|
index2 = index1;
|
||||||
|
rare1 = b;
|
||||||
|
index1 = u8::try_from(i).unwrap();
|
||||||
|
} else if b != rare1 && ranker.rank(b) < ranker.rank(rare2) {
|
||||||
|
rare2 = b;
|
||||||
|
index2 = u8::try_from(i).unwrap();
|
||||||
|
}
|
||||||
|
}
|
||||||
|
// While not strictly required for how a Pair is normally used, we
|
||||||
|
// really don't want these to be equivalent. If they were, it would
|
||||||
|
// reduce the effectiveness of candidate searching using these rare
|
||||||
|
// bytes by increasing the rate of false positives.
|
||||||
|
assert_ne!(index1, index2);
|
||||||
|
Some(Pair { index1, index2 })
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new pair using the offsets given for the needle given.
|
||||||
|
///
|
||||||
|
/// This bypasses any sort of heuristic process for choosing the offsets
|
||||||
|
/// and permits the caller to choose the offsets themselves.
|
||||||
|
///
|
||||||
|
/// Indices are limited to valid `u8` values so that a `Pair` uses less
|
||||||
|
/// memory. It is not possible to create a `Pair` with offsets bigger than
|
||||||
|
/// `u8::MAX`. It's likely that such a thing is not needed, but if it is,
|
||||||
|
/// it's suggested to build your own bespoke algorithm because you're
|
||||||
|
/// likely working on a very niche case. (File an issue if this suggestion
|
||||||
|
/// does not make sense to you.)
|
||||||
|
///
|
||||||
|
/// If a pair could not be created (for example, if the needle is too
|
||||||
|
/// short), then `None` is returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_indices(
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Pair> {
|
||||||
|
// While not strictly required for how a Pair is normally used, we
|
||||||
|
// really don't want these to be equivalent. If they were, it would
|
||||||
|
// reduce the effectiveness of candidate searching using these rare
|
||||||
|
// bytes by increasing the rate of false positives.
|
||||||
|
if index1 == index2 {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
// Similarly, invalid indices means the Pair is invalid too.
|
||||||
|
if usize::from(index1) >= needle.len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
if usize::from(index2) >= needle.len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(Pair { index1, index2 })
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the first offset of the pair.
|
||||||
|
#[inline]
|
||||||
|
pub fn index1(&self) -> u8 {
|
||||||
|
self.index1
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the second offset of the pair.
|
||||||
|
#[inline]
|
||||||
|
pub fn index2(&self) -> u8 {
|
||||||
|
self.index2
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// This trait allows the user to customize the heuristic used to determine the
|
||||||
|
/// relative frequency of a given byte in the dataset being searched.
|
||||||
|
///
|
||||||
|
/// The use of this trait can have a dramatic impact on performance depending
|
||||||
|
/// on the type of data being searched. The details of why are explained in the
|
||||||
|
/// docs of [`crate::memmem::Prefilter`]. To summarize, the core algorithm uses
|
||||||
|
/// a prefilter to quickly identify candidate matches that are later verified
|
||||||
|
/// more slowly. This prefilter is implemented in terms of trying to find
|
||||||
|
/// `rare` bytes at specific offsets that will occur less frequently in the
|
||||||
|
/// dataset. While the concept of a `rare` byte is similar for most datasets,
|
||||||
|
/// there are some specific datasets (like binary executables) that have
|
||||||
|
/// dramatically different byte distributions. For these datasets customizing
|
||||||
|
/// the byte frequency heuristic can have a massive impact on performance, and
|
||||||
|
/// might even need to be done at runtime.
|
||||||
|
///
|
||||||
|
/// The default implementation of `HeuristicFrequencyRank` reads from the
|
||||||
|
/// static frequency table defined in `src/memmem/byte_frequencies.rs`. This
|
||||||
|
/// is optimal for most inputs, so if you are unsure of the impact of using a
|
||||||
|
/// custom `HeuristicFrequencyRank` you should probably just use the default.
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::{
|
||||||
|
/// arch::all::packedpair::HeuristicFrequencyRank,
|
||||||
|
/// memmem::FinderBuilder,
|
||||||
|
/// };
|
||||||
|
///
|
||||||
|
/// /// A byte-frequency table that is good for scanning binary executables.
|
||||||
|
/// struct Binary;
|
||||||
|
///
|
||||||
|
/// impl HeuristicFrequencyRank for Binary {
|
||||||
|
/// fn rank(&self, byte: u8) -> u8 {
|
||||||
|
/// const TABLE: [u8; 256] = [
|
||||||
|
/// 255, 128, 61, 43, 50, 41, 27, 28, 57, 15, 21, 13, 24, 17, 17,
|
||||||
|
/// 89, 58, 16, 11, 7, 14, 23, 7, 6, 24, 9, 6, 5, 9, 4, 7, 16,
|
||||||
|
/// 68, 11, 9, 6, 88, 7, 4, 4, 23, 9, 4, 8, 8, 5, 10, 4, 30, 11,
|
||||||
|
/// 9, 24, 11, 5, 5, 5, 19, 11, 6, 17, 9, 9, 6, 8,
|
||||||
|
/// 48, 58, 11, 14, 53, 40, 9, 9, 254, 35, 3, 6, 52, 23, 6, 6, 27,
|
||||||
|
/// 4, 7, 11, 14, 13, 10, 11, 11, 5, 2, 10, 16, 12, 6, 19,
|
||||||
|
/// 19, 20, 5, 14, 16, 31, 19, 7, 14, 20, 4, 4, 19, 8, 18, 20, 24,
|
||||||
|
/// 1, 25, 19, 58, 29, 10, 5, 15, 20, 2, 2, 9, 4, 3, 5,
|
||||||
|
/// 51, 11, 4, 53, 23, 39, 6, 4, 13, 81, 4, 186, 5, 67, 3, 2, 15,
|
||||||
|
/// 0, 0, 1, 3, 2, 0, 0, 5, 0, 0, 0, 2, 0, 0, 0,
|
||||||
|
/// 12, 2, 1, 1, 3, 1, 1, 1, 6, 1, 2, 1, 3, 1, 1, 2, 9, 1, 1, 0,
|
||||||
|
/// 2, 2, 4, 4, 11, 6, 7, 3, 6, 9, 4, 5,
|
||||||
|
/// 46, 18, 8, 18, 17, 3, 8, 20, 16, 10, 3, 7, 175, 4, 6, 7, 13,
|
||||||
|
/// 3, 7, 3, 3, 1, 3, 3, 10, 3, 1, 5, 2, 0, 1, 2,
|
||||||
|
/// 16, 3, 5, 1, 6, 1, 1, 2, 58, 20, 3, 14, 12, 2, 1, 3, 16, 3, 5,
|
||||||
|
/// 8, 3, 1, 8, 6, 17, 6, 5, 3, 8, 6, 13, 175,
|
||||||
|
/// ];
|
||||||
|
/// TABLE[byte as usize]
|
||||||
|
/// }
|
||||||
|
/// }
|
||||||
|
/// // Create a new finder with the custom heuristic.
|
||||||
|
/// let finder = FinderBuilder::new()
|
||||||
|
/// .build_forward_with_ranker(Binary, b"\x00\x00\xdd\xdd");
|
||||||
|
/// // Find needle with custom heuristic.
|
||||||
|
/// assert!(finder.find(b"\x00\x00\x00\xdd\xdd").is_some());
|
||||||
|
/// ```
|
||||||
|
pub trait HeuristicFrequencyRank {
|
||||||
|
/// Return the heuristic frequency rank of the given byte. A lower rank
|
||||||
|
/// means the byte is believed to occur less frequently in the haystack.
|
||||||
|
///
|
||||||
|
/// Some uses of this heuristic may treat arbitrary absolute rank values as
|
||||||
|
/// significant. For example, an implementation detail in this crate may
|
||||||
|
/// determine that heuristic prefilters are inappropriate if every byte in
|
||||||
|
/// the needle has a "high" rank.
|
||||||
|
fn rank(&self, byte: u8) -> u8;
|
||||||
|
}
|
||||||
|
|
||||||
|
/// The default byte frequency heuristic that is good for most haystacks.
|
||||||
|
pub(crate) struct DefaultFrequencyRank;
|
||||||
|
|
||||||
|
impl HeuristicFrequencyRank for DefaultFrequencyRank {
|
||||||
|
fn rank(&self, byte: u8) -> u8 {
|
||||||
|
self::default_rank::RANK[usize::from(byte)]
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// This permits passing any implementation of `HeuristicFrequencyRank` as a
|
||||||
|
/// borrowed version of itself.
|
||||||
|
impl<'a, R> HeuristicFrequencyRank for &'a R
|
||||||
|
where
|
||||||
|
R: HeuristicFrequencyRank,
|
||||||
|
{
|
||||||
|
fn rank(&self, byte: u8) -> u8 {
|
||||||
|
(**self).rank(byte)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
_index1: u8,
|
||||||
|
_index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
// We ignore the index positions requested since it winds up making
|
||||||
|
// this test too slow overall.
|
||||||
|
let f = Finder::new(needle)?;
|
||||||
|
Some(f.find_prefilter(haystack))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
}
|
||||||
390
third_party/crates/memchr-2.8.3/src/arch/all/rabinkarp.rs
vendored
Normal file
390
third_party/crates/memchr-2.8.3/src/arch/all/rabinkarp.rs
vendored
Normal file
@@ -0,0 +1,390 @@
|
|||||||
|
/*!
|
||||||
|
An implementation of the [Rabin-Karp substring search algorithm][rabinkarp].
|
||||||
|
|
||||||
|
Rabin-Karp works by creating a hash of the needle provided and then computing
|
||||||
|
a rolling hash for each needle sized window in the haystack. When the rolling
|
||||||
|
hash matches the hash of the needle, a byte-wise comparison is done to check
|
||||||
|
if a match exists. The worst case time complexity of Rabin-Karp is `O(m *
|
||||||
|
n)` where `m ~ len(needle)` and `n ~ len(haystack)`. Its worst case space
|
||||||
|
complexity is constant.
|
||||||
|
|
||||||
|
The main utility of Rabin-Karp is that the searcher can be constructed very
|
||||||
|
quickly with very little memory. This makes it especially useful when searching
|
||||||
|
for small needles in small haystacks, as it might finish its search before a
|
||||||
|
beefier algorithm (like Two-Way) even starts.
|
||||||
|
|
||||||
|
[rabinkarp]: https://en.wikipedia.org/wiki/Rabin%E2%80%93Karp_algorithm
|
||||||
|
*/
|
||||||
|
|
||||||
|
/*
|
||||||
|
(This was the comment I wrote for this module originally when it was not
|
||||||
|
exposed. The comment still looks useful, but it's a bit in the weeds, so it's
|
||||||
|
not public itself.)
|
||||||
|
|
||||||
|
This module implements the classical Rabin-Karp substring search algorithm,
|
||||||
|
with no extra frills. While its use would seem to break our time complexity
|
||||||
|
guarantee of O(m+n) (RK's time complexity is O(mn)), we are careful to only
|
||||||
|
ever use RK on a constant subset of haystacks. The main point here is that
|
||||||
|
RK has good latency properties for small needles/haystacks. It's very quick
|
||||||
|
to compute a needle hash and zip through the haystack when compared to
|
||||||
|
initializing Two-Way, for example. And this is especially useful for cases
|
||||||
|
where the haystack is just too short for vector instructions to do much good.
|
||||||
|
|
||||||
|
The hashing function used here is the same one recommended by ESMAJ.
|
||||||
|
|
||||||
|
Another choice instead of Rabin-Karp would be Shift-Or. But its latency
|
||||||
|
isn't quite as good since its preprocessing time is a bit more expensive
|
||||||
|
(both in practice and in theory). However, perhaps Shift-Or has a place
|
||||||
|
somewhere else for short patterns. I think the main problem is that it
|
||||||
|
requires space proportional to the alphabet and the needle. If we, for
|
||||||
|
example, supported needles up to length 16, then the total table size would be
|
||||||
|
len(alphabet)*size_of::<u16>()==512 bytes. Which isn't exactly small, and it's
|
||||||
|
probably bad to put that on the stack. So ideally, we'd throw it on the heap,
|
||||||
|
but we'd really like to write as much code without using alloc/std as possible.
|
||||||
|
But maybe it's worth the special casing. It's a TODO to benchmark.
|
||||||
|
|
||||||
|
Wikipedia has a decent explanation, if a bit heavy on the theory:
|
||||||
|
https://en.wikipedia.org/wiki/Rabin%E2%80%93Karp_algorithm
|
||||||
|
|
||||||
|
But ESMAJ provides something a bit more concrete:
|
||||||
|
http://www-igm.univ-mlv.fr/~lecroq/string/node5.html
|
||||||
|
|
||||||
|
Finally, aho-corasick uses Rabin-Karp for multiple pattern match in some cases:
|
||||||
|
https://github.com/BurntSushi/aho-corasick/blob/3852632f10587db0ff72ef29e88d58bf305a0946/src/packed/rabinkarp.rs
|
||||||
|
*/
|
||||||
|
|
||||||
|
use crate::ext::Pointer;
|
||||||
|
|
||||||
|
/// A forward substring searcher using the Rabin-Karp algorithm.
|
||||||
|
///
|
||||||
|
/// Note that, as a lower level API, a `Finder` does not have access to the
|
||||||
|
/// needle it was constructed with. For this reason, executing a search
|
||||||
|
/// with a `Finder` requires passing both the needle and the haystack,
|
||||||
|
/// where the needle is exactly equivalent to the one given to the `Finder`
|
||||||
|
/// at construction time. This design was chosen so that callers can have
|
||||||
|
/// more precise control over where and how many times a needle is stored.
|
||||||
|
/// For example, in cases where Rabin-Karp is just one of several possible
|
||||||
|
/// substring search algorithms.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct Finder {
|
||||||
|
/// The actual hash.
|
||||||
|
hash: Hash,
|
||||||
|
/// The factor needed to multiply a byte by in order to subtract it from
|
||||||
|
/// the hash. It is defined to be 2^(n-1) (using wrapping exponentiation),
|
||||||
|
/// where n is the length of the needle. This is how we "remove" a byte
|
||||||
|
/// from the hash once the hash window rolls past it.
|
||||||
|
hash_2pow: u32,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
/// Create a new Rabin-Karp forward searcher for the given `needle`.
|
||||||
|
///
|
||||||
|
/// The needle may be empty. The empty needle matches at every byte offset.
|
||||||
|
///
|
||||||
|
/// Note that callers must pass the same needle to all search calls using
|
||||||
|
/// this `Finder`.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Finder {
|
||||||
|
let mut s = Finder { hash: Hash::new(), hash_2pow: 1 };
|
||||||
|
let first_byte = match needle.first() {
|
||||||
|
None => return s,
|
||||||
|
Some(&first_byte) => first_byte,
|
||||||
|
};
|
||||||
|
s.hash.add(first_byte);
|
||||||
|
for b in needle.iter().copied().skip(1) {
|
||||||
|
s.hash.add(b);
|
||||||
|
s.hash_2pow = s.hash_2pow.wrapping_shl(1);
|
||||||
|
}
|
||||||
|
s
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return the first occurrence of the `needle` in the `haystack`
|
||||||
|
/// given. If no such occurrence exists, then `None` is returned.
|
||||||
|
///
|
||||||
|
/// The `needle` provided must match the needle given to this finder at
|
||||||
|
/// construction time.
|
||||||
|
///
|
||||||
|
/// The maximum value this can return is `haystack.len()`, which can only
|
||||||
|
/// occur when the needle and haystack both have length zero. Otherwise,
|
||||||
|
/// for non-empty haystacks, the maximum value is `haystack.len() - 1`.
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
unsafe {
|
||||||
|
let hstart = haystack.as_ptr();
|
||||||
|
let hend = hstart.add(haystack.len());
|
||||||
|
let nstart = needle.as_ptr();
|
||||||
|
let nend = nstart.add(needle.len());
|
||||||
|
let found = self.find_raw(hstart, hend, nstart, nend)?;
|
||||||
|
Some(found.distance(hstart))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Like `find`, but accepts and returns raw pointers.
|
||||||
|
///
|
||||||
|
/// When a match is found, the pointer returned is guaranteed to be
|
||||||
|
/// `>= start` and `<= end`. The pointer returned is only ever equivalent
|
||||||
|
/// to `end` when both the needle and haystack are empty. (That is, the
|
||||||
|
/// empty string matches the empty string.)
|
||||||
|
///
|
||||||
|
/// This routine is useful if you're already using raw pointers and would
|
||||||
|
/// like to avoid converting back to a slice before executing a search.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Note that `start` and `end` below refer to both pairs of pointers given
|
||||||
|
/// to this routine. That is, the conditions apply to both `hstart`/`hend`
|
||||||
|
/// and `nstart`/`nend`.
|
||||||
|
///
|
||||||
|
/// * Both `start` and `end` must be valid for reads.
|
||||||
|
/// * Both `start` and `end` must point to an initialized value.
|
||||||
|
/// * Both `start` and `end` must point to the same allocated object and
|
||||||
|
/// must either be in bounds or at most one byte past the end of the
|
||||||
|
/// allocated object.
|
||||||
|
/// * Both `start` and `end` must be _derived from_ a pointer to the same
|
||||||
|
/// object.
|
||||||
|
/// * The distance between `start` and `end` must not overflow `isize`.
|
||||||
|
/// * The distance being in bounds must not rely on "wrapping around" the
|
||||||
|
/// address space.
|
||||||
|
/// * It must be the case that `start <= end`.
|
||||||
|
#[inline]
|
||||||
|
pub unsafe fn find_raw(
|
||||||
|
&self,
|
||||||
|
hstart: *const u8,
|
||||||
|
hend: *const u8,
|
||||||
|
nstart: *const u8,
|
||||||
|
nend: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
let hlen = hend.distance(hstart);
|
||||||
|
let nlen = nend.distance(nstart);
|
||||||
|
if nlen > hlen {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
let mut cur = hstart;
|
||||||
|
let end = hend.sub(nlen);
|
||||||
|
let mut hash = Hash::forward(cur, cur.add(nlen));
|
||||||
|
loop {
|
||||||
|
if self.hash == hash && is_equal_raw(cur, nstart, nlen) {
|
||||||
|
return Some(cur);
|
||||||
|
}
|
||||||
|
if cur >= end {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
hash.roll(self, cur.read(), cur.add(nlen).read());
|
||||||
|
cur = cur.add(1);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A reverse substring searcher using the Rabin-Karp algorithm.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct FinderRev(Finder);
|
||||||
|
|
||||||
|
impl FinderRev {
|
||||||
|
/// Create a new Rabin-Karp reverse searcher for the given `needle`.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> FinderRev {
|
||||||
|
let mut s = FinderRev(Finder { hash: Hash::new(), hash_2pow: 1 });
|
||||||
|
let last_byte = match needle.last() {
|
||||||
|
None => return s,
|
||||||
|
Some(&last_byte) => last_byte,
|
||||||
|
};
|
||||||
|
s.0.hash.add(last_byte);
|
||||||
|
for b in needle.iter().rev().copied().skip(1) {
|
||||||
|
s.0.hash.add(b);
|
||||||
|
s.0.hash_2pow = s.0.hash_2pow.wrapping_shl(1);
|
||||||
|
}
|
||||||
|
s
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return the last occurrence of the `needle` in the `haystack`
|
||||||
|
/// given. If no such occurrence exists, then `None` is returned.
|
||||||
|
///
|
||||||
|
/// The `needle` provided must match the needle given to this finder at
|
||||||
|
/// construction time.
|
||||||
|
///
|
||||||
|
/// The maximum value this can return is `haystack.len()`, which can only
|
||||||
|
/// occur when the needle and haystack both have length zero. Otherwise,
|
||||||
|
/// for non-empty haystacks, the maximum value is `haystack.len() - 1`.
|
||||||
|
#[inline]
|
||||||
|
pub fn rfind(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
unsafe {
|
||||||
|
let hstart = haystack.as_ptr();
|
||||||
|
let hend = hstart.add(haystack.len());
|
||||||
|
let nstart = needle.as_ptr();
|
||||||
|
let nend = nstart.add(needle.len());
|
||||||
|
let found = self.rfind_raw(hstart, hend, nstart, nend)?;
|
||||||
|
Some(found.distance(hstart))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Like `rfind`, but accepts and returns raw pointers.
|
||||||
|
///
|
||||||
|
/// When a match is found, the pointer returned is guaranteed to be
|
||||||
|
/// `>= start` and `<= end`. The pointer returned is only ever equivalent
|
||||||
|
/// to `end` when both the needle and haystack are empty. (That is, the
|
||||||
|
/// empty string matches the empty string.)
|
||||||
|
///
|
||||||
|
/// This routine is useful if you're already using raw pointers and would
|
||||||
|
/// like to avoid converting back to a slice before executing a search.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Note that `start` and `end` below refer to both pairs of pointers given
|
||||||
|
/// to this routine. That is, the conditions apply to both `hstart`/`hend`
|
||||||
|
/// and `nstart`/`nend`.
|
||||||
|
///
|
||||||
|
/// * Both `start` and `end` must be valid for reads.
|
||||||
|
/// * Both `start` and `end` must point to an initialized value.
|
||||||
|
/// * Both `start` and `end` must point to the same allocated object and
|
||||||
|
/// must either be in bounds or at most one byte past the end of the
|
||||||
|
/// allocated object.
|
||||||
|
/// * Both `start` and `end` must be _derived from_ a pointer to the same
|
||||||
|
/// object.
|
||||||
|
/// * The distance between `start` and `end` must not overflow `isize`.
|
||||||
|
/// * The distance being in bounds must not rely on "wrapping around" the
|
||||||
|
/// address space.
|
||||||
|
/// * It must be the case that `start <= end`.
|
||||||
|
#[inline]
|
||||||
|
pub unsafe fn rfind_raw(
|
||||||
|
&self,
|
||||||
|
hstart: *const u8,
|
||||||
|
hend: *const u8,
|
||||||
|
nstart: *const u8,
|
||||||
|
nend: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
let hlen = hend.distance(hstart);
|
||||||
|
let nlen = nend.distance(nstart);
|
||||||
|
if nlen > hlen {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
let mut cur = hend.sub(nlen);
|
||||||
|
let start = hstart;
|
||||||
|
let mut hash = Hash::reverse(cur, cur.add(nlen));
|
||||||
|
loop {
|
||||||
|
if self.0.hash == hash && is_equal_raw(cur, nstart, nlen) {
|
||||||
|
return Some(cur);
|
||||||
|
}
|
||||||
|
if cur <= start {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
cur = cur.sub(1);
|
||||||
|
hash.roll(&self.0, cur.add(nlen).read(), cur.read());
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Whether RK is believed to be very fast for the given needle/haystack.
|
||||||
|
#[inline]
|
||||||
|
pub(crate) fn is_fast(haystack: &[u8], _needle: &[u8]) -> bool {
|
||||||
|
haystack.len() < 16
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A Rabin-Karp hash. This might represent the hash of a needle, or the hash
|
||||||
|
/// of a rolling window in the haystack.
|
||||||
|
#[derive(Clone, Copy, Debug, Default, Eq, PartialEq)]
|
||||||
|
struct Hash(u32);
|
||||||
|
|
||||||
|
impl Hash {
|
||||||
|
/// Create a new hash that represents the empty string.
|
||||||
|
#[inline(always)]
|
||||||
|
fn new() -> Hash {
|
||||||
|
Hash(0)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new hash from the bytes given for use in forward searches.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// The given pointers must be valid to read from within their range.
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn forward(mut start: *const u8, end: *const u8) -> Hash {
|
||||||
|
let mut hash = Hash::new();
|
||||||
|
while start < end {
|
||||||
|
hash.add(start.read());
|
||||||
|
start = start.add(1);
|
||||||
|
}
|
||||||
|
hash
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new hash from the bytes given for use in reverse searches.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// The given pointers must be valid to read from within their range.
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn reverse(start: *const u8, mut end: *const u8) -> Hash {
|
||||||
|
let mut hash = Hash::new();
|
||||||
|
while start < end {
|
||||||
|
end = end.sub(1);
|
||||||
|
hash.add(end.read());
|
||||||
|
}
|
||||||
|
hash
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Add 'new' and remove 'old' from this hash. The given needle hash should
|
||||||
|
/// correspond to the hash computed for the needle being searched for.
|
||||||
|
///
|
||||||
|
/// This is meant to be used when the rolling window of the haystack is
|
||||||
|
/// advanced.
|
||||||
|
#[inline(always)]
|
||||||
|
fn roll(&mut self, finder: &Finder, old: u8, new: u8) {
|
||||||
|
self.del(finder, old);
|
||||||
|
self.add(new);
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Add a byte to this hash.
|
||||||
|
#[inline(always)]
|
||||||
|
fn add(&mut self, byte: u8) {
|
||||||
|
self.0 = self.0.wrapping_shl(1).wrapping_add(u32::from(byte));
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Remove a byte from this hash. The given needle hash should correspond
|
||||||
|
/// to the hash computed for the needle being searched for.
|
||||||
|
#[inline(always)]
|
||||||
|
fn del(&mut self, finder: &Finder, byte: u8) {
|
||||||
|
let factor = finder.hash_2pow;
|
||||||
|
self.0 = self.0.wrapping_sub(u32::from(byte).wrapping_mul(factor));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns true when `x[i] == y[i]` for all `0 <= i < n`.
|
||||||
|
///
|
||||||
|
/// We forcefully don't inline this to hint at the compiler that it is unlikely
|
||||||
|
/// to be called. This causes the inner rabinkarp loop above to be a bit
|
||||||
|
/// tighter and leads to some performance improvement. See the
|
||||||
|
/// memmem/krate/prebuilt/sliceslice-words/words benchmark.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same as `crate::arch::all::is_equal_raw`.
|
||||||
|
#[cold]
|
||||||
|
#[inline(never)]
|
||||||
|
unsafe fn is_equal_raw(x: *const u8, y: *const u8, n: usize) -> bool {
|
||||||
|
crate::arch::all::is_equal_raw(x, y, n)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(|h, n| Some(
|
||||||
|
Finder::new(n).find(h, n)
|
||||||
|
));
|
||||||
|
define_substring_reverse_quickcheck!(|h, n| Some(
|
||||||
|
FinderRev::new(n).rfind(h, n)
|
||||||
|
));
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.fwd(|h, n| Some(Finder::new(n).find(h, n)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.rev(|h, n| Some(FinderRev::new(n).rfind(h, n)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
}
|
||||||
89
third_party/crates/memchr-2.8.3/src/arch/all/shiftor.rs
vendored
Normal file
89
third_party/crates/memchr-2.8.3/src/arch/all/shiftor.rs
vendored
Normal file
@@ -0,0 +1,89 @@
|
|||||||
|
/*!
|
||||||
|
An implementation of the [Shift-Or substring search algorithm][shiftor].
|
||||||
|
|
||||||
|
[shiftor]: https://en.wikipedia.org/wiki/Bitap_algorithm
|
||||||
|
*/
|
||||||
|
|
||||||
|
use alloc::boxed::Box;
|
||||||
|
|
||||||
|
/// The type of our mask.
|
||||||
|
///
|
||||||
|
/// While we don't expose anyway to configure this in the public API, if one
|
||||||
|
/// really needs less memory usage or support for longer needles, then it is
|
||||||
|
/// suggested to copy the code from this module and modify it to fit your
|
||||||
|
/// needs. The code below is written to be correct regardless of whether Mask
|
||||||
|
/// is a u8, u16, u32, u64 or u128.
|
||||||
|
type Mask = u16;
|
||||||
|
|
||||||
|
/// A forward substring searcher using the Shift-Or algorithm.
|
||||||
|
#[derive(Debug)]
|
||||||
|
pub struct Finder {
|
||||||
|
masks: Box<[Mask; 256]>,
|
||||||
|
needle_len: usize,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
const MAX_NEEDLE_LEN: usize = (Mask::BITS - 1) as usize;
|
||||||
|
|
||||||
|
/// Create a new Shift-Or forward searcher for the given `needle`.
|
||||||
|
///
|
||||||
|
/// The needle may be empty. The empty needle matches at every byte offset.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Finder> {
|
||||||
|
let needle_len = needle.len();
|
||||||
|
if needle_len > Finder::MAX_NEEDLE_LEN {
|
||||||
|
// A match is found when bit 7 is set in 'result' in the search
|
||||||
|
// routine below. So our needle can't be bigger than 7. We could
|
||||||
|
// permit bigger needles by using u16, u32 or u64 for our mask
|
||||||
|
// entries. But this is all we need for this example.
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
let mut searcher = Finder { masks: Box::from([!0; 256]), needle_len };
|
||||||
|
for (i, &byte) in needle.iter().enumerate() {
|
||||||
|
searcher.masks[usize::from(byte)] &= !(1 << i);
|
||||||
|
}
|
||||||
|
Some(searcher)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return the first occurrence of the needle given to `Finder::new` in
|
||||||
|
/// the `haystack` given. If no such occurrence exists, then `None` is
|
||||||
|
/// returned.
|
||||||
|
///
|
||||||
|
/// Unlike most other substring search implementations in this crate, this
|
||||||
|
/// finder does not require passing the needle at search time. A match can
|
||||||
|
/// be determined without the needle at all since the required information
|
||||||
|
/// is already encoded into this finder at construction time.
|
||||||
|
///
|
||||||
|
/// The maximum value this can return is `haystack.len()`, which can only
|
||||||
|
/// occur when the needle and haystack both have length zero. Otherwise,
|
||||||
|
/// for non-empty haystacks, the maximum value is `haystack.len() - 1`.
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
if self.needle_len == 0 {
|
||||||
|
return Some(0);
|
||||||
|
}
|
||||||
|
let mut result = !1;
|
||||||
|
for (i, &byte) in haystack.iter().enumerate() {
|
||||||
|
result |= self.masks[usize::from(byte)];
|
||||||
|
result <<= 1;
|
||||||
|
if result & (1 << self.needle_len) == 0 {
|
||||||
|
return Some(i + 1 - self.needle_len);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(|h, n| Some(Finder::new(n)?.find(h)));
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.fwd(|h, n| Some(Finder::new(n)?.find(h)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
}
|
||||||
877
third_party/crates/memchr-2.8.3/src/arch/all/twoway.rs
vendored
Normal file
877
third_party/crates/memchr-2.8.3/src/arch/all/twoway.rs
vendored
Normal file
@@ -0,0 +1,877 @@
|
|||||||
|
/*!
|
||||||
|
An implementation of the [Two-Way substring search algorithm][two-way].
|
||||||
|
|
||||||
|
[`Finder`] can be built for forward searches, while [`FinderRev`] can be built
|
||||||
|
for reverse searches.
|
||||||
|
|
||||||
|
Two-Way makes for a nice general purpose substring search algorithm because of
|
||||||
|
its time and space complexity properties. It also performs well in practice.
|
||||||
|
Namely, with `m = len(needle)` and `n = len(haystack)`, Two-Way takes `O(m)`
|
||||||
|
time to create a finder, `O(1)` space and `O(n)` search time. In other words,
|
||||||
|
the preprocessing step is quick, doesn't require any heap memory and the worst
|
||||||
|
case search time is guaranteed to be linear in the haystack regardless of the
|
||||||
|
size of the needle.
|
||||||
|
|
||||||
|
While vector algorithms will usually beat Two-Way handedly, vector algorithms
|
||||||
|
also usually have pathological or edge cases that are better handled by Two-Way.
|
||||||
|
Moreover, not all targets support vector algorithms or implementations for them
|
||||||
|
simply may not exist yet.
|
||||||
|
|
||||||
|
Two-Way can be found in the `memmem` implementations in at least [GNU libc] and
|
||||||
|
[musl].
|
||||||
|
|
||||||
|
[two-way]: https://en.wikipedia.org/wiki/Two-way_string-matching_algorithm
|
||||||
|
[GNU libc]: https://www.gnu.org/software/libc/
|
||||||
|
[musl]: https://www.musl-libc.org/
|
||||||
|
*/
|
||||||
|
|
||||||
|
use core::cmp;
|
||||||
|
|
||||||
|
use crate::{
|
||||||
|
arch::all::{is_prefix, is_suffix},
|
||||||
|
memmem::Pre,
|
||||||
|
};
|
||||||
|
|
||||||
|
/// A forward substring searcher that uses the Two-Way algorithm.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Finder(TwoWay);
|
||||||
|
|
||||||
|
/// A reverse substring searcher that uses the Two-Way algorithm.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct FinderRev(TwoWay);
|
||||||
|
|
||||||
|
/// An implementation of the TwoWay substring search algorithm.
|
||||||
|
///
|
||||||
|
/// This searcher supports forward and reverse search, although not
|
||||||
|
/// simultaneously. It runs in `O(n + m)` time and `O(1)` space, where
|
||||||
|
/// `n ~ len(needle)` and `m ~ len(haystack)`.
|
||||||
|
///
|
||||||
|
/// The implementation here roughly matches that which was developed by
|
||||||
|
/// Crochemore and Perrin in their 1991 paper "Two-way string-matching." The
|
||||||
|
/// changes in this implementation are 1) the use of zero-based indices, 2) a
|
||||||
|
/// heuristic skip table based on the last byte (borrowed from Rust's standard
|
||||||
|
/// library) and 3) the addition of heuristics for a fast skip loop. For (3),
|
||||||
|
/// callers can pass any kind of prefilter they want, but usually it's one
|
||||||
|
/// based on a heuristic that uses an approximate background frequency of bytes
|
||||||
|
/// to choose rare bytes to quickly look for candidate match positions. Note
|
||||||
|
/// though that currently, this prefilter functionality is not exposed directly
|
||||||
|
/// in the public API. (File an issue if you want it and provide a use case
|
||||||
|
/// please.)
|
||||||
|
///
|
||||||
|
/// The heuristic for fast skipping is automatically shut off if it's
|
||||||
|
/// detected to be ineffective at search time. Generally, this only occurs in
|
||||||
|
/// pathological cases. But this is generally necessary in order to preserve
|
||||||
|
/// a `O(n + m)` time bound.
|
||||||
|
///
|
||||||
|
/// The code below is fairly complex and not obviously correct at all. It's
|
||||||
|
/// likely necessary to read the Two-Way paper cited above in order to fully
|
||||||
|
/// grok this code. The essence of it is:
|
||||||
|
///
|
||||||
|
/// 1. Do something to detect a "critical" position in the needle.
|
||||||
|
/// 2. For the current position in the haystack, look if `needle[critical..]`
|
||||||
|
/// matches at that position.
|
||||||
|
/// 3. If so, look if `needle[..critical]` matches.
|
||||||
|
/// 4. If a mismatch occurs, shift the search by some amount based on the
|
||||||
|
/// critical position and a pre-computed shift.
|
||||||
|
///
|
||||||
|
/// This type is wrapped in the forward and reverse finders that expose
|
||||||
|
/// consistent forward or reverse APIs.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
struct TwoWay {
|
||||||
|
/// A small bitset used as a quick prefilter (in addition to any prefilter
|
||||||
|
/// given by the caller). Namely, a bit `i` is set if and only if `b%64==i`
|
||||||
|
/// for any `b == needle[i]`.
|
||||||
|
///
|
||||||
|
/// When used as a prefilter, if the last byte at the current candidate
|
||||||
|
/// position is NOT in this set, then we can skip that entire candidate
|
||||||
|
/// position (the length of the needle). This is essentially the shift
|
||||||
|
/// trick found in Boyer-Moore, but only applied to bytes that don't appear
|
||||||
|
/// in the needle.
|
||||||
|
///
|
||||||
|
/// N.B. This trick was inspired by something similar in std's
|
||||||
|
/// implementation of Two-Way.
|
||||||
|
byteset: ApproximateByteSet,
|
||||||
|
/// A critical position in needle. Specifically, this position corresponds
|
||||||
|
/// to beginning of either the minimal or maximal suffix in needle. (N.B.
|
||||||
|
/// See SuffixType below for why "minimal" isn't quite the correct word
|
||||||
|
/// here.)
|
||||||
|
///
|
||||||
|
/// This is the position at which every search begins. Namely, search
|
||||||
|
/// starts by scanning text to the right of this position, and only if
|
||||||
|
/// there's a match does the text to the left of this position get scanned.
|
||||||
|
critical_pos: usize,
|
||||||
|
/// The amount we shift by in the Two-Way search algorithm. This
|
||||||
|
/// corresponds to the "small period" and "large period" cases.
|
||||||
|
shift: Shift,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
/// Create a searcher that finds occurrences of the given `needle`.
|
||||||
|
///
|
||||||
|
/// An empty `needle` results in a match at every position in a haystack,
|
||||||
|
/// including at `haystack.len()`.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Finder {
|
||||||
|
let byteset = ApproximateByteSet::new(needle);
|
||||||
|
let min_suffix = Suffix::forward(needle, SuffixKind::Minimal);
|
||||||
|
let max_suffix = Suffix::forward(needle, SuffixKind::Maximal);
|
||||||
|
let (period_lower_bound, critical_pos) =
|
||||||
|
if min_suffix.pos > max_suffix.pos {
|
||||||
|
(min_suffix.period, min_suffix.pos)
|
||||||
|
} else {
|
||||||
|
(max_suffix.period, max_suffix.pos)
|
||||||
|
};
|
||||||
|
let shift = Shift::forward(needle, period_lower_bound, critical_pos);
|
||||||
|
Finder(TwoWay { byteset, critical_pos, shift })
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the first occurrence of `needle` in the given `haystack`, or
|
||||||
|
/// `None` if no such occurrence could be found.
|
||||||
|
///
|
||||||
|
/// The `needle` given must be the same as the `needle` provided to
|
||||||
|
/// [`Finder::new`].
|
||||||
|
///
|
||||||
|
/// An empty `needle` results in a match at every position in a haystack,
|
||||||
|
/// including at `haystack.len()`.
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
self.find_with_prefilter(None, haystack, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// This is like [`Finder::find`], but it accepts a prefilter for
|
||||||
|
/// accelerating searches.
|
||||||
|
///
|
||||||
|
/// Currently this is not exposed in the public API because, at the time
|
||||||
|
/// of writing, I didn't want to spend time thinking about how to expose
|
||||||
|
/// the prefilter infrastructure (if at all). If you have a compelling use
|
||||||
|
/// case for exposing this routine, please create an issue. Do *not* open
|
||||||
|
/// a PR that just exposes `Pre` and friends. Exporting this routine will
|
||||||
|
/// require API design.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn find_with_prefilter(
|
||||||
|
&self,
|
||||||
|
pre: Option<Pre<'_>>,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
match self.0.shift {
|
||||||
|
Shift::Small { period } => {
|
||||||
|
self.find_small_imp(pre, haystack, needle, period)
|
||||||
|
}
|
||||||
|
Shift::Large { shift } => {
|
||||||
|
self.find_large_imp(pre, haystack, needle, shift)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Each of the two search implementations below can be accelerated by a
|
||||||
|
// prefilter, but it is not always enabled. To avoid its overhead when
|
||||||
|
// its disabled, we explicitly inline each search implementation based on
|
||||||
|
// whether a prefilter will be used or not. The decision on which to use
|
||||||
|
// is made in the parent meta searcher.
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn find_small_imp(
|
||||||
|
&self,
|
||||||
|
mut pre: Option<Pre<'_>>,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
period: usize,
|
||||||
|
) -> Option<usize> {
|
||||||
|
let mut pos = 0;
|
||||||
|
let mut shift = 0;
|
||||||
|
let last_byte_pos = match needle.len().checked_sub(1) {
|
||||||
|
None => return Some(pos),
|
||||||
|
Some(last_byte) => last_byte,
|
||||||
|
};
|
||||||
|
while pos + needle.len() <= haystack.len() {
|
||||||
|
let mut i = cmp::max(self.0.critical_pos, shift);
|
||||||
|
if let Some(pre) = pre.as_mut() {
|
||||||
|
if pre.is_effective() {
|
||||||
|
pos += pre.find(&haystack[pos..])?;
|
||||||
|
shift = 0;
|
||||||
|
i = self.0.critical_pos;
|
||||||
|
if pos + needle.len() > haystack.len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
if !self.0.byteset.contains(haystack[pos + last_byte_pos]) {
|
||||||
|
pos += needle.len();
|
||||||
|
shift = 0;
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
while i < needle.len() && needle[i] == haystack[pos + i] {
|
||||||
|
i += 1;
|
||||||
|
}
|
||||||
|
if i < needle.len() {
|
||||||
|
pos += i - self.0.critical_pos + 1;
|
||||||
|
shift = 0;
|
||||||
|
} else {
|
||||||
|
let mut j = self.0.critical_pos;
|
||||||
|
while j > shift && needle[j] == haystack[pos + j] {
|
||||||
|
j -= 1;
|
||||||
|
}
|
||||||
|
if j <= shift && needle[shift] == haystack[pos + shift] {
|
||||||
|
return Some(pos);
|
||||||
|
}
|
||||||
|
pos += period;
|
||||||
|
shift = needle.len() - period;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn find_large_imp(
|
||||||
|
&self,
|
||||||
|
mut pre: Option<Pre<'_>>,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
shift: usize,
|
||||||
|
) -> Option<usize> {
|
||||||
|
let mut pos = 0;
|
||||||
|
let last_byte_pos = match needle.len().checked_sub(1) {
|
||||||
|
None => return Some(pos),
|
||||||
|
Some(last_byte) => last_byte,
|
||||||
|
};
|
||||||
|
'outer: while pos + needle.len() <= haystack.len() {
|
||||||
|
if let Some(pre) = pre.as_mut() {
|
||||||
|
if pre.is_effective() {
|
||||||
|
pos += pre.find(&haystack[pos..])?;
|
||||||
|
if pos + needle.len() > haystack.len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
if !self.0.byteset.contains(haystack[pos + last_byte_pos]) {
|
||||||
|
pos += needle.len();
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
let mut i = self.0.critical_pos;
|
||||||
|
while i < needle.len() && needle[i] == haystack[pos + i] {
|
||||||
|
i += 1;
|
||||||
|
}
|
||||||
|
if i < needle.len() {
|
||||||
|
pos += i - self.0.critical_pos + 1;
|
||||||
|
} else {
|
||||||
|
for j in (0..self.0.critical_pos).rev() {
|
||||||
|
if needle[j] != haystack[pos + j] {
|
||||||
|
pos += shift;
|
||||||
|
continue 'outer;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
return Some(pos);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl FinderRev {
|
||||||
|
/// Create a searcher that finds occurrences of the given `needle`.
|
||||||
|
///
|
||||||
|
/// An empty `needle` results in a match at every position in a haystack,
|
||||||
|
/// including at `haystack.len()`.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> FinderRev {
|
||||||
|
let byteset = ApproximateByteSet::new(needle);
|
||||||
|
let min_suffix = Suffix::reverse(needle, SuffixKind::Minimal);
|
||||||
|
let max_suffix = Suffix::reverse(needle, SuffixKind::Maximal);
|
||||||
|
let (period_lower_bound, critical_pos) =
|
||||||
|
if min_suffix.pos < max_suffix.pos {
|
||||||
|
(min_suffix.period, min_suffix.pos)
|
||||||
|
} else {
|
||||||
|
(max_suffix.period, max_suffix.pos)
|
||||||
|
};
|
||||||
|
let shift = Shift::reverse(needle, period_lower_bound, critical_pos);
|
||||||
|
FinderRev(TwoWay { byteset, critical_pos, shift })
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the last occurrence of `needle` in the given `haystack`, or
|
||||||
|
/// `None` if no such occurrence could be found.
|
||||||
|
///
|
||||||
|
/// The `needle` given must be the same as the `needle` provided to
|
||||||
|
/// [`FinderRev::new`].
|
||||||
|
///
|
||||||
|
/// An empty `needle` results in a match at every position in a haystack,
|
||||||
|
/// including at `haystack.len()`.
|
||||||
|
#[inline]
|
||||||
|
pub fn rfind(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
// For the reverse case, we don't use a prefilter. It's plausible that
|
||||||
|
// perhaps we should, but it's a lot of additional code to do it, and
|
||||||
|
// it's not clear that it's actually worth it. If you have a really
|
||||||
|
// compelling use case for this, please file an issue.
|
||||||
|
match self.0.shift {
|
||||||
|
Shift::Small { period } => {
|
||||||
|
self.rfind_small_imp(haystack, needle, period)
|
||||||
|
}
|
||||||
|
Shift::Large { shift } => {
|
||||||
|
self.rfind_large_imp(haystack, needle, shift)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn rfind_small_imp(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
period: usize,
|
||||||
|
) -> Option<usize> {
|
||||||
|
let nlen = needle.len();
|
||||||
|
let mut pos = haystack.len();
|
||||||
|
let mut shift = nlen;
|
||||||
|
let first_byte = match needle.first() {
|
||||||
|
None => return Some(pos),
|
||||||
|
Some(&first_byte) => first_byte,
|
||||||
|
};
|
||||||
|
while pos >= nlen {
|
||||||
|
if !self.0.byteset.contains(haystack[pos - nlen]) {
|
||||||
|
pos -= nlen;
|
||||||
|
shift = nlen;
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
let mut i = cmp::min(self.0.critical_pos, shift);
|
||||||
|
while i > 0 && needle[i - 1] == haystack[pos - nlen + i - 1] {
|
||||||
|
i -= 1;
|
||||||
|
}
|
||||||
|
if i > 0 || first_byte != haystack[pos - nlen] {
|
||||||
|
pos -= self.0.critical_pos - i + 1;
|
||||||
|
shift = nlen;
|
||||||
|
} else {
|
||||||
|
let mut j = self.0.critical_pos;
|
||||||
|
while j < shift && needle[j] == haystack[pos - nlen + j] {
|
||||||
|
j += 1;
|
||||||
|
}
|
||||||
|
if j >= shift {
|
||||||
|
return Some(pos - nlen);
|
||||||
|
}
|
||||||
|
pos -= period;
|
||||||
|
shift = period;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn rfind_large_imp(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
shift: usize,
|
||||||
|
) -> Option<usize> {
|
||||||
|
let nlen = needle.len();
|
||||||
|
let mut pos = haystack.len();
|
||||||
|
let first_byte = match needle.first() {
|
||||||
|
None => return Some(pos),
|
||||||
|
Some(&first_byte) => first_byte,
|
||||||
|
};
|
||||||
|
while pos >= nlen {
|
||||||
|
if !self.0.byteset.contains(haystack[pos - nlen]) {
|
||||||
|
pos -= nlen;
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
let mut i = self.0.critical_pos;
|
||||||
|
while i > 0 && needle[i - 1] == haystack[pos - nlen + i - 1] {
|
||||||
|
i -= 1;
|
||||||
|
}
|
||||||
|
if i > 0 || first_byte != haystack[pos - nlen] {
|
||||||
|
pos -= self.0.critical_pos - i + 1;
|
||||||
|
} else {
|
||||||
|
let mut j = self.0.critical_pos;
|
||||||
|
while j < nlen && needle[j] == haystack[pos - nlen + j] {
|
||||||
|
j += 1;
|
||||||
|
}
|
||||||
|
if j == nlen {
|
||||||
|
return Some(pos - nlen);
|
||||||
|
}
|
||||||
|
pos -= shift;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A representation of the amount we're allowed to shift by during Two-Way
|
||||||
|
/// search.
|
||||||
|
///
|
||||||
|
/// When computing a critical factorization of the needle, we find the position
|
||||||
|
/// of the critical factorization by finding the needle's maximal (or minimal)
|
||||||
|
/// suffix, along with the period of that suffix. It turns out that the period
|
||||||
|
/// of that suffix is a lower bound on the period of the needle itself.
|
||||||
|
///
|
||||||
|
/// This lower bound is equivalent to the actual period of the needle in
|
||||||
|
/// some cases. To describe that case, we denote the needle as `x` where
|
||||||
|
/// `x = uv` and `v` is the lexicographic maximal suffix of `v`. The lower
|
||||||
|
/// bound given here is always the period of `v`, which is `<= period(x)`. The
|
||||||
|
/// case where `period(v) == period(x)` occurs when `len(u) < (len(x) / 2)` and
|
||||||
|
/// where `u` is a suffix of `v[0..period(v)]`.
|
||||||
|
///
|
||||||
|
/// This case is important because the search algorithm for when the
|
||||||
|
/// periods are equivalent is slightly different than the search algorithm
|
||||||
|
/// for when the periods are not equivalent. In particular, when they aren't
|
||||||
|
/// equivalent, we know that the period of the needle is no less than half its
|
||||||
|
/// length. In this case, we shift by an amount less than or equal to the
|
||||||
|
/// period of the needle (determined by the maximum length of the components
|
||||||
|
/// of the critical factorization of `x`, i.e., `max(len(u), len(v))`)..
|
||||||
|
///
|
||||||
|
/// The above two cases are represented by the variants below. Each entails
|
||||||
|
/// a different instantiation of the Two-Way search algorithm.
|
||||||
|
///
|
||||||
|
/// N.B. If we could find a way to compute the exact period in all cases,
|
||||||
|
/// then we could collapse this case analysis and simplify the algorithm. The
|
||||||
|
/// Two-Way paper suggests this is possible, but more reading is required to
|
||||||
|
/// grok why the authors didn't pursue that path.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
enum Shift {
|
||||||
|
Small { period: usize },
|
||||||
|
Large { shift: usize },
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Shift {
|
||||||
|
/// Compute the shift for a given needle in the forward direction.
|
||||||
|
///
|
||||||
|
/// This requires a lower bound on the period and a critical position.
|
||||||
|
/// These can be computed by extracting both the minimal and maximal
|
||||||
|
/// lexicographic suffixes, and choosing the right-most starting position.
|
||||||
|
/// The lower bound on the period is then the period of the chosen suffix.
|
||||||
|
fn forward(
|
||||||
|
needle: &[u8],
|
||||||
|
period_lower_bound: usize,
|
||||||
|
critical_pos: usize,
|
||||||
|
) -> Shift {
|
||||||
|
let large = cmp::max(critical_pos, needle.len() - critical_pos);
|
||||||
|
if critical_pos * 2 >= needle.len() {
|
||||||
|
return Shift::Large { shift: large };
|
||||||
|
}
|
||||||
|
|
||||||
|
let (u, v) = needle.split_at(critical_pos);
|
||||||
|
if !is_suffix(&v[..period_lower_bound], u) {
|
||||||
|
return Shift::Large { shift: large };
|
||||||
|
}
|
||||||
|
Shift::Small { period: period_lower_bound }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Compute the shift for a given needle in the reverse direction.
|
||||||
|
///
|
||||||
|
/// This requires a lower bound on the period and a critical position.
|
||||||
|
/// These can be computed by extracting both the minimal and maximal
|
||||||
|
/// lexicographic suffixes, and choosing the left-most starting position.
|
||||||
|
/// The lower bound on the period is then the period of the chosen suffix.
|
||||||
|
fn reverse(
|
||||||
|
needle: &[u8],
|
||||||
|
period_lower_bound: usize,
|
||||||
|
critical_pos: usize,
|
||||||
|
) -> Shift {
|
||||||
|
let large = cmp::max(critical_pos, needle.len() - critical_pos);
|
||||||
|
if (needle.len() - critical_pos) * 2 >= needle.len() {
|
||||||
|
return Shift::Large { shift: large };
|
||||||
|
}
|
||||||
|
|
||||||
|
let (v, u) = needle.split_at(critical_pos);
|
||||||
|
if !is_prefix(&v[v.len() - period_lower_bound..], u) {
|
||||||
|
return Shift::Large { shift: large };
|
||||||
|
}
|
||||||
|
Shift::Small { period: period_lower_bound }
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A suffix extracted from a needle along with its period.
|
||||||
|
#[derive(Debug)]
|
||||||
|
struct Suffix {
|
||||||
|
/// The starting position of this suffix.
|
||||||
|
///
|
||||||
|
/// If this is a forward suffix, then `&bytes[pos..]` can be used. If this
|
||||||
|
/// is a reverse suffix, then `&bytes[..pos]` can be used. That is, for
|
||||||
|
/// forward suffixes, this is an inclusive starting position, where as for
|
||||||
|
/// reverse suffixes, this is an exclusive ending position.
|
||||||
|
pos: usize,
|
||||||
|
/// The period of this suffix.
|
||||||
|
///
|
||||||
|
/// Note that this is NOT necessarily the period of the string from which
|
||||||
|
/// this suffix comes from. (It is always less than or equal to the period
|
||||||
|
/// of the original string.)
|
||||||
|
period: usize,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Suffix {
|
||||||
|
fn forward(needle: &[u8], kind: SuffixKind) -> Suffix {
|
||||||
|
// suffix represents our maximal (or minimal) suffix, along with
|
||||||
|
// its period.
|
||||||
|
let mut suffix = Suffix { pos: 0, period: 1 };
|
||||||
|
// The start of a suffix in `needle` that we are considering as a
|
||||||
|
// more maximal (or minimal) suffix than what's in `suffix`.
|
||||||
|
let mut candidate_start = 1;
|
||||||
|
// The current offset of our suffixes that we're comparing.
|
||||||
|
//
|
||||||
|
// When the characters at this offset are the same, then we mush on
|
||||||
|
// to the next position since no decision is possible. When the
|
||||||
|
// candidate's character is greater (or lesser) than the corresponding
|
||||||
|
// character than our current maximal (or minimal) suffix, then the
|
||||||
|
// current suffix is changed over to the candidate and we restart our
|
||||||
|
// search. Otherwise, the candidate suffix is no good and we restart
|
||||||
|
// our search on the next candidate.
|
||||||
|
//
|
||||||
|
// The three cases above correspond to the three cases in the loop
|
||||||
|
// below.
|
||||||
|
let mut offset = 0;
|
||||||
|
|
||||||
|
while candidate_start + offset < needle.len() {
|
||||||
|
let current = needle[suffix.pos + offset];
|
||||||
|
let candidate = needle[candidate_start + offset];
|
||||||
|
match kind.cmp(current, candidate) {
|
||||||
|
SuffixOrdering::Accept => {
|
||||||
|
suffix = Suffix { pos: candidate_start, period: 1 };
|
||||||
|
candidate_start += 1;
|
||||||
|
offset = 0;
|
||||||
|
}
|
||||||
|
SuffixOrdering::Skip => {
|
||||||
|
candidate_start += offset + 1;
|
||||||
|
offset = 0;
|
||||||
|
suffix.period = candidate_start - suffix.pos;
|
||||||
|
}
|
||||||
|
SuffixOrdering::Push => {
|
||||||
|
if offset + 1 == suffix.period {
|
||||||
|
candidate_start += suffix.period;
|
||||||
|
offset = 0;
|
||||||
|
} else {
|
||||||
|
offset += 1;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
suffix
|
||||||
|
}
|
||||||
|
|
||||||
|
fn reverse(needle: &[u8], kind: SuffixKind) -> Suffix {
|
||||||
|
// See the comments in `forward` for how this works.
|
||||||
|
let mut suffix = Suffix { pos: needle.len(), period: 1 };
|
||||||
|
if needle.len() == 1 {
|
||||||
|
return suffix;
|
||||||
|
}
|
||||||
|
let mut candidate_start = match needle.len().checked_sub(1) {
|
||||||
|
None => return suffix,
|
||||||
|
Some(candidate_start) => candidate_start,
|
||||||
|
};
|
||||||
|
let mut offset = 0;
|
||||||
|
|
||||||
|
while offset < candidate_start {
|
||||||
|
let current = needle[suffix.pos - offset - 1];
|
||||||
|
let candidate = needle[candidate_start - offset - 1];
|
||||||
|
match kind.cmp(current, candidate) {
|
||||||
|
SuffixOrdering::Accept => {
|
||||||
|
suffix = Suffix { pos: candidate_start, period: 1 };
|
||||||
|
candidate_start -= 1;
|
||||||
|
offset = 0;
|
||||||
|
}
|
||||||
|
SuffixOrdering::Skip => {
|
||||||
|
candidate_start -= offset + 1;
|
||||||
|
offset = 0;
|
||||||
|
suffix.period = suffix.pos - candidate_start;
|
||||||
|
}
|
||||||
|
SuffixOrdering::Push => {
|
||||||
|
if offset + 1 == suffix.period {
|
||||||
|
candidate_start -= suffix.period;
|
||||||
|
offset = 0;
|
||||||
|
} else {
|
||||||
|
offset += 1;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
suffix
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// The kind of suffix to extract.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
enum SuffixKind {
|
||||||
|
/// Extract the smallest lexicographic suffix from a string.
|
||||||
|
///
|
||||||
|
/// Technically, this doesn't actually pick the smallest lexicographic
|
||||||
|
/// suffix. e.g., Given the choice between `a` and `aa`, this will choose
|
||||||
|
/// the latter over the former, even though `a < aa`. The reasoning for
|
||||||
|
/// this isn't clear from the paper, but it still smells like a minimal
|
||||||
|
/// suffix.
|
||||||
|
Minimal,
|
||||||
|
/// Extract the largest lexicographic suffix from a string.
|
||||||
|
///
|
||||||
|
/// Unlike `Minimal`, this really does pick the maximum suffix. e.g., Given
|
||||||
|
/// the choice between `z` and `zz`, this will choose the latter over the
|
||||||
|
/// former.
|
||||||
|
Maximal,
|
||||||
|
}
|
||||||
|
|
||||||
|
/// The result of comparing corresponding bytes between two suffixes.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
enum SuffixOrdering {
|
||||||
|
/// This occurs when the given candidate byte indicates that the candidate
|
||||||
|
/// suffix is better than the current maximal (or minimal) suffix. That is,
|
||||||
|
/// the current candidate suffix should supplant the current maximal (or
|
||||||
|
/// minimal) suffix.
|
||||||
|
Accept,
|
||||||
|
/// This occurs when the given candidate byte excludes the candidate suffix
|
||||||
|
/// from being better than the current maximal (or minimal) suffix. That
|
||||||
|
/// is, the current candidate suffix should be dropped and the next one
|
||||||
|
/// should be considered.
|
||||||
|
Skip,
|
||||||
|
/// This occurs when no decision to accept or skip the candidate suffix
|
||||||
|
/// can be made, e.g., when corresponding bytes are equivalent. In this
|
||||||
|
/// case, the next corresponding bytes should be compared.
|
||||||
|
Push,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl SuffixKind {
|
||||||
|
/// Returns true if and only if the given candidate byte indicates that
|
||||||
|
/// it should replace the current suffix as the maximal (or minimal)
|
||||||
|
/// suffix.
|
||||||
|
fn cmp(self, current: u8, candidate: u8) -> SuffixOrdering {
|
||||||
|
use self::SuffixOrdering::*;
|
||||||
|
|
||||||
|
match self {
|
||||||
|
SuffixKind::Minimal if candidate < current => Accept,
|
||||||
|
SuffixKind::Minimal if candidate > current => Skip,
|
||||||
|
SuffixKind::Minimal => Push,
|
||||||
|
SuffixKind::Maximal if candidate > current => Accept,
|
||||||
|
SuffixKind::Maximal if candidate < current => Skip,
|
||||||
|
SuffixKind::Maximal => Push,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A bitset used to track whether a particular byte exists in a needle or not.
|
||||||
|
///
|
||||||
|
/// Namely, bit 'i' is set if and only if byte%64==i for any byte in the
|
||||||
|
/// needle. If a particular byte in the haystack is NOT in this set, then one
|
||||||
|
/// can conclude that it is also not in the needle, and thus, one can advance
|
||||||
|
/// in the haystack by needle.len() bytes.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
struct ApproximateByteSet(u64);
|
||||||
|
|
||||||
|
impl ApproximateByteSet {
|
||||||
|
/// Create a new set from the given needle.
|
||||||
|
fn new(needle: &[u8]) -> ApproximateByteSet {
|
||||||
|
let mut bits = 0;
|
||||||
|
for &b in needle {
|
||||||
|
bits |= 1 << (b % 64);
|
||||||
|
}
|
||||||
|
ApproximateByteSet(bits)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return true if and only if the given byte might be in this set. This
|
||||||
|
/// may return a false positive, but will never return a false negative.
|
||||||
|
#[inline(always)]
|
||||||
|
fn contains(&self, byte: u8) -> bool {
|
||||||
|
self.0 & (1 << (byte % 64)) != 0
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use alloc::vec::Vec;
|
||||||
|
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
/// Convenience wrapper for computing the suffix as a byte string.
|
||||||
|
fn get_suffix_forward(needle: &[u8], kind: SuffixKind) -> (&[u8], usize) {
|
||||||
|
let s = Suffix::forward(needle, kind);
|
||||||
|
(&needle[s.pos..], s.period)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convenience wrapper for computing the reverse suffix as a byte string.
|
||||||
|
fn get_suffix_reverse(needle: &[u8], kind: SuffixKind) -> (&[u8], usize) {
|
||||||
|
let s = Suffix::reverse(needle, kind);
|
||||||
|
(&needle[..s.pos], s.period)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return all of the non-empty suffixes in the given byte string.
|
||||||
|
fn suffixes(bytes: &[u8]) -> Vec<&[u8]> {
|
||||||
|
(0..bytes.len()).map(|i| &bytes[i..]).collect()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return the lexicographically maximal suffix of the given byte string.
|
||||||
|
fn naive_maximal_suffix_forward(needle: &[u8]) -> &[u8] {
|
||||||
|
let mut sufs = suffixes(needle);
|
||||||
|
sufs.sort();
|
||||||
|
sufs.pop().unwrap()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return the lexicographically maximal suffix of the reverse of the given
|
||||||
|
/// byte string.
|
||||||
|
fn naive_maximal_suffix_reverse(needle: &[u8]) -> Vec<u8> {
|
||||||
|
let mut reversed = needle.to_vec();
|
||||||
|
reversed.reverse();
|
||||||
|
let mut got = naive_maximal_suffix_forward(&reversed).to_vec();
|
||||||
|
got.reverse();
|
||||||
|
got
|
||||||
|
}
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(|h, n| Some(
|
||||||
|
Finder::new(n).find(h, n)
|
||||||
|
));
|
||||||
|
define_substring_reverse_quickcheck!(|h, n| Some(
|
||||||
|
FinderRev::new(n).rfind(h, n)
|
||||||
|
));
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.fwd(|h, n| Some(Finder::new(n).find(h, n)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.rev(|h, n| Some(FinderRev::new(n).rfind(h, n)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn suffix_forward() {
|
||||||
|
macro_rules! assert_suffix_min {
|
||||||
|
($given:expr, $expected:expr, $period:expr) => {
|
||||||
|
let (got_suffix, got_period) =
|
||||||
|
get_suffix_forward($given.as_bytes(), SuffixKind::Minimal);
|
||||||
|
let got_suffix = core::str::from_utf8(got_suffix).unwrap();
|
||||||
|
assert_eq!(($expected, $period), (got_suffix, got_period));
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! assert_suffix_max {
|
||||||
|
($given:expr, $expected:expr, $period:expr) => {
|
||||||
|
let (got_suffix, got_period) =
|
||||||
|
get_suffix_forward($given.as_bytes(), SuffixKind::Maximal);
|
||||||
|
let got_suffix = core::str::from_utf8(got_suffix).unwrap();
|
||||||
|
assert_eq!(($expected, $period), (got_suffix, got_period));
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
assert_suffix_min!("a", "a", 1);
|
||||||
|
assert_suffix_max!("a", "a", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("ab", "ab", 2);
|
||||||
|
assert_suffix_max!("ab", "b", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("ba", "a", 1);
|
||||||
|
assert_suffix_max!("ba", "ba", 2);
|
||||||
|
|
||||||
|
assert_suffix_min!("abc", "abc", 3);
|
||||||
|
assert_suffix_max!("abc", "c", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("acb", "acb", 3);
|
||||||
|
assert_suffix_max!("acb", "cb", 2);
|
||||||
|
|
||||||
|
assert_suffix_min!("cba", "a", 1);
|
||||||
|
assert_suffix_max!("cba", "cba", 3);
|
||||||
|
|
||||||
|
assert_suffix_min!("abcabc", "abcabc", 3);
|
||||||
|
assert_suffix_max!("abcabc", "cabc", 3);
|
||||||
|
|
||||||
|
assert_suffix_min!("abcabcabc", "abcabcabc", 3);
|
||||||
|
assert_suffix_max!("abcabcabc", "cabcabc", 3);
|
||||||
|
|
||||||
|
assert_suffix_min!("abczz", "abczz", 5);
|
||||||
|
assert_suffix_max!("abczz", "zz", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("zzabc", "abc", 3);
|
||||||
|
assert_suffix_max!("zzabc", "zzabc", 5);
|
||||||
|
|
||||||
|
assert_suffix_min!("aaa", "aaa", 1);
|
||||||
|
assert_suffix_max!("aaa", "aaa", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("foobar", "ar", 2);
|
||||||
|
assert_suffix_max!("foobar", "r", 1);
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn suffix_reverse() {
|
||||||
|
macro_rules! assert_suffix_min {
|
||||||
|
($given:expr, $expected:expr, $period:expr) => {
|
||||||
|
let (got_suffix, got_period) =
|
||||||
|
get_suffix_reverse($given.as_bytes(), SuffixKind::Minimal);
|
||||||
|
let got_suffix = core::str::from_utf8(got_suffix).unwrap();
|
||||||
|
assert_eq!(($expected, $period), (got_suffix, got_period));
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! assert_suffix_max {
|
||||||
|
($given:expr, $expected:expr, $period:expr) => {
|
||||||
|
let (got_suffix, got_period) =
|
||||||
|
get_suffix_reverse($given.as_bytes(), SuffixKind::Maximal);
|
||||||
|
let got_suffix = core::str::from_utf8(got_suffix).unwrap();
|
||||||
|
assert_eq!(($expected, $period), (got_suffix, got_period));
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
assert_suffix_min!("a", "a", 1);
|
||||||
|
assert_suffix_max!("a", "a", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("ab", "a", 1);
|
||||||
|
assert_suffix_max!("ab", "ab", 2);
|
||||||
|
|
||||||
|
assert_suffix_min!("ba", "ba", 2);
|
||||||
|
assert_suffix_max!("ba", "b", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("abc", "a", 1);
|
||||||
|
assert_suffix_max!("abc", "abc", 3);
|
||||||
|
|
||||||
|
assert_suffix_min!("acb", "a", 1);
|
||||||
|
assert_suffix_max!("acb", "ac", 2);
|
||||||
|
|
||||||
|
assert_suffix_min!("cba", "cba", 3);
|
||||||
|
assert_suffix_max!("cba", "c", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("abcabc", "abca", 3);
|
||||||
|
assert_suffix_max!("abcabc", "abcabc", 3);
|
||||||
|
|
||||||
|
assert_suffix_min!("abcabcabc", "abcabca", 3);
|
||||||
|
assert_suffix_max!("abcabcabc", "abcabcabc", 3);
|
||||||
|
|
||||||
|
assert_suffix_min!("abczz", "a", 1);
|
||||||
|
assert_suffix_max!("abczz", "abczz", 5);
|
||||||
|
|
||||||
|
assert_suffix_min!("zzabc", "zza", 3);
|
||||||
|
assert_suffix_max!("zzabc", "zz", 1);
|
||||||
|
|
||||||
|
assert_suffix_min!("aaa", "aaa", 1);
|
||||||
|
assert_suffix_max!("aaa", "aaa", 1);
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
quickcheck::quickcheck! {
|
||||||
|
fn qc_suffix_forward_maximal(bytes: Vec<u8>) -> bool {
|
||||||
|
if bytes.is_empty() {
|
||||||
|
return true;
|
||||||
|
}
|
||||||
|
|
||||||
|
let (got, _) = get_suffix_forward(&bytes, SuffixKind::Maximal);
|
||||||
|
let expected = naive_maximal_suffix_forward(&bytes);
|
||||||
|
got == expected
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_suffix_reverse_maximal(bytes: Vec<u8>) -> bool {
|
||||||
|
if bytes.is_empty() {
|
||||||
|
return true;
|
||||||
|
}
|
||||||
|
|
||||||
|
let (got, _) = get_suffix_reverse(&bytes, SuffixKind::Maximal);
|
||||||
|
let expected = naive_maximal_suffix_reverse(&bytes);
|
||||||
|
expected == got
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// This is a regression test caught by quickcheck that exercised a bug in
|
||||||
|
// the reverse small period handling. The bug was that we were using 'if j
|
||||||
|
// == shift' to determine if a match occurred, but the correct guard is 'if
|
||||||
|
// j >= shift', which matches the corresponding guard in the forward impl.
|
||||||
|
#[test]
|
||||||
|
fn regression_rev_small_period() {
|
||||||
|
let rfind = |h, n| FinderRev::new(n).rfind(h, n);
|
||||||
|
let haystack = "ababaz";
|
||||||
|
let needle = "abab";
|
||||||
|
assert_eq!(Some(0), rfind(haystack.as_bytes(), needle.as_bytes()));
|
||||||
|
}
|
||||||
|
}
|
||||||
1220
third_party/crates/memchr-2.8.3/src/arch/generic/memchr.rs
vendored
Normal file
1220
third_party/crates/memchr-2.8.3/src/arch/generic/memchr.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
14
third_party/crates/memchr-2.8.3/src/arch/generic/mod.rs
vendored
Normal file
14
third_party/crates/memchr-2.8.3/src/arch/generic/mod.rs
vendored
Normal file
@@ -0,0 +1,14 @@
|
|||||||
|
/*!
|
||||||
|
This module defines "generic" routines that can be specialized to specific
|
||||||
|
architectures.
|
||||||
|
|
||||||
|
We don't expose this module primarily because it would require exposing all
|
||||||
|
of the internal infrastructure required to write these generic routines.
|
||||||
|
That infrastructure should be treated as an implementation detail so that
|
||||||
|
it is allowed to evolve. Instead, what we expose are architecture specific
|
||||||
|
instantiations of these generic implementations. The generic code just lets us
|
||||||
|
write the code once (usually).
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub(crate) mod memchr;
|
||||||
|
pub(crate) mod packedpair;
|
||||||
317
third_party/crates/memchr-2.8.3/src/arch/generic/packedpair.rs
vendored
Normal file
317
third_party/crates/memchr-2.8.3/src/arch/generic/packedpair.rs
vendored
Normal file
@@ -0,0 +1,317 @@
|
|||||||
|
/*!
|
||||||
|
Generic crate-internal routines for the "packed pair" SIMD algorithm.
|
||||||
|
|
||||||
|
The "packed pair" algorithm is based on the [generic SIMD] algorithm. The main
|
||||||
|
difference is that it (by default) uses a background distribution of byte
|
||||||
|
frequencies to heuristically select the pair of bytes to search for.
|
||||||
|
|
||||||
|
[generic SIMD]: http://0x80.pl/articles/simd-strfind.html#first-and-last
|
||||||
|
*/
|
||||||
|
|
||||||
|
use crate::{
|
||||||
|
arch::all::{is_equal_raw, packedpair::Pair},
|
||||||
|
ext::Pointer,
|
||||||
|
vector::{MoveMask, Vector},
|
||||||
|
};
|
||||||
|
|
||||||
|
/// A generic architecture dependent "packed pair" finder.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power
|
||||||
|
/// for indicating an overall match of a needle. Depending on whether
|
||||||
|
/// `Finder::find` or `Finder::find_prefilter` is used, it reports offsets
|
||||||
|
/// where the needle matches or could match. In the prefilter case, candidates
|
||||||
|
/// are reported whenever the [`Pair`] of bytes given matches.
|
||||||
|
///
|
||||||
|
/// This is architecture dependent because it uses specific vector operations
|
||||||
|
/// to look for occurrences of the pair of bytes.
|
||||||
|
///
|
||||||
|
/// This type is not meant to be exported and is instead meant to be used as
|
||||||
|
/// the implementation for architecture specific facades. Why? Because it's a
|
||||||
|
/// bit of a quirky API that requires `inline(always)` annotations. And pretty
|
||||||
|
/// much everything has safety obligations due (at least) to the caller needing
|
||||||
|
/// to inline calls into routines marked with
|
||||||
|
/// `#[target_feature(enable = "...")]`.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub(crate) struct Finder<V> {
|
||||||
|
pair: Pair,
|
||||||
|
v1: V,
|
||||||
|
v2: V,
|
||||||
|
min_haystack_len: usize,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<V: Vector> Finder<V> {
|
||||||
|
/// Create a new pair searcher. The searcher returned can either report
|
||||||
|
/// exact matches of `needle` or act as a prefilter and report candidate
|
||||||
|
/// positions of `needle`.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Callers must ensure that whatever vector type this routine is called
|
||||||
|
/// with is supported by the current environment.
|
||||||
|
///
|
||||||
|
/// Callers must also ensure that `needle.len() >= 2`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn new(needle: &[u8], pair: Pair) -> Finder<V> {
|
||||||
|
let max_index = pair.index1().max(pair.index2());
|
||||||
|
let min_haystack_len =
|
||||||
|
core::cmp::max(needle.len(), usize::from(max_index) + V::BYTES);
|
||||||
|
let v1 = V::splat(needle[usize::from(pair.index1())]);
|
||||||
|
let v2 = V::splat(needle[usize::from(pair.index2())]);
|
||||||
|
Finder { pair, v1, v2, min_haystack_len }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Searches the given haystack for the given needle. The needle given
|
||||||
|
/// should be the same as the needle that this finder was initialized
|
||||||
|
/// with.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Since this is meant to be used with vector functions, callers need to
|
||||||
|
/// specialize this inside of a function with a `target_feature` attribute.
|
||||||
|
/// Therefore, callers must ensure that whatever target feature is being
|
||||||
|
/// used supports the vector functions that this function is specialized
|
||||||
|
/// for. (For the specific vector functions used, see the Vector trait
|
||||||
|
/// implementations.)
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn find(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
assert!(
|
||||||
|
haystack.len() >= self.min_haystack_len,
|
||||||
|
"haystack too small, should be at least {} but got {}",
|
||||||
|
self.min_haystack_len,
|
||||||
|
haystack.len(),
|
||||||
|
);
|
||||||
|
|
||||||
|
let all = V::Mask::all_zeros_except_least_significant(0);
|
||||||
|
let start = haystack.as_ptr();
|
||||||
|
let end = start.add(haystack.len());
|
||||||
|
let max = end.sub(self.min_haystack_len);
|
||||||
|
let mut cur = start;
|
||||||
|
|
||||||
|
// N.B. I did experiment with unrolling the loop to deal with size(V)
|
||||||
|
// bytes at a time and 2*size(V) bytes at a time. The double unroll
|
||||||
|
// was marginally faster while the quadruple unroll was unambiguously
|
||||||
|
// slower. In the end, I decided the complexity from unrolling wasn't
|
||||||
|
// worth it. I used the memmem/krate/prebuilt/huge-en/ benchmarks to
|
||||||
|
// compare.
|
||||||
|
while cur <= max {
|
||||||
|
if let Some(chunki) = self.find_in_chunk(needle, cur, end, all) {
|
||||||
|
return Some(matched(start, cur, chunki));
|
||||||
|
}
|
||||||
|
cur = cur.add(V::BYTES);
|
||||||
|
}
|
||||||
|
if cur < end {
|
||||||
|
let remaining = end.distance(cur);
|
||||||
|
debug_assert!(
|
||||||
|
remaining < self.min_haystack_len,
|
||||||
|
"remaining bytes should be smaller than the minimum haystack \
|
||||||
|
length of {}, but there are {} bytes remaining",
|
||||||
|
self.min_haystack_len,
|
||||||
|
remaining,
|
||||||
|
);
|
||||||
|
if remaining < needle.len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
debug_assert!(
|
||||||
|
max < cur,
|
||||||
|
"after main loop, cur should have exceeded max",
|
||||||
|
);
|
||||||
|
let overlap = cur.distance(max);
|
||||||
|
debug_assert!(
|
||||||
|
overlap > 0,
|
||||||
|
"overlap ({}) must always be non-zero",
|
||||||
|
overlap,
|
||||||
|
);
|
||||||
|
debug_assert!(
|
||||||
|
overlap < V::BYTES,
|
||||||
|
"overlap ({}) cannot possibly be >= than a vector ({})",
|
||||||
|
overlap,
|
||||||
|
V::BYTES,
|
||||||
|
);
|
||||||
|
// The mask has all of its bits set except for the first N least
|
||||||
|
// significant bits, where N=overlap. This way, any matches that
|
||||||
|
// occur in find_in_chunk within the overlap are automatically
|
||||||
|
// ignored.
|
||||||
|
let mask = V::Mask::all_zeros_except_least_significant(overlap);
|
||||||
|
cur = max;
|
||||||
|
let m = self.find_in_chunk(needle, cur, end, mask);
|
||||||
|
if let Some(chunki) = m {
|
||||||
|
return Some(matched(start, cur, chunki));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Searches the given haystack for offsets that represent candidate
|
||||||
|
/// matches of the `needle` given to this finder's constructor. The offsets
|
||||||
|
/// returned, if they are a match, correspond to the starting offset of
|
||||||
|
/// `needle` in the given `haystack`.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Since this is meant to be used with vector functions, callers need to
|
||||||
|
/// specialize this inside of a function with a `target_feature` attribute.
|
||||||
|
/// Therefore, callers must ensure that whatever target feature is being
|
||||||
|
/// used supports the vector functions that this function is specialized
|
||||||
|
/// for. (For the specific vector functions used, see the Vector trait
|
||||||
|
/// implementations.)
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn find_prefilter(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
assert!(
|
||||||
|
haystack.len() >= self.min_haystack_len,
|
||||||
|
"haystack too small, should be at least {} but got {}",
|
||||||
|
self.min_haystack_len,
|
||||||
|
haystack.len(),
|
||||||
|
);
|
||||||
|
|
||||||
|
let start = haystack.as_ptr();
|
||||||
|
let end = start.add(haystack.len());
|
||||||
|
let max = end.sub(self.min_haystack_len);
|
||||||
|
let mut cur = start;
|
||||||
|
|
||||||
|
// N.B. I did experiment with unrolling the loop to deal with size(V)
|
||||||
|
// bytes at a time and 2*size(V) bytes at a time. The double unroll
|
||||||
|
// was marginally faster while the quadruple unroll was unambiguously
|
||||||
|
// slower. In the end, I decided the complexity from unrolling wasn't
|
||||||
|
// worth it. I used the memmem/krate/prebuilt/huge-en/ benchmarks to
|
||||||
|
// compare.
|
||||||
|
while cur <= max {
|
||||||
|
if let Some(chunki) = self.find_prefilter_in_chunk(cur) {
|
||||||
|
return Some(matched(start, cur, chunki));
|
||||||
|
}
|
||||||
|
cur = cur.add(V::BYTES);
|
||||||
|
}
|
||||||
|
if cur < end {
|
||||||
|
// This routine immediately quits if a candidate match is found.
|
||||||
|
// That means that if we're here, no candidate matches have been
|
||||||
|
// found at or before 'ptr'. Thus, we don't need to mask anything
|
||||||
|
// out even though we might technically search part of the haystack
|
||||||
|
// that we've already searched (because we know it can't match).
|
||||||
|
cur = max;
|
||||||
|
if let Some(chunki) = self.find_prefilter_in_chunk(cur) {
|
||||||
|
return Some(matched(start, cur, chunki));
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for an occurrence of our byte pair from the needle in the chunk
|
||||||
|
/// pointed to by cur, with the end of the haystack pointed to by end.
|
||||||
|
/// When an occurrence is found, memcmp is run to check if a match occurs
|
||||||
|
/// at the corresponding position.
|
||||||
|
///
|
||||||
|
/// `mask` should have bits set corresponding the positions in the chunk
|
||||||
|
/// in which matches are considered. This is only used for the last vector
|
||||||
|
/// load where the beginning of the vector might have overlapped with the
|
||||||
|
/// last load in the main loop. The mask lets us avoid visiting positions
|
||||||
|
/// that have already been discarded as matches.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// It must be safe to do an unaligned read of size(V) bytes starting at
|
||||||
|
/// both (cur + self.index1) and (cur + self.index2). It must also be safe
|
||||||
|
/// to do unaligned loads on cur up to (end - needle.len()).
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn find_in_chunk(
|
||||||
|
&self,
|
||||||
|
needle: &[u8],
|
||||||
|
cur: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
mask: V::Mask,
|
||||||
|
) -> Option<usize> {
|
||||||
|
let index1 = usize::from(self.pair.index1());
|
||||||
|
let index2 = usize::from(self.pair.index2());
|
||||||
|
let chunk1 = V::load_unaligned(cur.add(index1));
|
||||||
|
let chunk2 = V::load_unaligned(cur.add(index2));
|
||||||
|
let eq1 = chunk1.cmpeq(self.v1);
|
||||||
|
let eq2 = chunk2.cmpeq(self.v2);
|
||||||
|
|
||||||
|
let mut offsets = eq1.and(eq2).movemask().and(mask);
|
||||||
|
while offsets.has_non_zero() {
|
||||||
|
let offset = offsets.first_offset();
|
||||||
|
let cur = cur.add(offset);
|
||||||
|
if end.distance(cur) < needle.len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
if is_equal_raw(needle.as_ptr(), cur, needle.len()) {
|
||||||
|
return Some(offset);
|
||||||
|
}
|
||||||
|
offsets = offsets.clear_least_significant_bit();
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for an occurrence of our byte pair from the needle in the chunk
|
||||||
|
/// pointed to by cur, with the end of the haystack pointed to by end.
|
||||||
|
/// When an occurrence is found, memcmp is run to check if a match occurs
|
||||||
|
/// at the corresponding position.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// It must be safe to do an unaligned read of size(V) bytes starting at
|
||||||
|
/// both (cur + self.index1) and (cur + self.index2). It must also be safe
|
||||||
|
/// to do unaligned reads on cur up to (end - needle.len()).
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn find_prefilter_in_chunk(&self, cur: *const u8) -> Option<usize> {
|
||||||
|
let index1 = usize::from(self.pair.index1());
|
||||||
|
let index2 = usize::from(self.pair.index2());
|
||||||
|
let chunk1 = V::load_unaligned(cur.add(index1));
|
||||||
|
let chunk2 = V::load_unaligned(cur.add(index2));
|
||||||
|
let eq1 = chunk1.cmpeq(self.v1);
|
||||||
|
let eq2 = chunk2.cmpeq(self.v2);
|
||||||
|
|
||||||
|
let offsets = eq1.and(eq2).movemask();
|
||||||
|
if !offsets.has_non_zero() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(offsets.first_offset())
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the pair of offsets (into the needle) used to check as a
|
||||||
|
/// predicate before confirming whether a needle exists at a particular
|
||||||
|
/// position.
|
||||||
|
#[inline]
|
||||||
|
pub(crate) fn pair(&self) -> &Pair {
|
||||||
|
&self.pair
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the minimum haystack length that this `Finder` can search.
|
||||||
|
///
|
||||||
|
/// Providing a haystack to this `Finder` shorter than this length is
|
||||||
|
/// guaranteed to result in a panic.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn min_haystack_len(&self) -> usize {
|
||||||
|
self.min_haystack_len
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Accepts a chunk-relative offset and returns a haystack relative offset.
|
||||||
|
///
|
||||||
|
/// This used to be marked `#[cold]` and `#[inline(never)]`, but I couldn't
|
||||||
|
/// observe a consistent measureable difference between that and just inlining
|
||||||
|
/// it. So we go with inlining it.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same at `ptr::offset_from` in addition to `cur >= start`.
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn matched(start: *const u8, cur: *const u8, chunki: usize) -> usize {
|
||||||
|
cur.distance(start) + chunki
|
||||||
|
}
|
||||||
|
|
||||||
|
// If you're looking for tests, those are run for each instantiation of the
|
||||||
|
// above code. So for example, see arch::x86_64::sse2::packedpair.
|
||||||
16
third_party/crates/memchr-2.8.3/src/arch/mod.rs
vendored
Normal file
16
third_party/crates/memchr-2.8.3/src/arch/mod.rs
vendored
Normal file
@@ -0,0 +1,16 @@
|
|||||||
|
/*!
|
||||||
|
A module with low-level architecture dependent routines.
|
||||||
|
|
||||||
|
These routines are useful as primitives for tasks not covered by the higher
|
||||||
|
level crate API.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod all;
|
||||||
|
pub(crate) mod generic;
|
||||||
|
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
pub mod aarch64;
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
pub mod wasm32;
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
pub mod x86_64;
|
||||||
124
third_party/crates/memchr-2.8.3/src/arch/wasm32/memchr.rs
vendored
Normal file
124
third_party/crates/memchr-2.8.3/src/arch/wasm32/memchr.rs
vendored
Normal file
@@ -0,0 +1,124 @@
|
|||||||
|
/*!
|
||||||
|
Wrapper routines for `memchr` and friends.
|
||||||
|
|
||||||
|
These routines choose the best implementation at compile time. (This is
|
||||||
|
different from `x86_64` because it is expected that `simd128` is almost always
|
||||||
|
available for `wasm32` targets.)
|
||||||
|
*/
|
||||||
|
|
||||||
|
macro_rules! defraw {
|
||||||
|
($ty:ident, $find:ident, $start:ident, $end:ident, $($needles:ident),+) => {{
|
||||||
|
use crate::arch::wasm32::simd128::memchr::$ty;
|
||||||
|
|
||||||
|
debug!("chose simd128 for {}", stringify!($ty));
|
||||||
|
debug_assert!($ty::is_available());
|
||||||
|
// SAFETY: We know that wasm memchr is always available whenever
|
||||||
|
// code is compiled for `wasm32` with the `simd128` target feature
|
||||||
|
// enabled.
|
||||||
|
$ty::new_unchecked($($needles),+).$find($start, $end)
|
||||||
|
}}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(One, find_raw, start, end, n1)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(One, rfind_raw, start, end, n1)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr2_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Two, find_raw, start, end, n1, n2)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr2_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Two, rfind_raw, start, end, n1, n2)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr3_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Three, find_raw, start, end, n1, n2, n3)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr3_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
defraw!(Three, rfind_raw, start, end, n1, n2, n3)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Count all matching bytes, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::count_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn count_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> usize {
|
||||||
|
defraw!(One, count_raw, start, end, n1)
|
||||||
|
}
|
||||||
7
third_party/crates/memchr-2.8.3/src/arch/wasm32/mod.rs
vendored
Normal file
7
third_party/crates/memchr-2.8.3/src/arch/wasm32/mod.rs
vendored
Normal file
@@ -0,0 +1,7 @@
|
|||||||
|
/*!
|
||||||
|
Vector algorithms for the `wasm32` target.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod simd128;
|
||||||
|
|
||||||
|
pub(crate) mod memchr;
|
||||||
1020
third_party/crates/memchr-2.8.3/src/arch/wasm32/simd128/memchr.rs
vendored
Normal file
1020
third_party/crates/memchr-2.8.3/src/arch/wasm32/simd128/memchr.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
6
third_party/crates/memchr-2.8.3/src/arch/wasm32/simd128/mod.rs
vendored
Normal file
6
third_party/crates/memchr-2.8.3/src/arch/wasm32/simd128/mod.rs
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
/*!
|
||||||
|
Algorithms for the `wasm32` target using 128-bit vectors via simd128.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod memchr;
|
||||||
|
pub mod packedpair;
|
||||||
228
third_party/crates/memchr-2.8.3/src/arch/wasm32/simd128/packedpair.rs
vendored
Normal file
228
third_party/crates/memchr-2.8.3/src/arch/wasm32/simd128/packedpair.rs
vendored
Normal file
@@ -0,0 +1,228 @@
|
|||||||
|
/*!
|
||||||
|
A 128-bit vector implementation of the "packed pair" SIMD algorithm.
|
||||||
|
|
||||||
|
The "packed pair" algorithm is based on the [generic SIMD] algorithm. The main
|
||||||
|
difference is that it (by default) uses a background distribution of byte
|
||||||
|
frequencies to heuristically select the pair of bytes to search for.
|
||||||
|
|
||||||
|
[generic SIMD]: http://0x80.pl/articles/simd-strfind.html#first-and-last
|
||||||
|
*/
|
||||||
|
|
||||||
|
use core::arch::wasm32::v128;
|
||||||
|
|
||||||
|
use crate::arch::{all::packedpair::Pair, generic::packedpair};
|
||||||
|
|
||||||
|
/// A "packed pair" finder that uses 128-bit vector operations.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power
|
||||||
|
/// for indicating an overall match of a needle. Depending on whether
|
||||||
|
/// `Finder::find` or `Finder::find_prefilter` is used, it reports offsets
|
||||||
|
/// where the needle matches or could match. In the prefilter case, candidates
|
||||||
|
/// are reported whenever the [`Pair`] of bytes given matches.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Finder(packedpair::Finder<v128>);
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
/// Create a new pair searcher. The searcher returned can either report
|
||||||
|
/// exact matches of `needle` or act as a prefilter and report candidate
|
||||||
|
/// positions of `needle`.
|
||||||
|
///
|
||||||
|
/// If simd128 is unavailable in the current environment or if a [`Pair`]
|
||||||
|
/// could not be constructed from the needle given, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Finder> {
|
||||||
|
Finder::with_pair(needle, Pair::new(needle)?)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new "packed pair" finder using the pair of bytes given.
|
||||||
|
///
|
||||||
|
/// This constructor permits callers to control precisely which pair of
|
||||||
|
/// bytes is used as a predicate.
|
||||||
|
///
|
||||||
|
/// If simd128 is unavailable in the current environment, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_pair(needle: &[u8], pair: Pair) -> Option<Finder> {
|
||||||
|
if Finder::is_available() {
|
||||||
|
// SAFETY: we check that simd128 is available above. We are also
|
||||||
|
// guaranteed to have needle.len() > 1 because we have a valid
|
||||||
|
// Pair.
|
||||||
|
unsafe { Some(Finder::with_pair_impl(needle, pair)) }
|
||||||
|
} else {
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new `Finder` specific to simd128 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same as the safety for `packedpair::Finder::new`, and callers must also
|
||||||
|
/// ensure that simd128 is available.
|
||||||
|
#[target_feature(enable = "simd128")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn with_pair_impl(needle: &[u8], pair: Pair) -> Finder {
|
||||||
|
let finder = packedpair::Finder::<v128>::new(needle, pair);
|
||||||
|
Finder(finder)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns true when this implementation is available in the current
|
||||||
|
/// environment.
|
||||||
|
///
|
||||||
|
/// When this is true, it is guaranteed that [`Finder::with_pair`] will
|
||||||
|
/// return a `Some` value. Similarly, when it is false, it is guaranteed
|
||||||
|
/// that `Finder::with_pair` will return a `None` value. Notice that this
|
||||||
|
/// does not guarantee that [`Finder::new`] will return a `Finder`. Namely,
|
||||||
|
/// even when `Finder::is_available` is true, it is not guaranteed that a
|
||||||
|
/// valid [`Pair`] can be found from the needle given.
|
||||||
|
///
|
||||||
|
/// Note also that for the lifetime of a single program, if this returns
|
||||||
|
/// true then it will always return true.
|
||||||
|
#[inline]
|
||||||
|
pub fn is_available() -> bool {
|
||||||
|
// We used to gate on `cfg(target_feature = "simd128")` here, but
|
||||||
|
// we've since required the feature to be enabled at compile time to
|
||||||
|
// even include this module at all. Therefore, it is always enabled
|
||||||
|
// in this context. See the linked issue for why this was changed.
|
||||||
|
//
|
||||||
|
// Ref: https://github.com/BurntSushi/memchr/issues/144
|
||||||
|
true
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using wasm32 v128 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
self.find_impl(haystack, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using wasm32 v128 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find_prefilter(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
self.find_prefilter_impl(haystack)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using wasm32 v128 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `simd128` routines.)
|
||||||
|
#[target_feature(enable = "simd128")]
|
||||||
|
#[inline]
|
||||||
|
fn find_impl(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: The target feature safety obligation is automatically
|
||||||
|
// fulfilled by virtue of being a method on `Finder`, which can only be
|
||||||
|
// constructed when it is safe to call `simd128` routines.
|
||||||
|
unsafe { self.0.find(haystack, needle) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a prefilter search using wasm32 v128 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `simd128` routines.)
|
||||||
|
#[target_feature(enable = "simd128")]
|
||||||
|
#[inline]
|
||||||
|
fn find_prefilter_impl(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: The target feature safety obligation is automatically
|
||||||
|
// fulfilled by virtue of being a method on `Finder`, which can only be
|
||||||
|
// constructed when it is safe to call `simd128` routines.
|
||||||
|
unsafe { self.0.find_prefilter(haystack) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the pair of offsets (into the needle) used to check as a
|
||||||
|
/// predicate before confirming whether a needle exists at a particular
|
||||||
|
/// position.
|
||||||
|
#[inline]
|
||||||
|
pub fn pair(&self) -> &Pair {
|
||||||
|
self.0.pair()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the minimum haystack length that this `Finder` can search.
|
||||||
|
///
|
||||||
|
/// Using a haystack with length smaller than this in a search will result
|
||||||
|
/// in a panic. The reason for this restriction is that this finder is
|
||||||
|
/// meant to be a low-level component that is part of a larger substring
|
||||||
|
/// strategy. In that sense, it avoids trying to handle all cases and
|
||||||
|
/// instead only handles the cases that it can handle very well.
|
||||||
|
#[inline]
|
||||||
|
pub fn min_haystack_len(&self) -> usize {
|
||||||
|
self.0.min_haystack_len()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
fn find(haystack: &[u8], needle: &[u8]) -> Option<Option<usize>> {
|
||||||
|
let f = Finder::new(needle)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(find);
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_substring() {
|
||||||
|
crate::tests::substring::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair_prefilter() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find_prefilter(haystack))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
}
|
||||||
1352
third_party/crates/memchr-2.8.3/src/arch/x86_64/avx2/memchr.rs
vendored
Normal file
1352
third_party/crates/memchr-2.8.3/src/arch/x86_64/avx2/memchr.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
6
third_party/crates/memchr-2.8.3/src/arch/x86_64/avx2/mod.rs
vendored
Normal file
6
third_party/crates/memchr-2.8.3/src/arch/x86_64/avx2/mod.rs
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
/*!
|
||||||
|
Algorithms for the `x86_64` target using 256-bit vectors via AVX2.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod memchr;
|
||||||
|
pub mod packedpair;
|
||||||
272
third_party/crates/memchr-2.8.3/src/arch/x86_64/avx2/packedpair.rs
vendored
Normal file
272
third_party/crates/memchr-2.8.3/src/arch/x86_64/avx2/packedpair.rs
vendored
Normal file
@@ -0,0 +1,272 @@
|
|||||||
|
/*!
|
||||||
|
A 256-bit vector implementation of the "packed pair" SIMD algorithm.
|
||||||
|
|
||||||
|
The "packed pair" algorithm is based on the [generic SIMD] algorithm. The main
|
||||||
|
difference is that it (by default) uses a background distribution of byte
|
||||||
|
frequencies to heuristically select the pair of bytes to search for.
|
||||||
|
|
||||||
|
[generic SIMD]: http://0x80.pl/articles/simd-strfind.html#first-and-last
|
||||||
|
*/
|
||||||
|
|
||||||
|
use core::arch::x86_64::{__m128i, __m256i};
|
||||||
|
|
||||||
|
use crate::arch::{all::packedpair::Pair, generic::packedpair};
|
||||||
|
|
||||||
|
/// A "packed pair" finder that uses 256-bit vector operations.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power
|
||||||
|
/// for indicating an overall match of a needle. Depending on whether
|
||||||
|
/// `Finder::find` or `Finder::find_prefilter` is used, it reports offsets
|
||||||
|
/// where the needle matches or could match. In the prefilter case, candidates
|
||||||
|
/// are reported whenever the [`Pair`] of bytes given matches.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Finder {
|
||||||
|
sse2: packedpair::Finder<__m128i>,
|
||||||
|
avx2: packedpair::Finder<__m256i>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
/// Create a new pair searcher. The searcher returned can either report
|
||||||
|
/// exact matches of `needle` or act as a prefilter and report candidate
|
||||||
|
/// positions of `needle`.
|
||||||
|
///
|
||||||
|
/// If AVX2 is unavailable in the current environment or if a [`Pair`]
|
||||||
|
/// could not be constructed from the needle given, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Finder> {
|
||||||
|
Finder::with_pair(needle, Pair::new(needle)?)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new "packed pair" finder using the pair of bytes given.
|
||||||
|
///
|
||||||
|
/// This constructor permits callers to control precisely which pair of
|
||||||
|
/// bytes is used as a predicate.
|
||||||
|
///
|
||||||
|
/// If AVX2 is unavailable in the current environment, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_pair(needle: &[u8], pair: Pair) -> Option<Finder> {
|
||||||
|
if Finder::is_available() {
|
||||||
|
// SAFETY: we check that sse2/avx2 is available above. We are also
|
||||||
|
// guaranteed to have needle.len() > 1 because we have a valid
|
||||||
|
// Pair.
|
||||||
|
unsafe { Some(Finder::with_pair_impl(needle, pair)) }
|
||||||
|
} else {
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new `Finder` specific to SSE2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same as the safety for `packedpair::Finder::new`, and callers must also
|
||||||
|
/// ensure that both SSE2 and AVX2 are available.
|
||||||
|
#[target_feature(enable = "sse2", enable = "avx2")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn with_pair_impl(needle: &[u8], pair: Pair) -> Finder {
|
||||||
|
let sse2 = packedpair::Finder::<__m128i>::new(needle, pair);
|
||||||
|
let avx2 = packedpair::Finder::<__m256i>::new(needle, pair);
|
||||||
|
Finder { sse2, avx2 }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns true when this implementation is available in the current
|
||||||
|
/// environment.
|
||||||
|
///
|
||||||
|
/// When this is true, it is guaranteed that [`Finder::with_pair`] will
|
||||||
|
/// return a `Some` value. Similarly, when it is false, it is guaranteed
|
||||||
|
/// that `Finder::with_pair` will return a `None` value. Notice that this
|
||||||
|
/// does not guarantee that [`Finder::new`] will return a `Finder`. Namely,
|
||||||
|
/// even when `Finder::is_available` is true, it is not guaranteed that a
|
||||||
|
/// valid [`Pair`] can be found from the needle given.
|
||||||
|
///
|
||||||
|
/// Note also that for the lifetime of a single program, if this returns
|
||||||
|
/// true then it will always return true.
|
||||||
|
#[inline]
|
||||||
|
pub fn is_available() -> bool {
|
||||||
|
#[cfg(not(target_feature = "sse2"))]
|
||||||
|
{
|
||||||
|
false
|
||||||
|
}
|
||||||
|
#[cfg(target_feature = "sse2")]
|
||||||
|
{
|
||||||
|
#[cfg(target_feature = "avx2")]
|
||||||
|
{
|
||||||
|
true
|
||||||
|
}
|
||||||
|
#[cfg(not(target_feature = "avx2"))]
|
||||||
|
{
|
||||||
|
#[cfg(feature = "std")]
|
||||||
|
{
|
||||||
|
std::is_x86_feature_detected!("avx2")
|
||||||
|
}
|
||||||
|
#[cfg(not(feature = "std"))]
|
||||||
|
{
|
||||||
|
false
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using AVX2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: Building a `Finder` means it's safe to call 'sse2' routines.
|
||||||
|
unsafe { self.find_impl(haystack, needle) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run this finder on the given haystack as a prefilter.
|
||||||
|
///
|
||||||
|
/// If a candidate match is found, then an offset where the needle *could*
|
||||||
|
/// begin in the haystack is returned.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find_prefilter(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: Building a `Finder` means it's safe to call 'sse2' routines.
|
||||||
|
unsafe { self.find_prefilter_impl(haystack) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using AVX2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `sse2` and `avx2` routines.)
|
||||||
|
#[target_feature(enable = "sse2", enable = "avx2")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn find_impl(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
if haystack.len() < self.avx2.min_haystack_len() {
|
||||||
|
self.sse2.find(haystack, needle)
|
||||||
|
} else {
|
||||||
|
self.avx2.find(haystack, needle)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a prefilter search using AVX2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `sse2` and `avx2` routines.)
|
||||||
|
#[target_feature(enable = "sse2", enable = "avx2")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn find_prefilter_impl(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
if haystack.len() < self.avx2.min_haystack_len() {
|
||||||
|
self.sse2.find_prefilter(haystack)
|
||||||
|
} else {
|
||||||
|
self.avx2.find_prefilter(haystack)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the pair of offsets (into the needle) used to check as a
|
||||||
|
/// predicate before confirming whether a needle exists at a particular
|
||||||
|
/// position.
|
||||||
|
#[inline]
|
||||||
|
pub fn pair(&self) -> &Pair {
|
||||||
|
self.avx2.pair()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the minimum haystack length that this `Finder` can search.
|
||||||
|
///
|
||||||
|
/// Using a haystack with length smaller than this in a search will result
|
||||||
|
/// in a panic. The reason for this restriction is that this finder is
|
||||||
|
/// meant to be a low-level component that is part of a larger substring
|
||||||
|
/// strategy. In that sense, it avoids trying to handle all cases and
|
||||||
|
/// instead only handles the cases that it can handle very well.
|
||||||
|
#[inline]
|
||||||
|
pub fn min_haystack_len(&self) -> usize {
|
||||||
|
// The caller doesn't need to care about AVX2's min_haystack_len
|
||||||
|
// since this implementation will automatically switch to the SSE2
|
||||||
|
// implementation if the haystack is too short for AVX2. Therefore, the
|
||||||
|
// caller only needs to care about SSE2's min_haystack_len.
|
||||||
|
//
|
||||||
|
// This does assume that SSE2's min_haystack_len is less than or
|
||||||
|
// equal to AVX2's min_haystack_len. In practice, this is true and
|
||||||
|
// there is no way it could be false based on how this Finder is
|
||||||
|
// implemented. Namely, both SSE2 and AVX2 use the same `Pair`. If
|
||||||
|
// they used different pairs, then it's possible (although perhaps
|
||||||
|
// pathological) for SSE2's min_haystack_len to be bigger than AVX2's.
|
||||||
|
self.sse2.min_haystack_len()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
fn find(haystack: &[u8], needle: &[u8]) -> Option<Option<usize>> {
|
||||||
|
let f = Finder::new(needle)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(find);
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_substring() {
|
||||||
|
crate::tests::substring::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair_prefilter() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
if !cfg!(target_feature = "sse2") {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find_prefilter(haystack))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
}
|
||||||
339
third_party/crates/memchr-2.8.3/src/arch/x86_64/memchr.rs
vendored
Normal file
339
third_party/crates/memchr-2.8.3/src/arch/x86_64/memchr.rs
vendored
Normal file
@@ -0,0 +1,339 @@
|
|||||||
|
/*!
|
||||||
|
Wrapper routines for `memchr` and friends.
|
||||||
|
|
||||||
|
These routines efficiently dispatch to the best implementation based on what
|
||||||
|
the CPU supports.
|
||||||
|
*/
|
||||||
|
|
||||||
|
/// Provides a way to run a memchr-like function while amortizing the cost of
|
||||||
|
/// runtime CPU feature detection.
|
||||||
|
///
|
||||||
|
/// This works by loading a function pointer from an atomic global. Initially,
|
||||||
|
/// this global is set to a function that does CPU feature detection. For
|
||||||
|
/// example, if AVX2 is enabled, then the AVX2 implementation is used.
|
||||||
|
/// Otherwise, at least on x86_64, the SSE2 implementation is used. (And
|
||||||
|
/// in some niche cases, if SSE2 isn't available, then the architecture
|
||||||
|
/// independent fallback implementation is used.)
|
||||||
|
///
|
||||||
|
/// After the first call to this function, the atomic global is replaced with
|
||||||
|
/// the specific AVX2, SSE2 or fallback routine chosen. Subsequent calls then
|
||||||
|
/// will directly call the chosen routine instead of needing to go through the
|
||||||
|
/// CPU feature detection branching again.
|
||||||
|
///
|
||||||
|
/// This particular macro is specifically written to provide the implementation
|
||||||
|
/// of functions with the following signature:
|
||||||
|
///
|
||||||
|
/// ```ignore
|
||||||
|
/// fn memchr(needle1: u8, start: *const u8, end: *const u8) -> Option<usize>;
|
||||||
|
/// ```
|
||||||
|
///
|
||||||
|
/// Where you can also have `memchr2` and `memchr3`, but with `needle2` and
|
||||||
|
/// `needle3`, respectively. The `start` and `end` parameters correspond to the
|
||||||
|
/// start and end of the haystack, respectively.
|
||||||
|
///
|
||||||
|
/// We use raw pointers here instead of the more obvious `haystack: &[u8]` so
|
||||||
|
/// that the function is compatible with our lower level iterator logic that
|
||||||
|
/// operates on raw pointers. We use this macro to implement "raw" memchr
|
||||||
|
/// routines with the signature above, and then define memchr routines using
|
||||||
|
/// regular slices on top of them.
|
||||||
|
///
|
||||||
|
/// Note that we use `#[cfg(target_feature = "sse2")]` below even though
|
||||||
|
/// it shouldn't be strictly necessary because without it, it seems to
|
||||||
|
/// cause the compiler to blow up. I guess it can't handle a function
|
||||||
|
/// pointer being created with a sse target feature? Dunno. See the
|
||||||
|
/// `build-for-x86-64-but-non-sse-target` CI job if you want to experiment with
|
||||||
|
/// this.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Primarily callers must ensure that `$fnty` is a correct function pointer
|
||||||
|
/// type and not something else.
|
||||||
|
///
|
||||||
|
/// Callers must also ensure that `$memchrty::$memchrfind` corresponds to a
|
||||||
|
/// routine that returns a valid function pointer when a match is found. That
|
||||||
|
/// is, a pointer that is `>= start` and `< end`.
|
||||||
|
///
|
||||||
|
/// Callers must also ensure that the `$hay_start` and `$hay_end` identifiers
|
||||||
|
/// correspond to valid pointers.
|
||||||
|
macro_rules! unsafe_ifunc {
|
||||||
|
(
|
||||||
|
$memchrty:ident,
|
||||||
|
$memchrfind:ident,
|
||||||
|
$fnty:ty,
|
||||||
|
$retty:ty,
|
||||||
|
$hay_start:ident,
|
||||||
|
$hay_end:ident,
|
||||||
|
$($needle:ident),+
|
||||||
|
) => {{
|
||||||
|
#![allow(unused_unsafe)]
|
||||||
|
|
||||||
|
use core::sync::atomic::{AtomicPtr, Ordering};
|
||||||
|
|
||||||
|
type Fn = *mut ();
|
||||||
|
type RealFn = $fnty;
|
||||||
|
static FN: AtomicPtr<()> = AtomicPtr::new(detect as Fn);
|
||||||
|
|
||||||
|
#[cfg(target_feature = "sse2")]
|
||||||
|
#[target_feature(enable = "sse2", enable = "avx2")]
|
||||||
|
unsafe fn find_avx2(
|
||||||
|
$($needle: u8),+,
|
||||||
|
$hay_start: *const u8,
|
||||||
|
$hay_end: *const u8,
|
||||||
|
) -> $retty {
|
||||||
|
use crate::arch::x86_64::avx2::memchr::$memchrty;
|
||||||
|
$memchrty::new_unchecked($($needle),+)
|
||||||
|
.$memchrfind($hay_start, $hay_end)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(target_feature = "sse2")]
|
||||||
|
#[target_feature(enable = "sse2")]
|
||||||
|
unsafe fn find_sse2(
|
||||||
|
$($needle: u8),+,
|
||||||
|
$hay_start: *const u8,
|
||||||
|
$hay_end: *const u8,
|
||||||
|
) -> $retty {
|
||||||
|
use crate::arch::x86_64::sse2::memchr::$memchrty;
|
||||||
|
$memchrty::new_unchecked($($needle),+)
|
||||||
|
.$memchrfind($hay_start, $hay_end)
|
||||||
|
}
|
||||||
|
|
||||||
|
unsafe fn find_fallback(
|
||||||
|
$($needle: u8),+,
|
||||||
|
$hay_start: *const u8,
|
||||||
|
$hay_end: *const u8,
|
||||||
|
) -> $retty {
|
||||||
|
use crate::arch::all::memchr::$memchrty;
|
||||||
|
$memchrty::new($($needle),+).$memchrfind($hay_start, $hay_end)
|
||||||
|
}
|
||||||
|
|
||||||
|
unsafe fn detect(
|
||||||
|
$($needle: u8),+,
|
||||||
|
$hay_start: *const u8,
|
||||||
|
$hay_end: *const u8,
|
||||||
|
) -> $retty {
|
||||||
|
let fun = {
|
||||||
|
#[cfg(not(target_feature = "sse2"))]
|
||||||
|
{
|
||||||
|
debug!(
|
||||||
|
"no sse2 feature available, using fallback for {}",
|
||||||
|
stringify!($memchrty),
|
||||||
|
);
|
||||||
|
find_fallback as RealFn
|
||||||
|
}
|
||||||
|
#[cfg(target_feature = "sse2")]
|
||||||
|
{
|
||||||
|
use crate::arch::x86_64::{sse2, avx2};
|
||||||
|
if avx2::memchr::$memchrty::is_available() {
|
||||||
|
debug!("chose AVX2 for {}", stringify!($memchrty));
|
||||||
|
find_avx2 as RealFn
|
||||||
|
} else if sse2::memchr::$memchrty::is_available() {
|
||||||
|
debug!("chose SSE2 for {}", stringify!($memchrty));
|
||||||
|
find_sse2 as RealFn
|
||||||
|
} else {
|
||||||
|
debug!("chose fallback for {}", stringify!($memchrty));
|
||||||
|
find_fallback as RealFn
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
FN.store(fun as Fn, Ordering::Relaxed);
|
||||||
|
// SAFETY: The only thing we need to uphold here is the
|
||||||
|
// `#[target_feature]` requirements. Since we check is_available
|
||||||
|
// above before using the corresponding implementation, we are
|
||||||
|
// guaranteed to only call code that is supported on the current
|
||||||
|
// CPU.
|
||||||
|
fun($($needle),+, $hay_start, $hay_end)
|
||||||
|
}
|
||||||
|
|
||||||
|
// SAFETY: By virtue of the caller contract, RealFn is a function
|
||||||
|
// pointer, which is always safe to transmute with a *mut (). Also,
|
||||||
|
// since we use $memchrty::is_available, it is guaranteed to be safe
|
||||||
|
// to call $memchrty::$memchrfind.
|
||||||
|
unsafe {
|
||||||
|
let fun = FN.load(Ordering::Relaxed);
|
||||||
|
core::mem::transmute::<Fn, RealFn>(fun)(
|
||||||
|
$($needle),+,
|
||||||
|
$hay_start,
|
||||||
|
$hay_end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
}};
|
||||||
|
}
|
||||||
|
|
||||||
|
// The routines below dispatch to AVX2, SSE2 or a fallback routine based on
|
||||||
|
// what's available in the current environment. The secret sauce here is that
|
||||||
|
// we only check for which one to use approximately once, and then "cache" that
|
||||||
|
// choice into a global function pointer. Subsequent invocations then just call
|
||||||
|
// the appropriate function directly.
|
||||||
|
|
||||||
|
/// memchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
One,
|
||||||
|
find_raw,
|
||||||
|
unsafe fn(u8, *const u8, *const u8) -> Option<*const u8>,
|
||||||
|
Option<*const u8>,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
One,
|
||||||
|
rfind_raw,
|
||||||
|
unsafe fn(u8, *const u8, *const u8) -> Option<*const u8>,
|
||||||
|
Option<*const u8>,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr2_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
Two,
|
||||||
|
find_raw,
|
||||||
|
unsafe fn(u8, u8, *const u8, *const u8) -> Option<*const u8>,
|
||||||
|
Option<*const u8>,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1,
|
||||||
|
n2
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr2_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
Two,
|
||||||
|
rfind_raw,
|
||||||
|
unsafe fn(u8, u8, *const u8, *const u8) -> Option<*const u8>,
|
||||||
|
Option<*const u8>,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1,
|
||||||
|
n2
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::find_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memchr3_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
Three,
|
||||||
|
find_raw,
|
||||||
|
unsafe fn(u8, u8, u8, *const u8, *const u8) -> Option<*const u8>,
|
||||||
|
Option<*const u8>,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1,
|
||||||
|
n2,
|
||||||
|
n3
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::rfind_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn memrchr3_raw(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
Three,
|
||||||
|
rfind_raw,
|
||||||
|
unsafe fn(u8, u8, u8, *const u8, *const u8) -> Option<*const u8>,
|
||||||
|
Option<*const u8>,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1,
|
||||||
|
n2,
|
||||||
|
n3
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Count all matching bytes, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::count_raw`.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) unsafe fn count_raw(
|
||||||
|
n1: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> usize {
|
||||||
|
// SAFETY: We provide a valid function pointer type.
|
||||||
|
unsafe_ifunc!(
|
||||||
|
One,
|
||||||
|
count_raw,
|
||||||
|
unsafe fn(u8, *const u8, *const u8) -> usize,
|
||||||
|
usize,
|
||||||
|
start,
|
||||||
|
end,
|
||||||
|
n1
|
||||||
|
)
|
||||||
|
}
|
||||||
8
third_party/crates/memchr-2.8.3/src/arch/x86_64/mod.rs
vendored
Normal file
8
third_party/crates/memchr-2.8.3/src/arch/x86_64/mod.rs
vendored
Normal file
@@ -0,0 +1,8 @@
|
|||||||
|
/*!
|
||||||
|
Vector algorithms for the `x86_64` target.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod avx2;
|
||||||
|
pub mod sse2;
|
||||||
|
|
||||||
|
pub(crate) mod memchr;
|
||||||
1077
third_party/crates/memchr-2.8.3/src/arch/x86_64/sse2/memchr.rs
vendored
Normal file
1077
third_party/crates/memchr-2.8.3/src/arch/x86_64/sse2/memchr.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
6
third_party/crates/memchr-2.8.3/src/arch/x86_64/sse2/mod.rs
vendored
Normal file
6
third_party/crates/memchr-2.8.3/src/arch/x86_64/sse2/mod.rs
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
/*!
|
||||||
|
Algorithms for the `x86_64` target using 128-bit vectors via SSE2.
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub mod memchr;
|
||||||
|
pub mod packedpair;
|
||||||
253
third_party/crates/memchr-2.8.3/src/arch/x86_64/sse2/packedpair.rs
vendored
Normal file
253
third_party/crates/memchr-2.8.3/src/arch/x86_64/sse2/packedpair.rs
vendored
Normal file
@@ -0,0 +1,253 @@
|
|||||||
|
/*!
|
||||||
|
A 128-bit vector implementation of the "packed pair" SIMD algorithm.
|
||||||
|
|
||||||
|
The "packed pair" algorithm is based on the [generic SIMD] algorithm. The main
|
||||||
|
difference is that it (by default) uses a background distribution of byte
|
||||||
|
frequencies to heuristically select the pair of bytes to search for.
|
||||||
|
|
||||||
|
[generic SIMD]: http://0x80.pl/articles/simd-strfind.html#first-and-last
|
||||||
|
*/
|
||||||
|
|
||||||
|
use core::arch::x86_64::__m128i;
|
||||||
|
|
||||||
|
use crate::arch::{all::packedpair::Pair, generic::packedpair};
|
||||||
|
|
||||||
|
/// A "packed pair" finder that uses 128-bit vector operations.
|
||||||
|
///
|
||||||
|
/// This finder picks two bytes that it believes have high predictive power
|
||||||
|
/// for indicating an overall match of a needle. Depending on whether
|
||||||
|
/// `Finder::find` or `Finder::find_prefilter` is used, it reports offsets
|
||||||
|
/// where the needle matches or could match. In the prefilter case, candidates
|
||||||
|
/// are reported whenever the [`Pair`] of bytes given matches.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub struct Finder(packedpair::Finder<__m128i>);
|
||||||
|
|
||||||
|
impl Finder {
|
||||||
|
/// Create a new pair searcher. The searcher returned can either report
|
||||||
|
/// exact matches of `needle` or act as a prefilter and report candidate
|
||||||
|
/// positions of `needle`.
|
||||||
|
///
|
||||||
|
/// If SSE2 is unavailable in the current environment or if a [`Pair`]
|
||||||
|
/// could not be constructed from the needle given, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle: &[u8]) -> Option<Finder> {
|
||||||
|
Finder::with_pair(needle, Pair::new(needle)?)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new "packed pair" finder using the pair of bytes given.
|
||||||
|
///
|
||||||
|
/// This constructor permits callers to control precisely which pair of
|
||||||
|
/// bytes is used as a predicate.
|
||||||
|
///
|
||||||
|
/// If SSE2 is unavailable in the current environment, then `None` is
|
||||||
|
/// returned.
|
||||||
|
#[inline]
|
||||||
|
pub fn with_pair(needle: &[u8], pair: Pair) -> Option<Finder> {
|
||||||
|
if Finder::is_available() {
|
||||||
|
// SAFETY: we check that sse2 is available above. We are also
|
||||||
|
// guaranteed to have needle.len() > 1 because we have a valid
|
||||||
|
// Pair.
|
||||||
|
unsafe { Some(Finder::with_pair_impl(needle, pair)) }
|
||||||
|
} else {
|
||||||
|
None
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new `Finder` specific to SSE2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same as the safety for `packedpair::Finder::new`, and callers must also
|
||||||
|
/// ensure that SSE2 is available.
|
||||||
|
#[target_feature(enable = "sse2")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn with_pair_impl(needle: &[u8], pair: Pair) -> Finder {
|
||||||
|
let finder = packedpair::Finder::<__m128i>::new(needle, pair);
|
||||||
|
Finder(finder)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns true when this implementation is available in the current
|
||||||
|
/// environment.
|
||||||
|
///
|
||||||
|
/// When this is true, it is guaranteed that [`Finder::with_pair`] will
|
||||||
|
/// return a `Some` value. Similarly, when it is false, it is guaranteed
|
||||||
|
/// that `Finder::with_pair` will return a `None` value. Notice that this
|
||||||
|
/// does not guarantee that [`Finder::new`] will return a `Finder`. Namely,
|
||||||
|
/// even when `Finder::is_available` is true, it is not guaranteed that a
|
||||||
|
/// valid [`Pair`] can be found from the needle given.
|
||||||
|
///
|
||||||
|
/// Note also that for the lifetime of a single program, if this returns
|
||||||
|
/// true then it will always return true.
|
||||||
|
#[inline]
|
||||||
|
pub fn is_available() -> bool {
|
||||||
|
#[cfg(not(target_feature = "sse2"))]
|
||||||
|
{
|
||||||
|
false
|
||||||
|
}
|
||||||
|
#[cfg(target_feature = "sse2")]
|
||||||
|
{
|
||||||
|
true
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using SSE2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: Building a `Finder` means it's safe to call 'sse2' routines.
|
||||||
|
unsafe { self.find_impl(haystack, needle) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run this finder on the given haystack as a prefilter.
|
||||||
|
///
|
||||||
|
/// If a candidate match is found, then an offset where the needle *could*
|
||||||
|
/// begin in the haystack is returned.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
#[inline]
|
||||||
|
pub fn find_prefilter(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: Building a `Finder` means it's safe to call 'sse2' routines.
|
||||||
|
unsafe { self.find_prefilter_impl(haystack) }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a search using SSE2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `sse2` routines.)
|
||||||
|
#[target_feature(enable = "sse2")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn find_impl(
|
||||||
|
&self,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
self.0.find(haystack, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Execute a prefilter search using SSE2 vectors and routines.
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// When `haystack.len()` is less than [`Finder::min_haystack_len`].
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// (The target feature safety obligation is automatically fulfilled by
|
||||||
|
/// virtue of being a method on `Finder`, which can only be constructed
|
||||||
|
/// when it is safe to call `sse2` routines.)
|
||||||
|
#[target_feature(enable = "sse2")]
|
||||||
|
#[inline]
|
||||||
|
unsafe fn find_prefilter_impl(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
self.0.find_prefilter(haystack)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the pair of offsets (into the needle) used to check as a
|
||||||
|
/// predicate before confirming whether a needle exists at a particular
|
||||||
|
/// position.
|
||||||
|
#[inline]
|
||||||
|
pub fn pair(&self) -> &Pair {
|
||||||
|
self.0.pair()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the minimum haystack length that this `Finder` can search.
|
||||||
|
///
|
||||||
|
/// Using a haystack with length smaller than this in a search will result
|
||||||
|
/// in a panic. The reason for this restriction is that this finder is
|
||||||
|
/// meant to be a low-level component that is part of a larger substring
|
||||||
|
/// strategy. In that sense, it avoids trying to handle all cases and
|
||||||
|
/// instead only handles the cases that it can handle very well.
|
||||||
|
#[inline]
|
||||||
|
pub fn min_haystack_len(&self) -> usize {
|
||||||
|
self.0.min_haystack_len()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
fn find(haystack: &[u8], needle: &[u8]) -> Option<Option<usize>> {
|
||||||
|
let f = Finder::new(needle)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(find);
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_substring() {
|
||||||
|
crate::tests::substring::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find(haystack, needle))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward_packedpair_prefilter() {
|
||||||
|
fn find(
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
) -> Option<Option<usize>> {
|
||||||
|
let pair = Pair::with_indices(needle, index1, index2)?;
|
||||||
|
let f = Finder::with_pair(needle, pair)?;
|
||||||
|
if haystack.len() < f.min_haystack_len() {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
Some(f.find_prefilter(haystack))
|
||||||
|
}
|
||||||
|
crate::tests::packedpair::Runner::new().fwd(find).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
// A demonstration of UB (caught under Miri) through some of memchr's
|
||||||
|
// lower level but public APIs.
|
||||||
|
//
|
||||||
|
// See: https://github.com/BurntSushi/memchr/issues/225
|
||||||
|
#[test]
|
||||||
|
fn regression_undefined_behavior() {
|
||||||
|
let construct_needle: &[u8] = b"ab"; // length 2 → pair indices 0,1
|
||||||
|
let pair = Pair::new(construct_needle).unwrap();
|
||||||
|
let Some(finder) = Finder::with_pair(construct_needle, pair) else {
|
||||||
|
return;
|
||||||
|
};
|
||||||
|
let mhl = finder.min_haystack_len(); // 17
|
||||||
|
let mut haystack = alloc::vec![b'.'; mhl + 5];
|
||||||
|
haystack[0] = b'a';
|
||||||
|
// force entry into find_in_chunk inner branch
|
||||||
|
haystack[1] = b'b';
|
||||||
|
// 122 > haystack.len()=22
|
||||||
|
let long_needle = alloc::vec![b'X'; haystack.len() + 100];
|
||||||
|
let _ = finder.find(&haystack, &long_needle);
|
||||||
|
}
|
||||||
|
}
|
||||||
109
third_party/crates/memchr-2.8.3/src/cow.rs
vendored
Normal file
109
third_party/crates/memchr-2.8.3/src/cow.rs
vendored
Normal file
@@ -0,0 +1,109 @@
|
|||||||
|
use core::ops;
|
||||||
|
|
||||||
|
/// A specialized copy-on-write byte string.
|
||||||
|
///
|
||||||
|
/// The purpose of this type is to permit usage of a "borrowed or owned
|
||||||
|
/// byte string" in a way that keeps std/no-std compatibility. That is, in
|
||||||
|
/// no-std/alloc mode, this type devolves into a simple &[u8] with no owned
|
||||||
|
/// variant available. We can't just use a plain Cow because Cow is not in
|
||||||
|
/// core.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct CowBytes<'a>(Imp<'a>);
|
||||||
|
|
||||||
|
// N.B. We don't use alloc::borrow::Cow here since we can get away with a
|
||||||
|
// Box<[u8]> for our use case, which is 1/3 smaller than the Vec<u8> that
|
||||||
|
// a Cow<[u8]> would use.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
enum Imp<'a> {
|
||||||
|
Borrowed(&'a [u8]),
|
||||||
|
Owned(alloc::boxed::Box<[u8]>),
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(not(feature = "alloc"))]
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
struct Imp<'a>(&'a [u8]);
|
||||||
|
|
||||||
|
impl<'a> ops::Deref for CowBytes<'a> {
|
||||||
|
type Target = [u8];
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn deref(&self) -> &[u8] {
|
||||||
|
self.as_slice()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'a> CowBytes<'a> {
|
||||||
|
/// Create a new borrowed CowBytes.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn new<B: ?Sized + AsRef<[u8]>>(bytes: &'a B) -> CowBytes<'a> {
|
||||||
|
CowBytes(Imp::new(bytes.as_ref()))
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Create a new owned CowBytes.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn new_owned(
|
||||||
|
bytes: alloc::boxed::Box<[u8]>,
|
||||||
|
) -> CowBytes<'static> {
|
||||||
|
CowBytes(Imp::Owned(bytes))
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return a borrowed byte string, regardless of whether this is an owned
|
||||||
|
/// or borrowed byte string internally.
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn as_slice(&self) -> &[u8] {
|
||||||
|
self.0.as_slice()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Return an owned version of this copy-on-write byte string.
|
||||||
|
///
|
||||||
|
/// If this is already an owned byte string internally, then this is a
|
||||||
|
/// no-op. Otherwise, the internal byte string is copied.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn into_owned(self) -> CowBytes<'static> {
|
||||||
|
match self.0 {
|
||||||
|
Imp::Borrowed(b) => {
|
||||||
|
CowBytes::new_owned(alloc::boxed::Box::from(b))
|
||||||
|
}
|
||||||
|
Imp::Owned(b) => CowBytes::new_owned(b),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'a> Imp<'a> {
|
||||||
|
#[inline(always)]
|
||||||
|
pub fn new(bytes: &'a [u8]) -> Imp<'a> {
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
{
|
||||||
|
Imp::Borrowed(bytes)
|
||||||
|
}
|
||||||
|
#[cfg(not(feature = "alloc"))]
|
||||||
|
{
|
||||||
|
Imp(bytes)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline(always)]
|
||||||
|
pub fn as_slice(&self) -> &[u8] {
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
{
|
||||||
|
match self {
|
||||||
|
Imp::Owned(ref x) => x,
|
||||||
|
Imp::Borrowed(x) => x,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
#[cfg(not(feature = "alloc"))]
|
||||||
|
{
|
||||||
|
self.0
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(not(feature = "alloc"))]
|
||||||
|
#[inline(always)]
|
||||||
|
pub fn as_slice(&self) -> &[u8] {
|
||||||
|
self.0
|
||||||
|
}
|
||||||
|
}
|
||||||
54
third_party/crates/memchr-2.8.3/src/ext.rs
vendored
Normal file
54
third_party/crates/memchr-2.8.3/src/ext.rs
vendored
Normal file
@@ -0,0 +1,54 @@
|
|||||||
|
/// A trait for adding some helper routines to pointers.
|
||||||
|
pub(crate) trait Pointer {
|
||||||
|
/// Returns the distance, in units of `T`, between `self` and `origin`.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Same as `ptr::offset_from` in addition to `self >= origin`.
|
||||||
|
unsafe fn distance(self, origin: Self) -> usize;
|
||||||
|
|
||||||
|
/// Casts this pointer to `usize`.
|
||||||
|
///
|
||||||
|
/// Callers should not convert the `usize` back to a pointer if at all
|
||||||
|
/// possible. (And if you believe it's necessary, open an issue to discuss
|
||||||
|
/// why. Otherwise, it has the potential to violate pointer provenance.)
|
||||||
|
/// The purpose of this function is just to be able to do arithmetic, i.e.,
|
||||||
|
/// computing offsets or alignments.
|
||||||
|
fn as_usize(self) -> usize;
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<T> Pointer for *const T {
|
||||||
|
unsafe fn distance(self, origin: *const T) -> usize {
|
||||||
|
// TODO: Replace with `ptr::sub_ptr` once stabilized.
|
||||||
|
usize::try_from(self.offset_from(origin)).unwrap_unchecked()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn as_usize(self) -> usize {
|
||||||
|
self as usize
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<T> Pointer for *mut T {
|
||||||
|
unsafe fn distance(self, origin: *mut T) -> usize {
|
||||||
|
(self as *const T).distance(origin as *const T)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn as_usize(self) -> usize {
|
||||||
|
(self as *const T).as_usize()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A trait for adding some helper routines to raw bytes.
|
||||||
|
#[cfg(test)]
|
||||||
|
pub(crate) trait Byte {
|
||||||
|
/// Converts this byte to a `char` if it's ASCII. Otherwise panics.
|
||||||
|
fn to_char(self) -> char;
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
impl Byte for u8 {
|
||||||
|
fn to_char(self) -> char {
|
||||||
|
assert!(self.is_ascii());
|
||||||
|
char::from(self)
|
||||||
|
}
|
||||||
|
}
|
||||||
221
third_party/crates/memchr-2.8.3/src/lib.rs
vendored
Normal file
221
third_party/crates/memchr-2.8.3/src/lib.rs
vendored
Normal file
@@ -0,0 +1,221 @@
|
|||||||
|
/*!
|
||||||
|
This library provides heavily optimized routines for string search primitives.
|
||||||
|
|
||||||
|
# Overview
|
||||||
|
|
||||||
|
This section gives a brief high level overview of what this crate offers.
|
||||||
|
|
||||||
|
* The top-level module provides routines for searching for 1, 2 or 3 bytes
|
||||||
|
in the forward or reverse direction. When searching for more than one byte,
|
||||||
|
positions are considered a match if the byte at that position matches any
|
||||||
|
of the bytes.
|
||||||
|
* The [`memmem`] sub-module provides forward and reverse substring search
|
||||||
|
routines.
|
||||||
|
|
||||||
|
In all such cases, routines operate on `&[u8]` without regard to encoding. This
|
||||||
|
is exactly what you want when searching either UTF-8 or arbitrary bytes.
|
||||||
|
|
||||||
|
# Example: using `memchr`
|
||||||
|
|
||||||
|
This example shows how to use `memchr` to find the first occurrence of `z` in
|
||||||
|
a haystack:
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memchr;
|
||||||
|
|
||||||
|
let haystack = b"foo bar baz quuz";
|
||||||
|
assert_eq!(Some(10), memchr(b'z', haystack));
|
||||||
|
```
|
||||||
|
|
||||||
|
# Example: matching one of three possible bytes
|
||||||
|
|
||||||
|
This examples shows how to use `memrchr3` to find occurrences of `a`, `b` or
|
||||||
|
`c`, starting at the end of the haystack.
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memchr3_iter;
|
||||||
|
|
||||||
|
let haystack = b"xyzaxyzbxyzc";
|
||||||
|
|
||||||
|
let mut it = memchr3_iter(b'a', b'b', b'c', haystack).rev();
|
||||||
|
assert_eq!(Some(11), it.next());
|
||||||
|
assert_eq!(Some(7), it.next());
|
||||||
|
assert_eq!(Some(3), it.next());
|
||||||
|
assert_eq!(None, it.next());
|
||||||
|
```
|
||||||
|
|
||||||
|
# Example: iterating over substring matches
|
||||||
|
|
||||||
|
This example shows how to use the [`memmem`] sub-module to find occurrences of
|
||||||
|
a substring in a haystack.
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memmem;
|
||||||
|
|
||||||
|
let haystack = b"foo bar foo baz foo";
|
||||||
|
|
||||||
|
let mut it = memmem::find_iter(haystack, "foo");
|
||||||
|
assert_eq!(Some(0), it.next());
|
||||||
|
assert_eq!(Some(8), it.next());
|
||||||
|
assert_eq!(Some(16), it.next());
|
||||||
|
assert_eq!(None, it.next());
|
||||||
|
```
|
||||||
|
|
||||||
|
# Example: repeating a search for the same needle
|
||||||
|
|
||||||
|
It may be possible for the overhead of constructing a substring searcher to be
|
||||||
|
measurable in some workloads. In cases where the same needle is used to search
|
||||||
|
many haystacks, it is possible to do construction once and thus to avoid it for
|
||||||
|
subsequent searches. This can be done with a [`memmem::Finder`]:
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memmem;
|
||||||
|
|
||||||
|
let finder = memmem::Finder::new("foo");
|
||||||
|
|
||||||
|
assert_eq!(Some(4), finder.find(b"baz foo quux"));
|
||||||
|
assert_eq!(None, finder.find(b"quux baz bar"));
|
||||||
|
```
|
||||||
|
|
||||||
|
# Why use this crate?
|
||||||
|
|
||||||
|
At first glance, the APIs provided by this crate might seem weird. Why provide
|
||||||
|
a dedicated routine like `memchr` for something that could be implemented
|
||||||
|
clearly and trivially in one line:
|
||||||
|
|
||||||
|
```
|
||||||
|
fn memchr(needle: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
haystack.iter().position(|&b| b == needle)
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
Or similarly, why does this crate provide substring search routines when Rust's
|
||||||
|
core library already provides them?
|
||||||
|
|
||||||
|
```
|
||||||
|
fn search(haystack: &str, needle: &str) -> Option<usize> {
|
||||||
|
haystack.find(needle)
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
The primary reason for both of them to exist is performance. When it comes to
|
||||||
|
performance, at a high level at least, there are two primary ways to look at
|
||||||
|
it:
|
||||||
|
|
||||||
|
* **Throughput**: For this, think about it as, "given some very large haystack
|
||||||
|
and a byte that never occurs in that haystack, how long does it take to
|
||||||
|
search through it and determine that it, in fact, does not occur?"
|
||||||
|
* **Latency**: For this, think about it as, "given a tiny haystack---just a
|
||||||
|
few bytes---how long does it take to determine if a byte is in it?"
|
||||||
|
|
||||||
|
The `memchr` routine in this crate has _slightly_ worse latency than the
|
||||||
|
solution presented above, however, its throughput can easily be over an
|
||||||
|
order of magnitude faster. This is a good general purpose trade off to make.
|
||||||
|
You rarely lose, but often gain big.
|
||||||
|
|
||||||
|
**NOTE:** The name `memchr` comes from the corresponding routine in `libc`. A
|
||||||
|
key advantage of using this library is that its performance is not tied to its
|
||||||
|
quality of implementation in the `libc` you happen to be using, which can vary
|
||||||
|
greatly from platform to platform.
|
||||||
|
|
||||||
|
But what about substring search? This one is a bit more complicated. The
|
||||||
|
primary reason for its existence is still indeed performance, but it's also
|
||||||
|
useful because Rust's core library doesn't actually expose any substring
|
||||||
|
search routine on arbitrary bytes. The only substring search routine that
|
||||||
|
exists works exclusively on valid UTF-8.
|
||||||
|
|
||||||
|
So if you have valid UTF-8, is there a reason to use this over the standard
|
||||||
|
library substring search routine? Yes. This routine is faster on almost every
|
||||||
|
metric, including latency. The natural question then, is why isn't this
|
||||||
|
implementation in the standard library, even if only for searching on UTF-8?
|
||||||
|
The reason is that the implementation details for using SIMD in the standard
|
||||||
|
library haven't quite been worked out yet.
|
||||||
|
|
||||||
|
**NOTE:** Currently, only `x86_64`, `wasm32` and `aarch64` targets have vector
|
||||||
|
accelerated implementations of `memchr` (and friends) and `memmem`.
|
||||||
|
|
||||||
|
# Crate features
|
||||||
|
|
||||||
|
* **std** - When enabled (the default), this will permit features specific to
|
||||||
|
the standard library. Currently, the only thing used from the standard library
|
||||||
|
is runtime SIMD CPU feature detection. This means that this feature must be
|
||||||
|
enabled to get AVX2 accelerated routines on `x86_64` targets without enabling
|
||||||
|
the `avx2` feature at compile time, for example. When `std` is not enabled,
|
||||||
|
this crate will still attempt to use SSE2 accelerated routines on `x86_64`. It
|
||||||
|
will also use AVX2 accelerated routines when the `avx2` feature is enabled at
|
||||||
|
compile time. In general, enable this feature if you can.
|
||||||
|
* **alloc** - When enabled (the default), APIs in this crate requiring some
|
||||||
|
kind of allocation will become available. For example, the
|
||||||
|
[`memmem::Finder::into_owned`](crate::memmem::Finder::into_owned) API and the
|
||||||
|
[`arch::all::shiftor`](crate::arch::all::shiftor) substring search
|
||||||
|
implementation. Otherwise, this crate is designed from the ground up to be
|
||||||
|
usable in core-only contexts, so the `alloc` feature doesn't add much
|
||||||
|
currently. Notably, disabling `std` but enabling `alloc` will **not** result
|
||||||
|
in the use of AVX2 on `x86_64` targets unless the `avx2` feature is enabled
|
||||||
|
at compile time. (With `std` enabled, AVX2 can be used even without the `avx2`
|
||||||
|
feature enabled at compile time by way of runtime CPU feature detection.)
|
||||||
|
* **logging** - When enabled (disabled by default), the `log` crate is used
|
||||||
|
to emit log messages about what kinds of `memchr` and `memmem` algorithms
|
||||||
|
are used. Namely, both `memchr` and `memmem` have a number of different
|
||||||
|
implementation choices depending on the target and CPU, and the log messages
|
||||||
|
can help show what specific implementations are being used. Generally, this is
|
||||||
|
useful for debugging performance issues.
|
||||||
|
* **libc** - **DEPRECATED**. Previously, this enabled the use of the target's
|
||||||
|
`memchr` function from whatever `libc` was linked into the program. This
|
||||||
|
feature is now a no-op because this crate's implementation of `memchr` should
|
||||||
|
now be sufficiently fast on a number of platforms that `libc` should no longer
|
||||||
|
be needed. (This feature is somewhat of a holdover from this crate's origins.
|
||||||
|
Originally, this crate was literally just a safe wrapper function around the
|
||||||
|
`memchr` function from `libc`.)
|
||||||
|
*/
|
||||||
|
|
||||||
|
#![deny(missing_docs)]
|
||||||
|
#![no_std]
|
||||||
|
// It's just not worth trying to squash all dead code warnings. Pretty
|
||||||
|
// unfortunate IMO. Not really sure how to fix this other than to either
|
||||||
|
// live with it or sprinkle a whole mess of `cfg` annotations everywhere.
|
||||||
|
#![cfg_attr(
|
||||||
|
not(any(
|
||||||
|
all(target_arch = "x86_64", target_feature = "sse2"),
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64",
|
||||||
|
)),
|
||||||
|
allow(dead_code)
|
||||||
|
)]
|
||||||
|
// Same deal for miri.
|
||||||
|
#![cfg_attr(miri, allow(dead_code, unused_macros))]
|
||||||
|
|
||||||
|
// Supporting 8-bit (or others) would be fine. If you need it, please submit a
|
||||||
|
// bug report at https://github.com/BurntSushi/memchr
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_pointer_width = "16",
|
||||||
|
target_pointer_width = "32",
|
||||||
|
target_pointer_width = "64"
|
||||||
|
)))]
|
||||||
|
compile_error!("memchr currently not supported on non-{16,32,64}");
|
||||||
|
|
||||||
|
#[cfg(any(test, feature = "std"))]
|
||||||
|
extern crate std;
|
||||||
|
|
||||||
|
#[cfg(any(test, feature = "alloc"))]
|
||||||
|
extern crate alloc;
|
||||||
|
|
||||||
|
pub use crate::memchr::{
|
||||||
|
memchr, memchr2, memchr2_iter, memchr3, memchr3_iter, memchr_iter,
|
||||||
|
memrchr, memrchr2, memrchr2_iter, memrchr3, memrchr3_iter, memrchr_iter,
|
||||||
|
Memchr, Memchr2, Memchr3,
|
||||||
|
};
|
||||||
|
|
||||||
|
#[macro_use]
|
||||||
|
mod macros;
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
#[macro_use]
|
||||||
|
mod tests;
|
||||||
|
|
||||||
|
pub mod arch;
|
||||||
|
mod cow;
|
||||||
|
mod ext;
|
||||||
|
mod memchr;
|
||||||
|
pub mod memmem;
|
||||||
|
mod vector;
|
||||||
20
third_party/crates/memchr-2.8.3/src/macros.rs
vendored
Normal file
20
third_party/crates/memchr-2.8.3/src/macros.rs
vendored
Normal file
@@ -0,0 +1,20 @@
|
|||||||
|
// Some feature combinations result in some of these macros never being used.
|
||||||
|
// Which is fine. Just squash the warnings.
|
||||||
|
#![allow(unused_macros)]
|
||||||
|
|
||||||
|
macro_rules! log {
|
||||||
|
($($tt:tt)*) => {
|
||||||
|
#[cfg(feature = "logging")]
|
||||||
|
{
|
||||||
|
$($tt)*
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! debug {
|
||||||
|
($($tt:tt)*) => { log!(log::debug!($($tt)*)) }
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! trace {
|
||||||
|
($($tt:tt)*) => { log!(log::trace!($($tt)*)) }
|
||||||
|
}
|
||||||
903
third_party/crates/memchr-2.8.3/src/memchr.rs
vendored
Normal file
903
third_party/crates/memchr-2.8.3/src/memchr.rs
vendored
Normal file
@@ -0,0 +1,903 @@
|
|||||||
|
use core::iter::Rev;
|
||||||
|
|
||||||
|
use crate::arch::generic::memchr as generic;
|
||||||
|
|
||||||
|
/// Search for the first occurrence of a byte in a slice.
|
||||||
|
///
|
||||||
|
/// This returns the index corresponding to the first occurrence of `needle` in
|
||||||
|
/// `haystack`, or `None` if one is not found. If an index is returned, it is
|
||||||
|
/// guaranteed to be less than `haystack.len()`.
|
||||||
|
///
|
||||||
|
/// While this is semantically the same as something like
|
||||||
|
/// `haystack.iter().position(|&b| b == needle)`, this routine will attempt to
|
||||||
|
/// use highly optimized vector operations that can be an order of magnitude
|
||||||
|
/// faster (or more).
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// This shows how to find the first position of a byte in a byte string.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memchr;
|
||||||
|
///
|
||||||
|
/// let haystack = b"the quick brown fox";
|
||||||
|
/// assert_eq!(memchr(b'k', haystack), Some(8));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn memchr(needle: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: memchr_raw, when a match is found, always returns a valid
|
||||||
|
// pointer between start and end.
|
||||||
|
unsafe {
|
||||||
|
generic::search_slice_with_raw(haystack, |start, end| {
|
||||||
|
memchr_raw(needle, start, end)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for the last occurrence of a byte in a slice.
|
||||||
|
///
|
||||||
|
/// This returns the index corresponding to the last occurrence of `needle` in
|
||||||
|
/// `haystack`, or `None` if one is not found. If an index is returned, it is
|
||||||
|
/// guaranteed to be less than `haystack.len()`.
|
||||||
|
///
|
||||||
|
/// While this is semantically the same as something like
|
||||||
|
/// `haystack.iter().rposition(|&b| b == needle)`, this routine will attempt to
|
||||||
|
/// use highly optimized vector operations that can be an order of magnitude
|
||||||
|
/// faster (or more).
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// This shows how to find the last position of a byte in a byte string.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memrchr;
|
||||||
|
///
|
||||||
|
/// let haystack = b"the quick brown fox";
|
||||||
|
/// assert_eq!(memrchr(b'o', haystack), Some(17));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn memrchr(needle: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: memrchr_raw, when a match is found, always returns a valid
|
||||||
|
// pointer between start and end.
|
||||||
|
unsafe {
|
||||||
|
generic::search_slice_with_raw(haystack, |start, end| {
|
||||||
|
memrchr_raw(needle, start, end)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for the first occurrence of two possible bytes in a haystack.
|
||||||
|
///
|
||||||
|
/// This returns the index corresponding to the first occurrence of one of the
|
||||||
|
/// needle bytes in `haystack`, or `None` if one is not found. If an index is
|
||||||
|
/// returned, it is guaranteed to be less than `haystack.len()`.
|
||||||
|
///
|
||||||
|
/// While this is semantically the same as something like
|
||||||
|
/// `haystack.iter().position(|&b| b == needle1 || b == needle2)`, this routine
|
||||||
|
/// will attempt to use highly optimized vector operations that can be an order
|
||||||
|
/// of magnitude faster (or more).
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// This shows how to find the first position of one of two possible bytes in a
|
||||||
|
/// haystack.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memchr2;
|
||||||
|
///
|
||||||
|
/// let haystack = b"the quick brown fox";
|
||||||
|
/// assert_eq!(memchr2(b'k', b'q', haystack), Some(4));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn memchr2(needle1: u8, needle2: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: memchr2_raw, when a match is found, always returns a valid
|
||||||
|
// pointer between start and end.
|
||||||
|
unsafe {
|
||||||
|
generic::search_slice_with_raw(haystack, |start, end| {
|
||||||
|
memchr2_raw(needle1, needle2, start, end)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for the last occurrence of two possible bytes in a haystack.
|
||||||
|
///
|
||||||
|
/// This returns the index corresponding to the last occurrence of one of the
|
||||||
|
/// needle bytes in `haystack`, or `None` if one is not found. If an index is
|
||||||
|
/// returned, it is guaranteed to be less than `haystack.len()`.
|
||||||
|
///
|
||||||
|
/// While this is semantically the same as something like
|
||||||
|
/// `haystack.iter().rposition(|&b| b == needle1 || b == needle2)`, this
|
||||||
|
/// routine will attempt to use highly optimized vector operations that can be
|
||||||
|
/// an order of magnitude faster (or more).
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// This shows how to find the last position of one of two possible bytes in a
|
||||||
|
/// haystack.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memrchr2;
|
||||||
|
///
|
||||||
|
/// let haystack = b"the quick brown fox";
|
||||||
|
/// assert_eq!(memrchr2(b'k', b'o', haystack), Some(17));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn memrchr2(needle1: u8, needle2: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
// SAFETY: memrchr2_raw, when a match is found, always returns a valid
|
||||||
|
// pointer between start and end.
|
||||||
|
unsafe {
|
||||||
|
generic::search_slice_with_raw(haystack, |start, end| {
|
||||||
|
memrchr2_raw(needle1, needle2, start, end)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for the first occurrence of three possible bytes in a haystack.
|
||||||
|
///
|
||||||
|
/// This returns the index corresponding to the first occurrence of one of the
|
||||||
|
/// needle bytes in `haystack`, or `None` if one is not found. If an index is
|
||||||
|
/// returned, it is guaranteed to be less than `haystack.len()`.
|
||||||
|
///
|
||||||
|
/// While this is semantically the same as something like
|
||||||
|
/// `haystack.iter().position(|&b| b == needle1 || b == needle2 || b == needle3)`,
|
||||||
|
/// this routine will attempt to use highly optimized vector operations that
|
||||||
|
/// can be an order of magnitude faster (or more).
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// This shows how to find the first position of one of three possible bytes in
|
||||||
|
/// a haystack.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memchr3;
|
||||||
|
///
|
||||||
|
/// let haystack = b"the quick brown fox";
|
||||||
|
/// assert_eq!(memchr3(b'k', b'q', b'u', haystack), Some(4));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn memchr3(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
// SAFETY: memchr3_raw, when a match is found, always returns a valid
|
||||||
|
// pointer between start and end.
|
||||||
|
unsafe {
|
||||||
|
generic::search_slice_with_raw(haystack, |start, end| {
|
||||||
|
memchr3_raw(needle1, needle2, needle3, start, end)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Search for the last occurrence of three possible bytes in a haystack.
|
||||||
|
///
|
||||||
|
/// This returns the index corresponding to the last occurrence of one of the
|
||||||
|
/// needle bytes in `haystack`, or `None` if one is not found. If an index is
|
||||||
|
/// returned, it is guaranteed to be less than `haystack.len()`.
|
||||||
|
///
|
||||||
|
/// While this is semantically the same as something like
|
||||||
|
/// `haystack.iter().rposition(|&b| b == needle1 || b == needle2 || b == needle3)`,
|
||||||
|
/// this routine will attempt to use highly optimized vector operations that
|
||||||
|
/// can be an order of magnitude faster (or more).
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// This shows how to find the last position of one of three possible bytes in
|
||||||
|
/// a haystack.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memrchr3;
|
||||||
|
///
|
||||||
|
/// let haystack = b"the quick brown fox";
|
||||||
|
/// assert_eq!(memrchr3(b'k', b'o', b'n', haystack), Some(17));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn memrchr3(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
// SAFETY: memrchr3_raw, when a match is found, always returns a valid
|
||||||
|
// pointer between start and end.
|
||||||
|
unsafe {
|
||||||
|
generic::search_slice_with_raw(haystack, |start, end| {
|
||||||
|
memrchr3_raw(needle1, needle2, needle3, start, end)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of the needle in a haystack.
|
||||||
|
///
|
||||||
|
/// The iterator returned implements `DoubleEndedIterator`. This means it
|
||||||
|
/// can also be used to find occurrences in reverse order.
|
||||||
|
#[inline]
|
||||||
|
pub fn memchr_iter<'h>(needle: u8, haystack: &'h [u8]) -> Memchr<'h> {
|
||||||
|
Memchr::new(needle, haystack)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of the needle in a haystack, in
|
||||||
|
/// reverse.
|
||||||
|
#[inline]
|
||||||
|
pub fn memrchr_iter(needle: u8, haystack: &[u8]) -> Rev<Memchr<'_>> {
|
||||||
|
Memchr::new(needle, haystack).rev()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of the needles in a haystack.
|
||||||
|
///
|
||||||
|
/// The iterator returned implements `DoubleEndedIterator`. This means it
|
||||||
|
/// can also be used to find occurrences in reverse order.
|
||||||
|
#[inline]
|
||||||
|
pub fn memchr2_iter<'h>(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
haystack: &'h [u8],
|
||||||
|
) -> Memchr2<'h> {
|
||||||
|
Memchr2::new(needle1, needle2, haystack)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of the needles in a haystack, in
|
||||||
|
/// reverse.
|
||||||
|
#[inline]
|
||||||
|
pub fn memrchr2_iter(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Rev<Memchr2<'_>> {
|
||||||
|
Memchr2::new(needle1, needle2, haystack).rev()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of the needles in a haystack.
|
||||||
|
///
|
||||||
|
/// The iterator returned implements `DoubleEndedIterator`. This means it
|
||||||
|
/// can also be used to find occurrences in reverse order.
|
||||||
|
#[inline]
|
||||||
|
pub fn memchr3_iter<'h>(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
haystack: &'h [u8],
|
||||||
|
) -> Memchr3<'h> {
|
||||||
|
Memchr3::new(needle1, needle2, needle3, haystack)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of the needles in a haystack, in
|
||||||
|
/// reverse.
|
||||||
|
#[inline]
|
||||||
|
pub fn memrchr3_iter(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Rev<Memchr3<'_>> {
|
||||||
|
Memchr3::new(needle1, needle2, needle3, haystack).rev()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// An iterator over all occurrences of a single byte in a haystack.
|
||||||
|
///
|
||||||
|
/// This iterator implements `DoubleEndedIterator`, which means it can also be
|
||||||
|
/// used to find occurrences in reverse order.
|
||||||
|
///
|
||||||
|
/// This iterator is created by the [`memchr_iter`] or `[memrchr_iter`]
|
||||||
|
/// functions. It can also be created with the [`Memchr::new`] method.
|
||||||
|
///
|
||||||
|
/// The lifetime parameter `'h` refers to the lifetime of the haystack being
|
||||||
|
/// searched.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct Memchr<'h> {
|
||||||
|
needle1: u8,
|
||||||
|
it: crate::arch::generic::memchr::Iter<'h>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> Memchr<'h> {
|
||||||
|
/// Returns an iterator over all occurrences of the needle byte in the
|
||||||
|
/// given haystack.
|
||||||
|
///
|
||||||
|
/// The iterator returned implements `DoubleEndedIterator`. This means it
|
||||||
|
/// can also be used to find occurrences in reverse order.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle1: u8, haystack: &'h [u8]) -> Memchr<'h> {
|
||||||
|
Memchr {
|
||||||
|
needle1,
|
||||||
|
it: crate::arch::generic::memchr::Iter::new(haystack),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> Iterator for Memchr<'h> {
|
||||||
|
type Item = usize;
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn next(&mut self) -> Option<usize> {
|
||||||
|
// SAFETY: All of our implementations of memchr ensure that any
|
||||||
|
// pointers returns will fall within the start and end bounds, and this
|
||||||
|
// upholds the safety contract of `self.it.next`.
|
||||||
|
unsafe {
|
||||||
|
// NOTE: I attempted to define an enum of previously created
|
||||||
|
// searchers and then switch on those here instead of just
|
||||||
|
// calling `memchr_raw` (or `One::new(..).find_raw(..)`). But
|
||||||
|
// that turned out to have a fair bit of extra overhead when
|
||||||
|
// searching very small haystacks.
|
||||||
|
self.it.next(|s, e| memchr_raw(self.needle1, s, e))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn count(self) -> usize {
|
||||||
|
self.it.count(|s, e| {
|
||||||
|
// SAFETY: We rely on our generic iterator to return valid start
|
||||||
|
// and end pointers.
|
||||||
|
unsafe { count_raw(self.needle1, s, e) }
|
||||||
|
})
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn size_hint(&self) -> (usize, Option<usize>) {
|
||||||
|
self.it.size_hint()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> DoubleEndedIterator for Memchr<'h> {
|
||||||
|
#[inline]
|
||||||
|
fn next_back(&mut self) -> Option<usize> {
|
||||||
|
// SAFETY: All of our implementations of memchr ensure that any
|
||||||
|
// pointers returns will fall within the start and end bounds, and this
|
||||||
|
// upholds the safety contract of `self.it.next_back`.
|
||||||
|
unsafe { self.it.next_back(|s, e| memrchr_raw(self.needle1, s, e)) }
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> core::iter::FusedIterator for Memchr<'h> {}
|
||||||
|
|
||||||
|
/// An iterator over all occurrences of two possible bytes in a haystack.
|
||||||
|
///
|
||||||
|
/// This iterator implements `DoubleEndedIterator`, which means it can also be
|
||||||
|
/// used to find occurrences in reverse order.
|
||||||
|
///
|
||||||
|
/// This iterator is created by the [`memchr2_iter`] or `[memrchr2_iter`]
|
||||||
|
/// functions. It can also be created with the [`Memchr2::new`] method.
|
||||||
|
///
|
||||||
|
/// The lifetime parameter `'h` refers to the lifetime of the haystack being
|
||||||
|
/// searched.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct Memchr2<'h> {
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
it: crate::arch::generic::memchr::Iter<'h>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> Memchr2<'h> {
|
||||||
|
/// Returns an iterator over all occurrences of the needle bytes in the
|
||||||
|
/// given haystack.
|
||||||
|
///
|
||||||
|
/// The iterator returned implements `DoubleEndedIterator`. This means it
|
||||||
|
/// can also be used to find occurrences in reverse order.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(needle1: u8, needle2: u8, haystack: &'h [u8]) -> Memchr2<'h> {
|
||||||
|
Memchr2 {
|
||||||
|
needle1,
|
||||||
|
needle2,
|
||||||
|
it: crate::arch::generic::memchr::Iter::new(haystack),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> Iterator for Memchr2<'h> {
|
||||||
|
type Item = usize;
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn next(&mut self) -> Option<usize> {
|
||||||
|
// SAFETY: All of our implementations of memchr ensure that any
|
||||||
|
// pointers returns will fall within the start and end bounds, and this
|
||||||
|
// upholds the safety contract of `self.it.next`.
|
||||||
|
unsafe {
|
||||||
|
self.it.next(|s, e| memchr2_raw(self.needle1, self.needle2, s, e))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn size_hint(&self) -> (usize, Option<usize>) {
|
||||||
|
self.it.size_hint()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> DoubleEndedIterator for Memchr2<'h> {
|
||||||
|
#[inline]
|
||||||
|
fn next_back(&mut self) -> Option<usize> {
|
||||||
|
// SAFETY: All of our implementations of memchr ensure that any
|
||||||
|
// pointers returns will fall within the start and end bounds, and this
|
||||||
|
// upholds the safety contract of `self.it.next_back`.
|
||||||
|
unsafe {
|
||||||
|
self.it.next_back(|s, e| {
|
||||||
|
memrchr2_raw(self.needle1, self.needle2, s, e)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> core::iter::FusedIterator for Memchr2<'h> {}
|
||||||
|
|
||||||
|
/// An iterator over all occurrences of three possible bytes in a haystack.
|
||||||
|
///
|
||||||
|
/// This iterator implements `DoubleEndedIterator`, which means it can also be
|
||||||
|
/// used to find occurrences in reverse order.
|
||||||
|
///
|
||||||
|
/// This iterator is created by the [`memchr2_iter`] or `[memrchr2_iter`]
|
||||||
|
/// functions. It can also be created with the [`Memchr3::new`] method.
|
||||||
|
///
|
||||||
|
/// The lifetime parameter `'h` refers to the lifetime of the haystack being
|
||||||
|
/// searched.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct Memchr3<'h> {
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
it: crate::arch::generic::memchr::Iter<'h>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> Memchr3<'h> {
|
||||||
|
/// Returns an iterator over all occurrences of the needle bytes in the
|
||||||
|
/// given haystack.
|
||||||
|
///
|
||||||
|
/// The iterator returned implements `DoubleEndedIterator`. This means it
|
||||||
|
/// can also be used to find occurrences in reverse order.
|
||||||
|
#[inline]
|
||||||
|
pub fn new(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
haystack: &'h [u8],
|
||||||
|
) -> Memchr3<'h> {
|
||||||
|
Memchr3 {
|
||||||
|
needle1,
|
||||||
|
needle2,
|
||||||
|
needle3,
|
||||||
|
it: crate::arch::generic::memchr::Iter::new(haystack),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> Iterator for Memchr3<'h> {
|
||||||
|
type Item = usize;
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn next(&mut self) -> Option<usize> {
|
||||||
|
// SAFETY: All of our implementations of memchr ensure that any
|
||||||
|
// pointers returns will fall within the start and end bounds, and this
|
||||||
|
// upholds the safety contract of `self.it.next`.
|
||||||
|
unsafe {
|
||||||
|
self.it.next(|s, e| {
|
||||||
|
memchr3_raw(self.needle1, self.needle2, self.needle3, s, e)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline]
|
||||||
|
fn size_hint(&self) -> (usize, Option<usize>) {
|
||||||
|
self.it.size_hint()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> DoubleEndedIterator for Memchr3<'h> {
|
||||||
|
#[inline]
|
||||||
|
fn next_back(&mut self) -> Option<usize> {
|
||||||
|
// SAFETY: All of our implementations of memchr ensure that any
|
||||||
|
// pointers returns will fall within the start and end bounds, and this
|
||||||
|
// upholds the safety contract of `self.it.next_back`.
|
||||||
|
unsafe {
|
||||||
|
self.it.next_back(|s, e| {
|
||||||
|
memrchr3_raw(self.needle1, self.needle2, self.needle3, s, e)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h> core::iter::FusedIterator for Memchr3<'h> {}
|
||||||
|
|
||||||
|
/// memchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::find_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn memchr_raw(
|
||||||
|
needle: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
// x86_64 does CPU feature detection at runtime in order to use AVX2
|
||||||
|
// instructions even when the `avx2` feature isn't enabled at compile
|
||||||
|
// time. This function also handles using a fallback if neither AVX2
|
||||||
|
// nor SSE2 (unusual) are available.
|
||||||
|
crate::arch::x86_64::memchr::memchr_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::memchr_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::memchr_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::One::new(needle).find_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::rfind_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn memrchr_raw(
|
||||||
|
needle: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
crate::arch::x86_64::memchr::memrchr_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::memrchr_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::memrchr_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::One::new(needle).rfind_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::find_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn memchr2_raw(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
crate::arch::x86_64::memchr::memchr2_raw(needle1, needle2, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::memchr2_raw(needle1, needle2, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::memchr2_raw(needle1, needle2, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::Two::new(needle1, needle2)
|
||||||
|
.find_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr2, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Two::rfind_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn memrchr2_raw(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
crate::arch::x86_64::memchr::memrchr2_raw(needle1, needle2, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::memrchr2_raw(needle1, needle2, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::memrchr2_raw(
|
||||||
|
needle1, needle2, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::Two::new(needle1, needle2)
|
||||||
|
.rfind_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::find_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn memchr3_raw(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
crate::arch::x86_64::memchr::memchr3_raw(
|
||||||
|
needle1, needle2, needle3, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::memchr3_raw(
|
||||||
|
needle1, needle2, needle3, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::memchr3_raw(
|
||||||
|
needle1, needle2, needle3, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::Three::new(needle1, needle2, needle3)
|
||||||
|
.find_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// memrchr3, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `Three::rfind_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn memrchr3_raw(
|
||||||
|
needle1: u8,
|
||||||
|
needle2: u8,
|
||||||
|
needle3: u8,
|
||||||
|
start: *const u8,
|
||||||
|
end: *const u8,
|
||||||
|
) -> Option<*const u8> {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
crate::arch::x86_64::memchr::memrchr3_raw(
|
||||||
|
needle1, needle2, needle3, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::memrchr3_raw(
|
||||||
|
needle1, needle2, needle3, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::memrchr3_raw(
|
||||||
|
needle1, needle2, needle3, start, end,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::Three::new(needle1, needle2, needle3)
|
||||||
|
.rfind_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Count all matching bytes, but using raw pointers to represent the haystack.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Pointers must be valid. See `One::count_raw`.
|
||||||
|
#[inline]
|
||||||
|
unsafe fn count_raw(needle: u8, start: *const u8, end: *const u8) -> usize {
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
{
|
||||||
|
crate::arch::x86_64::memchr::count_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
{
|
||||||
|
crate::arch::wasm32::memchr::count_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
{
|
||||||
|
crate::arch::aarch64::memchr::count_raw(needle, start, end)
|
||||||
|
}
|
||||||
|
#[cfg(not(any(
|
||||||
|
target_arch = "x86_64",
|
||||||
|
all(target_arch = "wasm32", target_feature = "simd128"),
|
||||||
|
target_arch = "aarch64"
|
||||||
|
)))]
|
||||||
|
{
|
||||||
|
crate::arch::all::memchr::One::new(needle).count_raw(start, end)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward1_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(1).forward_iter(
|
||||||
|
|haystack, needles| {
|
||||||
|
Some(memchr_iter(needles[0], haystack).collect())
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward1_oneshot() {
|
||||||
|
crate::tests::memchr::Runner::new(1).forward_oneshot(
|
||||||
|
|haystack, needles| Some(memchr(needles[0], haystack)),
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse1_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(1).reverse_iter(
|
||||||
|
|haystack, needles| {
|
||||||
|
Some(memrchr_iter(needles[0], haystack).collect())
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse1_oneshot() {
|
||||||
|
crate::tests::memchr::Runner::new(1).reverse_oneshot(
|
||||||
|
|haystack, needles| Some(memrchr(needles[0], haystack)),
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn count1_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(1).count_iter(|haystack, needles| {
|
||||||
|
Some(memchr_iter(needles[0], haystack).count())
|
||||||
|
})
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward2_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(2).forward_iter(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
Some(memchr2_iter(n1, n2, haystack).collect())
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward2_oneshot() {
|
||||||
|
crate::tests::memchr::Runner::new(2).forward_oneshot(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
Some(memchr2(n1, n2, haystack))
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse2_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(2).reverse_iter(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
Some(memrchr2_iter(n1, n2, haystack).collect())
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse2_oneshot() {
|
||||||
|
crate::tests::memchr::Runner::new(2).reverse_oneshot(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
Some(memrchr2(n1, n2, haystack))
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward3_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(3).forward_iter(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
let n3 = needles.get(2).copied()?;
|
||||||
|
Some(memchr3_iter(n1, n2, n3, haystack).collect())
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward3_oneshot() {
|
||||||
|
crate::tests::memchr::Runner::new(3).forward_oneshot(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
let n3 = needles.get(2).copied()?;
|
||||||
|
Some(memchr3(n1, n2, n3, haystack))
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse3_iter() {
|
||||||
|
crate::tests::memchr::Runner::new(3).reverse_iter(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
let n3 = needles.get(2).copied()?;
|
||||||
|
Some(memrchr3_iter(n1, n2, n3, haystack).collect())
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse3_oneshot() {
|
||||||
|
crate::tests::memchr::Runner::new(3).reverse_oneshot(
|
||||||
|
|haystack, needles| {
|
||||||
|
let n1 = needles.get(0).copied()?;
|
||||||
|
let n2 = needles.get(1).copied()?;
|
||||||
|
let n3 = needles.get(2).copied()?;
|
||||||
|
Some(memrchr3(n1, n2, n3, haystack))
|
||||||
|
},
|
||||||
|
)
|
||||||
|
}
|
||||||
|
|
||||||
|
// Prior to memchr 2.6, the memchr iterators both implemented Send and
|
||||||
|
// Sync. But in memchr 2.6, the iterator changed to use raw pointers
|
||||||
|
// internally and I didn't add explicit Send/Sync impls. This ended up
|
||||||
|
// regressing the API. This test ensures we don't do that again.
|
||||||
|
//
|
||||||
|
// See: https://github.com/BurntSushi/memchr/issues/133
|
||||||
|
#[test]
|
||||||
|
fn sync_regression() {
|
||||||
|
use core::panic::{RefUnwindSafe, UnwindSafe};
|
||||||
|
|
||||||
|
fn assert_send_sync<T: Send + Sync + UnwindSafe + RefUnwindSafe>() {}
|
||||||
|
assert_send_sync::<Memchr>();
|
||||||
|
assert_send_sync::<Memchr2>();
|
||||||
|
assert_send_sync::<Memchr3>()
|
||||||
|
}
|
||||||
|
}
|
||||||
767
third_party/crates/memchr-2.8.3/src/memmem/mod.rs
vendored
Normal file
767
third_party/crates/memchr-2.8.3/src/memmem/mod.rs
vendored
Normal file
@@ -0,0 +1,767 @@
|
|||||||
|
/*!
|
||||||
|
This module provides forward and reverse substring search routines.
|
||||||
|
|
||||||
|
Unlike the standard library's substring search routines, these work on
|
||||||
|
arbitrary bytes. For all non-empty needles, these routines will report exactly
|
||||||
|
the same values as the corresponding routines in the standard library. For
|
||||||
|
the empty needle, the standard library reports matches only at valid UTF-8
|
||||||
|
boundaries, where as these routines will report matches at every position.
|
||||||
|
|
||||||
|
Other than being able to work on arbitrary bytes, the primary reason to prefer
|
||||||
|
these routines over the standard library routines is that these will generally
|
||||||
|
be faster. In some cases, significantly so.
|
||||||
|
|
||||||
|
# Example: iterating over substring matches
|
||||||
|
|
||||||
|
This example shows how to use [`find_iter`] to find occurrences of a substring
|
||||||
|
in a haystack.
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memmem;
|
||||||
|
|
||||||
|
let haystack = b"foo bar foo baz foo";
|
||||||
|
|
||||||
|
let mut it = memmem::find_iter(haystack, "foo");
|
||||||
|
assert_eq!(Some(0), it.next());
|
||||||
|
assert_eq!(Some(8), it.next());
|
||||||
|
assert_eq!(Some(16), it.next());
|
||||||
|
assert_eq!(None, it.next());
|
||||||
|
```
|
||||||
|
|
||||||
|
# Example: iterating over substring matches in reverse
|
||||||
|
|
||||||
|
This example shows how to use [`rfind_iter`] to find occurrences of a substring
|
||||||
|
in a haystack starting from the end of the haystack.
|
||||||
|
|
||||||
|
**NOTE:** This module does not implement double ended iterators, so reverse
|
||||||
|
searches aren't done by calling `rev` on a forward iterator.
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memmem;
|
||||||
|
|
||||||
|
let haystack = b"foo bar foo baz foo";
|
||||||
|
|
||||||
|
let mut it = memmem::rfind_iter(haystack, "foo");
|
||||||
|
assert_eq!(Some(16), it.next());
|
||||||
|
assert_eq!(Some(8), it.next());
|
||||||
|
assert_eq!(Some(0), it.next());
|
||||||
|
assert_eq!(None, it.next());
|
||||||
|
```
|
||||||
|
|
||||||
|
# Example: repeating a search for the same needle
|
||||||
|
|
||||||
|
It may be possible for the overhead of constructing a substring searcher to be
|
||||||
|
measurable in some workloads. In cases where the same needle is used to search
|
||||||
|
many haystacks, it is possible to do construction once and thus to avoid it for
|
||||||
|
subsequent searches. This can be done with a [`Finder`] (or a [`FinderRev`] for
|
||||||
|
reverse searches).
|
||||||
|
|
||||||
|
```
|
||||||
|
use memchr::memmem;
|
||||||
|
|
||||||
|
let finder = memmem::Finder::new("foo");
|
||||||
|
|
||||||
|
assert_eq!(Some(4), finder.find(b"baz foo quux"));
|
||||||
|
assert_eq!(None, finder.find(b"quux baz bar"));
|
||||||
|
```
|
||||||
|
*/
|
||||||
|
|
||||||
|
pub use crate::memmem::searcher::PrefilterConfig as Prefilter;
|
||||||
|
|
||||||
|
// This is exported here for use in the crate::arch::all::twoway
|
||||||
|
// implementation. This is essentially an abstraction breaker. Namely, the
|
||||||
|
// public API of twoway doesn't support providing a prefilter, but its crate
|
||||||
|
// internal API does. The main reason for this is that I didn't want to do the
|
||||||
|
// API design required to support it without a concrete use case.
|
||||||
|
pub(crate) use crate::memmem::searcher::Pre;
|
||||||
|
|
||||||
|
use crate::{
|
||||||
|
arch::all::{
|
||||||
|
packedpair::{DefaultFrequencyRank, HeuristicFrequencyRank},
|
||||||
|
rabinkarp,
|
||||||
|
},
|
||||||
|
cow::CowBytes,
|
||||||
|
memmem::searcher::{PrefilterState, Searcher, SearcherRev},
|
||||||
|
};
|
||||||
|
|
||||||
|
mod searcher;
|
||||||
|
|
||||||
|
/// Returns an iterator over all non-overlapping occurrences of a substring in
|
||||||
|
/// a haystack.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar foo baz foo";
|
||||||
|
/// let mut it = memmem::find_iter(haystack, b"foo");
|
||||||
|
/// assert_eq!(Some(0), it.next());
|
||||||
|
/// assert_eq!(Some(8), it.next());
|
||||||
|
/// assert_eq!(Some(16), it.next());
|
||||||
|
/// assert_eq!(None, it.next());
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn find_iter<'h, 'n, N: 'n + ?Sized + AsRef<[u8]>>(
|
||||||
|
haystack: &'h [u8],
|
||||||
|
needle: &'n N,
|
||||||
|
) -> FindIter<'h, 'n> {
|
||||||
|
FindIter::new(haystack, Finder::new(needle))
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns a reverse iterator over all non-overlapping occurrences of a
|
||||||
|
/// substring in a haystack.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar foo baz foo";
|
||||||
|
/// let mut it = memmem::rfind_iter(haystack, b"foo");
|
||||||
|
/// assert_eq!(Some(16), it.next());
|
||||||
|
/// assert_eq!(Some(8), it.next());
|
||||||
|
/// assert_eq!(Some(0), it.next());
|
||||||
|
/// assert_eq!(None, it.next());
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn rfind_iter<'h, 'n, N: 'n + ?Sized + AsRef<[u8]>>(
|
||||||
|
haystack: &'h [u8],
|
||||||
|
needle: &'n N,
|
||||||
|
) -> FindRevIter<'h, 'n> {
|
||||||
|
FindRevIter::new(haystack, FinderRev::new(needle))
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the index of the first occurrence of the given needle.
|
||||||
|
///
|
||||||
|
/// Note that if you're are searching for the same needle in many different
|
||||||
|
/// small haystacks, it may be faster to initialize a [`Finder`] once,
|
||||||
|
/// and reuse it for each search.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar baz";
|
||||||
|
/// assert_eq!(Some(0), memmem::find(haystack, b"foo"));
|
||||||
|
/// assert_eq!(Some(4), memmem::find(haystack, b"bar"));
|
||||||
|
/// assert_eq!(None, memmem::find(haystack, b"quux"));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn find(haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
if haystack.len() < 64 {
|
||||||
|
rabinkarp::Finder::new(needle).find(haystack, needle)
|
||||||
|
} else {
|
||||||
|
Finder::new(needle).find(haystack)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the index of the last occurrence of the given needle.
|
||||||
|
///
|
||||||
|
/// Note that if you're are searching for the same needle in many different
|
||||||
|
/// small haystacks, it may be faster to initialize a [`FinderRev`] once,
|
||||||
|
/// and reuse it for each search.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar baz";
|
||||||
|
/// assert_eq!(Some(0), memmem::rfind(haystack, b"foo"));
|
||||||
|
/// assert_eq!(Some(4), memmem::rfind(haystack, b"bar"));
|
||||||
|
/// assert_eq!(Some(8), memmem::rfind(haystack, b"ba"));
|
||||||
|
/// assert_eq!(None, memmem::rfind(haystack, b"quux"));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn rfind(haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
if haystack.len() < 64 {
|
||||||
|
rabinkarp::FinderRev::new(needle).rfind(haystack, needle)
|
||||||
|
} else {
|
||||||
|
FinderRev::new(needle).rfind(haystack)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// An iterator over non-overlapping substring matches.
|
||||||
|
///
|
||||||
|
/// Matches are reported by the byte offset at which they begin.
|
||||||
|
///
|
||||||
|
/// `'h` is the lifetime of the haystack while `'n` is the lifetime of the
|
||||||
|
/// needle.
|
||||||
|
#[derive(Debug, Clone)]
|
||||||
|
pub struct FindIter<'h, 'n> {
|
||||||
|
haystack: &'h [u8],
|
||||||
|
prestate: PrefilterState,
|
||||||
|
finder: Finder<'n>,
|
||||||
|
pos: usize,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h, 'n> FindIter<'h, 'n> {
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn new(
|
||||||
|
haystack: &'h [u8],
|
||||||
|
finder: Finder<'n>,
|
||||||
|
) -> FindIter<'h, 'n> {
|
||||||
|
let prestate = PrefilterState::new();
|
||||||
|
FindIter { haystack, prestate, finder, pos: 0 }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convert this iterator into its owned variant, such that it no longer
|
||||||
|
/// borrows the finder and needle.
|
||||||
|
///
|
||||||
|
/// If this is already an owned iterator, then this is a no-op. Otherwise,
|
||||||
|
/// this copies the needle.
|
||||||
|
///
|
||||||
|
/// This is only available when the `alloc` feature is enabled.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline]
|
||||||
|
pub fn into_owned(self) -> FindIter<'h, 'static> {
|
||||||
|
FindIter {
|
||||||
|
haystack: self.haystack,
|
||||||
|
prestate: self.prestate,
|
||||||
|
finder: self.finder.into_owned(),
|
||||||
|
pos: self.pos,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h, 'n> Iterator for FindIter<'h, 'n> {
|
||||||
|
type Item = usize;
|
||||||
|
|
||||||
|
fn next(&mut self) -> Option<usize> {
|
||||||
|
let needle = self.finder.needle();
|
||||||
|
let haystack = self.haystack.get(self.pos..)?;
|
||||||
|
let idx =
|
||||||
|
self.finder.searcher.find(&mut self.prestate, haystack, needle)?;
|
||||||
|
|
||||||
|
let pos = self.pos + idx;
|
||||||
|
self.pos = pos + needle.len().max(1);
|
||||||
|
|
||||||
|
Some(pos)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn size_hint(&self) -> (usize, Option<usize>) {
|
||||||
|
// The largest possible number of non-overlapping matches is the
|
||||||
|
// quotient of the haystack and the needle (or the length of the
|
||||||
|
// haystack, if the needle is empty)
|
||||||
|
match self.haystack.len().checked_sub(self.pos) {
|
||||||
|
None => (0, Some(0)),
|
||||||
|
Some(haystack_len) => match self.finder.needle().len() {
|
||||||
|
// Empty needles always succeed and match at every point
|
||||||
|
// (including the very end)
|
||||||
|
0 => (
|
||||||
|
haystack_len.saturating_add(1),
|
||||||
|
haystack_len.checked_add(1),
|
||||||
|
),
|
||||||
|
needle_len => (0, Some(haystack_len / needle_len)),
|
||||||
|
},
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// An iterator over non-overlapping substring matches in reverse.
|
||||||
|
///
|
||||||
|
/// Matches are reported by the byte offset at which they begin.
|
||||||
|
///
|
||||||
|
/// `'h` is the lifetime of the haystack while `'n` is the lifetime of the
|
||||||
|
/// needle.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct FindRevIter<'h, 'n> {
|
||||||
|
haystack: &'h [u8],
|
||||||
|
finder: FinderRev<'n>,
|
||||||
|
/// When searching with an empty needle, this gets set to `None` after
|
||||||
|
/// we've yielded the last element at `0`.
|
||||||
|
pos: Option<usize>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h, 'n> FindRevIter<'h, 'n> {
|
||||||
|
#[inline(always)]
|
||||||
|
pub(crate) fn new(
|
||||||
|
haystack: &'h [u8],
|
||||||
|
finder: FinderRev<'n>,
|
||||||
|
) -> FindRevIter<'h, 'n> {
|
||||||
|
let pos = Some(haystack.len());
|
||||||
|
FindRevIter { haystack, finder, pos }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convert this iterator into its owned variant, such that it no longer
|
||||||
|
/// borrows the finder and needle.
|
||||||
|
///
|
||||||
|
/// If this is already an owned iterator, then this is a no-op. Otherwise,
|
||||||
|
/// this copies the needle.
|
||||||
|
///
|
||||||
|
/// This is only available when the `std` feature is enabled.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline]
|
||||||
|
pub fn into_owned(self) -> FindRevIter<'h, 'static> {
|
||||||
|
FindRevIter {
|
||||||
|
haystack: self.haystack,
|
||||||
|
finder: self.finder.into_owned(),
|
||||||
|
pos: self.pos,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'h, 'n> Iterator for FindRevIter<'h, 'n> {
|
||||||
|
type Item = usize;
|
||||||
|
|
||||||
|
fn next(&mut self) -> Option<usize> {
|
||||||
|
let pos = self.pos?;
|
||||||
|
let result = self.finder.rfind(&self.haystack[..pos]);
|
||||||
|
match result {
|
||||||
|
None => None,
|
||||||
|
Some(i) => {
|
||||||
|
if pos == i {
|
||||||
|
self.pos = pos.checked_sub(1);
|
||||||
|
} else {
|
||||||
|
self.pos = Some(i);
|
||||||
|
}
|
||||||
|
Some(i)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A single substring searcher fixed to a particular needle.
|
||||||
|
///
|
||||||
|
/// The purpose of this type is to permit callers to construct a substring
|
||||||
|
/// searcher that can be used to search haystacks without the overhead of
|
||||||
|
/// constructing the searcher in the first place. This is a somewhat niche
|
||||||
|
/// concern when it's necessary to re-use the same needle to search multiple
|
||||||
|
/// different haystacks with as little overhead as possible. In general, using
|
||||||
|
/// [`find`] is good enough, but `Finder` is useful when you can meaningfully
|
||||||
|
/// observe searcher construction time in a profile.
|
||||||
|
///
|
||||||
|
/// When the `std` feature is enabled, then this type has an `into_owned`
|
||||||
|
/// version which permits building a `Finder` that is not connected to
|
||||||
|
/// the lifetime of its needle.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct Finder<'n> {
|
||||||
|
needle: CowBytes<'n>,
|
||||||
|
searcher: Searcher,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'n> Finder<'n> {
|
||||||
|
/// Create a new finder for the given needle.
|
||||||
|
#[inline]
|
||||||
|
pub fn new<B: ?Sized + AsRef<[u8]>>(needle: &'n B) -> Finder<'n> {
|
||||||
|
FinderBuilder::new().build_forward(needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the index of the first occurrence of this needle in the given
|
||||||
|
/// haystack.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem::Finder;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar baz";
|
||||||
|
/// assert_eq!(Some(0), Finder::new("foo").find(haystack));
|
||||||
|
/// assert_eq!(Some(4), Finder::new("bar").find(haystack));
|
||||||
|
/// assert_eq!(None, Finder::new("quux").find(haystack));
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn find(&self, haystack: &[u8]) -> Option<usize> {
|
||||||
|
let mut prestate = PrefilterState::new();
|
||||||
|
let needle = self.needle.as_slice();
|
||||||
|
self.searcher.find(&mut prestate, haystack, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns an iterator over all occurrences of a substring in a haystack.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem::Finder;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar foo baz foo";
|
||||||
|
/// let finder = Finder::new(b"foo");
|
||||||
|
/// let mut it = finder.find_iter(haystack);
|
||||||
|
/// assert_eq!(Some(0), it.next());
|
||||||
|
/// assert_eq!(Some(8), it.next());
|
||||||
|
/// assert_eq!(Some(16), it.next());
|
||||||
|
/// assert_eq!(None, it.next());
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn find_iter<'a, 'h>(
|
||||||
|
&'a self,
|
||||||
|
haystack: &'h [u8],
|
||||||
|
) -> FindIter<'h, 'a> {
|
||||||
|
FindIter::new(haystack, self.as_ref())
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convert this finder into its owned variant, such that it no longer
|
||||||
|
/// borrows the needle.
|
||||||
|
///
|
||||||
|
/// If this is already an owned finder, then this is a no-op. Otherwise,
|
||||||
|
/// this copies the needle.
|
||||||
|
///
|
||||||
|
/// This is only available when the `alloc` feature is enabled.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline]
|
||||||
|
pub fn into_owned(self) -> Finder<'static> {
|
||||||
|
Finder { needle: self.needle.into_owned(), searcher: self.searcher }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convert this finder into its borrowed variant.
|
||||||
|
///
|
||||||
|
/// This is primarily useful if your finder is owned and you'd like to
|
||||||
|
/// store its borrowed variant in some intermediate data structure.
|
||||||
|
///
|
||||||
|
/// Note that the lifetime parameter of the returned finder is tied to the
|
||||||
|
/// lifetime of `self`, and may be shorter than the `'n` lifetime of the
|
||||||
|
/// needle itself. Namely, a finder's needle can be either borrowed or
|
||||||
|
/// owned, so the lifetime of the needle returned must necessarily be the
|
||||||
|
/// shorter of the two.
|
||||||
|
#[inline]
|
||||||
|
pub fn as_ref(&self) -> Finder<'_> {
|
||||||
|
Finder {
|
||||||
|
needle: CowBytes::new(self.needle()),
|
||||||
|
searcher: self.searcher.clone(),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the needle that this finder searches for.
|
||||||
|
///
|
||||||
|
/// Note that the lifetime of the needle returned is tied to the lifetime
|
||||||
|
/// of the finder, and may be shorter than the `'n` lifetime. Namely, a
|
||||||
|
/// finder's needle can be either borrowed or owned, so the lifetime of the
|
||||||
|
/// needle returned must necessarily be the shorter of the two.
|
||||||
|
#[inline]
|
||||||
|
pub fn needle(&self) -> &[u8] {
|
||||||
|
self.needle.as_slice()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A single substring reverse searcher fixed to a particular needle.
|
||||||
|
///
|
||||||
|
/// The purpose of this type is to permit callers to construct a substring
|
||||||
|
/// searcher that can be used to search haystacks without the overhead of
|
||||||
|
/// constructing the searcher in the first place. This is a somewhat niche
|
||||||
|
/// concern when it's necessary to re-use the same needle to search multiple
|
||||||
|
/// different haystacks with as little overhead as possible. In general,
|
||||||
|
/// using [`rfind`] is good enough, but `FinderRev` is useful when you can
|
||||||
|
/// meaningfully observe searcher construction time in a profile.
|
||||||
|
///
|
||||||
|
/// When the `std` feature is enabled, then this type has an `into_owned`
|
||||||
|
/// version which permits building a `FinderRev` that is not connected to
|
||||||
|
/// the lifetime of its needle.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
pub struct FinderRev<'n> {
|
||||||
|
needle: CowBytes<'n>,
|
||||||
|
searcher: SearcherRev,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'n> FinderRev<'n> {
|
||||||
|
/// Create a new reverse finder for the given needle.
|
||||||
|
#[inline]
|
||||||
|
pub fn new<B: ?Sized + AsRef<[u8]>>(needle: &'n B) -> FinderRev<'n> {
|
||||||
|
FinderBuilder::new().build_reverse(needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the index of the last occurrence of this needle in the given
|
||||||
|
/// haystack.
|
||||||
|
///
|
||||||
|
/// The haystack may be any type that can be cheaply converted into a
|
||||||
|
/// `&[u8]`. This includes, but is not limited to, `&str` and `&[u8]`.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem::FinderRev;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar baz";
|
||||||
|
/// assert_eq!(Some(0), FinderRev::new("foo").rfind(haystack));
|
||||||
|
/// assert_eq!(Some(4), FinderRev::new("bar").rfind(haystack));
|
||||||
|
/// assert_eq!(None, FinderRev::new("quux").rfind(haystack));
|
||||||
|
/// ```
|
||||||
|
pub fn rfind<B: AsRef<[u8]>>(&self, haystack: B) -> Option<usize> {
|
||||||
|
self.searcher.rfind(haystack.as_ref(), self.needle.as_slice())
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns a reverse iterator over all occurrences of a substring in a
|
||||||
|
/// haystack.
|
||||||
|
///
|
||||||
|
/// # Complexity
|
||||||
|
///
|
||||||
|
/// This routine is guaranteed to have worst case linear time complexity
|
||||||
|
/// with respect to both the needle and the haystack. That is, this runs
|
||||||
|
/// in `O(needle.len() + haystack.len())` time.
|
||||||
|
///
|
||||||
|
/// This routine is also guaranteed to have worst case constant space
|
||||||
|
/// complexity.
|
||||||
|
///
|
||||||
|
/// # Examples
|
||||||
|
///
|
||||||
|
/// Basic usage:
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use memchr::memmem::FinderRev;
|
||||||
|
///
|
||||||
|
/// let haystack = b"foo bar foo baz foo";
|
||||||
|
/// let finder = FinderRev::new(b"foo");
|
||||||
|
/// let mut it = finder.rfind_iter(haystack);
|
||||||
|
/// assert_eq!(Some(16), it.next());
|
||||||
|
/// assert_eq!(Some(8), it.next());
|
||||||
|
/// assert_eq!(Some(0), it.next());
|
||||||
|
/// assert_eq!(None, it.next());
|
||||||
|
/// ```
|
||||||
|
#[inline]
|
||||||
|
pub fn rfind_iter<'a, 'h>(
|
||||||
|
&'a self,
|
||||||
|
haystack: &'h [u8],
|
||||||
|
) -> FindRevIter<'h, 'a> {
|
||||||
|
FindRevIter::new(haystack, self.as_ref())
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convert this finder into its owned variant, such that it no longer
|
||||||
|
/// borrows the needle.
|
||||||
|
///
|
||||||
|
/// If this is already an owned finder, then this is a no-op. Otherwise,
|
||||||
|
/// this copies the needle.
|
||||||
|
///
|
||||||
|
/// This is only available when the `std` feature is enabled.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
#[inline]
|
||||||
|
pub fn into_owned(self) -> FinderRev<'static> {
|
||||||
|
FinderRev { needle: self.needle.into_owned(), searcher: self.searcher }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Convert this finder into its borrowed variant.
|
||||||
|
///
|
||||||
|
/// This is primarily useful if your finder is owned and you'd like to
|
||||||
|
/// store its borrowed variant in some intermediate data structure.
|
||||||
|
///
|
||||||
|
/// Note that the lifetime parameter of the returned finder is tied to the
|
||||||
|
/// lifetime of `self`, and may be shorter than the `'n` lifetime of the
|
||||||
|
/// needle itself. Namely, a finder's needle can be either borrowed or
|
||||||
|
/// owned, so the lifetime of the needle returned must necessarily be the
|
||||||
|
/// shorter of the two.
|
||||||
|
#[inline]
|
||||||
|
pub fn as_ref(&self) -> FinderRev<'_> {
|
||||||
|
FinderRev {
|
||||||
|
needle: CowBytes::new(self.needle()),
|
||||||
|
searcher: self.searcher.clone(),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns the needle that this finder searches for.
|
||||||
|
///
|
||||||
|
/// Note that the lifetime of the needle returned is tied to the lifetime
|
||||||
|
/// of the finder, and may be shorter than the `'n` lifetime. Namely, a
|
||||||
|
/// finder's needle can be either borrowed or owned, so the lifetime of the
|
||||||
|
/// needle returned must necessarily be the shorter of the two.
|
||||||
|
#[inline]
|
||||||
|
pub fn needle(&self) -> &[u8] {
|
||||||
|
self.needle.as_slice()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A builder for constructing non-default forward or reverse memmem finders.
|
||||||
|
///
|
||||||
|
/// A builder is primarily useful for configuring a substring searcher.
|
||||||
|
/// Currently, the only configuration exposed is the ability to disable
|
||||||
|
/// heuristic prefilters used to speed up certain searches.
|
||||||
|
#[derive(Clone, Debug, Default)]
|
||||||
|
pub struct FinderBuilder {
|
||||||
|
prefilter: Prefilter,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl FinderBuilder {
|
||||||
|
/// Create a new finder builder with default settings.
|
||||||
|
pub fn new() -> FinderBuilder {
|
||||||
|
FinderBuilder::default()
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Build a forward finder using the given needle from the current
|
||||||
|
/// settings.
|
||||||
|
pub fn build_forward<'n, B: ?Sized + AsRef<[u8]>>(
|
||||||
|
&self,
|
||||||
|
needle: &'n B,
|
||||||
|
) -> Finder<'n> {
|
||||||
|
self.build_forward_with_ranker(DefaultFrequencyRank, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Build an owned forward finder using the given needle from the current
|
||||||
|
/// settings.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
pub fn build_forward_owned<B: Into<alloc::boxed::Box<[u8]>>>(
|
||||||
|
&self,
|
||||||
|
needle: B,
|
||||||
|
) -> Finder<'static> {
|
||||||
|
self.build_forward_with_ranker_owned(DefaultFrequencyRank, needle)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Build a forward finder using the given needle and a custom heuristic
|
||||||
|
/// for determining the frequency of a given byte in the dataset. See
|
||||||
|
/// [`HeuristicFrequencyRank`] for more details.
|
||||||
|
pub fn build_forward_with_ranker<
|
||||||
|
'n,
|
||||||
|
R: HeuristicFrequencyRank,
|
||||||
|
B: ?Sized + AsRef<[u8]>,
|
||||||
|
>(
|
||||||
|
&self,
|
||||||
|
ranker: R,
|
||||||
|
needle: &'n B,
|
||||||
|
) -> Finder<'n> {
|
||||||
|
let needle = needle.as_ref();
|
||||||
|
Finder {
|
||||||
|
needle: CowBytes::new(needle),
|
||||||
|
searcher: Searcher::new(self.prefilter, ranker, needle),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Build an owned forward finder using the given needle and a custom
|
||||||
|
/// heuristic for determining the frequency of a given byte in the dataset.
|
||||||
|
/// See [`HeuristicFrequencyRank`] for more details.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
pub fn build_forward_with_ranker_owned<
|
||||||
|
R: HeuristicFrequencyRank,
|
||||||
|
B: Into<alloc::boxed::Box<[u8]>>,
|
||||||
|
>(
|
||||||
|
&self,
|
||||||
|
ranker: R,
|
||||||
|
needle: B,
|
||||||
|
) -> Finder<'static> {
|
||||||
|
let needle = needle.into();
|
||||||
|
let searcher = Searcher::new(self.prefilter, ranker, &needle);
|
||||||
|
Finder { needle: CowBytes::new_owned(needle), searcher }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Build a reverse finder using the given needle from the current
|
||||||
|
/// settings.
|
||||||
|
pub fn build_reverse<'n, B: ?Sized + AsRef<[u8]>>(
|
||||||
|
&self,
|
||||||
|
needle: &'n B,
|
||||||
|
) -> FinderRev<'n> {
|
||||||
|
let needle = needle.as_ref();
|
||||||
|
FinderRev {
|
||||||
|
needle: CowBytes::new(needle),
|
||||||
|
searcher: SearcherRev::new(needle),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Build an owned reverse finder using the given needle from the current
|
||||||
|
/// settings.
|
||||||
|
#[cfg(feature = "alloc")]
|
||||||
|
pub fn build_reverse_owned<B: Into<alloc::boxed::Box<[u8]>>>(
|
||||||
|
&self,
|
||||||
|
needle: B,
|
||||||
|
) -> FinderRev<'static> {
|
||||||
|
let needle = needle.into();
|
||||||
|
let searcher = SearcherRev::new(&needle);
|
||||||
|
FinderRev { needle: CowBytes::new_owned(needle), searcher }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Configure the prefilter setting for the finder.
|
||||||
|
///
|
||||||
|
/// See the documentation for [`Prefilter`] for more discussion on why
|
||||||
|
/// you might want to configure this.
|
||||||
|
pub fn prefilter(&mut self, prefilter: Prefilter) -> &mut FinderBuilder {
|
||||||
|
self.prefilter = prefilter;
|
||||||
|
self
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
define_substring_forward_quickcheck!(|h, n| Some(Finder::new(n).find(h)));
|
||||||
|
define_substring_reverse_quickcheck!(|h, n| Some(
|
||||||
|
FinderRev::new(n).rfind(h)
|
||||||
|
));
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.fwd(|h, n| Some(Finder::new(n).find(h)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse() {
|
||||||
|
crate::tests::substring::Runner::new()
|
||||||
|
.rev(|h, n| Some(FinderRev::new(n).rfind(h)))
|
||||||
|
.run();
|
||||||
|
}
|
||||||
|
}
|
||||||
1028
third_party/crates/memchr-2.8.3/src/memmem/searcher.rs
vendored
Normal file
1028
third_party/crates/memchr-2.8.3/src/memmem/searcher.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
307
third_party/crates/memchr-2.8.3/src/tests/memchr/mod.rs
vendored
Normal file
307
third_party/crates/memchr-2.8.3/src/tests/memchr/mod.rs
vendored
Normal file
@@ -0,0 +1,307 @@
|
|||||||
|
use alloc::{
|
||||||
|
string::{String, ToString},
|
||||||
|
vec,
|
||||||
|
vec::Vec,
|
||||||
|
};
|
||||||
|
|
||||||
|
use crate::ext::Byte;
|
||||||
|
|
||||||
|
pub(crate) mod naive;
|
||||||
|
#[macro_use]
|
||||||
|
pub(crate) mod prop;
|
||||||
|
|
||||||
|
const SEEDS: &'static [Seed] = &[
|
||||||
|
Seed { haystack: "a", needles: &[b'a'], positions: &[0] },
|
||||||
|
Seed { haystack: "aa", needles: &[b'a'], positions: &[0, 1] },
|
||||||
|
Seed { haystack: "aaa", needles: &[b'a'], positions: &[0, 1, 2] },
|
||||||
|
Seed { haystack: "", needles: &[b'a'], positions: &[] },
|
||||||
|
Seed { haystack: "z", needles: &[b'a'], positions: &[] },
|
||||||
|
Seed { haystack: "zz", needles: &[b'a'], positions: &[] },
|
||||||
|
Seed { haystack: "zza", needles: &[b'a'], positions: &[2] },
|
||||||
|
Seed { haystack: "zaza", needles: &[b'a'], positions: &[1, 3] },
|
||||||
|
Seed { haystack: "zzza", needles: &[b'a'], positions: &[3] },
|
||||||
|
Seed { haystack: "\x00a", needles: &[b'a'], positions: &[1] },
|
||||||
|
Seed { haystack: "\x00", needles: &[b'\x00'], positions: &[0] },
|
||||||
|
Seed { haystack: "\x00\x00", needles: &[b'\x00'], positions: &[0, 1] },
|
||||||
|
Seed { haystack: "\x00a\x00", needles: &[b'\x00'], positions: &[0, 2] },
|
||||||
|
Seed { haystack: "zzzzzzzzzzzzzzzza", needles: &[b'a'], positions: &[16] },
|
||||||
|
Seed {
|
||||||
|
haystack: "zzzzzzzzzzzzzzzzzzzzzzzzzzzzzzzza",
|
||||||
|
needles: &[b'a'],
|
||||||
|
positions: &[32],
|
||||||
|
},
|
||||||
|
// two needles (applied to memchr2 + memchr3)
|
||||||
|
Seed { haystack: "az", needles: &[b'a', b'z'], positions: &[0, 1] },
|
||||||
|
Seed { haystack: "az", needles: &[b'a', b'z'], positions: &[0, 1] },
|
||||||
|
Seed { haystack: "az", needles: &[b'x', b'y'], positions: &[] },
|
||||||
|
Seed { haystack: "az", needles: &[b'a', b'y'], positions: &[0] },
|
||||||
|
Seed { haystack: "az", needles: &[b'x', b'z'], positions: &[1] },
|
||||||
|
Seed { haystack: "yyyyaz", needles: &[b'a', b'z'], positions: &[4, 5] },
|
||||||
|
Seed { haystack: "yyyyaz", needles: &[b'z', b'a'], positions: &[4, 5] },
|
||||||
|
// three needles (applied to memchr3)
|
||||||
|
Seed {
|
||||||
|
haystack: "xyz",
|
||||||
|
needles: &[b'x', b'y', b'z'],
|
||||||
|
positions: &[0, 1, 2],
|
||||||
|
},
|
||||||
|
Seed {
|
||||||
|
haystack: "zxy",
|
||||||
|
needles: &[b'x', b'y', b'z'],
|
||||||
|
positions: &[0, 1, 2],
|
||||||
|
},
|
||||||
|
Seed { haystack: "zxy", needles: &[b'x', b'a', b'z'], positions: &[0, 1] },
|
||||||
|
Seed { haystack: "zxy", needles: &[b't', b'a', b'z'], positions: &[0] },
|
||||||
|
Seed { haystack: "yxz", needles: &[b't', b'a', b'z'], positions: &[2] },
|
||||||
|
];
|
||||||
|
|
||||||
|
/// Runs a host of substring search tests.
|
||||||
|
///
|
||||||
|
/// This has support for "partial" substring search implementations only work
|
||||||
|
/// for a subset of needles/haystacks. For example, the "packed pair" substring
|
||||||
|
/// search implementation only works for haystacks of some minimum length based
|
||||||
|
/// of the pair of bytes selected and the size of the vector used.
|
||||||
|
pub(crate) struct Runner {
|
||||||
|
needle_len: usize,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Runner {
|
||||||
|
/// Create a new test runner for forward and reverse byte search
|
||||||
|
/// implementations.
|
||||||
|
///
|
||||||
|
/// The `needle_len` given must be at most `3` and at least `1`. It
|
||||||
|
/// corresponds to the number of needle bytes to search for.
|
||||||
|
pub(crate) fn new(needle_len: usize) -> Runner {
|
||||||
|
assert!(needle_len >= 1, "needle_len must be at least 1");
|
||||||
|
assert!(needle_len <= 3, "needle_len must be at most 3");
|
||||||
|
Runner { needle_len }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run all tests. This panics on the first failure.
|
||||||
|
///
|
||||||
|
/// If the implementation being tested returns `None` for a particular
|
||||||
|
/// haystack/needle combination, then that test is skipped.
|
||||||
|
pub(crate) fn forward_iter<F>(self, mut test: F)
|
||||||
|
where
|
||||||
|
F: FnMut(&[u8], &[u8]) -> Option<Vec<usize>> + 'static,
|
||||||
|
{
|
||||||
|
for seed in SEEDS.iter() {
|
||||||
|
if seed.needles.len() > self.needle_len {
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
for t in seed.generate() {
|
||||||
|
let results = match test(t.haystack.as_bytes(), &t.needles) {
|
||||||
|
None => continue,
|
||||||
|
Some(results) => results,
|
||||||
|
};
|
||||||
|
assert_eq!(
|
||||||
|
t.expected,
|
||||||
|
results,
|
||||||
|
"needles: {:?}, haystack: {:?}",
|
||||||
|
t.needles
|
||||||
|
.iter()
|
||||||
|
.map(|&b| b.to_char())
|
||||||
|
.collect::<Vec<char>>(),
|
||||||
|
t.haystack,
|
||||||
|
);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run all tests in the reverse direction. This panics on the first
|
||||||
|
/// failure.
|
||||||
|
///
|
||||||
|
/// If the implementation being tested returns `None` for a particular
|
||||||
|
/// haystack/needle combination, then that test is skipped.
|
||||||
|
pub(crate) fn reverse_iter<F>(self, mut test: F)
|
||||||
|
where
|
||||||
|
F: FnMut(&[u8], &[u8]) -> Option<Vec<usize>> + 'static,
|
||||||
|
{
|
||||||
|
for seed in SEEDS.iter() {
|
||||||
|
if seed.needles.len() > self.needle_len {
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
for t in seed.generate() {
|
||||||
|
let mut results = match test(t.haystack.as_bytes(), &t.needles)
|
||||||
|
{
|
||||||
|
None => continue,
|
||||||
|
Some(results) => results,
|
||||||
|
};
|
||||||
|
results.reverse();
|
||||||
|
assert_eq!(
|
||||||
|
t.expected,
|
||||||
|
results,
|
||||||
|
"needles: {:?}, haystack: {:?}",
|
||||||
|
t.needles
|
||||||
|
.iter()
|
||||||
|
.map(|&b| b.to_char())
|
||||||
|
.collect::<Vec<char>>(),
|
||||||
|
t.haystack,
|
||||||
|
);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run all tests as counting tests. This panics on the first failure.
|
||||||
|
///
|
||||||
|
/// That is, this only checks that the number of matches is correct and
|
||||||
|
/// not whether the offsets of each match are.
|
||||||
|
pub(crate) fn count_iter<F>(self, mut test: F)
|
||||||
|
where
|
||||||
|
F: FnMut(&[u8], &[u8]) -> Option<usize> + 'static,
|
||||||
|
{
|
||||||
|
for seed in SEEDS.iter() {
|
||||||
|
if seed.needles.len() > self.needle_len {
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
for t in seed.generate() {
|
||||||
|
let got = match test(t.haystack.as_bytes(), &t.needles) {
|
||||||
|
None => continue,
|
||||||
|
Some(got) => got,
|
||||||
|
};
|
||||||
|
assert_eq!(
|
||||||
|
t.expected.len(),
|
||||||
|
got,
|
||||||
|
"needles: {:?}, haystack: {:?}",
|
||||||
|
t.needles
|
||||||
|
.iter()
|
||||||
|
.map(|&b| b.to_char())
|
||||||
|
.collect::<Vec<char>>(),
|
||||||
|
t.haystack,
|
||||||
|
);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Like `Runner::forward`, but for a function that returns only the next
|
||||||
|
/// match and not all matches.
|
||||||
|
///
|
||||||
|
/// If the function returns `None`, then it is skipped.
|
||||||
|
pub(crate) fn forward_oneshot<F>(self, mut test: F)
|
||||||
|
where
|
||||||
|
F: FnMut(&[u8], &[u8]) -> Option<Option<usize>> + 'static,
|
||||||
|
{
|
||||||
|
self.forward_iter(move |haystack, needles| {
|
||||||
|
let mut start = 0;
|
||||||
|
let mut results = vec![];
|
||||||
|
while let Some(i) = test(&haystack[start..], needles)? {
|
||||||
|
results.push(start + i);
|
||||||
|
start += i + 1;
|
||||||
|
}
|
||||||
|
Some(results)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Like `Runner::reverse`, but for a function that returns only the last
|
||||||
|
/// match and not all matches.
|
||||||
|
///
|
||||||
|
/// If the function returns `None`, then it is skipped.
|
||||||
|
pub(crate) fn reverse_oneshot<F>(self, mut test: F)
|
||||||
|
where
|
||||||
|
F: FnMut(&[u8], &[u8]) -> Option<Option<usize>> + 'static,
|
||||||
|
{
|
||||||
|
self.reverse_iter(move |haystack, needles| {
|
||||||
|
let mut end = haystack.len();
|
||||||
|
let mut results = vec![];
|
||||||
|
while let Some(i) = test(&haystack[..end], needles)? {
|
||||||
|
results.push(i);
|
||||||
|
end = i;
|
||||||
|
}
|
||||||
|
Some(results)
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A single test for memr?chr{,2,3}.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
struct Test {
|
||||||
|
/// The string to search in.
|
||||||
|
haystack: String,
|
||||||
|
/// The needles to look for.
|
||||||
|
needles: Vec<u8>,
|
||||||
|
/// The offsets that are expected to be found for all needles in the
|
||||||
|
/// forward direction.
|
||||||
|
expected: Vec<usize>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Test {
|
||||||
|
fn new(seed: &Seed) -> Test {
|
||||||
|
Test {
|
||||||
|
haystack: seed.haystack.to_string(),
|
||||||
|
needles: seed.needles.to_vec(),
|
||||||
|
expected: seed.positions.to_vec(),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Data that can be expanded into many memchr tests by padding out the corpus.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
struct Seed {
|
||||||
|
/// The thing to search. We use `&str` instead of `&[u8]` because they
|
||||||
|
/// are nicer to write in tests, and we don't miss much since memchr
|
||||||
|
/// doesn't care about UTF-8.
|
||||||
|
///
|
||||||
|
/// Corpora cannot contain either '%' or '#'. We use these bytes when
|
||||||
|
/// expanding test cases into many test cases, and we assume they are not
|
||||||
|
/// used. If they are used, `memchr_tests` will panic.
|
||||||
|
haystack: &'static str,
|
||||||
|
/// The needles to search for. This is intended to be an alternation of
|
||||||
|
/// needles. The number of needles may cause this test to be skipped for
|
||||||
|
/// some memchr variants. For example, a test with 2 needles cannot be used
|
||||||
|
/// to test `memchr`, but can be used to test `memchr2` and `memchr3`.
|
||||||
|
/// However, a test with only 1 needle can be used to test all of `memchr`,
|
||||||
|
/// `memchr2` and `memchr3`. We achieve this by filling in the needles with
|
||||||
|
/// bytes that we never used in the corpus (such as '#').
|
||||||
|
needles: &'static [u8],
|
||||||
|
/// The positions expected to match for all of the needles.
|
||||||
|
positions: &'static [usize],
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Seed {
|
||||||
|
/// Controls how much we expand the haystack on either side for each test.
|
||||||
|
/// We lower this on Miri because otherwise running the tests would take
|
||||||
|
/// forever.
|
||||||
|
const EXPAND_LEN: usize = {
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
{
|
||||||
|
515
|
||||||
|
}
|
||||||
|
#[cfg(miri)]
|
||||||
|
{
|
||||||
|
6
|
||||||
|
}
|
||||||
|
};
|
||||||
|
|
||||||
|
/// Expand this test into many variations of the same test.
|
||||||
|
///
|
||||||
|
/// In particular, this will generate more tests with larger corpus sizes.
|
||||||
|
/// The expected positions are updated to maintain the integrity of the
|
||||||
|
/// test.
|
||||||
|
///
|
||||||
|
/// This is important in testing a memchr implementation, because there are
|
||||||
|
/// often different cases depending on the length of the corpus.
|
||||||
|
///
|
||||||
|
/// Note that we extend the corpus by adding `%` bytes, which we
|
||||||
|
/// don't otherwise use as a needle.
|
||||||
|
fn generate(&self) -> impl Iterator<Item = Test> {
|
||||||
|
let mut more = vec![];
|
||||||
|
|
||||||
|
// Add bytes to the start of the corpus.
|
||||||
|
for i in 0..Seed::EXPAND_LEN {
|
||||||
|
let mut t = Test::new(self);
|
||||||
|
let mut new: String = core::iter::repeat('%').take(i).collect();
|
||||||
|
new.push_str(&t.haystack);
|
||||||
|
t.haystack = new;
|
||||||
|
t.expected = t.expected.into_iter().map(|p| p + i).collect();
|
||||||
|
more.push(t);
|
||||||
|
}
|
||||||
|
// Add bytes to the end of the corpus.
|
||||||
|
for i in 1..Seed::EXPAND_LEN {
|
||||||
|
let mut t = Test::new(self);
|
||||||
|
let padding: String = core::iter::repeat('%').take(i).collect();
|
||||||
|
t.haystack.push_str(&padding);
|
||||||
|
more.push(t);
|
||||||
|
}
|
||||||
|
|
||||||
|
more.into_iter()
|
||||||
|
}
|
||||||
|
}
|
||||||
33
third_party/crates/memchr-2.8.3/src/tests/memchr/naive.rs
vendored
Normal file
33
third_party/crates/memchr-2.8.3/src/tests/memchr/naive.rs
vendored
Normal file
@@ -0,0 +1,33 @@
|
|||||||
|
pub(crate) fn memchr(n1: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
haystack.iter().position(|&b| b == n1)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn memchr2(n1: u8, n2: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
haystack.iter().position(|&b| b == n1 || b == n2)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn memchr3(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
haystack.iter().position(|&b| b == n1 || b == n2 || b == n3)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn memrchr(n1: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
haystack.iter().rposition(|&b| b == n1)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn memrchr2(n1: u8, n2: u8, haystack: &[u8]) -> Option<usize> {
|
||||||
|
haystack.iter().rposition(|&b| b == n1 || b == n2)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn memrchr3(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
haystack: &[u8],
|
||||||
|
) -> Option<usize> {
|
||||||
|
haystack.iter().rposition(|&b| b == n1 || b == n2 || b == n3)
|
||||||
|
}
|
||||||
323
third_party/crates/memchr-2.8.3/src/tests/memchr/prop.rs
vendored
Normal file
323
third_party/crates/memchr-2.8.3/src/tests/memchr/prop.rs
vendored
Normal file
@@ -0,0 +1,323 @@
|
|||||||
|
/// Defines a host of quickcheck tests for the given memchr searcher.
|
||||||
|
#[cfg(miri)]
|
||||||
|
#[macro_export]
|
||||||
|
macro_rules! define_memchr_quickcheck {
|
||||||
|
($($tt:tt)*) => {};
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Defines a host of quickcheck tests for the given memchr searcher.
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
#[macro_export]
|
||||||
|
macro_rules! define_memchr_quickcheck {
|
||||||
|
($mod:ident) => {
|
||||||
|
define_memchr_quickcheck!($mod, new);
|
||||||
|
};
|
||||||
|
($mod:ident, $cons:ident) => {
|
||||||
|
use alloc::vec::Vec;
|
||||||
|
|
||||||
|
use quickcheck::TestResult;
|
||||||
|
|
||||||
|
use crate::tests::memchr::{
|
||||||
|
naive,
|
||||||
|
prop::{double_ended_take, naive1_iter, naive2_iter, naive3_iter},
|
||||||
|
};
|
||||||
|
|
||||||
|
quickcheck::quickcheck! {
|
||||||
|
fn qc_memchr_matches_naive(n1: u8, corpus: Vec<u8>) -> TestResult {
|
||||||
|
let expected = naive::memchr(n1, &corpus);
|
||||||
|
let got = match $mod::One::$cons(n1) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(f) => f.find(&corpus),
|
||||||
|
};
|
||||||
|
TestResult::from_bool(expected == got)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memrchr_matches_naive(n1: u8, corpus: Vec<u8>) -> TestResult {
|
||||||
|
let expected = naive::memrchr(n1, &corpus);
|
||||||
|
let got = match $mod::One::$cons(n1) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(f) => f.rfind(&corpus),
|
||||||
|
};
|
||||||
|
TestResult::from_bool(expected == got)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr2_matches_naive(n1: u8, n2: u8, corpus: Vec<u8>) -> TestResult {
|
||||||
|
let expected = naive::memchr2(n1, n2, &corpus);
|
||||||
|
let got = match $mod::Two::$cons(n1, n2) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(f) => f.find(&corpus),
|
||||||
|
};
|
||||||
|
TestResult::from_bool(expected == got)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memrchr2_matches_naive(n1: u8, n2: u8, corpus: Vec<u8>) -> TestResult {
|
||||||
|
let expected = naive::memrchr2(n1, n2, &corpus);
|
||||||
|
let got = match $mod::Two::$cons(n1, n2) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(f) => f.rfind(&corpus),
|
||||||
|
};
|
||||||
|
TestResult::from_bool(expected == got)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr3_matches_naive(
|
||||||
|
n1: u8, n2: u8, n3: u8,
|
||||||
|
corpus: Vec<u8>
|
||||||
|
) -> TestResult {
|
||||||
|
let expected = naive::memchr3(n1, n2, n3, &corpus);
|
||||||
|
let got = match $mod::Three::$cons(n1, n2, n3) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(f) => f.find(&corpus),
|
||||||
|
};
|
||||||
|
TestResult::from_bool(expected == got)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memrchr3_matches_naive(
|
||||||
|
n1: u8, n2: u8, n3: u8,
|
||||||
|
corpus: Vec<u8>
|
||||||
|
) -> TestResult {
|
||||||
|
let expected = naive::memrchr3(n1, n2, n3, &corpus);
|
||||||
|
let got = match $mod::Three::$cons(n1, n2, n3) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(f) => f.rfind(&corpus),
|
||||||
|
};
|
||||||
|
TestResult::from_bool(expected == got)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr_double_ended_iter(
|
||||||
|
needle: u8, data: Vec<u8>, take_side: Vec<bool>
|
||||||
|
) -> TestResult {
|
||||||
|
// make nonempty
|
||||||
|
let mut take_side = take_side;
|
||||||
|
if take_side.is_empty() { take_side.push(true) };
|
||||||
|
|
||||||
|
let finder = match $mod::One::$cons(needle) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let iter = finder.iter(&data);
|
||||||
|
let got = double_ended_take(
|
||||||
|
iter,
|
||||||
|
take_side.iter().cycle().cloned(),
|
||||||
|
);
|
||||||
|
let expected = naive1_iter(needle, &data);
|
||||||
|
|
||||||
|
TestResult::from_bool(got.iter().cloned().eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr2_double_ended_iter(
|
||||||
|
needle1: u8, needle2: u8, data: Vec<u8>, take_side: Vec<bool>
|
||||||
|
) -> TestResult {
|
||||||
|
// make nonempty
|
||||||
|
let mut take_side = take_side;
|
||||||
|
if take_side.is_empty() { take_side.push(true) };
|
||||||
|
|
||||||
|
let finder = match $mod::Two::$cons(needle1, needle2) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let iter = finder.iter(&data);
|
||||||
|
let got = double_ended_take(
|
||||||
|
iter,
|
||||||
|
take_side.iter().cycle().cloned(),
|
||||||
|
);
|
||||||
|
let expected = naive2_iter(needle1, needle2, &data);
|
||||||
|
|
||||||
|
TestResult::from_bool(got.iter().cloned().eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr3_double_ended_iter(
|
||||||
|
needle1: u8, needle2: u8, needle3: u8,
|
||||||
|
data: Vec<u8>, take_side: Vec<bool>
|
||||||
|
) -> TestResult {
|
||||||
|
// make nonempty
|
||||||
|
let mut take_side = take_side;
|
||||||
|
if take_side.is_empty() { take_side.push(true) };
|
||||||
|
|
||||||
|
let finder = match $mod::Three::$cons(needle1, needle2, needle3) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let iter = finder.iter(&data);
|
||||||
|
let got = double_ended_take(
|
||||||
|
iter,
|
||||||
|
take_side.iter().cycle().cloned(),
|
||||||
|
);
|
||||||
|
let expected = naive3_iter(needle1, needle2, needle3, &data);
|
||||||
|
|
||||||
|
TestResult::from_bool(got.iter().cloned().eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr1_iter(data: Vec<u8>) -> TestResult {
|
||||||
|
let needle = 0;
|
||||||
|
let finder = match $mod::One::$cons(needle) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let got = finder.iter(&data);
|
||||||
|
let expected = naive1_iter(needle, &data);
|
||||||
|
TestResult::from_bool(got.eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr1_rev_iter(data: Vec<u8>) -> TestResult {
|
||||||
|
let needle = 0;
|
||||||
|
|
||||||
|
let finder = match $mod::One::$cons(needle) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let got = finder.iter(&data).rev();
|
||||||
|
let expected = naive1_iter(needle, &data).rev();
|
||||||
|
TestResult::from_bool(got.eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr2_iter(data: Vec<u8>) -> TestResult {
|
||||||
|
let needle1 = 0;
|
||||||
|
let needle2 = 1;
|
||||||
|
|
||||||
|
let finder = match $mod::Two::$cons(needle1, needle2) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let got = finder.iter(&data);
|
||||||
|
let expected = naive2_iter(needle1, needle2, &data);
|
||||||
|
TestResult::from_bool(got.eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr2_rev_iter(data: Vec<u8>) -> TestResult {
|
||||||
|
let needle1 = 0;
|
||||||
|
let needle2 = 1;
|
||||||
|
|
||||||
|
let finder = match $mod::Two::$cons(needle1, needle2) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let got = finder.iter(&data).rev();
|
||||||
|
let expected = naive2_iter(needle1, needle2, &data).rev();
|
||||||
|
TestResult::from_bool(got.eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr3_iter(data: Vec<u8>) -> TestResult {
|
||||||
|
let needle1 = 0;
|
||||||
|
let needle2 = 1;
|
||||||
|
let needle3 = 2;
|
||||||
|
|
||||||
|
let finder = match $mod::Three::$cons(needle1, needle2, needle3) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let got = finder.iter(&data);
|
||||||
|
let expected = naive3_iter(needle1, needle2, needle3, &data);
|
||||||
|
TestResult::from_bool(got.eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr3_rev_iter(data: Vec<u8>) -> TestResult {
|
||||||
|
let needle1 = 0;
|
||||||
|
let needle2 = 1;
|
||||||
|
let needle3 = 2;
|
||||||
|
|
||||||
|
let finder = match $mod::Three::$cons(needle1, needle2, needle3) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let got = finder.iter(&data).rev();
|
||||||
|
let expected = naive3_iter(needle1, needle2, needle3, &data).rev();
|
||||||
|
TestResult::from_bool(got.eq(expected))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_memchr1_iter_size_hint(data: Vec<u8>) -> TestResult {
|
||||||
|
// test that the size hint is within reasonable bounds
|
||||||
|
let needle = 0;
|
||||||
|
let finder = match $mod::One::$cons(needle) {
|
||||||
|
None => return TestResult::discard(),
|
||||||
|
Some(finder) => finder,
|
||||||
|
};
|
||||||
|
let mut iter = finder.iter(&data);
|
||||||
|
let mut real_count = data
|
||||||
|
.iter()
|
||||||
|
.filter(|&&elt| elt == needle)
|
||||||
|
.count();
|
||||||
|
|
||||||
|
while let Some(index) = iter.next() {
|
||||||
|
real_count -= 1;
|
||||||
|
let (lower, upper) = iter.size_hint();
|
||||||
|
assert!(lower <= real_count);
|
||||||
|
assert!(upper.unwrap() >= real_count);
|
||||||
|
assert!(upper.unwrap() <= data.len() - index);
|
||||||
|
}
|
||||||
|
TestResult::passed()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
// take items from a DEI, taking front for each true and back for each false.
|
||||||
|
// Return a vector with the concatenation of the fronts and the reverse of the
|
||||||
|
// backs.
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
pub(crate) fn double_ended_take<I, J>(
|
||||||
|
mut iter: I,
|
||||||
|
take_side: J,
|
||||||
|
) -> alloc::vec::Vec<I::Item>
|
||||||
|
where
|
||||||
|
I: DoubleEndedIterator,
|
||||||
|
J: Iterator<Item = bool>,
|
||||||
|
{
|
||||||
|
let mut found_front = alloc::vec![];
|
||||||
|
let mut found_back = alloc::vec![];
|
||||||
|
|
||||||
|
for take_front in take_side {
|
||||||
|
if take_front {
|
||||||
|
if let Some(pos) = iter.next() {
|
||||||
|
found_front.push(pos);
|
||||||
|
} else {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
if let Some(pos) = iter.next_back() {
|
||||||
|
found_back.push(pos);
|
||||||
|
} else {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
let mut all_found = found_front;
|
||||||
|
all_found.extend(found_back.into_iter().rev());
|
||||||
|
all_found
|
||||||
|
}
|
||||||
|
|
||||||
|
// return an iterator of the 0-based indices of haystack that match the needle
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
pub(crate) fn naive1_iter<'a>(
|
||||||
|
n1: u8,
|
||||||
|
haystack: &'a [u8],
|
||||||
|
) -> impl DoubleEndedIterator<Item = usize> + 'a {
|
||||||
|
haystack.iter().enumerate().filter(move |&(_, &b)| b == n1).map(|t| t.0)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
pub(crate) fn naive2_iter<'a>(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
haystack: &'a [u8],
|
||||||
|
) -> impl DoubleEndedIterator<Item = usize> + 'a {
|
||||||
|
haystack
|
||||||
|
.iter()
|
||||||
|
.enumerate()
|
||||||
|
.filter(move |&(_, &b)| b == n1 || b == n2)
|
||||||
|
.map(|t| t.0)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
pub(crate) fn naive3_iter<'a>(
|
||||||
|
n1: u8,
|
||||||
|
n2: u8,
|
||||||
|
n3: u8,
|
||||||
|
haystack: &'a [u8],
|
||||||
|
) -> impl DoubleEndedIterator<Item = usize> + 'a {
|
||||||
|
haystack
|
||||||
|
.iter()
|
||||||
|
.enumerate()
|
||||||
|
.filter(move |&(_, &b)| b == n1 || b == n2 || b == n3)
|
||||||
|
.map(|t| t.0)
|
||||||
|
}
|
||||||
15
third_party/crates/memchr-2.8.3/src/tests/mod.rs
vendored
Normal file
15
third_party/crates/memchr-2.8.3/src/tests/mod.rs
vendored
Normal file
@@ -0,0 +1,15 @@
|
|||||||
|
#[macro_use]
|
||||||
|
pub(crate) mod memchr;
|
||||||
|
pub(crate) mod packedpair;
|
||||||
|
#[macro_use]
|
||||||
|
pub(crate) mod substring;
|
||||||
|
|
||||||
|
// For debugging, particularly in CI, print out the byte order of the current
|
||||||
|
// target.
|
||||||
|
#[test]
|
||||||
|
fn byte_order() {
|
||||||
|
#[cfg(target_endian = "little")]
|
||||||
|
std::eprintln!("LITTLE ENDIAN");
|
||||||
|
#[cfg(target_endian = "big")]
|
||||||
|
std::eprintln!("BIG ENDIAN");
|
||||||
|
}
|
||||||
216
third_party/crates/memchr-2.8.3/src/tests/packedpair.rs
vendored
Normal file
216
third_party/crates/memchr-2.8.3/src/tests/packedpair.rs
vendored
Normal file
@@ -0,0 +1,216 @@
|
|||||||
|
use alloc::{boxed::Box, vec, vec::Vec};
|
||||||
|
|
||||||
|
/// A set of "packed pair" test seeds. Each seed serves as the base for the
|
||||||
|
/// generation of many other tests. In essence, the seed captures the pair of
|
||||||
|
/// bytes we used for a predicate and first byte among our needle. The tests
|
||||||
|
/// generated from each seed essentially vary the length of the needle and
|
||||||
|
/// haystack, while using the rare/first byte configuration from the seed.
|
||||||
|
///
|
||||||
|
/// The purpose of this is to test many different needle/haystack lengths.
|
||||||
|
/// In particular, some of the vector optimizations might only have bugs
|
||||||
|
/// in haystacks of a certain size.
|
||||||
|
const SEEDS: &[Seed] = &[
|
||||||
|
// Why not use different 'first' bytes? It seemed like a good idea to be
|
||||||
|
// able to configure it, but when I wrote the test generator below, it
|
||||||
|
// didn't seem necessary to use for reasons that I forget.
|
||||||
|
Seed { first: b'x', index1: b'y', index2: b'z' },
|
||||||
|
Seed { first: b'x', index1: b'x', index2: b'z' },
|
||||||
|
Seed { first: b'x', index1: b'y', index2: b'x' },
|
||||||
|
Seed { first: b'x', index1: b'x', index2: b'x' },
|
||||||
|
Seed { first: b'x', index1: b'y', index2: b'y' },
|
||||||
|
];
|
||||||
|
|
||||||
|
/// Runs a host of "packed pair" search tests.
|
||||||
|
///
|
||||||
|
/// These tests specifically look for the occurrence of a possible substring
|
||||||
|
/// match based on a pair of bytes matching at the right offsets.
|
||||||
|
pub(crate) struct Runner {
|
||||||
|
fwd: Option<
|
||||||
|
Box<
|
||||||
|
dyn FnMut(&[u8], &[u8], u8, u8) -> Option<Option<usize>> + 'static,
|
||||||
|
>,
|
||||||
|
>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Runner {
|
||||||
|
/// Create a new test runner for "packed pair" substring search.
|
||||||
|
pub(crate) fn new() -> Runner {
|
||||||
|
Runner { fwd: None }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run all tests. This panics on the first failure.
|
||||||
|
///
|
||||||
|
/// If the implementation being tested returns `None` for a particular
|
||||||
|
/// haystack/needle combination, then that test is skipped.
|
||||||
|
///
|
||||||
|
/// This runs tests on both the forward and reverse implementations given.
|
||||||
|
/// If either (or both) are missing, then tests for that implementation are
|
||||||
|
/// skipped.
|
||||||
|
pub(crate) fn run(self) {
|
||||||
|
if let Some(mut fwd) = self.fwd {
|
||||||
|
for seed in SEEDS.iter() {
|
||||||
|
for t in seed.generate() {
|
||||||
|
match fwd(&t.haystack, &t.needle, t.index1, t.index2) {
|
||||||
|
None => continue,
|
||||||
|
Some(result) => {
|
||||||
|
assert_eq!(
|
||||||
|
t.fwd, result,
|
||||||
|
"FORWARD, needle: {:?}, haystack: {:?}, \
|
||||||
|
index1: {:?}, index2: {:?}",
|
||||||
|
t.needle, t.haystack, t.index1, t.index2,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Set the implementation for forward "packed pair" substring search.
|
||||||
|
///
|
||||||
|
/// If the closure returns `None`, then it is assumed that the given
|
||||||
|
/// test cannot be applied to the particular implementation and it is
|
||||||
|
/// skipped. For example, if a particular implementation only supports
|
||||||
|
/// needles or haystacks for some minimum length.
|
||||||
|
///
|
||||||
|
/// If this is not set, then forward "packed pair" search is not tested.
|
||||||
|
pub(crate) fn fwd(
|
||||||
|
mut self,
|
||||||
|
search: impl FnMut(&[u8], &[u8], u8, u8) -> Option<Option<usize>> + 'static,
|
||||||
|
) -> Runner {
|
||||||
|
self.fwd = Some(Box::new(search));
|
||||||
|
self
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A test that represents the input and expected output to a "packed pair"
|
||||||
|
/// search function. The test should be able to run with any "packed pair"
|
||||||
|
/// implementation and get the expected output.
|
||||||
|
struct Test {
|
||||||
|
haystack: Vec<u8>,
|
||||||
|
needle: Vec<u8>,
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
fwd: Option<usize>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Test {
|
||||||
|
/// Create a new "packed pair" test from a seed and some given offsets to
|
||||||
|
/// the pair of bytes to use as a predicate in the seed's needle.
|
||||||
|
///
|
||||||
|
/// If a valid test could not be constructed, then None is returned.
|
||||||
|
/// (Currently, we take the approach of massaging tests to be valid
|
||||||
|
/// instead of rejecting them outright.)
|
||||||
|
fn new(
|
||||||
|
seed: Seed,
|
||||||
|
index1: usize,
|
||||||
|
index2: usize,
|
||||||
|
haystack_len: usize,
|
||||||
|
needle_len: usize,
|
||||||
|
fwd: Option<usize>,
|
||||||
|
) -> Option<Test> {
|
||||||
|
let mut index1: u8 = index1.try_into().unwrap();
|
||||||
|
let mut index2: u8 = index2.try_into().unwrap();
|
||||||
|
// The '#' byte is never used in a haystack (unless we're expecting
|
||||||
|
// a match), while the '@' byte is never used in a needle.
|
||||||
|
let mut haystack = vec![b'@'; haystack_len];
|
||||||
|
let mut needle = vec![b'#'; needle_len];
|
||||||
|
needle[0] = seed.first;
|
||||||
|
needle[index1 as usize] = seed.index1;
|
||||||
|
needle[index2 as usize] = seed.index2;
|
||||||
|
// If we're expecting a match, then make sure the needle occurs
|
||||||
|
// in the haystack at the expected position.
|
||||||
|
if let Some(i) = fwd {
|
||||||
|
haystack[i..i + needle.len()].copy_from_slice(&needle);
|
||||||
|
}
|
||||||
|
// If the operations above lead to rare offsets pointing to the
|
||||||
|
// non-first occurrence of a byte, then adjust it. This might lead
|
||||||
|
// to redundant tests, but it's simpler than trying to change the
|
||||||
|
// generation process I think.
|
||||||
|
if let Some(i) = crate::memchr(seed.index1, &needle) {
|
||||||
|
index1 = u8::try_from(i).unwrap();
|
||||||
|
}
|
||||||
|
if let Some(i) = crate::memchr(seed.index2, &needle) {
|
||||||
|
index2 = u8::try_from(i).unwrap();
|
||||||
|
}
|
||||||
|
Some(Test { haystack, needle, index1, index2, fwd })
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Data that describes a single prefilter test seed.
|
||||||
|
#[derive(Clone, Copy)]
|
||||||
|
struct Seed {
|
||||||
|
first: u8,
|
||||||
|
index1: u8,
|
||||||
|
index2: u8,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Seed {
|
||||||
|
const NEEDLE_LENGTH_LIMIT: usize = {
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
{
|
||||||
|
33
|
||||||
|
}
|
||||||
|
#[cfg(miri)]
|
||||||
|
{
|
||||||
|
5
|
||||||
|
}
|
||||||
|
};
|
||||||
|
|
||||||
|
const HAYSTACK_LENGTH_LIMIT: usize = {
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
{
|
||||||
|
65
|
||||||
|
}
|
||||||
|
#[cfg(miri)]
|
||||||
|
{
|
||||||
|
8
|
||||||
|
}
|
||||||
|
};
|
||||||
|
|
||||||
|
/// Generate a series of prefilter tests from this seed.
|
||||||
|
fn generate(self) -> impl Iterator<Item = Test> {
|
||||||
|
let len_start = 2;
|
||||||
|
// The iterator below generates *a lot* of tests. The number of
|
||||||
|
// tests was chosen somewhat empirically to be "bearable" when
|
||||||
|
// running the test suite.
|
||||||
|
//
|
||||||
|
// We use an iterator here because the collective haystacks of all
|
||||||
|
// these test cases add up to enough memory to OOM a conservative
|
||||||
|
// sandbox or a small laptop.
|
||||||
|
(len_start..=Seed::NEEDLE_LENGTH_LIMIT).flat_map(move |needle_len| {
|
||||||
|
let index_start = len_start - 1;
|
||||||
|
(index_start..needle_len).flat_map(move |index1| {
|
||||||
|
(index1..needle_len).flat_map(move |index2| {
|
||||||
|
(needle_len..=Seed::HAYSTACK_LENGTH_LIMIT).flat_map(
|
||||||
|
move |haystack_len| {
|
||||||
|
Test::new(
|
||||||
|
self,
|
||||||
|
index1,
|
||||||
|
index2,
|
||||||
|
haystack_len,
|
||||||
|
needle_len,
|
||||||
|
None,
|
||||||
|
)
|
||||||
|
.into_iter()
|
||||||
|
.chain(
|
||||||
|
(0..=(haystack_len - needle_len)).flat_map(
|
||||||
|
move |output| {
|
||||||
|
Test::new(
|
||||||
|
self,
|
||||||
|
index1,
|
||||||
|
index2,
|
||||||
|
haystack_len,
|
||||||
|
needle_len,
|
||||||
|
Some(output),
|
||||||
|
)
|
||||||
|
},
|
||||||
|
),
|
||||||
|
)
|
||||||
|
},
|
||||||
|
)
|
||||||
|
})
|
||||||
|
})
|
||||||
|
})
|
||||||
|
}
|
||||||
|
}
|
||||||
232
third_party/crates/memchr-2.8.3/src/tests/substring/mod.rs
vendored
Normal file
232
third_party/crates/memchr-2.8.3/src/tests/substring/mod.rs
vendored
Normal file
@@ -0,0 +1,232 @@
|
|||||||
|
/*!
|
||||||
|
This module defines tests and test helpers for substring implementations.
|
||||||
|
*/
|
||||||
|
|
||||||
|
use alloc::{
|
||||||
|
boxed::Box,
|
||||||
|
format,
|
||||||
|
string::{String, ToString},
|
||||||
|
};
|
||||||
|
|
||||||
|
pub(crate) mod naive;
|
||||||
|
#[macro_use]
|
||||||
|
pub(crate) mod prop;
|
||||||
|
|
||||||
|
const SEEDS: &'static [Seed] = &[
|
||||||
|
Seed::new("", "", Some(0), Some(0)),
|
||||||
|
Seed::new("", "a", Some(0), Some(1)),
|
||||||
|
Seed::new("", "ab", Some(0), Some(2)),
|
||||||
|
Seed::new("", "abc", Some(0), Some(3)),
|
||||||
|
Seed::new("a", "", None, None),
|
||||||
|
Seed::new("a", "a", Some(0), Some(0)),
|
||||||
|
Seed::new("a", "aa", Some(0), Some(1)),
|
||||||
|
Seed::new("a", "ba", Some(1), Some(1)),
|
||||||
|
Seed::new("a", "bba", Some(2), Some(2)),
|
||||||
|
Seed::new("a", "bbba", Some(3), Some(3)),
|
||||||
|
Seed::new("a", "bbbab", Some(3), Some(3)),
|
||||||
|
Seed::new("a", "bbbabb", Some(3), Some(3)),
|
||||||
|
Seed::new("a", "bbbabbb", Some(3), Some(3)),
|
||||||
|
Seed::new("a", "bbbbbb", None, None),
|
||||||
|
Seed::new("ab", "", None, None),
|
||||||
|
Seed::new("ab", "a", None, None),
|
||||||
|
Seed::new("ab", "b", None, None),
|
||||||
|
Seed::new("ab", "ab", Some(0), Some(0)),
|
||||||
|
Seed::new("ab", "aab", Some(1), Some(1)),
|
||||||
|
Seed::new("ab", "aaab", Some(2), Some(2)),
|
||||||
|
Seed::new("ab", "abaab", Some(0), Some(3)),
|
||||||
|
Seed::new("ab", "baaab", Some(3), Some(3)),
|
||||||
|
Seed::new("ab", "acb", None, None),
|
||||||
|
Seed::new("ab", "abba", Some(0), Some(0)),
|
||||||
|
Seed::new("abc", "ab", None, None),
|
||||||
|
Seed::new("abc", "abc", Some(0), Some(0)),
|
||||||
|
Seed::new("abc", "abcz", Some(0), Some(0)),
|
||||||
|
Seed::new("abc", "abczz", Some(0), Some(0)),
|
||||||
|
Seed::new("abc", "zabc", Some(1), Some(1)),
|
||||||
|
Seed::new("abc", "zzabc", Some(2), Some(2)),
|
||||||
|
Seed::new("abc", "azbc", None, None),
|
||||||
|
Seed::new("abc", "abzc", None, None),
|
||||||
|
Seed::new("abczdef", "abczdefzzzzzzzzzzzzzzzzzzzz", Some(0), Some(0)),
|
||||||
|
Seed::new("abczdef", "zzzzzzzzzzzzzzzzzzzzabczdef", Some(20), Some(20)),
|
||||||
|
Seed::new(
|
||||||
|
"xyz",
|
||||||
|
"aaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaxyz",
|
||||||
|
Some(32),
|
||||||
|
Some(32),
|
||||||
|
),
|
||||||
|
Seed::new("\u{0}\u{15}", "\u{0}\u{15}\u{15}\u{0}", Some(0), Some(0)),
|
||||||
|
Seed::new("\u{0}\u{1e}", "\u{1e}\u{0}", None, None),
|
||||||
|
];
|
||||||
|
|
||||||
|
/// Runs a host of substring search tests.
|
||||||
|
///
|
||||||
|
/// This has support for "partial" substring search implementations only work
|
||||||
|
/// for a subset of needles/haystacks. For example, the "packed pair" substring
|
||||||
|
/// search implementation only works for haystacks of some minimum length based
|
||||||
|
/// of the pair of bytes selected and the size of the vector used.
|
||||||
|
pub(crate) struct Runner {
|
||||||
|
fwd: Option<
|
||||||
|
Box<dyn FnMut(&[u8], &[u8]) -> Option<Option<usize>> + 'static>,
|
||||||
|
>,
|
||||||
|
rev: Option<
|
||||||
|
Box<dyn FnMut(&[u8], &[u8]) -> Option<Option<usize>> + 'static>,
|
||||||
|
>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Runner {
|
||||||
|
/// Create a new test runner for forward and reverse substring search
|
||||||
|
/// implementations.
|
||||||
|
pub(crate) fn new() -> Runner {
|
||||||
|
Runner { fwd: None, rev: None }
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Run all tests. This panics on the first failure.
|
||||||
|
///
|
||||||
|
/// If the implementation being tested returns `None` for a particular
|
||||||
|
/// haystack/needle combination, then that test is skipped.
|
||||||
|
///
|
||||||
|
/// This runs tests on both the forward and reverse implementations given.
|
||||||
|
/// If either (or both) are missing, then tests for that implementation are
|
||||||
|
/// skipped.
|
||||||
|
pub(crate) fn run(self) {
|
||||||
|
if let Some(mut fwd) = self.fwd {
|
||||||
|
for seed in SEEDS.iter() {
|
||||||
|
for t in seed.generate() {
|
||||||
|
match fwd(t.haystack.as_bytes(), t.needle.as_bytes()) {
|
||||||
|
None => continue,
|
||||||
|
Some(result) => {
|
||||||
|
assert_eq!(
|
||||||
|
t.fwd, result,
|
||||||
|
"FORWARD, needle: {:?}, haystack: {:?}",
|
||||||
|
t.needle, t.haystack,
|
||||||
|
);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
if let Some(mut rev) = self.rev {
|
||||||
|
for seed in SEEDS.iter() {
|
||||||
|
for t in seed.generate() {
|
||||||
|
match rev(t.haystack.as_bytes(), t.needle.as_bytes()) {
|
||||||
|
None => continue,
|
||||||
|
Some(result) => {
|
||||||
|
assert_eq!(
|
||||||
|
t.rev, result,
|
||||||
|
"REVERSE, needle: {:?}, haystack: {:?}",
|
||||||
|
t.needle, t.haystack,
|
||||||
|
);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Set the implementation for forward substring search.
|
||||||
|
///
|
||||||
|
/// If the closure returns `None`, then it is assumed that the given
|
||||||
|
/// test cannot be applied to the particular implementation and it is
|
||||||
|
/// skipped. For example, if a particular implementation only supports
|
||||||
|
/// needles or haystacks for some minimum length.
|
||||||
|
///
|
||||||
|
/// If this is not set, then forward substring search is not tested.
|
||||||
|
pub(crate) fn fwd(
|
||||||
|
mut self,
|
||||||
|
search: impl FnMut(&[u8], &[u8]) -> Option<Option<usize>> + 'static,
|
||||||
|
) -> Runner {
|
||||||
|
self.fwd = Some(Box::new(search));
|
||||||
|
self
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Set the implementation for reverse substring search.
|
||||||
|
///
|
||||||
|
/// If the closure returns `None`, then it is assumed that the given
|
||||||
|
/// test cannot be applied to the particular implementation and it is
|
||||||
|
/// skipped. For example, if a particular implementation only supports
|
||||||
|
/// needles or haystacks for some minimum length.
|
||||||
|
///
|
||||||
|
/// If this is not set, then reverse substring search is not tested.
|
||||||
|
pub(crate) fn rev(
|
||||||
|
mut self,
|
||||||
|
search: impl FnMut(&[u8], &[u8]) -> Option<Option<usize>> + 'static,
|
||||||
|
) -> Runner {
|
||||||
|
self.rev = Some(Box::new(search));
|
||||||
|
self
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A single substring test for forward and reverse searches.
|
||||||
|
#[derive(Clone, Debug)]
|
||||||
|
struct Test {
|
||||||
|
needle: String,
|
||||||
|
haystack: String,
|
||||||
|
fwd: Option<usize>,
|
||||||
|
rev: Option<usize>,
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A single substring test for forward and reverse searches.
|
||||||
|
///
|
||||||
|
/// Each seed is valid on its own, but it also serves as a starting point
|
||||||
|
/// to generate more tests. Namely, we pad out the haystacks with other
|
||||||
|
/// characters so that we get more complete coverage. This is especially useful
|
||||||
|
/// for testing vector algorithms that tend to have weird special cases for
|
||||||
|
/// alignment and loop unrolling.
|
||||||
|
///
|
||||||
|
/// Padding works by assuming certain characters never otherwise appear in a
|
||||||
|
/// needle or a haystack. Neither should contain a `#` character.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
struct Seed {
|
||||||
|
needle: &'static str,
|
||||||
|
haystack: &'static str,
|
||||||
|
fwd: Option<usize>,
|
||||||
|
rev: Option<usize>,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Seed {
|
||||||
|
const MAX_PAD: usize = 34;
|
||||||
|
|
||||||
|
const fn new(
|
||||||
|
needle: &'static str,
|
||||||
|
haystack: &'static str,
|
||||||
|
fwd: Option<usize>,
|
||||||
|
rev: Option<usize>,
|
||||||
|
) -> Seed {
|
||||||
|
Seed { needle, haystack, fwd, rev }
|
||||||
|
}
|
||||||
|
|
||||||
|
fn generate(self) -> impl Iterator<Item = Test> {
|
||||||
|
assert!(!self.needle.contains('#'), "needle must not contain '#'");
|
||||||
|
assert!(!self.haystack.contains('#'), "haystack must not contain '#'");
|
||||||
|
(0..=Seed::MAX_PAD)
|
||||||
|
// Generate tests for padding at the beginning of haystack.
|
||||||
|
.map(move |pad| {
|
||||||
|
let needle = self.needle.to_string();
|
||||||
|
let prefix = "#".repeat(pad);
|
||||||
|
let haystack = format!("{}{}", prefix, self.haystack);
|
||||||
|
let fwd = if needle.is_empty() {
|
||||||
|
Some(0)
|
||||||
|
} else {
|
||||||
|
self.fwd.map(|i| pad + i)
|
||||||
|
};
|
||||||
|
let rev = if needle.is_empty() {
|
||||||
|
Some(haystack.len())
|
||||||
|
} else {
|
||||||
|
self.rev.map(|i| pad + i)
|
||||||
|
};
|
||||||
|
Test { needle, haystack, fwd, rev }
|
||||||
|
})
|
||||||
|
// Generate tests for padding at the end of haystack.
|
||||||
|
.chain((1..=Seed::MAX_PAD).map(move |pad| {
|
||||||
|
let needle = self.needle.to_string();
|
||||||
|
let suffix = "#".repeat(pad);
|
||||||
|
let haystack = format!("{}{}", self.haystack, suffix);
|
||||||
|
let fwd = if needle.is_empty() { Some(0) } else { self.fwd };
|
||||||
|
let rev = if needle.is_empty() {
|
||||||
|
Some(haystack.len())
|
||||||
|
} else {
|
||||||
|
self.rev
|
||||||
|
};
|
||||||
|
Test { needle, haystack, fwd, rev }
|
||||||
|
}))
|
||||||
|
}
|
||||||
|
}
|
||||||
45
third_party/crates/memchr-2.8.3/src/tests/substring/naive.rs
vendored
Normal file
45
third_party/crates/memchr-2.8.3/src/tests/substring/naive.rs
vendored
Normal file
@@ -0,0 +1,45 @@
|
|||||||
|
/*!
|
||||||
|
This module defines "naive" implementations of substring search.
|
||||||
|
|
||||||
|
These are sometimes useful to compare with "real" substring implementations.
|
||||||
|
The idea is that they are so simple that they are unlikely to be incorrect.
|
||||||
|
*/
|
||||||
|
|
||||||
|
/// Naively search forwards for the given needle in the given haystack.
|
||||||
|
pub(crate) fn find(haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
let end = haystack.len().checked_sub(needle.len()).map_or(0, |i| i + 1);
|
||||||
|
for i in 0..end {
|
||||||
|
if needle == &haystack[i..i + needle.len()] {
|
||||||
|
return Some(i);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Naively search in reverse for the given needle in the given haystack.
|
||||||
|
pub(crate) fn rfind(haystack: &[u8], needle: &[u8]) -> Option<usize> {
|
||||||
|
let end = haystack.len().checked_sub(needle.len()).map_or(0, |i| i + 1);
|
||||||
|
for i in (0..end).rev() {
|
||||||
|
if needle == &haystack[i..i + needle.len()] {
|
||||||
|
return Some(i);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
None
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(test)]
|
||||||
|
mod tests {
|
||||||
|
use crate::tests::substring;
|
||||||
|
|
||||||
|
use super::*;
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn forward() {
|
||||||
|
substring::Runner::new().fwd(|h, n| Some(find(h, n))).run()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[test]
|
||||||
|
fn reverse() {
|
||||||
|
substring::Runner::new().rev(|h, n| Some(rfind(h, n))).run()
|
||||||
|
}
|
||||||
|
}
|
||||||
126
third_party/crates/memchr-2.8.3/src/tests/substring/prop.rs
vendored
Normal file
126
third_party/crates/memchr-2.8.3/src/tests/substring/prop.rs
vendored
Normal file
@@ -0,0 +1,126 @@
|
|||||||
|
/*!
|
||||||
|
This module defines a few quickcheck properties for substring search.
|
||||||
|
|
||||||
|
It also provides a forward and reverse macro for conveniently defining
|
||||||
|
quickcheck tests that run these properties over any substring search
|
||||||
|
implementation.
|
||||||
|
*/
|
||||||
|
|
||||||
|
use crate::tests::substring::naive;
|
||||||
|
|
||||||
|
/// $fwd is a `impl FnMut(haystack, needle) -> Option<Option<usize>>`. When the
|
||||||
|
/// routine returns `None`, then it's skipped, which is useful for substring
|
||||||
|
/// implementations that don't work for all inputs.
|
||||||
|
#[macro_export]
|
||||||
|
macro_rules! define_substring_forward_quickcheck {
|
||||||
|
($fwd:expr) => {
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
quickcheck::quickcheck! {
|
||||||
|
fn qc_fwd_prefix_is_substring(bs: alloc::vec::Vec<u8>) -> bool {
|
||||||
|
crate::tests::substring::prop::prefix_is_substring(&bs, $fwd)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_fwd_suffix_is_substring(bs: alloc::vec::Vec<u8>) -> bool {
|
||||||
|
crate::tests::substring::prop::suffix_is_substring(&bs, $fwd)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_fwd_matches_naive(
|
||||||
|
haystack: alloc::vec::Vec<u8>,
|
||||||
|
needle: alloc::vec::Vec<u8>
|
||||||
|
) -> bool {
|
||||||
|
crate::tests::substring::prop::same_as_naive(
|
||||||
|
false,
|
||||||
|
&haystack,
|
||||||
|
&needle,
|
||||||
|
$fwd,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
/// $rev is a `impl FnMut(haystack, needle) -> Option<Option<usize>>`. When the
|
||||||
|
/// routine returns `None`, then it's skipped, which is useful for substring
|
||||||
|
/// implementations that don't work for all inputs.
|
||||||
|
#[macro_export]
|
||||||
|
macro_rules! define_substring_reverse_quickcheck {
|
||||||
|
($rev:expr) => {
|
||||||
|
#[cfg(not(miri))]
|
||||||
|
quickcheck::quickcheck! {
|
||||||
|
fn qc_rev_prefix_is_substring(bs: alloc::vec::Vec<u8>) -> bool {
|
||||||
|
crate::tests::substring::prop::prefix_is_substring(&bs, $rev)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_rev_suffix_is_substring(bs: alloc::vec::Vec<u8>) -> bool {
|
||||||
|
crate::tests::substring::prop::suffix_is_substring(&bs, $rev)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn qc_rev_matches_naive(
|
||||||
|
haystack: alloc::vec::Vec<u8>,
|
||||||
|
needle: alloc::vec::Vec<u8>
|
||||||
|
) -> bool {
|
||||||
|
crate::tests::substring::prop::same_as_naive(
|
||||||
|
true,
|
||||||
|
&haystack,
|
||||||
|
&needle,
|
||||||
|
$rev,
|
||||||
|
)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Check that every prefix of the given byte string is a substring.
|
||||||
|
pub(crate) fn prefix_is_substring(
|
||||||
|
bs: &[u8],
|
||||||
|
mut search: impl FnMut(&[u8], &[u8]) -> Option<Option<usize>>,
|
||||||
|
) -> bool {
|
||||||
|
for i in 0..bs.len().saturating_sub(1) {
|
||||||
|
let prefix = &bs[..i];
|
||||||
|
let result = match search(bs, prefix) {
|
||||||
|
None => continue,
|
||||||
|
Some(result) => result,
|
||||||
|
};
|
||||||
|
if !result.is_some() {
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
true
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Check that every suffix of the given byte string is a substring.
|
||||||
|
pub(crate) fn suffix_is_substring(
|
||||||
|
bs: &[u8],
|
||||||
|
mut search: impl FnMut(&[u8], &[u8]) -> Option<Option<usize>>,
|
||||||
|
) -> bool {
|
||||||
|
for i in 0..bs.len().saturating_sub(1) {
|
||||||
|
let suffix = &bs[i..];
|
||||||
|
let result = match search(bs, suffix) {
|
||||||
|
None => continue,
|
||||||
|
Some(result) => result,
|
||||||
|
};
|
||||||
|
if !result.is_some() {
|
||||||
|
return false;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
true
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Check that naive substring search matches the result of the given search
|
||||||
|
/// algorithm.
|
||||||
|
pub(crate) fn same_as_naive(
|
||||||
|
reverse: bool,
|
||||||
|
haystack: &[u8],
|
||||||
|
needle: &[u8],
|
||||||
|
mut search: impl FnMut(&[u8], &[u8]) -> Option<Option<usize>>,
|
||||||
|
) -> bool {
|
||||||
|
let result = match search(haystack, needle) {
|
||||||
|
None => return true,
|
||||||
|
Some(result) => result,
|
||||||
|
};
|
||||||
|
if reverse {
|
||||||
|
result == naive::rfind(haystack, needle)
|
||||||
|
} else {
|
||||||
|
result == naive::find(haystack, needle)
|
||||||
|
}
|
||||||
|
}
|
||||||
514
third_party/crates/memchr-2.8.3/src/vector.rs
vendored
Normal file
514
third_party/crates/memchr-2.8.3/src/vector.rs
vendored
Normal file
@@ -0,0 +1,514 @@
|
|||||||
|
/// A trait for describing vector operations used by vectorized searchers.
|
||||||
|
///
|
||||||
|
/// The trait is highly constrained to low level vector operations needed.
|
||||||
|
/// In general, it was invented mostly to be generic over x86's __m128i and
|
||||||
|
/// __m256i types. At time of writing, it also supports wasm and aarch64
|
||||||
|
/// 128-bit vector types as well.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// All methods are not safe since they are intended to be implemented using
|
||||||
|
/// vendor intrinsics, which are also not safe. Callers must ensure that the
|
||||||
|
/// appropriate target features are enabled in the calling function, and that
|
||||||
|
/// the current CPU supports them. All implementations should avoid marking the
|
||||||
|
/// routines with #[target_feature] and instead mark them as #[inline(always)]
|
||||||
|
/// to ensure they get appropriately inlined. (inline(always) cannot be used
|
||||||
|
/// with target_feature.)
|
||||||
|
pub(crate) trait Vector: Copy + core::fmt::Debug {
|
||||||
|
/// The number of bytes in the vector. That is, this is the size of the
|
||||||
|
/// vector in memory.
|
||||||
|
const BYTES: usize;
|
||||||
|
/// The bits that must be zero in order for a `*const u8` pointer to be
|
||||||
|
/// correctly aligned to read vector values.
|
||||||
|
const ALIGN: usize;
|
||||||
|
|
||||||
|
/// The type of the value returned by `Vector::movemask`.
|
||||||
|
///
|
||||||
|
/// This supports abstracting over the specific representation used in
|
||||||
|
/// order to accommodate different representations in different ISAs.
|
||||||
|
type Mask: MoveMask;
|
||||||
|
|
||||||
|
/// Create a vector with 8-bit lanes with the given byte repeated into each
|
||||||
|
/// lane.
|
||||||
|
unsafe fn splat(byte: u8) -> Self;
|
||||||
|
|
||||||
|
/// Read a vector-size number of bytes from the given pointer. The pointer
|
||||||
|
/// must be aligned to the size of the vector.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Callers must guarantee that at least `BYTES` bytes are readable from
|
||||||
|
/// `data` and that `data` is aligned to a `BYTES` boundary.
|
||||||
|
unsafe fn load_aligned(data: *const u8) -> Self;
|
||||||
|
|
||||||
|
/// Read a vector-size number of bytes from the given pointer. The pointer
|
||||||
|
/// does not need to be aligned.
|
||||||
|
///
|
||||||
|
/// # Safety
|
||||||
|
///
|
||||||
|
/// Callers must guarantee that at least `BYTES` bytes are readable from
|
||||||
|
/// `data`.
|
||||||
|
unsafe fn load_unaligned(data: *const u8) -> Self;
|
||||||
|
|
||||||
|
/// _mm_movemask_epi8 or _mm256_movemask_epi8
|
||||||
|
unsafe fn movemask(self) -> Self::Mask;
|
||||||
|
/// _mm_cmpeq_epi8 or _mm256_cmpeq_epi8
|
||||||
|
unsafe fn cmpeq(self, vector2: Self) -> Self;
|
||||||
|
/// _mm_and_si128 or _mm256_and_si256
|
||||||
|
unsafe fn and(self, vector2: Self) -> Self;
|
||||||
|
/// _mm_or or _mm256_or_si256
|
||||||
|
unsafe fn or(self, vector2: Self) -> Self;
|
||||||
|
/// Returns true if and only if `Self::movemask` would return a mask that
|
||||||
|
/// contains at least one non-zero bit.
|
||||||
|
unsafe fn movemask_will_have_non_zero(self) -> bool {
|
||||||
|
self.movemask().has_non_zero()
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// A trait that abstracts over a vector-to-scalar operation called
|
||||||
|
/// "move mask."
|
||||||
|
///
|
||||||
|
/// On x86-64, this is `_mm_movemask_epi8` for SSE2 and `_mm256_movemask_epi8`
|
||||||
|
/// for AVX2. It takes a vector of `u8` lanes and returns a scalar where the
|
||||||
|
/// `i`th bit is set if and only if the most significant bit in the `i`th lane
|
||||||
|
/// of the vector is set. The simd128 ISA for wasm32 also supports this
|
||||||
|
/// exact same operation natively.
|
||||||
|
///
|
||||||
|
/// ... But aarch64 doesn't. So we have to fake it with more instructions and
|
||||||
|
/// a slightly different representation. We could do extra work to unify the
|
||||||
|
/// representations, but then would require additional costs in the hot path
|
||||||
|
/// for `memchr` and `packedpair`. So instead, we abstraction over the specific
|
||||||
|
/// representation with this trait and define the operations we actually need.
|
||||||
|
pub(crate) trait MoveMask: Copy + core::fmt::Debug {
|
||||||
|
/// Return a mask that is all zeros except for the least significant `n`
|
||||||
|
/// lanes in a corresponding vector.
|
||||||
|
fn all_zeros_except_least_significant(n: usize) -> Self;
|
||||||
|
|
||||||
|
/// Returns true if and only if this mask has a a non-zero bit anywhere.
|
||||||
|
fn has_non_zero(self) -> bool;
|
||||||
|
|
||||||
|
/// Returns the number of bits set to 1 in this mask.
|
||||||
|
fn count_ones(self) -> usize;
|
||||||
|
|
||||||
|
/// Does a bitwise `and` operation between `self` and `other`.
|
||||||
|
fn and(self, other: Self) -> Self;
|
||||||
|
|
||||||
|
/// Does a bitwise `or` operation between `self` and `other`.
|
||||||
|
fn or(self, other: Self) -> Self;
|
||||||
|
|
||||||
|
/// Returns a mask that is equivalent to `self` but with the least
|
||||||
|
/// significant 1-bit set to 0.
|
||||||
|
fn clear_least_significant_bit(self) -> Self;
|
||||||
|
|
||||||
|
/// Returns the offset of the first non-zero lane this mask represents.
|
||||||
|
fn first_offset(self) -> usize;
|
||||||
|
|
||||||
|
/// Returns the offset of the last non-zero lane this mask represents.
|
||||||
|
fn last_offset(self) -> usize;
|
||||||
|
}
|
||||||
|
|
||||||
|
/// This is a "sensible" movemask implementation where each bit represents
|
||||||
|
/// whether the most significant bit is set in each corresponding lane of a
|
||||||
|
/// vector. This is used on x86-64 and wasm, but such a mask is more expensive
|
||||||
|
/// to get on aarch64 so we use something a little different.
|
||||||
|
///
|
||||||
|
/// We call this "sensible" because this is what we get using native sse/avx
|
||||||
|
/// movemask instructions. But neon has no such native equivalent.
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub(crate) struct SensibleMoveMask(u32);
|
||||||
|
|
||||||
|
impl SensibleMoveMask {
|
||||||
|
/// Get the mask in a form suitable for computing offsets.
|
||||||
|
///
|
||||||
|
/// Basically, this normalizes to little endian. On big endian, this swaps
|
||||||
|
/// the bytes.
|
||||||
|
#[inline(always)]
|
||||||
|
fn get_for_offset(self) -> u32 {
|
||||||
|
#[cfg(target_endian = "big")]
|
||||||
|
{
|
||||||
|
self.0.swap_bytes()
|
||||||
|
}
|
||||||
|
#[cfg(target_endian = "little")]
|
||||||
|
{
|
||||||
|
self.0
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl MoveMask for SensibleMoveMask {
|
||||||
|
#[inline(always)]
|
||||||
|
fn all_zeros_except_least_significant(n: usize) -> SensibleMoveMask {
|
||||||
|
debug_assert!(n < 32);
|
||||||
|
SensibleMoveMask(!((1 << n) - 1))
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn has_non_zero(self) -> bool {
|
||||||
|
self.0 != 0
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn count_ones(self) -> usize {
|
||||||
|
self.0.count_ones() as usize
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn and(self, other: SensibleMoveMask) -> SensibleMoveMask {
|
||||||
|
SensibleMoveMask(self.0 & other.0)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn or(self, other: SensibleMoveMask) -> SensibleMoveMask {
|
||||||
|
SensibleMoveMask(self.0 | other.0)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn clear_least_significant_bit(self) -> SensibleMoveMask {
|
||||||
|
SensibleMoveMask(self.0 & (self.0 - 1))
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn first_offset(self) -> usize {
|
||||||
|
// We are dealing with little endian here (and if we aren't, we swap
|
||||||
|
// the bytes so we are in practice), where the most significant byte
|
||||||
|
// is at a higher address. That means the least significant bit that
|
||||||
|
// is set corresponds to the position of our first matching byte.
|
||||||
|
// That position corresponds to the number of zeros after the least
|
||||||
|
// significant bit.
|
||||||
|
self.get_for_offset().trailing_zeros() as usize
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn last_offset(self) -> usize {
|
||||||
|
// We are dealing with little endian here (and if we aren't, we swap
|
||||||
|
// the bytes so we are in practice), where the most significant byte is
|
||||||
|
// at a higher address. That means the most significant bit that is set
|
||||||
|
// corresponds to the position of our last matching byte. The position
|
||||||
|
// from the end of the mask is therefore the number of leading zeros
|
||||||
|
// in a 32 bit integer, and the position from the start of the mask is
|
||||||
|
// therefore 32 - (leading zeros) - 1.
|
||||||
|
32 - self.get_for_offset().leading_zeros() as usize - 1
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
mod x86sse2 {
|
||||||
|
use core::arch::x86_64::*;
|
||||||
|
|
||||||
|
use super::{SensibleMoveMask, Vector};
|
||||||
|
|
||||||
|
impl Vector for __m128i {
|
||||||
|
const BYTES: usize = 16;
|
||||||
|
const ALIGN: usize = Self::BYTES - 1;
|
||||||
|
|
||||||
|
type Mask = SensibleMoveMask;
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn splat(byte: u8) -> __m128i {
|
||||||
|
_mm_set1_epi8(byte as i8)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_aligned(data: *const u8) -> __m128i {
|
||||||
|
_mm_load_si128(data as *const __m128i)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_unaligned(data: *const u8) -> __m128i {
|
||||||
|
_mm_loadu_si128(data as *const __m128i)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn movemask(self) -> SensibleMoveMask {
|
||||||
|
SensibleMoveMask(_mm_movemask_epi8(self) as u32)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn cmpeq(self, vector2: Self) -> __m128i {
|
||||||
|
_mm_cmpeq_epi8(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn and(self, vector2: Self) -> __m128i {
|
||||||
|
_mm_and_si128(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn or(self, vector2: Self) -> __m128i {
|
||||||
|
_mm_or_si128(self, vector2)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(target_arch = "x86_64")]
|
||||||
|
mod x86avx2 {
|
||||||
|
use core::arch::x86_64::*;
|
||||||
|
|
||||||
|
use super::{SensibleMoveMask, Vector};
|
||||||
|
|
||||||
|
impl Vector for __m256i {
|
||||||
|
const BYTES: usize = 32;
|
||||||
|
const ALIGN: usize = Self::BYTES - 1;
|
||||||
|
|
||||||
|
type Mask = SensibleMoveMask;
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn splat(byte: u8) -> __m256i {
|
||||||
|
_mm256_set1_epi8(byte as i8)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_aligned(data: *const u8) -> __m256i {
|
||||||
|
_mm256_load_si256(data as *const __m256i)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_unaligned(data: *const u8) -> __m256i {
|
||||||
|
_mm256_loadu_si256(data as *const __m256i)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn movemask(self) -> SensibleMoveMask {
|
||||||
|
SensibleMoveMask(_mm256_movemask_epi8(self) as u32)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn cmpeq(self, vector2: Self) -> __m256i {
|
||||||
|
_mm256_cmpeq_epi8(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn and(self, vector2: Self) -> __m256i {
|
||||||
|
_mm256_and_si256(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn or(self, vector2: Self) -> __m256i {
|
||||||
|
_mm256_or_si256(self, vector2)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(target_arch = "aarch64")]
|
||||||
|
mod aarch64neon {
|
||||||
|
use core::arch::aarch64::*;
|
||||||
|
|
||||||
|
use super::{MoveMask, Vector};
|
||||||
|
|
||||||
|
impl Vector for uint8x16_t {
|
||||||
|
const BYTES: usize = 16;
|
||||||
|
const ALIGN: usize = Self::BYTES - 1;
|
||||||
|
|
||||||
|
type Mask = NeonMoveMask;
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn splat(byte: u8) -> uint8x16_t {
|
||||||
|
vdupq_n_u8(byte)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_aligned(data: *const u8) -> uint8x16_t {
|
||||||
|
// I've tried `data.cast::<uint8x16_t>().read()` instead, but
|
||||||
|
// couldn't observe any benchmark differences.
|
||||||
|
Self::load_unaligned(data)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_unaligned(data: *const u8) -> uint8x16_t {
|
||||||
|
vld1q_u8(data)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
#[cfg(target_endian = "little")]
|
||||||
|
unsafe fn movemask(self) -> NeonMoveMask {
|
||||||
|
let asu16s = vreinterpretq_u16_u8(self);
|
||||||
|
let mask = vshrn_n_u16(asu16s, 4);
|
||||||
|
let asu64 = vreinterpret_u64_u8(mask);
|
||||||
|
let scalar64 = vget_lane_u64(asu64, 0);
|
||||||
|
NeonMoveMask(scalar64 & 0x8888888888888888)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
#[cfg(target_endian = "big")]
|
||||||
|
unsafe fn movemask(self) -> NeonMoveMask {
|
||||||
|
// Swap the endianness of each 16-bit input.
|
||||||
|
let asu16s = vreinterpretq_u16_u8(vrev16q_u8(self));
|
||||||
|
let mask = vshrn_n_u16(asu16s, 4);
|
||||||
|
let asu64 = vreinterpret_u64_u8(mask);
|
||||||
|
// Use `swap_bytes` to swap the endianness of the 64-bit output.
|
||||||
|
let scalar64 = vget_lane_u64(asu64, 0).swap_bytes();
|
||||||
|
NeonMoveMask(scalar64 & 0x8888888888888888)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn cmpeq(self, vector2: Self) -> uint8x16_t {
|
||||||
|
vceqq_u8(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn and(self, vector2: Self) -> uint8x16_t {
|
||||||
|
vandq_u8(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn or(self, vector2: Self) -> uint8x16_t {
|
||||||
|
vorrq_u8(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
/// This is the only interesting implementation of this routine.
|
||||||
|
/// Basically, instead of doing the "shift right narrow" dance, we use
|
||||||
|
/// adjacent folding max to determine whether there are any non-zero
|
||||||
|
/// bytes in our mask. If there are, *then* we'll do the "shift right
|
||||||
|
/// narrow" dance. In benchmarks, this does lead to slightly better
|
||||||
|
/// throughput, but the win doesn't appear huge.
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn movemask_will_have_non_zero(self) -> bool {
|
||||||
|
let low = vreinterpretq_u64_u8(vpmaxq_u8(self, self));
|
||||||
|
vgetq_lane_u64(low, 0) != 0
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Neon doesn't have a `movemask` that works like the one in x86-64, so we
|
||||||
|
/// wind up using a different method[1]. The different method also produces
|
||||||
|
/// a mask, but 4 bits are set in the neon case instead of a single bit set
|
||||||
|
/// in the x86-64 case. We do an extra step to zero out 3 of the 4 bits,
|
||||||
|
/// but we still wind up with at least 3 zeroes between each set bit. This
|
||||||
|
/// generally means that we need to do some division by 4 before extracting
|
||||||
|
/// offsets.
|
||||||
|
///
|
||||||
|
/// In fact, the existence of this type is the entire reason that we have
|
||||||
|
/// the `MoveMask` trait in the first place. This basically lets us keep
|
||||||
|
/// the different representations of masks without being forced to unify
|
||||||
|
/// them into a single representation, which could result in extra and
|
||||||
|
/// unnecessary work.
|
||||||
|
///
|
||||||
|
/// [1]: https://community.arm.com/arm-community-blogs/b/infrastructure-solutions-blog/posts/porting-x86-vector-bitmask-optimizations-to-arm-neon
|
||||||
|
#[derive(Clone, Copy, Debug)]
|
||||||
|
pub(crate) struct NeonMoveMask(u64);
|
||||||
|
|
||||||
|
impl NeonMoveMask {
|
||||||
|
/// Get the mask in a form suitable for computing offsets.
|
||||||
|
///
|
||||||
|
/// The mask is always already in host-endianness, so this is a no-op.
|
||||||
|
#[inline(always)]
|
||||||
|
fn get_for_offset(self) -> u64 {
|
||||||
|
self.0
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl MoveMask for NeonMoveMask {
|
||||||
|
#[inline(always)]
|
||||||
|
fn all_zeros_except_least_significant(n: usize) -> NeonMoveMask {
|
||||||
|
debug_assert!(n < 16);
|
||||||
|
NeonMoveMask(!(((1 << n) << 2) - 1))
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn has_non_zero(self) -> bool {
|
||||||
|
self.0 != 0
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn count_ones(self) -> usize {
|
||||||
|
self.0.count_ones() as usize
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn and(self, other: NeonMoveMask) -> NeonMoveMask {
|
||||||
|
NeonMoveMask(self.0 & other.0)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn or(self, other: NeonMoveMask) -> NeonMoveMask {
|
||||||
|
NeonMoveMask(self.0 | other.0)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn clear_least_significant_bit(self) -> NeonMoveMask {
|
||||||
|
NeonMoveMask(self.0 & (self.0 - 1))
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn first_offset(self) -> usize {
|
||||||
|
// We are dealing with little endian here (and if we aren't,
|
||||||
|
// we swap the bytes so we are in practice), where the most
|
||||||
|
// significant byte is at a higher address. That means the least
|
||||||
|
// significant bit that is set corresponds to the position of our
|
||||||
|
// first matching byte. That position corresponds to the number of
|
||||||
|
// zeros after the least significant bit.
|
||||||
|
//
|
||||||
|
// Note that unlike `SensibleMoveMask`, this mask has its bits
|
||||||
|
// spread out over 64 bits instead of 16 bits (for a 128 bit
|
||||||
|
// vector). Namely, where as x86-64 will turn
|
||||||
|
//
|
||||||
|
// 0x00 0xFF 0x00 0x00 0xFF
|
||||||
|
//
|
||||||
|
// into 10010, our neon approach will turn it into
|
||||||
|
//
|
||||||
|
// 10000000000010000000
|
||||||
|
//
|
||||||
|
// And this happens because neon doesn't have a native `movemask`
|
||||||
|
// instruction, so we kind of fake it[1]. Thus, we divide the
|
||||||
|
// number of trailing zeros by 4 to get the "real" offset.
|
||||||
|
//
|
||||||
|
// [1]: https://community.arm.com/arm-community-blogs/b/infrastructure-solutions-blog/posts/porting-x86-vector-bitmask-optimizations-to-arm-neon
|
||||||
|
(self.get_for_offset().trailing_zeros() >> 2) as usize
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
fn last_offset(self) -> usize {
|
||||||
|
// See comment in `first_offset` above. This is basically the same,
|
||||||
|
// but coming from the other direction.
|
||||||
|
16 - (self.get_for_offset().leading_zeros() >> 2) as usize - 1
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(all(target_arch = "wasm32", target_feature = "simd128"))]
|
||||||
|
mod wasm_simd128 {
|
||||||
|
use core::arch::wasm32::*;
|
||||||
|
|
||||||
|
use super::{SensibleMoveMask, Vector};
|
||||||
|
|
||||||
|
impl Vector for v128 {
|
||||||
|
const BYTES: usize = 16;
|
||||||
|
const ALIGN: usize = Self::BYTES - 1;
|
||||||
|
|
||||||
|
type Mask = SensibleMoveMask;
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn splat(byte: u8) -> v128 {
|
||||||
|
u8x16_splat(byte)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_aligned(data: *const u8) -> v128 {
|
||||||
|
*data.cast()
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn load_unaligned(data: *const u8) -> v128 {
|
||||||
|
v128_load(data.cast())
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn movemask(self) -> SensibleMoveMask {
|
||||||
|
SensibleMoveMask(u8x16_bitmask(self).into())
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn cmpeq(self, vector2: Self) -> v128 {
|
||||||
|
u8x16_eq(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn and(self, vector2: Self) -> v128 {
|
||||||
|
v128_and(self, vector2)
|
||||||
|
}
|
||||||
|
|
||||||
|
#[inline(always)]
|
||||||
|
unsafe fn or(self, vector2: Self) -> v128 {
|
||||||
|
v128_or(self, vector2)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
1
third_party/crates/proc-macro2-1.0.107/.cargo-checksum.json
vendored
Normal file
1
third_party/crates/proc-macro2-1.0.107/.cargo-checksum.json
vendored
Normal file
@@ -0,0 +1 @@
|
|||||||
|
{"$comment":"This file only protects against accidental modifications. It is not a security mechanism and does not protect against malicious changes.","files":{".cargo_vcs_info.json":"0a870b23ea0c10231ed5a850b8fe8f23dd74926e90594e49a35a7e1b5e8a92f5",".github/FUNDING.yml":"b017158736b3c9751a2d21edfce7fe61c8954e2fced8da8dd3013c2f3e295bd9",".github/workflows/ci.yml":"f0003fd6c9bd0f9208f552a57dd5dd76fee714a7d0be286cecc98f06add580ff","Cargo.lock":"30daf1b1e7557b089dfe7783a6cdd8bd7b4f82b31eaaa554c1afbca448f3a936","Cargo.toml":"6bdbe54a7f052e552dcfca90351764476e2767237ec3f954df8bd9f602861056","Cargo.toml.orig":"e04a009c48ea3e9b017807ea9183e330cc909a9cc0e754c5c6b3f7c0b29fb9de","LICENSE-APACHE":"62c7a1e35f56406896d7aa7ca52d0cc0d272ac022b5d2796e7d6905db8a3636a","LICENSE-MIT":"23f18e03dc49df91622fe2a76176497404e46ced8a715d9d2b67a7446571cca3","README.md":"8eebdcf2f9a5034693589a9982adf06c2aac5c9f078c07a44400d293ed5b4a8e","build.rs":"baeb20b52f6b536be8657a566591a507bb2e34a45cf8baa42b135510a0c3c729","rust-toolchain.toml":"6bbb61302978c736b2da03e4fb40e3beab908f85d533ab46fd541e637b5f3e0f","src/detection.rs":"ed9a5f9a979ab01247d7a68eeb1afa3c13209334c5bfff0f9289cb07e5bb4e8b","src/extra.rs":"29f094473279a29b71c3cc9f5fa27c2e2c30c670390cf7e4b7cf451486cc857e","src/fallback.rs":"416a3d24349c163d47f62ac8ae61c28ba6dc4990f04f3d5dacde030b86582d06","src/lib.rs":"ed6bf5e3c3b4fc952d4bdf9b48b149087bceaebf5392befce0bc6cae590a008d","src/location.rs":"9225c5a55f03b56cce42bc55ceb509e8216a5e0b24c94aa1cd071b04e3d6c15f","src/marker.rs":"c11c5a1be8bdf18be3fcd224393f350a9aae7ce282e19ce583c84910c6903a8f","src/num.rs":"82d625cbcd255965e46231ac3af1b74ab8bff9787c799e8ed1f978de146cb0b5","src/parse.rs":"1257d423e9311dda9db0239ff244dfe7b028c1048ab8a83d76daec6068b05114","src/probe.rs":"2b57e8ebf46a7c60ee2762f23f16d24ee9ddb8f1acd0a7faf7a99cf2e4187151","src/probe/proc_macro_span.rs":"53853f0c70170c9695294b8867821664d9b8f1c901957b003003a3c26987abbe","src/probe/proc_macro_span_file.rs":"e7fb4cf8852d9d589bfa3321d8d5cdc8cccb45606ec816a6b8a08f73e416b9ce","src/probe/proc_macro_span_location.rs":"e022386204b6e042b3c55a6c809923849a2f915199bcbf3be72d0b7c8ffa7f83","src/rcvec.rs":"d6e4c1ea42f75e63465fce50ca83f9257536ccdc0345fe78b0037aa2c08c5e37","src/rustc_literal_escaper.rs":"fb3f2f93a09b84f539e6ef514d4b403ee16f2112ff04642099170a60828318ee","src/wrapper.rs":"21a563ef1eec685e3d60ee0479812f212c578dc6d405053b7827c46f6801fdc6","tests/comments.rs":"11520f6baee23b9258db904f4c256fd3877493f754e2b99041f73a330e74a911","tests/features.rs":"7e52c0c801019b271bf11a994c2e1799a1429b0c1a3a34e551a23971797fe412","tests/marker.rs":"f16299460587d6c65603ed809f1a3b81853e4b99d6cb44d0b68bb07259d7e9f8","tests/test.rs":"7d58c3a754241ffdec84e4e9ac799852071db71d77359de164ca7ba6217020e9","tests/test_fmt.rs":"1fa3a817bf934c3bb38942e56eecb70ef525710c6bcfec0356adec654b053c0b","tests/test_size.rs":"7ed5f07c3ccc74c4d09f3c1c43542fbbe23417146761558a0fd4659e19ae1afc"},"package":"985e7ec9bb745e6ce6535b544d84d6cd6f7ad8bd711c398938ae983b91a766d9"}
|
||||||
6
third_party/crates/proc-macro2-1.0.107/.cargo_vcs_info.json
vendored
Normal file
6
third_party/crates/proc-macro2-1.0.107/.cargo_vcs_info.json
vendored
Normal file
@@ -0,0 +1,6 @@
|
|||||||
|
{
|
||||||
|
"git": {
|
||||||
|
"sha1": "ed8a5497669cd63db33bf24646f261b012bbbc4a"
|
||||||
|
},
|
||||||
|
"path_in_vcs": ""
|
||||||
|
}
|
||||||
1
third_party/crates/proc-macro2-1.0.107/.github/FUNDING.yml
vendored
Normal file
1
third_party/crates/proc-macro2-1.0.107/.github/FUNDING.yml
vendored
Normal file
@@ -0,0 +1 @@
|
|||||||
|
github: dtolnay
|
||||||
232
third_party/crates/proc-macro2-1.0.107/.github/workflows/ci.yml
vendored
Normal file
232
third_party/crates/proc-macro2-1.0.107/.github/workflows/ci.yml
vendored
Normal file
@@ -0,0 +1,232 @@
|
|||||||
|
name: CI
|
||||||
|
|
||||||
|
on:
|
||||||
|
push:
|
||||||
|
pull_request:
|
||||||
|
workflow_dispatch:
|
||||||
|
schedule: [cron: "40 1 * * *"]
|
||||||
|
|
||||||
|
permissions:
|
||||||
|
contents: read
|
||||||
|
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: -Dwarnings
|
||||||
|
|
||||||
|
jobs:
|
||||||
|
pre_ci:
|
||||||
|
uses: dtolnay/.github/.github/workflows/pre_ci.yml@master
|
||||||
|
|
||||||
|
test:
|
||||||
|
name: Rust ${{matrix.rust}}
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
strategy:
|
||||||
|
fail-fast: false
|
||||||
|
matrix:
|
||||||
|
rust: [1.80.0, stable, beta]
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@master
|
||||||
|
with:
|
||||||
|
toolchain: ${{matrix.rust}}
|
||||||
|
components: rust-src
|
||||||
|
- run: cargo test
|
||||||
|
- run: cargo test --no-default-features
|
||||||
|
- run: cargo test --features span-locations
|
||||||
|
- name: RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo test
|
||||||
|
run: cargo test
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_semver_exempt ${{env.RUSTFLAGS}}
|
||||||
|
- name: RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo test --no-default-features
|
||||||
|
run: cargo test --no-default-features
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_semver_exempt ${{env.RUSTFLAGS}}
|
||||||
|
|
||||||
|
nightly:
|
||||||
|
name: Rust nightly
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
with:
|
||||||
|
components: rust-src
|
||||||
|
- name: Enable type layout randomization
|
||||||
|
run: echo RUSTFLAGS=${RUSTFLAGS}\ -Zrandomize-layout\ --cfg=randomize_layout >> $GITHUB_ENV
|
||||||
|
- run: cargo check
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_nightly_testing ${{env.RUSTFLAGS}}
|
||||||
|
- run: cargo test
|
||||||
|
- run: cargo test --no-default-features
|
||||||
|
- run: cargo test --no-default-features --test features -- --ignored make_sure_no_proc_macro # run the ignored test to make sure the `proc-macro` feature is disabled
|
||||||
|
- run: cargo test --features span-locations
|
||||||
|
- run: cargo test --manifest-path tests/ui/Cargo.toml
|
||||||
|
- name: RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo test
|
||||||
|
run: cargo test
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_semver_exempt ${{env.RUSTFLAGS}}
|
||||||
|
- name: RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo test --no-default-features
|
||||||
|
run: cargo test --no-default-features
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_semver_exempt ${{env.RUSTFLAGS}}
|
||||||
|
- name: RUSTFLAGS='-Z allow-features=' cargo test
|
||||||
|
run: cargo test
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: -Z allow-features= --cfg procmacro2_backtrace ${{env.RUSTFLAGS}}
|
||||||
|
- uses: actions/upload-artifact@v7
|
||||||
|
if: always()
|
||||||
|
with:
|
||||||
|
name: Cargo.lock
|
||||||
|
path: Cargo.lock
|
||||||
|
continue-on-error: true
|
||||||
|
|
||||||
|
layout:
|
||||||
|
name: Layout
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
with:
|
||||||
|
components: rust-src
|
||||||
|
- run: cargo test --test test_size
|
||||||
|
- run: cargo test --test test_size --features span-locations
|
||||||
|
- run: cargo test --test test_size --no-default-features
|
||||||
|
- run: cargo test --test test_size --no-default-features --features span-locations
|
||||||
|
|
||||||
|
msrv:
|
||||||
|
name: Rust 1.71.0
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@1.71.0
|
||||||
|
with:
|
||||||
|
components: rust-src
|
||||||
|
- run: cargo check
|
||||||
|
- run: cargo check --no-default-features
|
||||||
|
- run: cargo check --features span-locations
|
||||||
|
- name: RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo check
|
||||||
|
run: cargo check
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_semver_exempt ${{env.RUSTFLAGS}}
|
||||||
|
- name: RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo check --no-default-features
|
||||||
|
run: cargo check --no-default-features
|
||||||
|
env:
|
||||||
|
RUSTFLAGS: --cfg procmacro2_semver_exempt ${{env.RUSTFLAGS}}
|
||||||
|
|
||||||
|
minimal:
|
||||||
|
name: Minimal versions
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
- run: cargo generate-lockfile -Z minimal-versions
|
||||||
|
- run: cargo check --locked
|
||||||
|
|
||||||
|
webassembly:
|
||||||
|
name: WebAssembly
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
with:
|
||||||
|
target: wasm32-unknown-unknown
|
||||||
|
components: rust-src
|
||||||
|
- name: Ignore WebAssembly linker warning
|
||||||
|
run: echo RUSTFLAGS=${RUSTFLAGS}\ -Alinker_messages >> $GITHUB_ENV
|
||||||
|
- run: cargo test --target wasm32-unknown-unknown --no-run
|
||||||
|
|
||||||
|
fuzz:
|
||||||
|
name: Fuzz
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
with:
|
||||||
|
components: rust-src
|
||||||
|
- uses: dtolnay/install@cargo-fuzz
|
||||||
|
- run: cargo fuzz check
|
||||||
|
- run: cargo check --no-default-features --features afl
|
||||||
|
working-directory: fuzz
|
||||||
|
- uses: dtolnay/install@honggfuzz
|
||||||
|
- name: Run apt install binutils-dev libunwind-dev
|
||||||
|
run: |
|
||||||
|
sudo sed -i 's/^update_initramfs=yes$/update_initramfs=no/' /etc/initramfs-tools/update-initramfs.conf
|
||||||
|
sudo rm -f /var/lib/man-db/auto-update
|
||||||
|
sudo apt-get update
|
||||||
|
sudo apt-get install binutils-dev libunwind-dev
|
||||||
|
- run: cargo hfuzz build --no-default-features --features honggfuzz
|
||||||
|
working-directory: fuzz
|
||||||
|
|
||||||
|
doc:
|
||||||
|
name: Documentation
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
env:
|
||||||
|
RUSTDOCFLAGS: -Dwarnings
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
with:
|
||||||
|
components: rust-src
|
||||||
|
- uses: dtolnay/install@cargo-docs-rs
|
||||||
|
- run: cargo docs-rs
|
||||||
|
|
||||||
|
clippy:
|
||||||
|
name: Clippy
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
if: github.event_name != 'pull_request'
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@nightly
|
||||||
|
with:
|
||||||
|
components: clippy, rust-src
|
||||||
|
- run: cargo clippy --tests -- -Dclippy::all -Dclippy::pedantic
|
||||||
|
- run: cargo clippy --tests --all-features -- -Dclippy::all -Dclippy::pedantic
|
||||||
|
|
||||||
|
miri:
|
||||||
|
name: Miri
|
||||||
|
needs: pre_ci
|
||||||
|
if: needs.pre_ci.outputs.continue
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@miri
|
||||||
|
- run: cargo miri setup
|
||||||
|
- run: cargo miri test
|
||||||
|
env:
|
||||||
|
MIRIFLAGS: -Zmiri-strict-provenance
|
||||||
|
|
||||||
|
outdated:
|
||||||
|
name: Outdated
|
||||||
|
runs-on: ubuntu-latest
|
||||||
|
if: github.event_name != 'pull_request'
|
||||||
|
timeout-minutes: 45
|
||||||
|
steps:
|
||||||
|
- uses: actions/checkout@v7
|
||||||
|
- uses: dtolnay/rust-toolchain@stable
|
||||||
|
- uses: dtolnay/install@cargo-outdated
|
||||||
|
- run: cargo outdated --workspace --exit-code 1
|
||||||
|
- run: cargo outdated --manifest-path fuzz/Cargo.toml --exit-code 1
|
||||||
186
third_party/crates/proc-macro2-1.0.107/BUILD.bazel
vendored
Normal file
186
third_party/crates/proc-macro2-1.0.107/BUILD.bazel
vendored
Normal file
@@ -0,0 +1,186 @@
|
|||||||
|
###############################################################################
|
||||||
|
# @generated
|
||||||
|
# DO NOT MODIFY: This file is auto-generated by a crate_universe tool. To
|
||||||
|
# regenerate this file, run the following:
|
||||||
|
#
|
||||||
|
# bazel run @@//third_party:vendor_crates
|
||||||
|
###############################################################################
|
||||||
|
|
||||||
|
load(
|
||||||
|
"@rules_rust//cargo:defs.bzl",
|
||||||
|
"cargo_build_script",
|
||||||
|
"cargo_toml_env_vars",
|
||||||
|
)
|
||||||
|
load("@rules_rust//rust:defs.bzl", "rust_library")
|
||||||
|
|
||||||
|
package(default_visibility = ["//visibility:public"])
|
||||||
|
|
||||||
|
cargo_toml_env_vars(
|
||||||
|
name = "cargo_toml_env_vars",
|
||||||
|
src = "Cargo.toml",
|
||||||
|
)
|
||||||
|
|
||||||
|
rust_library(
|
||||||
|
name = "proc_macro2",
|
||||||
|
srcs = glob(
|
||||||
|
include = ["**/*.rs"],
|
||||||
|
allow_empty = False,
|
||||||
|
),
|
||||||
|
compile_data = glob(
|
||||||
|
include = ["**"],
|
||||||
|
allow_empty = True,
|
||||||
|
exclude = [
|
||||||
|
"**/* *",
|
||||||
|
".tmp_git_root/**/*",
|
||||||
|
"BUILD",
|
||||||
|
"BUILD.bazel",
|
||||||
|
"WORKSPACE",
|
||||||
|
"WORKSPACE.bazel",
|
||||||
|
],
|
||||||
|
),
|
||||||
|
crate_features = [
|
||||||
|
"proc-macro",
|
||||||
|
],
|
||||||
|
crate_root = "src/lib.rs",
|
||||||
|
edition = "2021",
|
||||||
|
rustc_env_files = [
|
||||||
|
":cargo_toml_env_vars",
|
||||||
|
],
|
||||||
|
rustc_flags = [
|
||||||
|
"--cap-lints=allow",
|
||||||
|
],
|
||||||
|
tags = [
|
||||||
|
"cargo-bazel",
|
||||||
|
"crate-name=proc-macro2",
|
||||||
|
"manual",
|
||||||
|
"noclippy",
|
||||||
|
"norustfmt",
|
||||||
|
],
|
||||||
|
target_compatible_with = select({
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios-macabi": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-apple-ios-sim": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-fuchsia": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-nixos-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-none": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-nto-qnx710": [],
|
||||||
|
"@rules_rust//rust/platform:aarch64-unknown-uefi": [],
|
||||||
|
"@rules_rust//rust/platform:arm-unknown-linux-gnueabi": [],
|
||||||
|
"@rules_rust//rust/platform:arm-unknown-linux-musleabi": [],
|
||||||
|
"@rules_rust//rust/platform:armv7-linux-androideabi": [],
|
||||||
|
"@rules_rust//rust/platform:armv7-unknown-linux-gnueabi": [],
|
||||||
|
"@rules_rust//rust/platform:i686-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:i686-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:i686-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:i686-unknown-freebsd": [],
|
||||||
|
"@rules_rust//rust/platform:i686-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:loongarch64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:mips-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:powerpc-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:riscv32imac-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:riscv32imc-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:riscv64gc-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:riscv64gc-unknown-none-elf": [],
|
||||||
|
"@rules_rust//rust/platform:s390x-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-netbsd": [],
|
||||||
|
"@rules_rust//rust/platform:sparc64-unknown-openbsd": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv6m-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7em-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7em-none-eabihf": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv7m-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv8m.main-none-eabi": [],
|
||||||
|
"@rules_rust//rust/platform:thumbv8m.main-none-eabihf": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-unknown-emscripten": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-unknown-unknown": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip1": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip1-threads": [],
|
||||||
|
"@rules_rust//rust/platform:wasm32-wasip2": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-darwin": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-ios": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-apple-ios-macabi": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-linux-android": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-pc-windows-msvc": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-freebsd": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-fuchsia": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-linux-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-nixos-gnu": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-none": [],
|
||||||
|
"@rules_rust//rust/platform:x86_64-unknown-uefi": [],
|
||||||
|
"//conditions:default": ["@platforms//:incompatible"],
|
||||||
|
}),
|
||||||
|
version = "1.0.107",
|
||||||
|
deps = [
|
||||||
|
":build_script_build",
|
||||||
|
"//third_party/crates/unicode-ident-1.0.24:unicode_ident",
|
||||||
|
],
|
||||||
|
)
|
||||||
|
|
||||||
|
cargo_build_script(
|
||||||
|
name = "_bs",
|
||||||
|
srcs = glob(
|
||||||
|
include = ["**/*.rs"],
|
||||||
|
allow_empty = False,
|
||||||
|
),
|
||||||
|
build_script_env_files = [
|
||||||
|
":cargo_toml_env_vars",
|
||||||
|
],
|
||||||
|
compile_data = glob(
|
||||||
|
include = ["**"],
|
||||||
|
allow_empty = True,
|
||||||
|
exclude = [
|
||||||
|
"**/* *",
|
||||||
|
"**/*.rs",
|
||||||
|
".tmp_git_root/**/*",
|
||||||
|
"BUILD",
|
||||||
|
"BUILD.bazel",
|
||||||
|
"WORKSPACE",
|
||||||
|
"WORKSPACE.bazel",
|
||||||
|
],
|
||||||
|
),
|
||||||
|
crate_features = [
|
||||||
|
"proc-macro",
|
||||||
|
],
|
||||||
|
crate_name = "build_script_build",
|
||||||
|
crate_root = "build.rs",
|
||||||
|
data = glob(
|
||||||
|
include = ["**"],
|
||||||
|
allow_empty = True,
|
||||||
|
exclude = [
|
||||||
|
"**/* *",
|
||||||
|
".tmp_git_root/**/*",
|
||||||
|
"BUILD",
|
||||||
|
"BUILD.bazel",
|
||||||
|
"WORKSPACE",
|
||||||
|
"WORKSPACE.bazel",
|
||||||
|
],
|
||||||
|
),
|
||||||
|
edition = "2021",
|
||||||
|
emit_warnings = False,
|
||||||
|
pkg_name = "proc-macro2",
|
||||||
|
rustc_env_files = [
|
||||||
|
":cargo_toml_env_vars",
|
||||||
|
],
|
||||||
|
rustc_flags = [
|
||||||
|
"--cap-lints=allow",
|
||||||
|
],
|
||||||
|
tags = [
|
||||||
|
"cargo-bazel",
|
||||||
|
"crate-name=proc-macro2",
|
||||||
|
"manual",
|
||||||
|
"noclippy",
|
||||||
|
"norustfmt",
|
||||||
|
],
|
||||||
|
version = "1.0.107",
|
||||||
|
visibility = ["//visibility:private"],
|
||||||
|
)
|
||||||
|
|
||||||
|
alias(
|
||||||
|
name = "build_script_build",
|
||||||
|
actual = ":_bs",
|
||||||
|
tags = ["manual"],
|
||||||
|
)
|
||||||
230
third_party/crates/proc-macro2-1.0.107/Cargo.lock
generated
vendored
Normal file
230
third_party/crates/proc-macro2-1.0.107/Cargo.lock
generated
vendored
Normal file
@@ -0,0 +1,230 @@
|
|||||||
|
# This file is automatically @generated by Cargo.
|
||||||
|
# It is not intended for manual editing.
|
||||||
|
version = 3
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "adler2"
|
||||||
|
version = "2.0.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "320119579fcad9c21884f5c4861d16174d0e06250625266f50fe6898340abefa"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "bitflags"
|
||||||
|
version = "2.13.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "b588b76d00fde79687d7646a9b5bdf3cc0f655e0bbd080335a95d7e96f3587da"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "cfg-if"
|
||||||
|
version = "1.0.4"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "9330f8b2ff13f34540b44e946ef35111825727b38d33286ef986142615121801"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "crc32fast"
|
||||||
|
version = "1.5.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "9481c1c90cbf2ac953f07c8d4a58aa3945c425b7185c9154d67a65e4230da511"
|
||||||
|
dependencies = [
|
||||||
|
"cfg-if",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "crossbeam-deque"
|
||||||
|
version = "0.8.7"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "5181e0de7b61eb03a81e347d6dd8797bae9da5146707b51077e2d71a54ec0ceb"
|
||||||
|
dependencies = [
|
||||||
|
"crossbeam-epoch",
|
||||||
|
"crossbeam-utils",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "crossbeam-epoch"
|
||||||
|
version = "0.9.20"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "2d6914041f254d6e9176c01941b21115dcfb7089e55135a35411081bd106ef3f"
|
||||||
|
dependencies = [
|
||||||
|
"crossbeam-utils",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "crossbeam-utils"
|
||||||
|
version = "0.8.22"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "61803da095bee82a81bb1a452ecc25d3b2f1416d1897eb86430c6159ef717c17"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "either"
|
||||||
|
version = "1.16.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "91622ff5e7162018101f2fea40d6ebf4a78bbe5a49736a2020649edf9693679e"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "errno"
|
||||||
|
version = "0.3.14"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "39cab71617ae0d63f51a36d69f866391735b51691dbda63cf6f96d042b63efeb"
|
||||||
|
dependencies = [
|
||||||
|
"libc",
|
||||||
|
"windows-sys",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "filetime"
|
||||||
|
version = "0.2.29"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "5c287a33c7f0a620c38e641e7f60827713987b3c0f26e8ddc9462cc69cf75759"
|
||||||
|
dependencies = [
|
||||||
|
"cfg-if",
|
||||||
|
"libc",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "flate2"
|
||||||
|
version = "1.1.9"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "843fba2746e448b37e26a819579957415c8cef339bf08564fe8b7ddbd959573c"
|
||||||
|
dependencies = [
|
||||||
|
"crc32fast",
|
||||||
|
"miniz_oxide",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "libc"
|
||||||
|
version = "0.2.186"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "68ab91017fe16c622486840e4c83c9a37afeff978bd239b5293d61ece587de66"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "linux-raw-sys"
|
||||||
|
version = "0.12.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "32a66949e030da00e8c7d4434b251670a91556f4144941d37452769c25d58a53"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "miniz_oxide"
|
||||||
|
version = "0.8.9"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "1fa76a2c86f704bdb222d66965fb3d63269ce38518b83cb0575fca855ebb6316"
|
||||||
|
dependencies = [
|
||||||
|
"adler2",
|
||||||
|
"simd-adler32",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "proc-macro2"
|
||||||
|
version = "1.0.106"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "8fd00f0bb2e90d81d1044c2b32617f68fcb9fa3bb7640c23e9c748e53fb30934"
|
||||||
|
dependencies = [
|
||||||
|
"unicode-ident",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "proc-macro2"
|
||||||
|
version = "1.0.107"
|
||||||
|
dependencies = [
|
||||||
|
"flate2",
|
||||||
|
"quote",
|
||||||
|
"rayon",
|
||||||
|
"rustversion",
|
||||||
|
"tar",
|
||||||
|
"unicode-ident",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "quote"
|
||||||
|
version = "1.0.47"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "1fbf4db142a473a8d80c26bbf18454ed458bf8d26c8219c331daecfdbd079001"
|
||||||
|
dependencies = [
|
||||||
|
"proc-macro2 1.0.106",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rayon"
|
||||||
|
version = "1.12.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "fb39b166781f92d482534ef4b4b1b2568f42613b53e5b6c160e24cfbfa30926d"
|
||||||
|
dependencies = [
|
||||||
|
"either",
|
||||||
|
"rayon-core",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rayon-core"
|
||||||
|
version = "1.13.0"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "22e18b0f0062d30d4230b2e85ff77fdfe4326feb054b9783a3460d8435c8ab91"
|
||||||
|
dependencies = [
|
||||||
|
"crossbeam-deque",
|
||||||
|
"crossbeam-utils",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rustix"
|
||||||
|
version = "1.1.4"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "b6fe4565b9518b83ef4f91bb47ce29620ca828bd32cb7e408f0062e9930ba190"
|
||||||
|
dependencies = [
|
||||||
|
"bitflags",
|
||||||
|
"errno",
|
||||||
|
"libc",
|
||||||
|
"linux-raw-sys",
|
||||||
|
"windows-sys",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "rustversion"
|
||||||
|
version = "1.0.23"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "cf54715a573b99ac80df0bc206da022bcd442c974952c7b9720069370852e21f"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "simd-adler32"
|
||||||
|
version = "0.3.10"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "3a219298ac11a56ea9a6d2120044824d6f01aeb034955e7af7bc16858527deea"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "tar"
|
||||||
|
version = "0.4.46"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "3f6221d9a6003c78398e3b239969f352578258df48c8eb051caadae0015bc840"
|
||||||
|
dependencies = [
|
||||||
|
"filetime",
|
||||||
|
"libc",
|
||||||
|
"xattr",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "unicode-ident"
|
||||||
|
version = "1.0.24"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "e6e4313cd5fcd3dad5cafa179702e2b244f760991f45397d14d4ebf38247da75"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "windows-link"
|
||||||
|
version = "0.2.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "f0805222e57f7521d6a62e36fa9163bc891acd422f971defe97d64e70d0a4fe5"
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "windows-sys"
|
||||||
|
version = "0.61.2"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "ae137229bcbd6cdf0f7b80a31df61766145077ddf49416a728b02cb3921ff3fc"
|
||||||
|
dependencies = [
|
||||||
|
"windows-link",
|
||||||
|
]
|
||||||
|
|
||||||
|
[[package]]
|
||||||
|
name = "xattr"
|
||||||
|
version = "1.6.1"
|
||||||
|
source = "registry+https://github.com/rust-lang/crates.io-index"
|
||||||
|
checksum = "32e45ad4206f6d2479085147f02bc2ef834ac85886624a23575ae137c8aa8156"
|
||||||
|
dependencies = [
|
||||||
|
"libc",
|
||||||
|
"rustix",
|
||||||
|
]
|
||||||
105
third_party/crates/proc-macro2-1.0.107/Cargo.toml
vendored
Normal file
105
third_party/crates/proc-macro2-1.0.107/Cargo.toml
vendored
Normal file
@@ -0,0 +1,105 @@
|
|||||||
|
# THIS FILE IS AUTOMATICALLY GENERATED BY CARGO
|
||||||
|
#
|
||||||
|
# When uploading crates to the registry Cargo will automatically
|
||||||
|
# "normalize" Cargo.toml files for maximal compatibility
|
||||||
|
# with all versions of Cargo and also rewrite `path` dependencies
|
||||||
|
# to registry (e.g., crates.io) dependencies.
|
||||||
|
#
|
||||||
|
# If you are reading this file be aware that the original Cargo.toml
|
||||||
|
# will likely look very different (and much more reasonable).
|
||||||
|
# See Cargo.toml.orig for the original contents.
|
||||||
|
|
||||||
|
[package]
|
||||||
|
edition = "2021"
|
||||||
|
rust-version = "1.71"
|
||||||
|
name = "proc-macro2"
|
||||||
|
version = "1.0.107"
|
||||||
|
authors = [
|
||||||
|
"David Tolnay <dtolnay@gmail.com>",
|
||||||
|
"Alex Crichton <alex@alexcrichton.com>",
|
||||||
|
]
|
||||||
|
build = "build.rs"
|
||||||
|
autolib = false
|
||||||
|
autobins = false
|
||||||
|
autoexamples = false
|
||||||
|
autotests = false
|
||||||
|
autobenches = false
|
||||||
|
description = "A substitute implementation of the compiler's `proc_macro` API to decouple token-based libraries from the procedural macro use case."
|
||||||
|
documentation = "https://docs.rs/proc-macro2"
|
||||||
|
readme = "README.md"
|
||||||
|
keywords = [
|
||||||
|
"macros",
|
||||||
|
"syn",
|
||||||
|
]
|
||||||
|
categories = ["development-tools::procedural-macro-helpers"]
|
||||||
|
license = "MIT OR Apache-2.0"
|
||||||
|
repository = "https://github.com/dtolnay/proc-macro2"
|
||||||
|
|
||||||
|
[package.metadata.docs.rs]
|
||||||
|
rustc-args = ["--cfg=procmacro2_semver_exempt"]
|
||||||
|
targets = ["x86_64-unknown-linux-gnu"]
|
||||||
|
rustdoc-args = [
|
||||||
|
"--cfg=procmacro2_semver_exempt",
|
||||||
|
"--generate-link-to-definition",
|
||||||
|
"--generate-macro-expansion",
|
||||||
|
"--extern-html-root-url=core=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=alloc=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=std=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=proc_macro=https://doc.rust-lang.org",
|
||||||
|
]
|
||||||
|
|
||||||
|
[package.metadata.playground]
|
||||||
|
features = ["span-locations"]
|
||||||
|
|
||||||
|
[features]
|
||||||
|
default = ["proc-macro"]
|
||||||
|
nightly = []
|
||||||
|
proc-macro = []
|
||||||
|
span-locations = []
|
||||||
|
|
||||||
|
[lib]
|
||||||
|
name = "proc_macro2"
|
||||||
|
path = "src/lib.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "comments"
|
||||||
|
path = "tests/comments.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "features"
|
||||||
|
path = "tests/features.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "marker"
|
||||||
|
path = "tests/marker.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "test"
|
||||||
|
path = "tests/test.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "test_fmt"
|
||||||
|
path = "tests/test_fmt.rs"
|
||||||
|
|
||||||
|
[[test]]
|
||||||
|
name = "test_size"
|
||||||
|
path = "tests/test_size.rs"
|
||||||
|
|
||||||
|
[dependencies.unicode-ident]
|
||||||
|
version = "1.0"
|
||||||
|
|
||||||
|
[dev-dependencies.flate2]
|
||||||
|
version = "1.0"
|
||||||
|
|
||||||
|
[dev-dependencies.quote]
|
||||||
|
version = "1.0"
|
||||||
|
default-features = false
|
||||||
|
|
||||||
|
[dev-dependencies.rayon]
|
||||||
|
version = "1.0"
|
||||||
|
|
||||||
|
[dev-dependencies.rustversion]
|
||||||
|
version = "1"
|
||||||
|
|
||||||
|
[dev-dependencies.tar]
|
||||||
|
version = "0.4"
|
||||||
67
third_party/crates/proc-macro2-1.0.107/Cargo.toml.orig
generated
vendored
Normal file
67
third_party/crates/proc-macro2-1.0.107/Cargo.toml.orig
generated
vendored
Normal file
@@ -0,0 +1,67 @@
|
|||||||
|
[package]
|
||||||
|
name = "proc-macro2"
|
||||||
|
version = "1.0.107"
|
||||||
|
authors = ["David Tolnay <dtolnay@gmail.com>", "Alex Crichton <alex@alexcrichton.com>"]
|
||||||
|
autobenches = false
|
||||||
|
categories = ["development-tools::procedural-macro-helpers"]
|
||||||
|
description = "A substitute implementation of the compiler's `proc_macro` API to decouple token-based libraries from the procedural macro use case."
|
||||||
|
documentation = "https://docs.rs/proc-macro2"
|
||||||
|
edition = "2021"
|
||||||
|
keywords = ["macros", "syn"]
|
||||||
|
license = "MIT OR Apache-2.0"
|
||||||
|
repository = "https://github.com/dtolnay/proc-macro2"
|
||||||
|
rust-version = "1.71"
|
||||||
|
|
||||||
|
[package.metadata.docs.rs]
|
||||||
|
rustc-args = ["--cfg=procmacro2_semver_exempt"]
|
||||||
|
targets = ["x86_64-unknown-linux-gnu"]
|
||||||
|
rustdoc-args = [
|
||||||
|
"--cfg=procmacro2_semver_exempt",
|
||||||
|
"--generate-link-to-definition",
|
||||||
|
"--generate-macro-expansion",
|
||||||
|
"--extern-html-root-url=core=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=alloc=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=std=https://doc.rust-lang.org",
|
||||||
|
"--extern-html-root-url=proc_macro=https://doc.rust-lang.org",
|
||||||
|
]
|
||||||
|
|
||||||
|
[package.metadata.playground]
|
||||||
|
features = ["span-locations"]
|
||||||
|
|
||||||
|
[dependencies]
|
||||||
|
unicode-ident = "1.0"
|
||||||
|
|
||||||
|
[dev-dependencies]
|
||||||
|
flate2 = "1.0"
|
||||||
|
quote = { version = "1.0", default-features = false }
|
||||||
|
rayon = "1.0"
|
||||||
|
rustversion = "1"
|
||||||
|
tar = "0.4"
|
||||||
|
|
||||||
|
[features]
|
||||||
|
proc-macro = []
|
||||||
|
default = ["proc-macro"]
|
||||||
|
|
||||||
|
# Expose methods Span::start and Span::end which give the line/column location
|
||||||
|
# of a token.
|
||||||
|
span-locations = []
|
||||||
|
|
||||||
|
# This feature no longer means anything.
|
||||||
|
nightly = []
|
||||||
|
|
||||||
|
[workspace]
|
||||||
|
members = ["benches/bench-libproc-macro", "tests/ui"]
|
||||||
|
|
||||||
|
[patch.crates-io]
|
||||||
|
# Our doc tests depend on quote which depends on proc-macro2. Without this line,
|
||||||
|
# the proc-macro2 dependency of quote would be the released version of
|
||||||
|
# proc-macro2. Quote would implement its traits for types from that proc-macro2,
|
||||||
|
# meaning impls would be missing when tested against types from the local
|
||||||
|
# proc-macro2.
|
||||||
|
#
|
||||||
|
# GitHub Actions builds that are in progress at the time that you publish may
|
||||||
|
# spuriously fail. This is because they'll be building a local proc-macro2 which
|
||||||
|
# carries the second-most-recent version number, pulling in quote which resolves
|
||||||
|
# to a dependency on the just-published most recent version number. Thus the
|
||||||
|
# patch will fail to apply because the version numbers are different.
|
||||||
|
proc-macro2 = { path = "." }
|
||||||
176
third_party/crates/proc-macro2-1.0.107/LICENSE-APACHE
vendored
Normal file
176
third_party/crates/proc-macro2-1.0.107/LICENSE-APACHE
vendored
Normal file
@@ -0,0 +1,176 @@
|
|||||||
|
Apache License
|
||||||
|
Version 2.0, January 2004
|
||||||
|
http://www.apache.org/licenses/
|
||||||
|
|
||||||
|
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||||
|
|
||||||
|
1. Definitions.
|
||||||
|
|
||||||
|
"License" shall mean the terms and conditions for use, reproduction,
|
||||||
|
and distribution as defined by Sections 1 through 9 of this document.
|
||||||
|
|
||||||
|
"Licensor" shall mean the copyright owner or entity authorized by
|
||||||
|
the copyright owner that is granting the License.
|
||||||
|
|
||||||
|
"Legal Entity" shall mean the union of the acting entity and all
|
||||||
|
other entities that control, are controlled by, or are under common
|
||||||
|
control with that entity. For the purposes of this definition,
|
||||||
|
"control" means (i) the power, direct or indirect, to cause the
|
||||||
|
direction or management of such entity, whether by contract or
|
||||||
|
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||||
|
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||||
|
|
||||||
|
"You" (or "Your") shall mean an individual or Legal Entity
|
||||||
|
exercising permissions granted by this License.
|
||||||
|
|
||||||
|
"Source" form shall mean the preferred form for making modifications,
|
||||||
|
including but not limited to software source code, documentation
|
||||||
|
source, and configuration files.
|
||||||
|
|
||||||
|
"Object" form shall mean any form resulting from mechanical
|
||||||
|
transformation or translation of a Source form, including but
|
||||||
|
not limited to compiled object code, generated documentation,
|
||||||
|
and conversions to other media types.
|
||||||
|
|
||||||
|
"Work" shall mean the work of authorship, whether in Source or
|
||||||
|
Object form, made available under the License, as indicated by a
|
||||||
|
copyright notice that is included in or attached to the work
|
||||||
|
(an example is provided in the Appendix below).
|
||||||
|
|
||||||
|
"Derivative Works" shall mean any work, whether in Source or Object
|
||||||
|
form, that is based on (or derived from) the Work and for which the
|
||||||
|
editorial revisions, annotations, elaborations, or other modifications
|
||||||
|
represent, as a whole, an original work of authorship. For the purposes
|
||||||
|
of this License, Derivative Works shall not include works that remain
|
||||||
|
separable from, or merely link (or bind by name) to the interfaces of,
|
||||||
|
the Work and Derivative Works thereof.
|
||||||
|
|
||||||
|
"Contribution" shall mean any work of authorship, including
|
||||||
|
the original version of the Work and any modifications or additions
|
||||||
|
to that Work or Derivative Works thereof, that is intentionally
|
||||||
|
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||||
|
or by an individual or Legal Entity authorized to submit on behalf of
|
||||||
|
the copyright owner. For the purposes of this definition, "submitted"
|
||||||
|
means any form of electronic, verbal, or written communication sent
|
||||||
|
to the Licensor or its representatives, including but not limited to
|
||||||
|
communication on electronic mailing lists, source code control systems,
|
||||||
|
and issue tracking systems that are managed by, or on behalf of, the
|
||||||
|
Licensor for the purpose of discussing and improving the Work, but
|
||||||
|
excluding communication that is conspicuously marked or otherwise
|
||||||
|
designated in writing by the copyright owner as "Not a Contribution."
|
||||||
|
|
||||||
|
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||||
|
on behalf of whom a Contribution has been received by Licensor and
|
||||||
|
subsequently incorporated within the Work.
|
||||||
|
|
||||||
|
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||||
|
this License, each Contributor hereby grants to You a perpetual,
|
||||||
|
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||||
|
copyright license to reproduce, prepare Derivative Works of,
|
||||||
|
publicly display, publicly perform, sublicense, and distribute the
|
||||||
|
Work and such Derivative Works in Source or Object form.
|
||||||
|
|
||||||
|
3. Grant of Patent License. Subject to the terms and conditions of
|
||||||
|
this License, each Contributor hereby grants to You a perpetual,
|
||||||
|
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||||
|
(except as stated in this section) patent license to make, have made,
|
||||||
|
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||||
|
where such license applies only to those patent claims licensable
|
||||||
|
by such Contributor that are necessarily infringed by their
|
||||||
|
Contribution(s) alone or by combination of their Contribution(s)
|
||||||
|
with the Work to which such Contribution(s) was submitted. If You
|
||||||
|
institute patent litigation against any entity (including a
|
||||||
|
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||||
|
or a Contribution incorporated within the Work constitutes direct
|
||||||
|
or contributory patent infringement, then any patent licenses
|
||||||
|
granted to You under this License for that Work shall terminate
|
||||||
|
as of the date such litigation is filed.
|
||||||
|
|
||||||
|
4. Redistribution. You may reproduce and distribute copies of the
|
||||||
|
Work or Derivative Works thereof in any medium, with or without
|
||||||
|
modifications, and in Source or Object form, provided that You
|
||||||
|
meet the following conditions:
|
||||||
|
|
||||||
|
(a) You must give any other recipients of the Work or
|
||||||
|
Derivative Works a copy of this License; and
|
||||||
|
|
||||||
|
(b) You must cause any modified files to carry prominent notices
|
||||||
|
stating that You changed the files; and
|
||||||
|
|
||||||
|
(c) You must retain, in the Source form of any Derivative Works
|
||||||
|
that You distribute, all copyright, patent, trademark, and
|
||||||
|
attribution notices from the Source form of the Work,
|
||||||
|
excluding those notices that do not pertain to any part of
|
||||||
|
the Derivative Works; and
|
||||||
|
|
||||||
|
(d) If the Work includes a "NOTICE" text file as part of its
|
||||||
|
distribution, then any Derivative Works that You distribute must
|
||||||
|
include a readable copy of the attribution notices contained
|
||||||
|
within such NOTICE file, excluding those notices that do not
|
||||||
|
pertain to any part of the Derivative Works, in at least one
|
||||||
|
of the following places: within a NOTICE text file distributed
|
||||||
|
as part of the Derivative Works; within the Source form or
|
||||||
|
documentation, if provided along with the Derivative Works; or,
|
||||||
|
within a display generated by the Derivative Works, if and
|
||||||
|
wherever such third-party notices normally appear. The contents
|
||||||
|
of the NOTICE file are for informational purposes only and
|
||||||
|
do not modify the License. You may add Your own attribution
|
||||||
|
notices within Derivative Works that You distribute, alongside
|
||||||
|
or as an addendum to the NOTICE text from the Work, provided
|
||||||
|
that such additional attribution notices cannot be construed
|
||||||
|
as modifying the License.
|
||||||
|
|
||||||
|
You may add Your own copyright statement to Your modifications and
|
||||||
|
may provide additional or different license terms and conditions
|
||||||
|
for use, reproduction, or distribution of Your modifications, or
|
||||||
|
for any such Derivative Works as a whole, provided Your use,
|
||||||
|
reproduction, and distribution of the Work otherwise complies with
|
||||||
|
the conditions stated in this License.
|
||||||
|
|
||||||
|
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||||
|
any Contribution intentionally submitted for inclusion in the Work
|
||||||
|
by You to the Licensor shall be under the terms and conditions of
|
||||||
|
this License, without any additional terms or conditions.
|
||||||
|
Notwithstanding the above, nothing herein shall supersede or modify
|
||||||
|
the terms of any separate license agreement you may have executed
|
||||||
|
with Licensor regarding such Contributions.
|
||||||
|
|
||||||
|
6. Trademarks. This License does not grant permission to use the trade
|
||||||
|
names, trademarks, service marks, or product names of the Licensor,
|
||||||
|
except as required for reasonable and customary use in describing the
|
||||||
|
origin of the Work and reproducing the content of the NOTICE file.
|
||||||
|
|
||||||
|
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||||
|
agreed to in writing, Licensor provides the Work (and each
|
||||||
|
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||||
|
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||||
|
implied, including, without limitation, any warranties or conditions
|
||||||
|
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||||
|
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||||
|
appropriateness of using or redistributing the Work and assume any
|
||||||
|
risks associated with Your exercise of permissions under this License.
|
||||||
|
|
||||||
|
8. Limitation of Liability. In no event and under no legal theory,
|
||||||
|
whether in tort (including negligence), contract, or otherwise,
|
||||||
|
unless required by applicable law (such as deliberate and grossly
|
||||||
|
negligent acts) or agreed to in writing, shall any Contributor be
|
||||||
|
liable to You for damages, including any direct, indirect, special,
|
||||||
|
incidental, or consequential damages of any character arising as a
|
||||||
|
result of this License or out of the use or inability to use the
|
||||||
|
Work (including but not limited to damages for loss of goodwill,
|
||||||
|
work stoppage, computer failure or malfunction, or any and all
|
||||||
|
other commercial damages or losses), even if such Contributor
|
||||||
|
has been advised of the possibility of such damages.
|
||||||
|
|
||||||
|
9. Accepting Warranty or Additional Liability. While redistributing
|
||||||
|
the Work or Derivative Works thereof, You may choose to offer,
|
||||||
|
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||||
|
or other liability obligations and/or rights consistent with this
|
||||||
|
License. However, in accepting such obligations, You may act only
|
||||||
|
on Your own behalf and on Your sole responsibility, not on behalf
|
||||||
|
of any other Contributor, and only if You agree to indemnify,
|
||||||
|
defend, and hold each Contributor harmless for any liability
|
||||||
|
incurred by, or claims asserted against, such Contributor by reason
|
||||||
|
of your accepting any such warranty or additional liability.
|
||||||
|
|
||||||
|
END OF TERMS AND CONDITIONS
|
||||||
23
third_party/crates/proc-macro2-1.0.107/LICENSE-MIT
vendored
Normal file
23
third_party/crates/proc-macro2-1.0.107/LICENSE-MIT
vendored
Normal file
@@ -0,0 +1,23 @@
|
|||||||
|
Permission is hereby granted, free of charge, to any
|
||||||
|
person obtaining a copy of this software and associated
|
||||||
|
documentation files (the "Software"), to deal in the
|
||||||
|
Software without restriction, including without
|
||||||
|
limitation the rights to use, copy, modify, merge,
|
||||||
|
publish, distribute, sublicense, and/or sell copies of
|
||||||
|
the Software, and to permit persons to whom the Software
|
||||||
|
is furnished to do so, subject to the following
|
||||||
|
conditions:
|
||||||
|
|
||||||
|
The above copyright notice and this permission notice
|
||||||
|
shall be included in all copies or substantial portions
|
||||||
|
of the Software.
|
||||||
|
|
||||||
|
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF
|
||||||
|
ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED
|
||||||
|
TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A
|
||||||
|
PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT
|
||||||
|
SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY
|
||||||
|
CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION
|
||||||
|
OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR
|
||||||
|
IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER
|
||||||
|
DEALINGS IN THE SOFTWARE.
|
||||||
94
third_party/crates/proc-macro2-1.0.107/README.md
vendored
Normal file
94
third_party/crates/proc-macro2-1.0.107/README.md
vendored
Normal file
@@ -0,0 +1,94 @@
|
|||||||
|
# proc-macro2
|
||||||
|
|
||||||
|
[<img alt="github" src="https://img.shields.io/badge/github-dtolnay/proc--macro2-8da0cb?style=for-the-badge&labelColor=555555&logo=github" height="20">](https://github.com/dtolnay/proc-macro2)
|
||||||
|
[<img alt="crates.io" src="https://img.shields.io/crates/v/proc-macro2.svg?style=for-the-badge&color=fc8d62&logo=rust" height="20">](https://crates.io/crates/proc-macro2)
|
||||||
|
[<img alt="docs.rs" src="https://img.shields.io/badge/docs.rs-proc--macro2-66c2a5?style=for-the-badge&labelColor=555555&logo=docs.rs" height="20">](https://docs.rs/proc-macro2)
|
||||||
|
[<img alt="build status" src="https://img.shields.io/github/actions/workflow/status/dtolnay/proc-macro2/ci.yml?branch=master&style=for-the-badge" height="20">](https://github.com/dtolnay/proc-macro2/actions?query=branch%3Amaster)
|
||||||
|
|
||||||
|
A wrapper around the procedural macro API of the compiler's `proc_macro` crate.
|
||||||
|
This library serves two purposes:
|
||||||
|
|
||||||
|
- **Bring proc-macro-like functionality to other contexts like build.rs and
|
||||||
|
main.rs.** Types from `proc_macro` are entirely specific to procedural macros
|
||||||
|
and cannot ever exist in code outside of a procedural macro. Meanwhile
|
||||||
|
`proc_macro2` types may exist anywhere including non-macro code. By developing
|
||||||
|
foundational libraries like [syn] and [quote] against `proc_macro2` rather
|
||||||
|
than `proc_macro`, the procedural macro ecosystem becomes easily applicable to
|
||||||
|
many other use cases and we avoid reimplementing non-macro equivalents of
|
||||||
|
those libraries.
|
||||||
|
|
||||||
|
- **Make procedural macros unit testable.** As a consequence of being specific
|
||||||
|
to procedural macros, nothing that uses `proc_macro` can be executed from a
|
||||||
|
unit test. In order for helper libraries or components of a macro to be
|
||||||
|
testable in isolation, they must be implemented using `proc_macro2`.
|
||||||
|
|
||||||
|
[syn]: https://github.com/dtolnay/syn
|
||||||
|
[quote]: https://github.com/dtolnay/quote
|
||||||
|
|
||||||
|
## Usage
|
||||||
|
|
||||||
|
```toml
|
||||||
|
[dependencies]
|
||||||
|
proc-macro2 = "1.0"
|
||||||
|
```
|
||||||
|
|
||||||
|
The skeleton of a typical procedural macro typically looks like this:
|
||||||
|
|
||||||
|
```rust
|
||||||
|
extern crate proc_macro;
|
||||||
|
|
||||||
|
#[proc_macro_derive(MyDerive)]
|
||||||
|
pub fn my_derive(input: proc_macro::TokenStream) -> proc_macro::TokenStream {
|
||||||
|
let input = proc_macro2::TokenStream::from(input);
|
||||||
|
|
||||||
|
let output: proc_macro2::TokenStream = {
|
||||||
|
/* transform input */
|
||||||
|
};
|
||||||
|
|
||||||
|
proc_macro::TokenStream::from(output)
|
||||||
|
}
|
||||||
|
```
|
||||||
|
|
||||||
|
If parsing with [Syn], you'll use [`parse_macro_input!`] instead to propagate
|
||||||
|
parse errors correctly back to the compiler when parsing fails.
|
||||||
|
|
||||||
|
[`parse_macro_input!`]: https://docs.rs/syn/3/syn/macro.parse_macro_input.html
|
||||||
|
|
||||||
|
## Unstable features
|
||||||
|
|
||||||
|
The default feature set of proc-macro2 tracks the most recent stable compiler
|
||||||
|
API. Functionality in `proc_macro` that is not yet stable is not exposed by
|
||||||
|
proc-macro2 by default.
|
||||||
|
|
||||||
|
To opt into the additional APIs available in the most recent nightly compiler,
|
||||||
|
the `procmacro2_semver_exempt` config flag must be passed to rustc. We will
|
||||||
|
polyfill those nightly-only APIs back to Rust 1.71.0. As these are unstable APIs
|
||||||
|
that track the nightly compiler, minor versions of proc-macro2 may make breaking
|
||||||
|
changes to them at any time.
|
||||||
|
|
||||||
|
```
|
||||||
|
RUSTFLAGS='--cfg procmacro2_semver_exempt' cargo build
|
||||||
|
```
|
||||||
|
|
||||||
|
Note that this must not only be done for your crate, but for any crate that
|
||||||
|
depends on your crate. This infectious nature is intentional, as it serves as a
|
||||||
|
reminder that you are outside of the normal semver guarantees.
|
||||||
|
|
||||||
|
Semver exempt methods are marked as such in the proc-macro2 documentation.
|
||||||
|
|
||||||
|
<br>
|
||||||
|
|
||||||
|
#### License
|
||||||
|
|
||||||
|
<sup>
|
||||||
|
Licensed under either of <a href="LICENSE-APACHE">Apache License, Version
|
||||||
|
2.0</a> or <a href="LICENSE-MIT">MIT license</a> at your option.
|
||||||
|
</sup>
|
||||||
|
|
||||||
|
<br>
|
||||||
|
|
||||||
|
<sub>
|
||||||
|
Unless you explicitly state otherwise, any contribution intentionally submitted
|
||||||
|
for inclusion in this crate by you, as defined in the Apache-2.0 license, shall
|
||||||
|
be dual licensed as above, without any additional terms or conditions.
|
||||||
|
</sub>
|
||||||
267
third_party/crates/proc-macro2-1.0.107/build.rs
vendored
Normal file
267
third_party/crates/proc-macro2-1.0.107/build.rs
vendored
Normal file
@@ -0,0 +1,267 @@
|
|||||||
|
#![allow(unknown_lints)]
|
||||||
|
#![allow(unexpected_cfgs)]
|
||||||
|
#![allow(clippy::uninlined_format_args)]
|
||||||
|
|
||||||
|
use std::env;
|
||||||
|
use std::ffi::OsString;
|
||||||
|
use std::fs;
|
||||||
|
use std::io::ErrorKind;
|
||||||
|
use std::iter;
|
||||||
|
use std::path::Path;
|
||||||
|
use std::process::{self, Command, Stdio};
|
||||||
|
use std::str;
|
||||||
|
|
||||||
|
fn main() {
|
||||||
|
let rustc = rustc_minor_version().unwrap_or(u32::MAX);
|
||||||
|
|
||||||
|
if rustc >= 80 {
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(fuzzing)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(no_is_available)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(no_literal_byte_character)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(no_literal_c_string)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(no_source_text)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(proc_macro_span)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(proc_macro_span_file)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(proc_macro_span_location)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(procmacro2_backtrace)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(procmacro2_build_probe)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(procmacro2_nightly_testing)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(procmacro2_semver_exempt)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(randomize_layout)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(span_locations)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(super_unstable)");
|
||||||
|
println!("cargo:rustc-check-cfg=cfg(wrap_proc_macro)");
|
||||||
|
}
|
||||||
|
|
||||||
|
let semver_exempt = cfg!(procmacro2_semver_exempt);
|
||||||
|
if semver_exempt {
|
||||||
|
// https://github.com/dtolnay/proc-macro2/issues/147
|
||||||
|
println!("cargo:rustc-cfg=procmacro2_semver_exempt");
|
||||||
|
}
|
||||||
|
|
||||||
|
if semver_exempt || cfg!(feature = "span-locations") {
|
||||||
|
// Provide methods Span::start and Span::end which give the line/column
|
||||||
|
// location of a token. This is behind a cfg because tracking location
|
||||||
|
// inside spans is a performance hit.
|
||||||
|
println!("cargo:rustc-cfg=span_locations");
|
||||||
|
}
|
||||||
|
|
||||||
|
if rustc < 57 {
|
||||||
|
// Do not use proc_macro::is_available() to detect whether the proc
|
||||||
|
// macro API is available vs needs to be polyfilled. Instead, use the
|
||||||
|
// proc macro API unconditionally and catch the panic that occurs if it
|
||||||
|
// isn't available.
|
||||||
|
println!("cargo:rustc-cfg=no_is_available");
|
||||||
|
}
|
||||||
|
|
||||||
|
if rustc < 66 {
|
||||||
|
// Do not call libproc_macro's Span::source_text. Always return None.
|
||||||
|
println!("cargo:rustc-cfg=no_source_text");
|
||||||
|
}
|
||||||
|
|
||||||
|
if rustc < 79 {
|
||||||
|
// Do not call Literal::byte_character nor Literal::c_string. They can
|
||||||
|
// be emulated by way of Literal::from_str.
|
||||||
|
println!("cargo:rustc-cfg=no_literal_byte_character");
|
||||||
|
println!("cargo:rustc-cfg=no_literal_c_string");
|
||||||
|
}
|
||||||
|
|
||||||
|
if !cfg!(feature = "proc-macro") {
|
||||||
|
println!("cargo:rerun-if-changed=build.rs");
|
||||||
|
return;
|
||||||
|
}
|
||||||
|
|
||||||
|
let proc_macro_span;
|
||||||
|
let consider_rustc_bootstrap;
|
||||||
|
if compile_probe_unstable("proc_macro_span", false) {
|
||||||
|
// This is a nightly or dev compiler, so it supports unstable features
|
||||||
|
// regardless of RUSTC_BOOTSTRAP. No need to rerun build script if
|
||||||
|
// RUSTC_BOOTSTRAP is changed.
|
||||||
|
proc_macro_span = true;
|
||||||
|
consider_rustc_bootstrap = false;
|
||||||
|
} else if let Some(rustc_bootstrap) = env::var_os("RUSTC_BOOTSTRAP") {
|
||||||
|
if compile_probe_unstable("proc_macro_span", true) {
|
||||||
|
// This is a stable or beta compiler for which the user has set
|
||||||
|
// RUSTC_BOOTSTRAP to turn on unstable features. Rerun build script
|
||||||
|
// if they change it.
|
||||||
|
proc_macro_span = true;
|
||||||
|
consider_rustc_bootstrap = true;
|
||||||
|
} else if rustc_bootstrap == "1" {
|
||||||
|
// This compiler does not support the proc macro Span API in the
|
||||||
|
// form that proc-macro2 expects. No need to pay attention to
|
||||||
|
// RUSTC_BOOTSTRAP.
|
||||||
|
proc_macro_span = false;
|
||||||
|
consider_rustc_bootstrap = false;
|
||||||
|
} else {
|
||||||
|
// This is a stable or beta compiler for which RUSTC_BOOTSTRAP is
|
||||||
|
// set to restrict the use of unstable features by this crate.
|
||||||
|
proc_macro_span = false;
|
||||||
|
consider_rustc_bootstrap = true;
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
// Without RUSTC_BOOTSTRAP, this compiler does not support the proc
|
||||||
|
// macro Span API in the form that proc-macro2 expects, but try again if
|
||||||
|
// the user turns on unstable features.
|
||||||
|
proc_macro_span = false;
|
||||||
|
consider_rustc_bootstrap = true;
|
||||||
|
}
|
||||||
|
|
||||||
|
if proc_macro_span || !semver_exempt {
|
||||||
|
// Wrap types from libproc_macro rather than polyfilling the whole API.
|
||||||
|
// Enabled as long as procmacro2_semver_exempt is not set, because we
|
||||||
|
// can't emulate the unstable API without emulating everything else.
|
||||||
|
// Also enabled unconditionally on nightly, in which case the
|
||||||
|
// procmacro2_semver_exempt surface area is implemented by using the
|
||||||
|
// nightly-only proc_macro API.
|
||||||
|
println!("cargo:rustc-cfg=wrap_proc_macro");
|
||||||
|
}
|
||||||
|
|
||||||
|
if proc_macro_span {
|
||||||
|
// Enable non-dummy behavior of Span::byte_range and Span::join methods
|
||||||
|
// which requires an unstable compiler feature. Enabled when building
|
||||||
|
// with nightly, unless `-Z allow-feature` in RUSTFLAGS disallows
|
||||||
|
// unstable features.
|
||||||
|
println!("cargo:rustc-cfg=proc_macro_span");
|
||||||
|
}
|
||||||
|
|
||||||
|
if proc_macro_span || (rustc >= 88 && compile_probe_stable("proc_macro_span_location")) {
|
||||||
|
// Enable non-dummy behavior of Span::start and Span::end methods on
|
||||||
|
// Rust 1.88+.
|
||||||
|
println!("cargo:rustc-cfg=proc_macro_span_location");
|
||||||
|
}
|
||||||
|
|
||||||
|
if proc_macro_span || (rustc >= 88 && compile_probe_stable("proc_macro_span_file")) {
|
||||||
|
// Enable non-dummy behavior of Span::file and Span::local_file methods
|
||||||
|
// on Rust 1.88+.
|
||||||
|
println!("cargo:rustc-cfg=proc_macro_span_file");
|
||||||
|
}
|
||||||
|
|
||||||
|
if semver_exempt && proc_macro_span {
|
||||||
|
// Implement the semver exempt API in terms of the nightly-only
|
||||||
|
// proc_macro API.
|
||||||
|
println!("cargo:rustc-cfg=super_unstable");
|
||||||
|
}
|
||||||
|
|
||||||
|
if consider_rustc_bootstrap {
|
||||||
|
println!("cargo:rerun-if-env-changed=RUSTC_BOOTSTRAP");
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn compile_probe_unstable(feature: &str, rustc_bootstrap: bool) -> bool {
|
||||||
|
// RUSTC_STAGE indicates that this crate is being compiled as a dependency
|
||||||
|
// of a multistage rustc bootstrap. This environment uses Cargo in a highly
|
||||||
|
// non-standard way with issues such as:
|
||||||
|
//
|
||||||
|
// https://github.com/rust-lang/cargo/issues/11138
|
||||||
|
// https://github.com/rust-lang/rust/issues/114839
|
||||||
|
//
|
||||||
|
env::var_os("RUSTC_STAGE").is_none() && do_compile_probe(feature, rustc_bootstrap)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn compile_probe_stable(feature: &str) -> bool {
|
||||||
|
env::var_os("RUSTC_STAGE").is_some() || do_compile_probe(feature, true)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn do_compile_probe(feature: &str, rustc_bootstrap: bool) -> bool {
|
||||||
|
println!("cargo:rerun-if-changed=src/probe/{}.rs", feature);
|
||||||
|
|
||||||
|
let rustc = cargo_env_var("RUSTC");
|
||||||
|
let out_dir = cargo_env_var("OUT_DIR");
|
||||||
|
let out_subdir = Path::new(&out_dir).join("probe");
|
||||||
|
let probefile = Path::new("src")
|
||||||
|
.join("probe")
|
||||||
|
.join(feature)
|
||||||
|
.with_extension("rs");
|
||||||
|
|
||||||
|
if let Err(err) = fs::create_dir(&out_subdir) {
|
||||||
|
if err.kind() != ErrorKind::AlreadyExists {
|
||||||
|
eprintln!("Failed to create {}: {}", out_subdir.display(), err);
|
||||||
|
process::exit(1);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
let rustc_wrapper = env::var_os("RUSTC_WRAPPER").filter(|wrapper| !wrapper.is_empty());
|
||||||
|
let rustc_workspace_wrapper =
|
||||||
|
env::var_os("RUSTC_WORKSPACE_WRAPPER").filter(|wrapper| !wrapper.is_empty());
|
||||||
|
let mut rustc = rustc_wrapper
|
||||||
|
.into_iter()
|
||||||
|
.chain(rustc_workspace_wrapper)
|
||||||
|
.chain(iter::once(rustc));
|
||||||
|
let mut cmd = Command::new(rustc.next().unwrap());
|
||||||
|
cmd.args(rustc);
|
||||||
|
|
||||||
|
if !rustc_bootstrap {
|
||||||
|
cmd.env_remove("RUSTC_BOOTSTRAP");
|
||||||
|
}
|
||||||
|
|
||||||
|
cmd.stderr(Stdio::null())
|
||||||
|
.arg("--cfg=procmacro2_build_probe")
|
||||||
|
.arg("--edition=2021")
|
||||||
|
.arg("--crate-name=proc_macro2")
|
||||||
|
.arg("--crate-type=lib")
|
||||||
|
.arg("--cap-lints=allow")
|
||||||
|
.arg("--emit=dep-info,metadata")
|
||||||
|
.arg("--out-dir")
|
||||||
|
.arg(&out_subdir)
|
||||||
|
.arg(probefile);
|
||||||
|
|
||||||
|
if let Some(target) = env::var_os("TARGET") {
|
||||||
|
cmd.arg("--target").arg(target);
|
||||||
|
}
|
||||||
|
|
||||||
|
// If Cargo wants to set RUSTFLAGS, use that.
|
||||||
|
if let Ok(rustflags) = env::var("CARGO_ENCODED_RUSTFLAGS") {
|
||||||
|
if !rustflags.is_empty() {
|
||||||
|
for arg in rustflags.split('\x1f') {
|
||||||
|
cmd.arg(arg);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
let success = match cmd.status() {
|
||||||
|
Ok(status) => status.success(),
|
||||||
|
Err(_) => false,
|
||||||
|
};
|
||||||
|
|
||||||
|
// Clean up to avoid leaving nondeterministic absolute paths in the dep-info
|
||||||
|
// file in OUT_DIR, which causes nonreproducible builds in build systems
|
||||||
|
// that treat the entire OUT_DIR as an artifact.
|
||||||
|
if let Err(err) = fs::remove_dir_all(&out_subdir) {
|
||||||
|
// libc::ENOTEMPTY
|
||||||
|
// Some filesystems (NFSv3) have timing issues under load where '.nfs*'
|
||||||
|
// dummy files can continue to get created for a short period after the
|
||||||
|
// probe command completes, breaking remove_dir_all.
|
||||||
|
// To be replaced with ErrorKind::DirectoryNotEmpty (Rust 1.83+).
|
||||||
|
const ENOTEMPTY: i32 = 39;
|
||||||
|
|
||||||
|
if !(err.kind() == ErrorKind::NotFound
|
||||||
|
|| (cfg!(target_os = "linux") && err.raw_os_error() == Some(ENOTEMPTY)))
|
||||||
|
{
|
||||||
|
eprintln!("Failed to clean up {}: {}", out_subdir.display(), err);
|
||||||
|
process::exit(1);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
success
|
||||||
|
}
|
||||||
|
|
||||||
|
fn rustc_minor_version() -> Option<u32> {
|
||||||
|
let rustc = cargo_env_var("RUSTC");
|
||||||
|
let output = Command::new(rustc).arg("--version").output().ok()?;
|
||||||
|
let version = str::from_utf8(&output.stdout).ok()?;
|
||||||
|
let mut pieces = version.split('.');
|
||||||
|
if pieces.next() != Some("rustc 1") {
|
||||||
|
return None;
|
||||||
|
}
|
||||||
|
pieces.next()?.parse().ok()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn cargo_env_var(key: &str) -> OsString {
|
||||||
|
env::var_os(key).unwrap_or_else(|| {
|
||||||
|
eprintln!(
|
||||||
|
"Environment variable ${} is not set during execution of build script",
|
||||||
|
key,
|
||||||
|
);
|
||||||
|
process::exit(1);
|
||||||
|
})
|
||||||
|
}
|
||||||
2
third_party/crates/proc-macro2-1.0.107/rust-toolchain.toml
vendored
Normal file
2
third_party/crates/proc-macro2-1.0.107/rust-toolchain.toml
vendored
Normal file
@@ -0,0 +1,2 @@
|
|||||||
|
[toolchain]
|
||||||
|
components = ["rust-src"]
|
||||||
75
third_party/crates/proc-macro2-1.0.107/src/detection.rs
vendored
Normal file
75
third_party/crates/proc-macro2-1.0.107/src/detection.rs
vendored
Normal file
@@ -0,0 +1,75 @@
|
|||||||
|
use core::sync::atomic::{AtomicUsize, Ordering};
|
||||||
|
use std::sync::Once;
|
||||||
|
|
||||||
|
static WORKS: AtomicUsize = AtomicUsize::new(0);
|
||||||
|
static INIT: Once = Once::new();
|
||||||
|
|
||||||
|
pub(crate) fn inside_proc_macro() -> bool {
|
||||||
|
match WORKS.load(Ordering::Relaxed) {
|
||||||
|
1 => return false,
|
||||||
|
2 => return true,
|
||||||
|
_ => {}
|
||||||
|
}
|
||||||
|
|
||||||
|
INIT.call_once(initialize);
|
||||||
|
inside_proc_macro()
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn force_fallback() {
|
||||||
|
WORKS.store(1, Ordering::Relaxed);
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn unforce_fallback() {
|
||||||
|
initialize();
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(not(no_is_available))]
|
||||||
|
fn initialize() {
|
||||||
|
let available = proc_macro::is_available();
|
||||||
|
WORKS.store(available as usize + 1, Ordering::Relaxed);
|
||||||
|
}
|
||||||
|
|
||||||
|
// Swap in a null panic hook to avoid printing "thread panicked" to stderr,
|
||||||
|
// then use catch_unwind to determine whether the compiler's proc_macro is
|
||||||
|
// working. When proc-macro2 is used from outside of a procedural macro all
|
||||||
|
// of the proc_macro crate's APIs currently panic.
|
||||||
|
//
|
||||||
|
// The Once is to prevent the possibility of this ordering:
|
||||||
|
//
|
||||||
|
// thread 1 calls take_hook, gets the user's original hook
|
||||||
|
// thread 1 calls set_hook with the null hook
|
||||||
|
// thread 2 calls take_hook, thinks null hook is the original hook
|
||||||
|
// thread 2 calls set_hook with the null hook
|
||||||
|
// thread 1 calls set_hook with the actual original hook
|
||||||
|
// thread 2 calls set_hook with what it thinks is the original hook
|
||||||
|
//
|
||||||
|
// in which the user's hook has been lost.
|
||||||
|
//
|
||||||
|
// There is still a race condition where a panic in a different thread can
|
||||||
|
// happen during the interval that the user's original panic hook is
|
||||||
|
// unregistered such that their hook is incorrectly not called. This is
|
||||||
|
// sufficiently unlikely and less bad than printing panic messages to stderr
|
||||||
|
// on correct use of this crate. Maybe there is a libstd feature request
|
||||||
|
// here. For now, if a user needs to guarantee that this failure mode does
|
||||||
|
// not occur, they need to call e.g. `proc_macro2::Span::call_site()` from
|
||||||
|
// the main thread before launching any other threads.
|
||||||
|
#[cfg(no_is_available)]
|
||||||
|
fn initialize() {
|
||||||
|
use std::panic::{self, PanicInfo};
|
||||||
|
|
||||||
|
type PanicHook = dyn Fn(&PanicInfo) + Sync + Send + 'static;
|
||||||
|
|
||||||
|
let null_hook: Box<PanicHook> = Box::new(|_panic_info| { /* ignore */ });
|
||||||
|
let sanity_check = &*null_hook as *const PanicHook;
|
||||||
|
let original_hook = panic::take_hook();
|
||||||
|
panic::set_hook(null_hook);
|
||||||
|
|
||||||
|
let works = panic::catch_unwind(proc_macro::Span::call_site).is_ok();
|
||||||
|
WORKS.store(works as usize + 1, Ordering::Relaxed);
|
||||||
|
|
||||||
|
let hopefully_null_hook = panic::take_hook();
|
||||||
|
panic::set_hook(original_hook);
|
||||||
|
if sanity_check != &*hopefully_null_hook {
|
||||||
|
panic!("observed race condition in proc_macro2::inside_proc_macro");
|
||||||
|
}
|
||||||
|
}
|
||||||
151
third_party/crates/proc-macro2-1.0.107/src/extra.rs
vendored
Normal file
151
third_party/crates/proc-macro2-1.0.107/src/extra.rs
vendored
Normal file
@@ -0,0 +1,151 @@
|
|||||||
|
//! Items which do not have a correspondence to any API in the proc_macro crate,
|
||||||
|
//! but are necessary to include in proc-macro2.
|
||||||
|
|
||||||
|
use crate::fallback;
|
||||||
|
use crate::imp;
|
||||||
|
use crate::marker::{ProcMacroAutoTraits, MARKER};
|
||||||
|
use crate::Span;
|
||||||
|
use core::fmt::{self, Debug};
|
||||||
|
|
||||||
|
/// Invalidate any `proc_macro2::Span` that exist on the current thread.
|
||||||
|
///
|
||||||
|
/// The implementation of `Span` uses thread-local data structures and this
|
||||||
|
/// function clears them. Calling any method on a `Span` on the current thread
|
||||||
|
/// created prior to the invalidation will return incorrect values or crash.
|
||||||
|
///
|
||||||
|
/// This function is useful for programs that process more than 2<sup>32</sup>
|
||||||
|
/// bytes of Rust source code on the same thread. Just like rustc, proc-macro2
|
||||||
|
/// uses 32-bit source locations, and these wrap around when the total source
|
||||||
|
/// code processed by the same thread exceeds 2<sup>32</sup> bytes (4
|
||||||
|
/// gigabytes). After a wraparound, `Span` methods such as `source_text()` can
|
||||||
|
/// return wrong data.
|
||||||
|
///
|
||||||
|
/// # Example
|
||||||
|
///
|
||||||
|
/// As of late 2023, there is 200 GB of Rust code published on crates.io.
|
||||||
|
/// Looking at just the newest version of every crate, it is 16 GB of code. So a
|
||||||
|
/// workload that involves parsing it all would overflow a 32-bit source
|
||||||
|
/// location unless spans are being invalidated.
|
||||||
|
///
|
||||||
|
/// ```
|
||||||
|
/// use flate2::read::GzDecoder;
|
||||||
|
/// use std::ffi::OsStr;
|
||||||
|
/// use std::io::{BufReader, Read};
|
||||||
|
/// use std::str::FromStr;
|
||||||
|
/// use tar::Archive;
|
||||||
|
///
|
||||||
|
/// rayon::scope(|s| {
|
||||||
|
/// for krate in every_version_of_every_crate() {
|
||||||
|
/// s.spawn(move |_| {
|
||||||
|
/// proc_macro2::extra::invalidate_current_thread_spans();
|
||||||
|
///
|
||||||
|
/// let reader = BufReader::new(krate);
|
||||||
|
/// let tar = GzDecoder::new(reader);
|
||||||
|
/// let mut archive = Archive::new(tar);
|
||||||
|
/// for entry in archive.entries().unwrap() {
|
||||||
|
/// let mut entry = entry.unwrap();
|
||||||
|
/// let path = entry.path().unwrap();
|
||||||
|
/// if path.extension() != Some(OsStr::new("rs")) {
|
||||||
|
/// continue;
|
||||||
|
/// }
|
||||||
|
/// let mut content = String::new();
|
||||||
|
/// entry.read_to_string(&mut content).unwrap();
|
||||||
|
/// match proc_macro2::TokenStream::from_str(&content) {
|
||||||
|
/// Ok(tokens) => {/* ... */},
|
||||||
|
/// Err(_) => continue,
|
||||||
|
/// }
|
||||||
|
/// }
|
||||||
|
/// });
|
||||||
|
/// }
|
||||||
|
/// });
|
||||||
|
/// #
|
||||||
|
/// # fn every_version_of_every_crate() -> Vec<std::fs::File> {
|
||||||
|
/// # Vec::new()
|
||||||
|
/// # }
|
||||||
|
/// ```
|
||||||
|
///
|
||||||
|
/// # Panics
|
||||||
|
///
|
||||||
|
/// This function is not applicable to and will panic if called from a
|
||||||
|
/// procedural macro.
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
#[cfg_attr(docsrs, doc(cfg(feature = "span-locations")))]
|
||||||
|
pub fn invalidate_current_thread_spans() {
|
||||||
|
crate::imp::invalidate_current_thread_spans();
|
||||||
|
}
|
||||||
|
|
||||||
|
/// An object that holds a [`Group`]'s `span_open()` and `span_close()` together
|
||||||
|
/// in a more compact representation than holding those 2 spans individually.
|
||||||
|
///
|
||||||
|
/// [`Group`]: crate::Group
|
||||||
|
#[derive(Copy, Clone)]
|
||||||
|
pub struct DelimSpan {
|
||||||
|
inner: DelimSpanEnum,
|
||||||
|
_marker: ProcMacroAutoTraits,
|
||||||
|
}
|
||||||
|
|
||||||
|
#[derive(Copy, Clone)]
|
||||||
|
enum DelimSpanEnum {
|
||||||
|
#[cfg(wrap_proc_macro)]
|
||||||
|
Compiler {
|
||||||
|
join: proc_macro::Span,
|
||||||
|
open: proc_macro::Span,
|
||||||
|
close: proc_macro::Span,
|
||||||
|
},
|
||||||
|
Fallback(fallback::Span),
|
||||||
|
}
|
||||||
|
|
||||||
|
impl DelimSpan {
|
||||||
|
pub(crate) fn new(group: &imp::Group) -> Self {
|
||||||
|
#[cfg(wrap_proc_macro)]
|
||||||
|
let inner = match group {
|
||||||
|
imp::Group::Compiler(group) => DelimSpanEnum::Compiler {
|
||||||
|
join: group.span(),
|
||||||
|
open: group.span_open(),
|
||||||
|
close: group.span_close(),
|
||||||
|
},
|
||||||
|
imp::Group::Fallback(group) => DelimSpanEnum::Fallback(group.span()),
|
||||||
|
};
|
||||||
|
|
||||||
|
#[cfg(not(wrap_proc_macro))]
|
||||||
|
let inner = DelimSpanEnum::Fallback(group.span());
|
||||||
|
|
||||||
|
DelimSpan {
|
||||||
|
inner,
|
||||||
|
_marker: MARKER,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns a span covering the entire delimited group.
|
||||||
|
pub fn join(&self) -> Span {
|
||||||
|
match &self.inner {
|
||||||
|
#[cfg(wrap_proc_macro)]
|
||||||
|
DelimSpanEnum::Compiler { join, .. } => Span::_new(imp::Span::Compiler(*join)),
|
||||||
|
DelimSpanEnum::Fallback(span) => Span::_new_fallback(*span),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns a span for the opening punctuation of the group only.
|
||||||
|
pub fn open(&self) -> Span {
|
||||||
|
match &self.inner {
|
||||||
|
#[cfg(wrap_proc_macro)]
|
||||||
|
DelimSpanEnum::Compiler { open, .. } => Span::_new(imp::Span::Compiler(*open)),
|
||||||
|
DelimSpanEnum::Fallback(span) => Span::_new_fallback(span.first_byte()),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
/// Returns a span for the closing punctuation of the group only.
|
||||||
|
pub fn close(&self) -> Span {
|
||||||
|
match &self.inner {
|
||||||
|
#[cfg(wrap_proc_macro)]
|
||||||
|
DelimSpanEnum::Compiler { close, .. } => Span::_new(imp::Span::Compiler(*close)),
|
||||||
|
DelimSpanEnum::Fallback(span) => Span::_new_fallback(span.last_byte()),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Debug for DelimSpan {
|
||||||
|
fn fmt(&self, f: &mut fmt::Formatter) -> fmt::Result {
|
||||||
|
Debug::fmt(&self.join(), f)
|
||||||
|
}
|
||||||
|
}
|
||||||
1279
third_party/crates/proc-macro2-1.0.107/src/fallback.rs
vendored
Normal file
1279
third_party/crates/proc-macro2-1.0.107/src/fallback.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
1527
third_party/crates/proc-macro2-1.0.107/src/lib.rs
vendored
Normal file
1527
third_party/crates/proc-macro2-1.0.107/src/lib.rs
vendored
Normal file
File diff suppressed because it is too large
Load Diff
29
third_party/crates/proc-macro2-1.0.107/src/location.rs
vendored
Normal file
29
third_party/crates/proc-macro2-1.0.107/src/location.rs
vendored
Normal file
@@ -0,0 +1,29 @@
|
|||||||
|
use core::cmp::Ordering;
|
||||||
|
|
||||||
|
/// A line-column pair representing the start or end of a `Span`.
|
||||||
|
///
|
||||||
|
/// This type is semver exempt and not exposed by default.
|
||||||
|
#[cfg_attr(docsrs, doc(cfg(feature = "span-locations")))]
|
||||||
|
#[derive(Copy, Clone, Debug, PartialEq, Eq, Hash)]
|
||||||
|
pub struct LineColumn {
|
||||||
|
/// The 1-indexed line in the source file on which the span starts or ends
|
||||||
|
/// (inclusive).
|
||||||
|
pub line: usize,
|
||||||
|
/// The 0-indexed column (in UTF-8 characters) in the source file on which
|
||||||
|
/// the span starts or ends (inclusive).
|
||||||
|
pub column: usize,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl Ord for LineColumn {
|
||||||
|
fn cmp(&self, other: &Self) -> Ordering {
|
||||||
|
self.line
|
||||||
|
.cmp(&other.line)
|
||||||
|
.then(self.column.cmp(&other.column))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
impl PartialOrd for LineColumn {
|
||||||
|
fn partial_cmp(&self, other: &Self) -> Option<Ordering> {
|
||||||
|
Some(self.cmp(other))
|
||||||
|
}
|
||||||
|
}
|
||||||
17
third_party/crates/proc-macro2-1.0.107/src/marker.rs
vendored
Normal file
17
third_party/crates/proc-macro2-1.0.107/src/marker.rs
vendored
Normal file
@@ -0,0 +1,17 @@
|
|||||||
|
use alloc::rc::Rc;
|
||||||
|
use core::marker::PhantomData;
|
||||||
|
use core::panic::{RefUnwindSafe, UnwindSafe};
|
||||||
|
|
||||||
|
// Zero sized marker with the correct set of autotrait impls we want all proc
|
||||||
|
// macro types to have.
|
||||||
|
#[derive(Copy, Clone)]
|
||||||
|
#[cfg_attr(
|
||||||
|
all(procmacro2_semver_exempt, any(not(wrap_proc_macro), super_unstable)),
|
||||||
|
derive(PartialEq, Eq)
|
||||||
|
)]
|
||||||
|
pub(crate) struct ProcMacroAutoTraits(PhantomData<Rc<()>>);
|
||||||
|
|
||||||
|
pub(crate) const MARKER: ProcMacroAutoTraits = ProcMacroAutoTraits(PhantomData);
|
||||||
|
|
||||||
|
impl UnwindSafe for ProcMacroAutoTraits {}
|
||||||
|
impl RefUnwindSafe for ProcMacroAutoTraits {}
|
||||||
17
third_party/crates/proc-macro2-1.0.107/src/num.rs
vendored
Normal file
17
third_party/crates/proc-macro2-1.0.107/src/num.rs
vendored
Normal file
@@ -0,0 +1,17 @@
|
|||||||
|
// TODO: use NonZero<char> in Rust 1.89+
|
||||||
|
#[derive(Copy, Clone, Debug, PartialEq, Eq)]
|
||||||
|
pub struct NonZeroChar(char);
|
||||||
|
|
||||||
|
impl NonZeroChar {
|
||||||
|
pub fn new(ch: char) -> Option<Self> {
|
||||||
|
if ch == '\0' {
|
||||||
|
None
|
||||||
|
} else {
|
||||||
|
Some(NonZeroChar(ch))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
pub fn get(self) -> char {
|
||||||
|
self.0
|
||||||
|
}
|
||||||
|
}
|
||||||
991
third_party/crates/proc-macro2-1.0.107/src/parse.rs
vendored
Normal file
991
third_party/crates/proc-macro2-1.0.107/src/parse.rs
vendored
Normal file
@@ -0,0 +1,991 @@
|
|||||||
|
use crate::fallback::{
|
||||||
|
self, is_ident_continue, is_ident_start, Group, Ident, LexError, Literal, Span, TokenStream,
|
||||||
|
TokenStreamBuilder,
|
||||||
|
};
|
||||||
|
use crate::{Delimiter, Punct, Spacing, TokenTree};
|
||||||
|
use alloc::borrow::ToOwned as _;
|
||||||
|
use alloc::string::ToString as _;
|
||||||
|
use alloc::vec::Vec;
|
||||||
|
use core::char;
|
||||||
|
use core::str::{Bytes, CharIndices, Chars};
|
||||||
|
|
||||||
|
#[derive(Copy, Clone, Eq, PartialEq)]
|
||||||
|
pub(crate) struct Cursor<'a> {
|
||||||
|
pub(crate) rest: &'a str,
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
pub(crate) off: u32,
|
||||||
|
}
|
||||||
|
|
||||||
|
impl<'a> Cursor<'a> {
|
||||||
|
pub(crate) fn advance(&self, bytes: usize) -> Cursor<'a> {
|
||||||
|
let (_front, rest) = self.rest.split_at(bytes);
|
||||||
|
Cursor {
|
||||||
|
rest,
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
off: self.off + _front.chars().count() as u32,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn starts_with(&self, s: &str) -> bool {
|
||||||
|
self.rest.starts_with(s)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn starts_with_char(&self, ch: char) -> bool {
|
||||||
|
self.rest.starts_with(ch)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn starts_with_fn<Pattern>(&self, f: Pattern) -> bool
|
||||||
|
where
|
||||||
|
Pattern: FnMut(char) -> bool,
|
||||||
|
{
|
||||||
|
self.rest.starts_with(f)
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn is_empty(&self) -> bool {
|
||||||
|
self.rest.is_empty()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn len(&self) -> usize {
|
||||||
|
self.rest.len()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn as_bytes(&self) -> &'a [u8] {
|
||||||
|
self.rest.as_bytes()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn bytes(&self) -> Bytes<'a> {
|
||||||
|
self.rest.bytes()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn chars(&self) -> Chars<'a> {
|
||||||
|
self.rest.chars()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn char_indices(&self) -> CharIndices<'a> {
|
||||||
|
self.rest.char_indices()
|
||||||
|
}
|
||||||
|
|
||||||
|
fn parse(&self, tag: &str) -> Result<Cursor<'a>, Reject> {
|
||||||
|
if self.starts_with(tag) {
|
||||||
|
Ok(self.advance(tag.len()))
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) struct Reject;
|
||||||
|
type PResult<'a, O> = Result<(Cursor<'a>, O), Reject>;
|
||||||
|
|
||||||
|
fn skip_whitespace(input: Cursor) -> Cursor {
|
||||||
|
let mut s = input;
|
||||||
|
|
||||||
|
while !s.is_empty() {
|
||||||
|
let byte = s.as_bytes()[0];
|
||||||
|
if byte == b'/' {
|
||||||
|
if s.starts_with("//")
|
||||||
|
&& (!s.starts_with("///") || s.starts_with("////"))
|
||||||
|
&& !s.starts_with("//!")
|
||||||
|
{
|
||||||
|
let (cursor, _) = take_until_newline_or_eof(s);
|
||||||
|
s = cursor;
|
||||||
|
continue;
|
||||||
|
} else if s.starts_with("/**/") {
|
||||||
|
s = s.advance(4);
|
||||||
|
continue;
|
||||||
|
} else if s.starts_with("/*")
|
||||||
|
&& (!s.starts_with("/**") || s.starts_with("/***"))
|
||||||
|
&& !s.starts_with("/*!")
|
||||||
|
{
|
||||||
|
match block_comment(s) {
|
||||||
|
Ok((rest, _)) => {
|
||||||
|
s = rest;
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
Err(Reject) => return s,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
match byte {
|
||||||
|
b' ' | 0x09..=0x0d => {
|
||||||
|
s = s.advance(1);
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
b if b.is_ascii() => {}
|
||||||
|
_ => {
|
||||||
|
let ch = s.chars().next().unwrap();
|
||||||
|
if is_whitespace(ch) {
|
||||||
|
s = s.advance(ch.len_utf8());
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
return s;
|
||||||
|
}
|
||||||
|
s
|
||||||
|
}
|
||||||
|
|
||||||
|
fn block_comment(input: Cursor) -> PResult<&str> {
|
||||||
|
if !input.starts_with("/*") {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
|
||||||
|
let mut depth = 0usize;
|
||||||
|
let bytes = input.as_bytes();
|
||||||
|
let mut i = 0usize;
|
||||||
|
let upper = bytes.len() - 1;
|
||||||
|
|
||||||
|
while i < upper {
|
||||||
|
if bytes[i] == b'/' && bytes[i + 1] == b'*' {
|
||||||
|
depth += 1;
|
||||||
|
i += 1; // eat '*'
|
||||||
|
} else if bytes[i] == b'*' && bytes[i + 1] == b'/' {
|
||||||
|
depth -= 1;
|
||||||
|
if depth == 0 {
|
||||||
|
return Ok((input.advance(i + 2), &input.rest[..i + 2]));
|
||||||
|
}
|
||||||
|
i += 1; // eat '/'
|
||||||
|
}
|
||||||
|
i += 1;
|
||||||
|
}
|
||||||
|
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn is_whitespace(ch: char) -> bool {
|
||||||
|
// Rust treats left-to-right mark and right-to-left mark as whitespace
|
||||||
|
ch.is_whitespace() || ch == '\u{200e}' || ch == '\u{200f}'
|
||||||
|
}
|
||||||
|
|
||||||
|
fn word_break(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
match input.chars().next() {
|
||||||
|
Some(ch) if is_ident_continue(ch) => Err(Reject),
|
||||||
|
Some(_) | None => Ok(input),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
// Rustc's representation of a macro expansion error in expression position or
|
||||||
|
// type position.
|
||||||
|
const ERROR: &str = "(/*ERROR*/)";
|
||||||
|
|
||||||
|
pub(crate) fn token_stream(mut input: Cursor) -> Result<TokenStream, LexError> {
|
||||||
|
let mut tokens = TokenStreamBuilder::new();
|
||||||
|
let mut stack = Vec::new();
|
||||||
|
|
||||||
|
loop {
|
||||||
|
input = skip_whitespace(input);
|
||||||
|
|
||||||
|
if let Ok((rest, ())) = doc_comment(input, &mut tokens) {
|
||||||
|
input = rest;
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
let lo = input.off;
|
||||||
|
|
||||||
|
let Some(first) = input.bytes().next() else {
|
||||||
|
return match stack.last() {
|
||||||
|
None => Ok(tokens.build()),
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
Some((lo, _frame)) => Err(LexError {
|
||||||
|
span: Span { lo: *lo, hi: *lo },
|
||||||
|
}),
|
||||||
|
#[cfg(not(span_locations))]
|
||||||
|
Some(_frame) => Err(LexError { span: Span {} }),
|
||||||
|
};
|
||||||
|
};
|
||||||
|
|
||||||
|
if let Some(open_delimiter) = match first {
|
||||||
|
b'(' if !input.starts_with(ERROR) => Some(Delimiter::Parenthesis),
|
||||||
|
b'[' => Some(Delimiter::Bracket),
|
||||||
|
b'{' => Some(Delimiter::Brace),
|
||||||
|
_ => None,
|
||||||
|
} {
|
||||||
|
input = input.advance(1);
|
||||||
|
let frame = (open_delimiter, tokens);
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
let frame = (lo, frame);
|
||||||
|
stack.push(frame);
|
||||||
|
tokens = TokenStreamBuilder::new();
|
||||||
|
} else if let Some(close_delimiter) = match first {
|
||||||
|
b')' => Some(Delimiter::Parenthesis),
|
||||||
|
b']' => Some(Delimiter::Bracket),
|
||||||
|
b'}' => Some(Delimiter::Brace),
|
||||||
|
_ => None,
|
||||||
|
} {
|
||||||
|
let Some(frame) = stack.pop() else {
|
||||||
|
return Err(lex_error(input));
|
||||||
|
};
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
let (lo, frame) = frame;
|
||||||
|
let (open_delimiter, outer) = frame;
|
||||||
|
if open_delimiter != close_delimiter {
|
||||||
|
return Err(lex_error(input));
|
||||||
|
}
|
||||||
|
input = input.advance(1);
|
||||||
|
let mut g = Group::new(open_delimiter, tokens.build());
|
||||||
|
g.set_span(Span {
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
lo,
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
hi: input.off,
|
||||||
|
});
|
||||||
|
tokens = outer;
|
||||||
|
tokens.push_token_from_parser(TokenTree::Group(crate::Group::_new_fallback(g)));
|
||||||
|
} else {
|
||||||
|
let (rest, mut tt) = match leaf_token(input) {
|
||||||
|
Ok((rest, tt)) => (rest, tt),
|
||||||
|
Err(Reject) => return Err(lex_error(input)),
|
||||||
|
};
|
||||||
|
tt.set_span(crate::Span::_new_fallback(Span {
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
lo,
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
hi: rest.off,
|
||||||
|
}));
|
||||||
|
tokens.push_token_from_parser(tt);
|
||||||
|
input = rest;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn lex_error(cursor: Cursor) -> LexError {
|
||||||
|
#[cfg(not(span_locations))]
|
||||||
|
let _ = cursor;
|
||||||
|
LexError {
|
||||||
|
span: Span {
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
lo: cursor.off,
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
hi: cursor.off,
|
||||||
|
},
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn leaf_token(input: Cursor) -> PResult<TokenTree> {
|
||||||
|
if let Ok((input, l)) = literal(input) {
|
||||||
|
// must be parsed before ident
|
||||||
|
Ok((input, TokenTree::Literal(crate::Literal::_new_fallback(l))))
|
||||||
|
} else if let Ok((input, p)) = punct(input) {
|
||||||
|
Ok((input, TokenTree::Punct(p)))
|
||||||
|
} else if let Ok((input, i)) = ident(input) {
|
||||||
|
Ok((input, TokenTree::Ident(i)))
|
||||||
|
} else if input.starts_with(ERROR) {
|
||||||
|
let rest = input.advance(ERROR.len());
|
||||||
|
let repr = crate::Literal::_new_fallback(Literal::_new(ERROR.to_owned()));
|
||||||
|
Ok((rest, TokenTree::Literal(repr)))
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn ident(input: Cursor) -> PResult<crate::Ident> {
|
||||||
|
if [
|
||||||
|
"r\"", "r#\"", "r##", "b\"", "b\'", "br\"", "br#", "c\"", "cr\"", "cr#",
|
||||||
|
]
|
||||||
|
.iter()
|
||||||
|
.any(|prefix| input.starts_with(prefix))
|
||||||
|
{
|
||||||
|
Err(Reject)
|
||||||
|
} else {
|
||||||
|
ident_any(input)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn ident_any(input: Cursor) -> PResult<crate::Ident> {
|
||||||
|
let raw = input.starts_with("r#");
|
||||||
|
let rest = input.advance((raw as usize) << 1);
|
||||||
|
|
||||||
|
let (rest, sym) = ident_not_raw(rest)?;
|
||||||
|
|
||||||
|
if !raw {
|
||||||
|
let ident =
|
||||||
|
crate::Ident::_new_fallback(Ident::new_unchecked(sym, fallback::Span::call_site()));
|
||||||
|
return Ok((rest, ident));
|
||||||
|
}
|
||||||
|
|
||||||
|
match sym {
|
||||||
|
"_" | "super" | "self" | "Self" | "crate" => return Err(Reject),
|
||||||
|
_ => {}
|
||||||
|
}
|
||||||
|
|
||||||
|
let ident =
|
||||||
|
crate::Ident::_new_fallback(Ident::new_raw_unchecked(sym, fallback::Span::call_site()));
|
||||||
|
Ok((rest, ident))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn ident_not_raw(input: Cursor) -> PResult<&str> {
|
||||||
|
let mut chars = input.char_indices();
|
||||||
|
|
||||||
|
match chars.next() {
|
||||||
|
Some((_, ch)) if is_ident_start(ch) => {}
|
||||||
|
_ => return Err(Reject),
|
||||||
|
}
|
||||||
|
|
||||||
|
let mut end = input.len();
|
||||||
|
for (i, ch) in chars {
|
||||||
|
if !is_ident_continue(ch) {
|
||||||
|
end = i;
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
Ok((input.advance(end), &input.rest[..end]))
|
||||||
|
}
|
||||||
|
|
||||||
|
pub(crate) fn literal(input: Cursor) -> PResult<Literal> {
|
||||||
|
let rest = literal_nocapture(input)?;
|
||||||
|
let end = input.len() - rest.len();
|
||||||
|
Ok((rest, Literal::_new(input.rest[..end].to_string())))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn literal_nocapture(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
if let Ok(ok) = string(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else if let Ok(ok) = byte_string(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else if let Ok(ok) = c_string(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else if let Ok(ok) = byte(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else if let Ok(ok) = character(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else if let Ok(ok) = float(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else if let Ok(ok) = int(input) {
|
||||||
|
Ok(ok)
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn literal_suffix(input: Cursor) -> Cursor {
|
||||||
|
match ident_not_raw(input) {
|
||||||
|
Ok((input, _)) => input,
|
||||||
|
Err(Reject) => input,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn string(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
if let Ok(input) = input.parse("\"") {
|
||||||
|
cooked_string(input)
|
||||||
|
} else if let Ok(input) = input.parse("r") {
|
||||||
|
raw_string(input)
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn cooked_string(mut input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let mut chars = input.char_indices();
|
||||||
|
|
||||||
|
while let Some((i, ch)) = chars.next() {
|
||||||
|
match ch {
|
||||||
|
'"' => {
|
||||||
|
let input = input.advance(i + 1);
|
||||||
|
return Ok(literal_suffix(input));
|
||||||
|
}
|
||||||
|
'\r' => match chars.next() {
|
||||||
|
Some((_, '\n')) => {}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
'\\' => match chars.next() {
|
||||||
|
Some((_, 'x')) => {
|
||||||
|
backslash_x_char(&mut chars)?;
|
||||||
|
}
|
||||||
|
Some((_, 'n' | 'r' | 't' | '\\' | '\'' | '"' | '0')) => {}
|
||||||
|
Some((_, 'u')) => {
|
||||||
|
backslash_u(&mut chars)?;
|
||||||
|
}
|
||||||
|
Some((newline, ch @ ('\n' | '\r'))) => {
|
||||||
|
input = input.advance(newline + 1);
|
||||||
|
trailing_backslash(&mut input, ch as u8)?;
|
||||||
|
chars = input.char_indices();
|
||||||
|
}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
_ch => {}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn raw_string(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let (input, delimiter) = delimiter_of_raw_string(input)?;
|
||||||
|
let mut bytes = input.bytes().enumerate();
|
||||||
|
while let Some((i, byte)) = bytes.next() {
|
||||||
|
match byte {
|
||||||
|
b'"' if input.rest[i + 1..].starts_with(delimiter) => {
|
||||||
|
let rest = input.advance(i + 1 + delimiter.len());
|
||||||
|
return Ok(literal_suffix(rest));
|
||||||
|
}
|
||||||
|
b'\r' => match bytes.next() {
|
||||||
|
Some((_, b'\n')) => {}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
_ => {}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn byte_string(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
if let Ok(input) = input.parse("b\"") {
|
||||||
|
cooked_byte_string(input)
|
||||||
|
} else if let Ok(input) = input.parse("br") {
|
||||||
|
raw_byte_string(input)
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn cooked_byte_string(mut input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let mut bytes = input.bytes().enumerate();
|
||||||
|
while let Some((offset, b)) = bytes.next() {
|
||||||
|
match b {
|
||||||
|
b'"' => {
|
||||||
|
let input = input.advance(offset + 1);
|
||||||
|
return Ok(literal_suffix(input));
|
||||||
|
}
|
||||||
|
b'\r' => match bytes.next() {
|
||||||
|
Some((_, b'\n')) => {}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
b'\\' => match bytes.next() {
|
||||||
|
Some((_, b'x')) => {
|
||||||
|
backslash_x_byte(&mut bytes)?;
|
||||||
|
}
|
||||||
|
Some((_, b'n' | b'r' | b't' | b'\\' | b'0' | b'\'' | b'"')) => {}
|
||||||
|
Some((newline, b @ (b'\n' | b'\r'))) => {
|
||||||
|
input = input.advance(newline + 1);
|
||||||
|
trailing_backslash(&mut input, b)?;
|
||||||
|
bytes = input.bytes().enumerate();
|
||||||
|
}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
b if b.is_ascii() => {}
|
||||||
|
_ => break,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn delimiter_of_raw_string(input: Cursor) -> PResult<&str> {
|
||||||
|
for (i, byte) in input.bytes().enumerate() {
|
||||||
|
match byte {
|
||||||
|
b'"' => {
|
||||||
|
if i > 255 {
|
||||||
|
// https://github.com/rust-lang/rust/pull/95251
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
return Ok((input.advance(i + 1), &input.rest[..i]));
|
||||||
|
}
|
||||||
|
b'#' => {}
|
||||||
|
_ => break,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn raw_byte_string(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let (input, delimiter) = delimiter_of_raw_string(input)?;
|
||||||
|
let mut bytes = input.bytes().enumerate();
|
||||||
|
while let Some((i, byte)) = bytes.next() {
|
||||||
|
match byte {
|
||||||
|
b'"' if input.rest[i + 1..].starts_with(delimiter) => {
|
||||||
|
let rest = input.advance(i + 1 + delimiter.len());
|
||||||
|
return Ok(literal_suffix(rest));
|
||||||
|
}
|
||||||
|
b'\r' => match bytes.next() {
|
||||||
|
Some((_, b'\n')) => {}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
other => {
|
||||||
|
if !other.is_ascii() {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn c_string(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
if let Ok(input) = input.parse("c\"") {
|
||||||
|
cooked_c_string(input)
|
||||||
|
} else if let Ok(input) = input.parse("cr") {
|
||||||
|
raw_c_string(input)
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn raw_c_string(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let (input, delimiter) = delimiter_of_raw_string(input)?;
|
||||||
|
let mut bytes = input.bytes().enumerate();
|
||||||
|
while let Some((i, byte)) = bytes.next() {
|
||||||
|
match byte {
|
||||||
|
b'"' if input.rest[i + 1..].starts_with(delimiter) => {
|
||||||
|
let rest = input.advance(i + 1 + delimiter.len());
|
||||||
|
return Ok(literal_suffix(rest));
|
||||||
|
}
|
||||||
|
b'\r' => match bytes.next() {
|
||||||
|
Some((_, b'\n')) => {}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
b'\0' => break,
|
||||||
|
_ => {}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn cooked_c_string(mut input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let mut chars = input.char_indices();
|
||||||
|
|
||||||
|
while let Some((i, ch)) = chars.next() {
|
||||||
|
match ch {
|
||||||
|
'"' => {
|
||||||
|
let input = input.advance(i + 1);
|
||||||
|
return Ok(literal_suffix(input));
|
||||||
|
}
|
||||||
|
'\r' => match chars.next() {
|
||||||
|
Some((_, '\n')) => {}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
'\\' => match chars.next() {
|
||||||
|
Some((_, 'x')) => {
|
||||||
|
backslash_x_nonzero(&mut chars)?;
|
||||||
|
}
|
||||||
|
Some((_, 'n' | 'r' | 't' | '\\' | '\'' | '"')) => {}
|
||||||
|
Some((_, 'u')) => {
|
||||||
|
if backslash_u(&mut chars)? == '\0' {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Some((newline, ch @ ('\n' | '\r'))) => {
|
||||||
|
input = input.advance(newline + 1);
|
||||||
|
trailing_backslash(&mut input, ch as u8)?;
|
||||||
|
chars = input.char_indices();
|
||||||
|
}
|
||||||
|
_ => break,
|
||||||
|
},
|
||||||
|
'\0' => break,
|
||||||
|
_ch => {}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn byte(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let input = input.parse("b'")?;
|
||||||
|
let mut bytes = input.bytes().enumerate();
|
||||||
|
let ok = match bytes.next().map(|(_, b)| b) {
|
||||||
|
Some(b'\\') => match bytes.next().map(|(_, b)| b) {
|
||||||
|
Some(b'x') => backslash_x_byte(&mut bytes).is_ok(),
|
||||||
|
Some(b'n' | b'r' | b't' | b'\\' | b'0' | b'\'' | b'"') => true,
|
||||||
|
_ => false,
|
||||||
|
},
|
||||||
|
b => b.is_some(),
|
||||||
|
};
|
||||||
|
if !ok {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
let (offset, _) = bytes.next().ok_or(Reject)?;
|
||||||
|
if !input.chars().as_str().is_char_boundary(offset) {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
let input = input.advance(offset).parse("'")?;
|
||||||
|
Ok(literal_suffix(input))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn character(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let input = input.parse("'")?;
|
||||||
|
let mut chars = input.char_indices();
|
||||||
|
let ok = match chars.next().map(|(_, ch)| ch) {
|
||||||
|
Some('\\') => match chars.next().map(|(_, ch)| ch) {
|
||||||
|
Some('x') => backslash_x_char(&mut chars).is_ok(),
|
||||||
|
Some('u') => backslash_u(&mut chars).is_ok(),
|
||||||
|
Some('n' | 'r' | 't' | '\\' | '0' | '\'' | '"') => true,
|
||||||
|
_ => false,
|
||||||
|
},
|
||||||
|
ch => ch.is_some(),
|
||||||
|
};
|
||||||
|
if !ok {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
let (idx, _) = chars.next().ok_or(Reject)?;
|
||||||
|
let input = input.advance(idx).parse("'")?;
|
||||||
|
Ok(literal_suffix(input))
|
||||||
|
}
|
||||||
|
|
||||||
|
macro_rules! next_ch {
|
||||||
|
($chars:ident @ $pat:pat) => {
|
||||||
|
match $chars.next() {
|
||||||
|
Some((_, ch)) => match ch {
|
||||||
|
$pat => ch,
|
||||||
|
_ => return Err(Reject),
|
||||||
|
},
|
||||||
|
None => return Err(Reject),
|
||||||
|
}
|
||||||
|
};
|
||||||
|
}
|
||||||
|
|
||||||
|
fn backslash_x_char<I>(chars: &mut I) -> Result<(), Reject>
|
||||||
|
where
|
||||||
|
I: Iterator<Item = (usize, char)>,
|
||||||
|
{
|
||||||
|
next_ch!(chars @ '0'..='7');
|
||||||
|
next_ch!(chars @ '0'..='9' | 'a'..='f' | 'A'..='F');
|
||||||
|
Ok(())
|
||||||
|
}
|
||||||
|
|
||||||
|
fn backslash_x_byte<I>(chars: &mut I) -> Result<(), Reject>
|
||||||
|
where
|
||||||
|
I: Iterator<Item = (usize, u8)>,
|
||||||
|
{
|
||||||
|
next_ch!(chars @ b'0'..=b'9' | b'a'..=b'f' | b'A'..=b'F');
|
||||||
|
next_ch!(chars @ b'0'..=b'9' | b'a'..=b'f' | b'A'..=b'F');
|
||||||
|
Ok(())
|
||||||
|
}
|
||||||
|
|
||||||
|
fn backslash_x_nonzero<I>(chars: &mut I) -> Result<(), Reject>
|
||||||
|
where
|
||||||
|
I: Iterator<Item = (usize, char)>,
|
||||||
|
{
|
||||||
|
let first = next_ch!(chars @ '0'..='9' | 'a'..='f' | 'A'..='F');
|
||||||
|
let second = next_ch!(chars @ '0'..='9' | 'a'..='f' | 'A'..='F');
|
||||||
|
if first == '0' && second == '0' {
|
||||||
|
Err(Reject)
|
||||||
|
} else {
|
||||||
|
Ok(())
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn backslash_u<I>(chars: &mut I) -> Result<char, Reject>
|
||||||
|
where
|
||||||
|
I: Iterator<Item = (usize, char)>,
|
||||||
|
{
|
||||||
|
next_ch!(chars @ '{');
|
||||||
|
let mut value = 0;
|
||||||
|
let mut len = 0;
|
||||||
|
for (_, ch) in chars {
|
||||||
|
let digit = match ch {
|
||||||
|
'0'..='9' => ch as u8 - b'0',
|
||||||
|
'a'..='f' => 10 + ch as u8 - b'a',
|
||||||
|
'A'..='F' => 10 + ch as u8 - b'A',
|
||||||
|
'_' if len > 0 => continue,
|
||||||
|
'}' if len > 0 => return char::from_u32(value).ok_or(Reject),
|
||||||
|
_ => break,
|
||||||
|
};
|
||||||
|
if len == 6 {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
value *= 0x10;
|
||||||
|
value += u32::from(digit);
|
||||||
|
len += 1;
|
||||||
|
}
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn trailing_backslash(input: &mut Cursor, mut last: u8) -> Result<(), Reject> {
|
||||||
|
let mut whitespace = input.bytes().enumerate();
|
||||||
|
loop {
|
||||||
|
if last == b'\r' && whitespace.next().map_or(true, |(_, b)| b != b'\n') {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
match whitespace.next() {
|
||||||
|
Some((_, b @ (b' ' | b'\t' | b'\n' | b'\r'))) => {
|
||||||
|
last = b;
|
||||||
|
}
|
||||||
|
Some((offset, _)) => {
|
||||||
|
*input = input.advance(offset);
|
||||||
|
return Ok(());
|
||||||
|
}
|
||||||
|
None => return Err(Reject),
|
||||||
|
}
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn float(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let mut rest = float_digits(input)?;
|
||||||
|
if let Some(ch) = rest.chars().next() {
|
||||||
|
if is_ident_start(ch) {
|
||||||
|
rest = ident_not_raw(rest)?.0;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
word_break(rest)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn float_digits(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let mut chars = input.chars().peekable();
|
||||||
|
match chars.next() {
|
||||||
|
Some(ch) if '0' <= ch && ch <= '9' => {}
|
||||||
|
_ => return Err(Reject),
|
||||||
|
}
|
||||||
|
|
||||||
|
let mut len = 1;
|
||||||
|
let mut has_dot = false;
|
||||||
|
let mut has_exp = false;
|
||||||
|
while let Some(&ch) = chars.peek() {
|
||||||
|
match ch {
|
||||||
|
'0'..='9' | '_' => {
|
||||||
|
chars.next();
|
||||||
|
len += 1;
|
||||||
|
}
|
||||||
|
'.' => {
|
||||||
|
if has_dot {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
chars.next();
|
||||||
|
if chars
|
||||||
|
.peek()
|
||||||
|
.is_some_and(|&ch| ch == '.' || is_ident_start(ch))
|
||||||
|
{
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
len += 1;
|
||||||
|
has_dot = true;
|
||||||
|
}
|
||||||
|
'e' | 'E' => {
|
||||||
|
chars.next();
|
||||||
|
len += 1;
|
||||||
|
has_exp = true;
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
_ => break,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
if !(has_dot || has_exp) {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
|
||||||
|
if has_exp {
|
||||||
|
let token_before_exp = if has_dot {
|
||||||
|
Ok(input.advance(len - 1))
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
};
|
||||||
|
let mut has_sign = false;
|
||||||
|
let mut has_exp_value = false;
|
||||||
|
while let Some(&ch) = chars.peek() {
|
||||||
|
match ch {
|
||||||
|
'+' | '-' => {
|
||||||
|
if has_exp_value {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
if has_sign {
|
||||||
|
return token_before_exp;
|
||||||
|
}
|
||||||
|
chars.next();
|
||||||
|
len += 1;
|
||||||
|
has_sign = true;
|
||||||
|
}
|
||||||
|
'0'..='9' => {
|
||||||
|
chars.next();
|
||||||
|
len += 1;
|
||||||
|
has_exp_value = true;
|
||||||
|
}
|
||||||
|
'_' => {
|
||||||
|
chars.next();
|
||||||
|
len += 1;
|
||||||
|
}
|
||||||
|
_ => break,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
if !has_exp_value {
|
||||||
|
return token_before_exp;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
Ok(input.advance(len))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn int(input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let mut rest = digits(input)?;
|
||||||
|
if let Some(ch) = rest.chars().next() {
|
||||||
|
if is_ident_start(ch) {
|
||||||
|
rest = ident_not_raw(rest)?.0;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
word_break(rest)
|
||||||
|
}
|
||||||
|
|
||||||
|
fn digits(mut input: Cursor) -> Result<Cursor, Reject> {
|
||||||
|
let base = if input.starts_with("0x") {
|
||||||
|
input = input.advance(2);
|
||||||
|
16
|
||||||
|
} else if input.starts_with("0o") {
|
||||||
|
input = input.advance(2);
|
||||||
|
8
|
||||||
|
} else if input.starts_with("0b") {
|
||||||
|
input = input.advance(2);
|
||||||
|
2
|
||||||
|
} else {
|
||||||
|
10
|
||||||
|
};
|
||||||
|
|
||||||
|
let mut len = 0;
|
||||||
|
let mut empty = true;
|
||||||
|
for b in input.bytes() {
|
||||||
|
match b {
|
||||||
|
b'0'..=b'9' => {
|
||||||
|
let digit = (b - b'0') as u64;
|
||||||
|
if digit >= base {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
b'a'..=b'f' => {
|
||||||
|
let digit = 10 + (b - b'a') as u64;
|
||||||
|
if digit >= base {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
b'A'..=b'F' => {
|
||||||
|
let digit = 10 + (b - b'A') as u64;
|
||||||
|
if digit >= base {
|
||||||
|
break;
|
||||||
|
}
|
||||||
|
}
|
||||||
|
b'_' => {
|
||||||
|
if empty && base == 10 {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
len += 1;
|
||||||
|
continue;
|
||||||
|
}
|
||||||
|
_ => break,
|
||||||
|
}
|
||||||
|
len += 1;
|
||||||
|
empty = false;
|
||||||
|
}
|
||||||
|
if empty {
|
||||||
|
Err(Reject)
|
||||||
|
} else {
|
||||||
|
Ok(input.advance(len))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn punct(input: Cursor) -> PResult<Punct> {
|
||||||
|
let (rest, ch) = punct_char(input)?;
|
||||||
|
if ch == '\'' {
|
||||||
|
let (after_lifetime, _ident) = ident_any(rest)?;
|
||||||
|
if after_lifetime.starts_with_char('\'')
|
||||||
|
|| (after_lifetime.starts_with_char('#') && !rest.starts_with("r#"))
|
||||||
|
{
|
||||||
|
Err(Reject)
|
||||||
|
} else {
|
||||||
|
Ok((rest, Punct::new('\'', Spacing::Joint)))
|
||||||
|
}
|
||||||
|
} else {
|
||||||
|
let kind = match punct_char(rest) {
|
||||||
|
Ok(_) => Spacing::Joint,
|
||||||
|
Err(Reject) => Spacing::Alone,
|
||||||
|
};
|
||||||
|
Ok((rest, Punct::new(ch, kind)))
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn punct_char(input: Cursor) -> PResult<char> {
|
||||||
|
if input.starts_with("//") || input.starts_with("/*") {
|
||||||
|
// Do not accept `/` of a comment as a punct.
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
|
||||||
|
let mut chars = input.chars();
|
||||||
|
let Some(first) = chars.next() else {
|
||||||
|
return Err(Reject);
|
||||||
|
};
|
||||||
|
let recognized = "~!@#$%^&*-=+|;:,<.>/?'";
|
||||||
|
if recognized.contains(first) {
|
||||||
|
Ok((input.advance(first.len_utf8()), first))
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn doc_comment<'a>(input: Cursor<'a>, tokens: &mut TokenStreamBuilder) -> PResult<'a, ()> {
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
let lo = input.off;
|
||||||
|
let (rest, (comment, inner)) = doc_comment_contents(input)?;
|
||||||
|
let fallback_span = Span {
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
lo,
|
||||||
|
#[cfg(span_locations)]
|
||||||
|
hi: rest.off,
|
||||||
|
};
|
||||||
|
let span = crate::Span::_new_fallback(fallback_span);
|
||||||
|
|
||||||
|
let mut scan_for_bare_cr = comment;
|
||||||
|
while let Some(cr) = scan_for_bare_cr.find('\r') {
|
||||||
|
let rest = &scan_for_bare_cr[cr + 1..];
|
||||||
|
if !rest.starts_with('\n') {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
scan_for_bare_cr = rest;
|
||||||
|
}
|
||||||
|
|
||||||
|
let mut pound = Punct::new('#', Spacing::Alone);
|
||||||
|
pound.set_span(span);
|
||||||
|
tokens.push_token_from_parser(TokenTree::Punct(pound));
|
||||||
|
|
||||||
|
if inner {
|
||||||
|
let mut bang = Punct::new('!', Spacing::Alone);
|
||||||
|
bang.set_span(span);
|
||||||
|
tokens.push_token_from_parser(TokenTree::Punct(bang));
|
||||||
|
}
|
||||||
|
|
||||||
|
let doc_ident = crate::Ident::_new_fallback(Ident::new_unchecked("doc", fallback_span));
|
||||||
|
let mut equal = Punct::new('=', Spacing::Alone);
|
||||||
|
equal.set_span(span);
|
||||||
|
let mut literal = crate::Literal::_new_fallback(Literal::string(comment));
|
||||||
|
literal.set_span(span);
|
||||||
|
let mut bracketed = TokenStreamBuilder::with_capacity(3);
|
||||||
|
bracketed.push_token_from_parser(TokenTree::Ident(doc_ident));
|
||||||
|
bracketed.push_token_from_parser(TokenTree::Punct(equal));
|
||||||
|
bracketed.push_token_from_parser(TokenTree::Literal(literal));
|
||||||
|
let group = Group::new(Delimiter::Bracket, bracketed.build());
|
||||||
|
let mut group = crate::Group::_new_fallback(group);
|
||||||
|
group.set_span(span);
|
||||||
|
tokens.push_token_from_parser(TokenTree::Group(group));
|
||||||
|
|
||||||
|
Ok((rest, ()))
|
||||||
|
}
|
||||||
|
|
||||||
|
fn doc_comment_contents(input: Cursor) -> PResult<(&str, bool)> {
|
||||||
|
if input.starts_with("//!") {
|
||||||
|
let input = input.advance(3);
|
||||||
|
let (input, s) = take_until_newline_or_eof(input);
|
||||||
|
Ok((input, (s, true)))
|
||||||
|
} else if input.starts_with("/*!") {
|
||||||
|
let (input, s) = block_comment(input)?;
|
||||||
|
Ok((input, (&s[3..s.len() - 2], true)))
|
||||||
|
} else if input.starts_with("///") {
|
||||||
|
let input = input.advance(3);
|
||||||
|
if input.starts_with_char('/') {
|
||||||
|
return Err(Reject);
|
||||||
|
}
|
||||||
|
let (input, s) = take_until_newline_or_eof(input);
|
||||||
|
Ok((input, (s, false)))
|
||||||
|
} else if input.starts_with("/**") && !input.rest[3..].starts_with('*') {
|
||||||
|
let (input, s) = block_comment(input)?;
|
||||||
|
Ok((input, (&s[3..s.len() - 2], false)))
|
||||||
|
} else {
|
||||||
|
Err(Reject)
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
fn take_until_newline_or_eof(input: Cursor) -> (Cursor, &str) {
|
||||||
|
let chars = input.char_indices();
|
||||||
|
|
||||||
|
for (i, ch) in chars {
|
||||||
|
if ch == '\n' {
|
||||||
|
return (input.advance(i), &input.rest[..i]);
|
||||||
|
} else if ch == '\r' && input.rest[i + 1..].starts_with('\n') {
|
||||||
|
return (input.advance(i + 1), &input.rest[..i]);
|
||||||
|
}
|
||||||
|
}
|
||||||
|
|
||||||
|
(input.advance(input.len()), input.rest)
|
||||||
|
}
|
||||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user