//! [![github]](https://github.com/dtolnay/zmij) [![crates-io]](https://crates.io/crates/zmij) [![docs-rs]](https://docs.rs/zmij)
//!
//! [github]: https://img.shields.io/badge/github-8da0cb?style=for-the-badge&labelColor=555555&logo=github
//! [crates-io]: https://img.shields.io/badge/crates.io-fc8d62?style=for-the-badge&labelColor=555555&logo=rust
//! [docs-rs]: https://img.shields.io/badge/docs.rs-66c2a5?style=for-the-badge&labelColor=555555&logo=docs.rs
//!
//!
//!
//! A double-to-string conversion algorithm based on [Schubfach] and [yy].
//!
//! This Rust implementation is a line-by-line port of Victor Zverovich's
//! implementation in C++, .
//!
//! [Schubfach]: https://fmt.dev/papers/Schubfach4.pdf
//! [yy]: https://github.com/ibireme/c_numconv_benchmark/blob/master/vendor/yy_double/yy_double.c
//!
//!
//!
//! # Example
//!
//! ```
//! fn main() {
//! let mut buffer = zmij::Buffer::new();
//! let printed = buffer.format(1.234);
//! assert_eq!(printed, "1.234");
//! }
//! ```
//!
//!
//!
//! ## Performance
//!
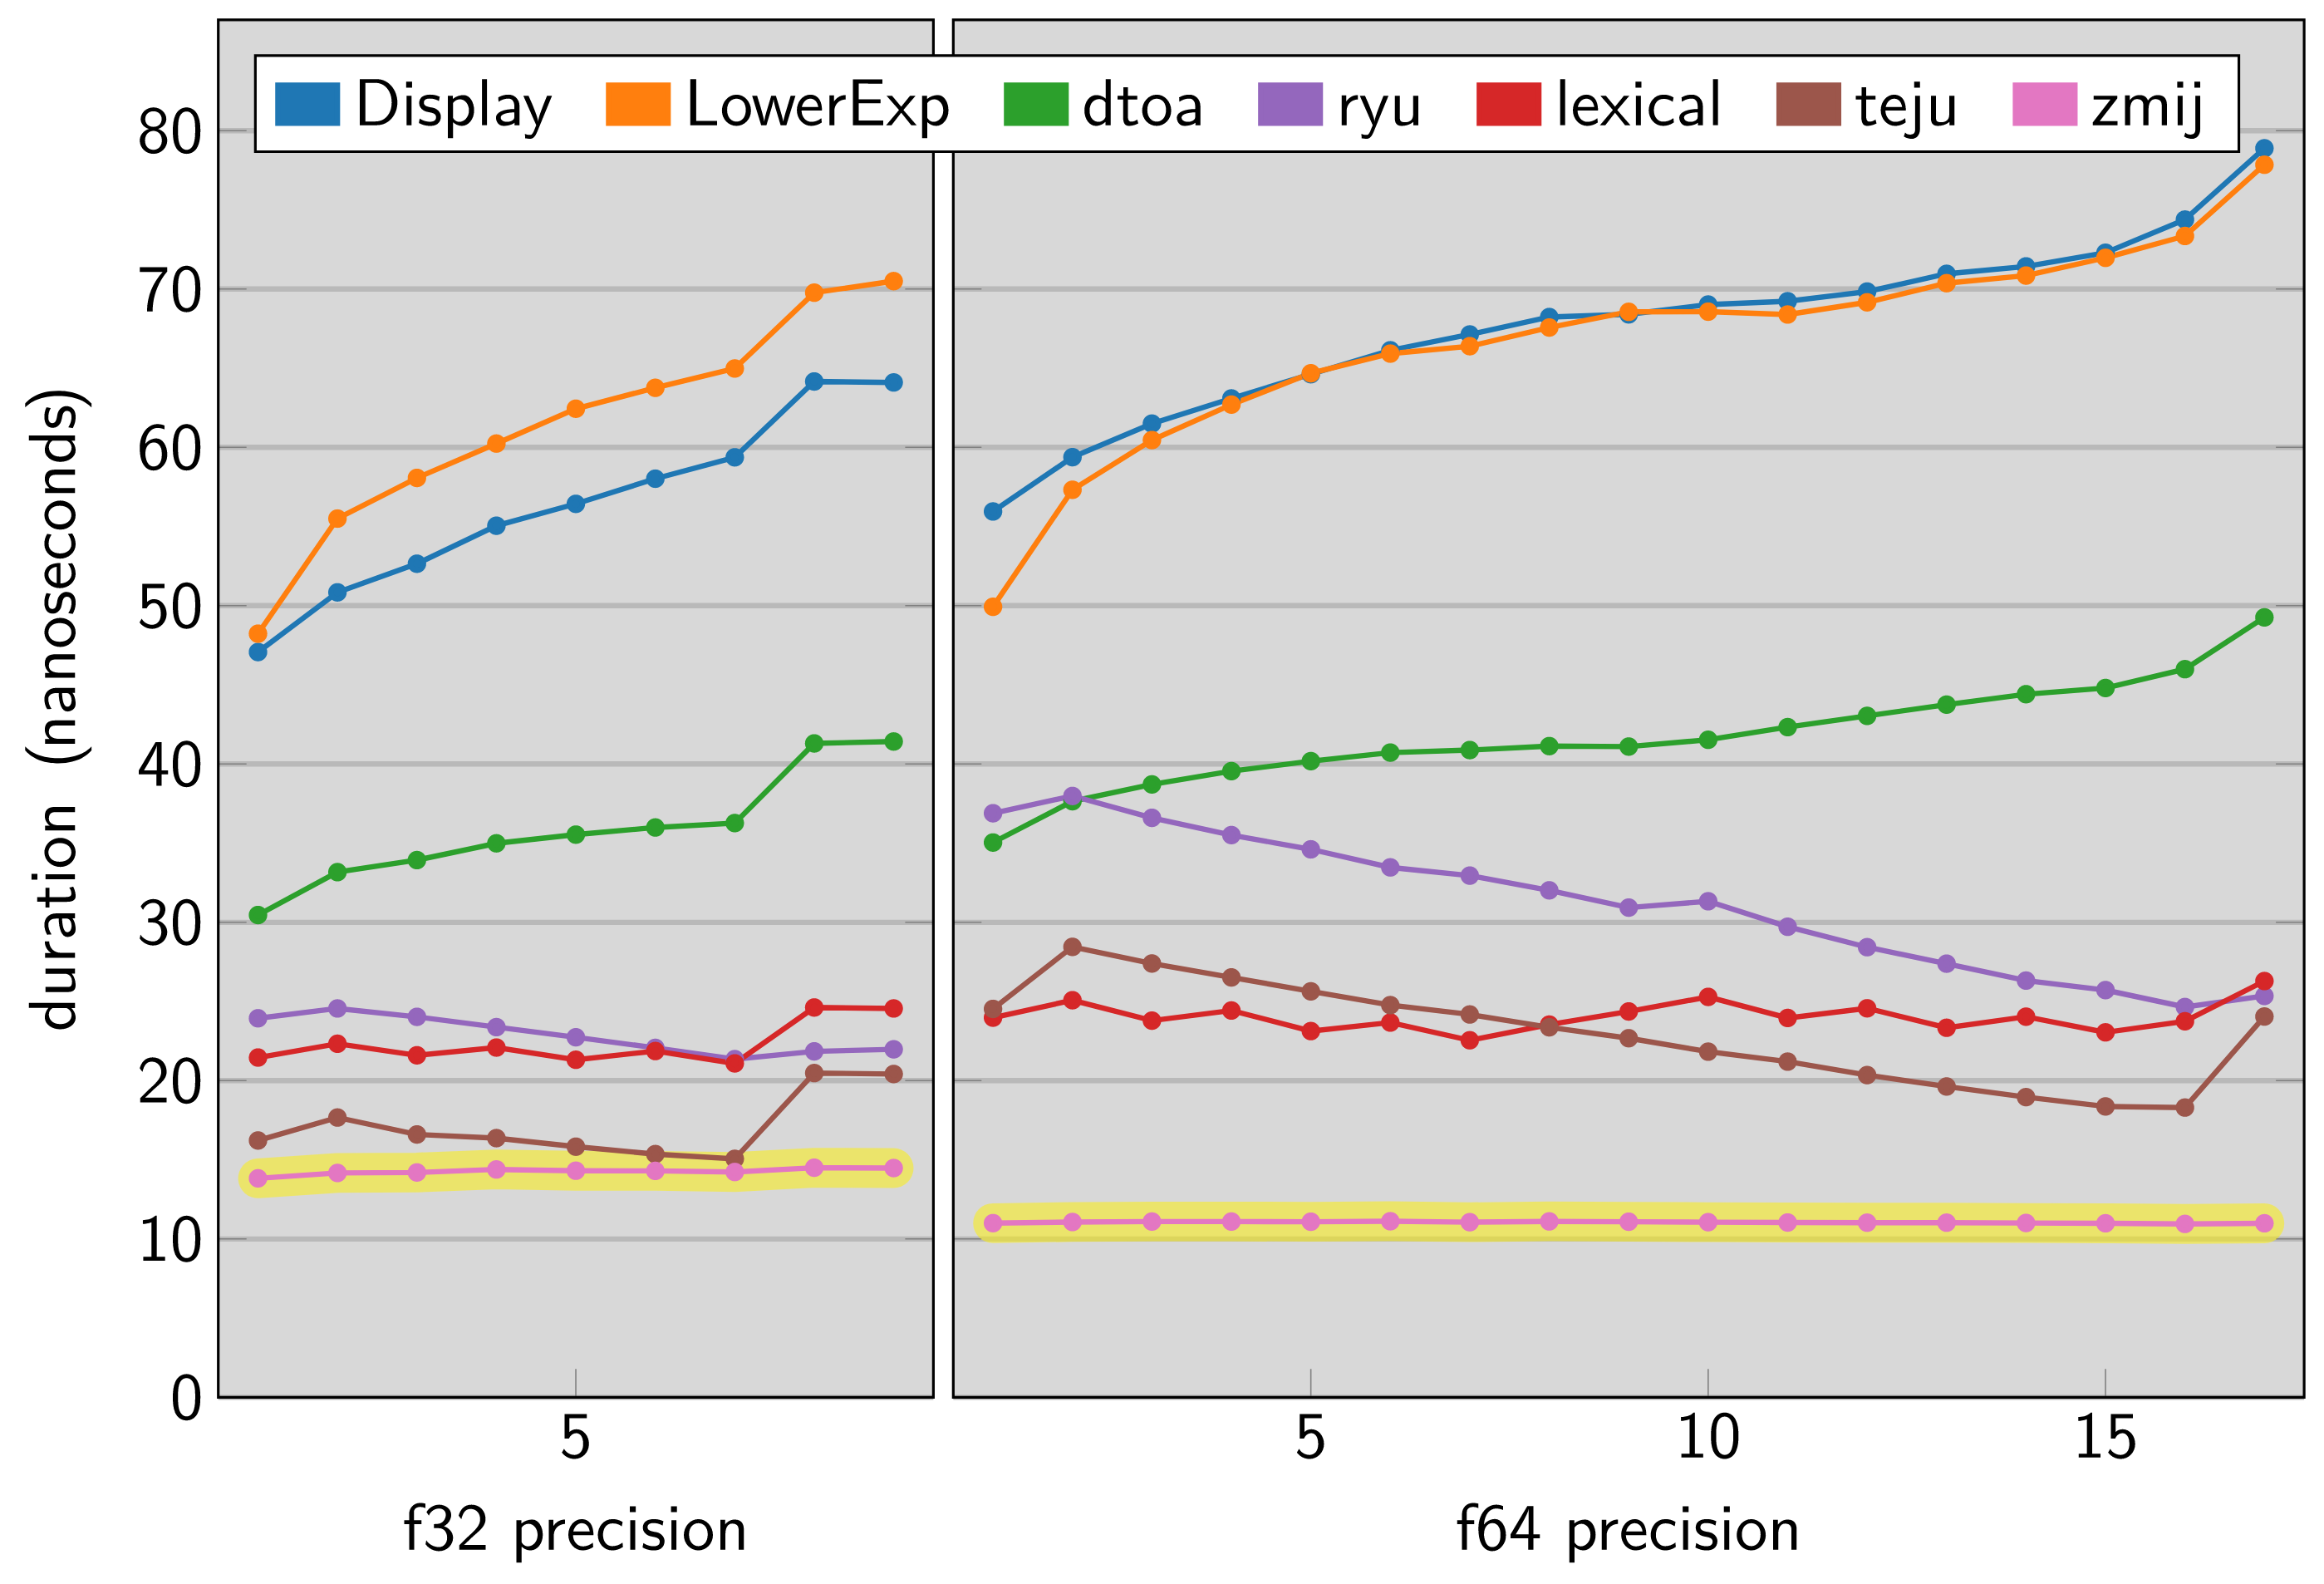
//! The [dtoa-benchmark] compares this library and other Rust floating point
//! formatting implementations across a range of precisions. The vertical axis
//! in this chart shows nanoseconds taken by a single execution of
//! `zmij::Buffer::new().format_finite(value)` so a lower result indicates a
//! faster library.
//!
//! [dtoa-benchmark]: https://github.com/dtolnay/dtoa-benchmark
//!
//! 
#![no_std]
#![doc(html_root_url = "https://docs.rs/zmij/1.0.23")]
#![deny(unsafe_op_in_unsafe_fn)]
#![allow(non_camel_case_types, non_snake_case)]
#![allow(
clippy::blocks_in_conditions,
clippy::cast_possible_truncation,
clippy::cast_possible_wrap,
clippy::cast_ptr_alignment,
clippy::cast_sign_loss,
clippy::doc_markdown,
clippy::incompatible_msrv,
clippy::items_after_statements,
clippy::manual_ilog2,
clippy::many_single_char_names,
clippy::modulo_one,
clippy::must_use_candidate,
clippy::needless_doctest_main,
clippy::needless_late_init,
clippy::never_loop,
clippy::redundant_else,
clippy::similar_names,
clippy::too_many_arguments,
clippy::too_many_lines,
clippy::unreadable_literal,
clippy::used_underscore_items,
clippy::while_immutable_condition,
clippy::wildcard_imports
)]
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
mod stdarch_x86;
#[cfg(test)]
mod tests;
mod traits;
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
use crate::stdarch_x86::{
__m128i, _mm_add_epi64, _mm_cmpgt_epi8, _mm_cvtsi128_si64, _mm_load_si128, _mm_movemask_epi8,
_mm_mul_epu32, _mm_mulhi_epu16, _mm_mullo_epi16, _mm_or_si128, _mm_set_epi64x,
_mm_setzero_si128, _mm_srli_epi64,
};
#[cfg(all(
target_arch = "x86_64",
target_feature = "sse2",
target_feature = "sse4.1",
not(miri)
))]
use crate::stdarch_x86::{
_mm_insert_epi64, _mm_mullo_epi32, _mm_shuffle_epi8, _mm_srli_epi32, _mm_storeu_si128,
};
#[cfg(all(
target_arch = "x86_64",
target_feature = "sse2",
not(target_feature = "sse4.1"),
not(miri)
))]
use crate::stdarch_x86::{
_mm_shuffle_epi32, _mm_slli_epi16, _mm_slli_epi32, _mm_srli_epi16, _mm_sub_epi16, _MM_SHUFFLE,
};
use crate::traits::Float as _;
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
use core::arch::aarch64::{
int16x8_t, int32x2_t, int32x4_t, uint16x8_t, uint64x1_t, uint8x16_t, vaddq_u16, vcgtzq_s8,
vcombine_s32, vcreate_u64, vdup_n_s32, vdupq_n_s8, vdupq_n_u8, vget_lane_u64, vget_low_u8,
vld1q_u8, vmla_n_s32, vmlaq_n_s16, vmlaq_n_s32, vorrq_u8, vqdmulh_n_s32, vqdmulhq_n_s16,
vqdmulhq_n_s32, vqtbl1q_u8, vreinterpret_s32_u32, vreinterpret_s32_u64, vreinterpret_u16_s32,
vreinterpret_u32_s32, vreinterpret_u64_u8, vreinterpretq_s16_s32, vreinterpretq_s32_u32,
vreinterpretq_s8_u8, vreinterpretq_u16_s8, vreinterpretq_u16_u8, vreinterpretq_u64_u8,
vreinterpretq_u8_s16, vreinterpretq_u8_u64, vrev64q_u8, vsetq_lane_u64, vshll_n_u16,
vshr_n_u32, vshrn_n_u16, vst1q_u8,
};
#[cfg(all(any(target_arch = "aarch64", target_arch = "x86_64"), not(miri)))]
use core::arch::asm;
use core::mem::{self, MaybeUninit};
use core::ops::RangeInclusive;
use core::ptr;
use core::slice;
use core::str;
#[cfg(feature = "no-panic")]
use no_panic::no_panic;
const BUFFER_SIZE: usize = 24;
const NAN: &str = "NaN";
const INFINITY: &str = "inf";
const NEG_INFINITY: &str = "-inf";
// Declares struct members that must live in memory on ARM64 but are encoded as
// immediates in the x64 assembly.
struct AArch64Mem {
#[cfg(target_arch = "aarch64")]
value: u64,
}
impl AArch64Mem {
const fn new() -> Self {
AArch64Mem {
#[cfg(target_arch = "aarch64")]
value: VALUE,
}
}
#[cfg_attr(not(target_arch = "aarch64"), allow(clippy::unused_self))]
const fn get(&self) -> u64 {
#[cfg(target_arch = "aarch64")]
{
self.value
}
#[cfg(not(target_arch = "aarch64"))]
{
VALUE
}
}
}
#[derive(Copy, Clone)]
#[cfg_attr(test, derive(Debug, PartialEq))]
struct uint128 {
hi: u64,
lo: u64,
}
// Use umul128_hi64 for division.
const USE_UMUL128_HI64: bool = cfg!(target_vendor = "apple");
// Computes 128-bit result of multiplication of two 64-bit unsigned integers.
const fn umul128(x: u64, y: u64) -> u128 {
x as u128 * y as u128
}
#[inline]
const fn umul128_hi64(x: u64, y: u64) -> u64 {
(umul128(x, y) >> 64) as u64
}
// Returns (x * y + c) >> 64.
#[cfg_attr(feature = "no-panic", no_panic)]
fn umul128_add_hi64(x: u64, y: u64, c: u64) -> u64 {
((u128::from(x) * u128::from(y) + u128::from(c)) >> 64) as u64
}
#[cfg_attr(feature = "no-panic", no_panic)]
fn umul192_hi128(x_hi: u64, x_lo: u64, y: u64) -> uint128 {
let p = umul128(x_hi, y);
let lo = (p as u64).wrapping_add((umul128(x_lo, y) >> 64) as u64);
uint128 {
hi: (p >> 64) as u64 + u64::from(lo < p as u64),
lo,
}
}
// Returns x / 10 for x <= 2**62.
#[cfg_attr(feature = "no-panic", no_panic)]
fn div10(x: u64) -> u64 {
debug_assert!(x < (1 << 62));
// ceil(2**64 / 10) computed as (1 << 63) / 5 + 1 to avoid int128.
const DIV10_SIG64: u64 = (1 << 63) / 5 + 1;
umul128_hi64(x, DIV10_SIG64)
}
// Computes the decimal exponent as floor(log10(2**bin_exp)) if regular or
// floor(log10(3/4 * 2**bin_exp)) otherwise, without branching.
const fn compute_dec_exp(bin_exp: i32, regular: bool) -> i32 {
debug_assert!(bin_exp >= -1334 && bin_exp <= 2620);
// log10_3_over_4_sig = -log10(3/4) * 2**log10_2_exp rounded to a power of 2
const LOG10_3_OVER_4_SIG: i32 = 131_072;
// log10_2_sig = round(log10(2) * 2**log10_2_exp)
const LOG10_2_SIG: i32 = 315_653;
const LOG10_2_EXP: i32 = 20;
(bin_exp * LOG10_2_SIG - !regular as i32 * LOG10_3_OVER_4_SIG) >> LOG10_2_EXP
}
trait FloatTraits: traits::Float {
// Note: Rust port uses wider fixed-notation ranges than upstream.
const FIXED_DEC_EXP: RangeInclusive;
const NUM_BITS: i32;
const NUM_SIG_BITS: i32 = Self::MANTISSA_DIGITS as i32 - 1;
const NUM_EXP_BITS: i32 = Self::NUM_BITS - Self::NUM_SIG_BITS - 1;
const EXP_MASK: i32 = (1 << Self::NUM_EXP_BITS) - 1;
const EXP_BIAS: i32 = (1 << (Self::NUM_EXP_BITS - 1)) - 1;
const EXP_OFFSET: i32 = Self::EXP_BIAS + Self::NUM_SIG_BITS;
type SigType: traits::UInt;
const IMPLICIT_BIT: Self::SigType;
type DecDigitsType: Copy;
#[cfg(any(
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
))]
type DecUnshuffledType;
fn to_bits(self) -> Self::SigType;
fn is_negative(bits: Self::SigType) -> bool {
(bits >> (Self::NUM_BITS - 1)) != Self::SigType::from(0)
}
fn get_sig(bits: Self::SigType) -> Self::SigType {
bits & (Self::IMPLICIT_BIT - Self::SigType::from(1))
}
fn get_exp(bits: Self::SigType) -> i64 {
(bits << 1u8 >> (Self::NUM_SIG_BITS + 1)).into() as i64
}
// Converts a significand to a string, removing trailing zeros. value has up
// to 17 decimal digits (16-17 for normals) for f64 and up to 9 digits (8-9
// for normals) for f32.
fn to_digits(value: u64, d: &Data) -> DecDigits;
unsafe fn write_exp_float_simd(
buffer: *mut u8,
dig: &DecDigits,
last_digit: i32,
has_last_digit: bool,
has_extra_digit: bool,
exp_data: u64,
d: &Data,
) -> *mut u8;
}
impl FloatTraits for f32 {
// Upstream uses -4..=6.
const FIXED_DEC_EXP: RangeInclusive = -6..=12;
const NUM_BITS: i32 = 32;
const IMPLICIT_BIT: u32 = 1 << Self::NUM_SIG_BITS;
type SigType = u32;
type DecDigitsType = u64;
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
type DecUnshuffledType = uint8x16_t;
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
type DecUnshuffledType = __m128i;
#[inline]
fn to_bits(self) -> Self::SigType {
self.to_bits()
}
#[inline]
fn to_digits(value: u64, d: &Data) -> DecDigits {
to_digits_32(value, d)
}
#[inline]
unsafe fn write_exp_float_simd(
buffer: *mut u8,
dig: &DecDigits,
last_digit: i32,
has_last_digit: bool,
has_extra_digit: bool,
exp_data: u64,
d: &Data,
) -> *mut u8 {
unsafe {
write_exp_float_simd_32(
buffer,
dig,
last_digit,
has_last_digit,
has_extra_digit,
exp_data,
d,
)
}
}
}
impl FloatTraits for f64 {
// Upstream uses -4..=15.
const FIXED_DEC_EXP: RangeInclusive = -5..=15;
const NUM_BITS: i32 = 64;
const IMPLICIT_BIT: u64 = 1 << Self::NUM_SIG_BITS;
type SigType = u64;
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
type DecDigitsType = uint16x8_t;
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
type DecDigitsType = __m128i;
#[cfg(not(any(
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
all(target_arch = "x86_64", target_feature = "sse2", not(miri)),
)))]
type DecDigitsType = [u64; 2];
#[cfg(any(
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
))]
type DecUnshuffledType = ();
#[inline]
fn to_bits(self) -> Self::SigType {
self.to_bits()
}
#[inline]
fn to_digits(value: u64, d: &Data) -> DecDigits {
to_digits_64(value, d)
}
#[inline]
unsafe fn write_exp_float_simd(
_buffer: *mut u8,
_dig: &DecDigits,
_last_digit: i32,
_has_last_digit: bool,
_has_extra_digit: bool,
_exp_data: u64,
_d: &Data,
) -> *mut u8 {
ptr::null_mut()
}
}
#[rustfmt::skip]
const POW10_MINOR: [u64; 28] = [
0x8000000000000000, 0xa000000000000000, 0xc800000000000000,
0xfa00000000000000, 0x9c40000000000000, 0xc350000000000000,
0xf424000000000000, 0x9896800000000000, 0xbebc200000000000,
0xee6b280000000000, 0x9502f90000000000, 0xba43b74000000000,
0xe8d4a51000000000, 0x9184e72a00000000, 0xb5e620f480000000,
0xe35fa931a0000000, 0x8e1bc9bf04000000, 0xb1a2bc2ec5000000,
0xde0b6b3a76400000, 0x8ac7230489e80000, 0xad78ebc5ac620000,
0xd8d726b7177a8000, 0x878678326eac9000, 0xa968163f0a57b400,
0xd3c21bcecceda100, 0x84595161401484a0, 0xa56fa5b99019a5c8,
0xcecb8f27f4200f3a,
];
#[rustfmt::skip]
const POW10_MAJOR: [uint128; 23] = [
uint128 { hi: 0xaf8e5410288e1b6f, lo: 0x07ecf0ae5ee44dda }, // -303
uint128 { hi: 0xb1442798f49ffb4a, lo: 0x99cd11cfdf41779d }, // -275
uint128 { hi: 0xb2fe3f0b8599ef07, lo: 0x861fa7e6dcb4aa15 }, // -247
uint128 { hi: 0xb4bca50b065abe63, lo: 0x0fed077a756b53aa }, // -219
uint128 { hi: 0xb67f6455292cbf08, lo: 0x1a3bc84c17b1d543 }, // -191
uint128 { hi: 0xb84687c269ef3bfb, lo: 0x3d5d514f40eea742 }, // -163
uint128 { hi: 0xba121a4650e4ddeb, lo: 0x92f34d62616ce413 }, // -135
uint128 { hi: 0xbbe226efb628afea, lo: 0x890489f70a55368c }, // -107
uint128 { hi: 0xbdb6b8e905cb600f, lo: 0x5400e987bbc1c921 }, // -79
uint128 { hi: 0xbf8fdb78849a5f96, lo: 0xde98520472bdd034 }, // -51
uint128 { hi: 0xc16d9a0095928a27, lo: 0x75b7053c0f178294 }, // -23
uint128 { hi: 0xc350000000000000, lo: 0x0000000000000000 }, // 5
uint128 { hi: 0xc5371912364ce305, lo: 0x6c28000000000000 }, // 33
uint128 { hi: 0xc722f0ef9d80aad6, lo: 0x424d3ad2b7b97ef6 }, // 61
uint128 { hi: 0xc913936dd571c84c, lo: 0x03bc3a19cd1e38ea }, // 89
uint128 { hi: 0xcb090c8001ab551c, lo: 0x5cadf5bfd3072cc6 }, // 117
uint128 { hi: 0xcd036837130890a1, lo: 0x36dba887c37a8c10 }, // 145
uint128 { hi: 0xcf02b2c21207ef2e, lo: 0x94f967e45e03f4bc }, // 173
uint128 { hi: 0xd106f86e69d785c7, lo: 0xe13336d701beba52 }, // 201
uint128 { hi: 0xd31045a8341ca07c, lo: 0x1ede48111209a051 }, // 229
uint128 { hi: 0xd51ea6fa85785631, lo: 0x552a74227f3ea566 }, // 257
uint128 { hi: 0xd732290fbacaf133, lo: 0xa97c177947ad4096 }, // 285
uint128 { hi: 0xd94ad8b1c7380874, lo: 0x18375281ae7822bc }, // 313
];
#[rustfmt::skip]
const POW10_FIXUPS: [u32; 20] = [
0x0a4e363f, 0x00001840, 0x00006400, 0x24200040, 0x00000000,
0x0c000000, 0x82c81380, 0x5e4ce01f, 0xd730f60f, 0x0000001b,
0x00000000, 0xcdf7fffc, 0x6e8201d8, 0x40cd3fd1, 0xdb642501,
0x00000d0d, 0x14042400, 0x53713840, 0x11781db4, 0x00000000,
];
// 128-bit significands of powers of 10 rounded down.
#[repr(C, align(64))]
struct Pow10SignificandTable {
data: [u64; if Self::COMPRESS {
0
} else {
Self::NUM_POW10S * 2
}],
}
impl Pow10SignificandTable {
const COMPRESS: bool = cfg!(opt_level = "s");
const SPLIT_TABLES: bool = !Self::COMPRESS && cfg!(target_arch = "aarch64");
const NUM_POW10S: usize = 618;
// Computes the 128-bit significand of 10**i using method by Dougall Johnson.
#[inline]
const fn compute(i: u32) -> uint128 {
const STRIDE: u32 = POW10_MINOR.len() as u32;
let m = unsafe { *POW10_MINOR.as_ptr().add(((i + 10) % STRIDE) as usize) };
let h = unsafe { *POW10_MAJOR.as_ptr().add(((i + 10) / STRIDE) as usize) };
let h1 = umul128_hi64(h.lo, m);
let c0 = h.lo.wrapping_mul(m);
let c1 = h1.wrapping_add(h.hi.wrapping_mul(m));
let c2 = (c1 < h1) as u64 + umul128_hi64(h.hi, m);
let mut result = if (c2 >> 63) != 0 {
uint128 { hi: c2, lo: c1 }
} else {
uint128 {
hi: (c2 << 1) | (c1 >> 63),
lo: (c1 << 1) | (c0 >> 63),
}
};
result.lo -=
((unsafe { *POW10_FIXUPS.as_ptr().add((i >> 5) as usize) } >> (i & 31)) & 1) as u64;
result
}
const fn new() -> Self {
let mut data = [0; if Self::COMPRESS {
0
} else {
Self::NUM_POW10S * 2
}];
let mut i = 0;
while i < Self::NUM_POW10S && !Self::COMPRESS {
let result = Self::compute(i as u32);
if Self::SPLIT_TABLES {
data[Self::NUM_POW10S - i - 1] = result.hi;
data[Self::NUM_POW10S * 2 - i - 1] = result.lo;
} else {
data[i * 2] = result.hi;
data[i * 2 + 1] = result.lo;
}
i += 1;
}
Pow10SignificandTable { data }
}
#[inline]
unsafe fn get_unchecked(&self, dec_exp: i32) -> uint128 {
const DEC_EXP_MIN: i32 = -293;
let i = dec_exp - DEC_EXP_MIN;
if Self::COMPRESS {
return Self::compute(i as u32);
}
if !Self::SPLIT_TABLES {
let p = unsafe { self.data.as_ptr().add((i * 2) as usize) };
return uint128 {
hi: unsafe { *p },
lo: unsafe { *p.add(1) },
};
}
unsafe {
// The caller passes -e - 1 as dec_exp, so ~dec_exp recovers e.
// Picking the base so that e itself is the index lets both loads
// share sxtw addressing.
#[cfg_attr(
not(all(any(target_arch = "x86_64", target_arch = "aarch64"), not(miri))),
allow(unused_mut)
)]
let mut p = self
.data
.as_ptr()
.offset(Self::NUM_POW10S as isize + DEC_EXP_MIN as isize);
#[cfg(all(any(target_arch = "x86_64", target_arch = "aarch64"), not(miri)))]
asm!("/*{0}*/", inout(reg) p);
uint128 {
hi: *p.offset(!(dec_exp as isize)),
lo: *p.offset(!(dec_exp as isize) + Self::NUM_POW10S as isize),
}
}
}
#[cfg(test)]
fn get(&self, dec_exp: i32) -> uint128 {
const DEC_EXP_MIN: i32 = -292;
assert!((DEC_EXP_MIN..DEC_EXP_MIN + Self::NUM_POW10S as i32).contains(&dec_exp));
unsafe { self.get_unchecked(dec_exp) }
}
}
// Computes a shift so that, after scaling by a power of 10, the intermediate
// result always has a fixed 128-bit fractional part (for double).
//
// Different binary exponents can map to the same decimal exponent, but place
// the decimal point at different bit positions. The shift compensates for this.
//
// For example, both 3 * 2**59 and 3 * 2**60 have dec_exp = 2, but dividing by
// 10^dec_exp puts the decimal point in different bit positions:
// 3 * 2**59 / 100 = 1.72...e+16 (needs shift = 1 + 1)
// 3 * 2**60 / 100 = 3.45...e+16 (needs shift = 2 + 1)
#[inline]
const fn compute_exp_shift(bin_exp: i32, dec_exp: i32) -> u8 {
debug_assert!(dec_exp >= -350 && dec_exp <= 350);
// log2_pow10_sig = round(log2(10) * 2**log2_pow10_exp) + 1
const LOG2_POW10_SIG: i32 = 217_707;
const LOG2_POW10_EXP: i32 = 16;
// pow10_bin_exp = floor(log2(10**-dec_exp))
let pow10_bin_exp = (-dec_exp * LOG2_POW10_SIG) >> LOG2_POW10_EXP;
// pow10 = ((pow10_hi << 64) | pow10_lo) * 2**(pow10_bin_exp - 127)
(bin_exp + pow10_bin_exp + 1) as u8
}
struct ExpShiftTable {
data: [u8; if Self::ENABLE {
f64::EXP_MASK as usize + 1
} else {
0
}],
}
impl ExpShiftTable {
const ENABLE: bool = cfg!(not(opt_level = "s"));
// extra_shift must be >= 3 to keep shift non-negative and <= 11 to fit the
// significand into 64 bits after the shift.
const EXTRA_SHIFT: usize = 6;
const fn new() -> Self {
let mut data = [0u8; if Self::ENABLE {
f64::EXP_MASK as usize + 1
} else {
0
}];
let mut raw_exp = 0;
while raw_exp < data.len() && Self::ENABLE {
let mut bin_exp = raw_exp as i32 - f64::EXP_OFFSET;
if raw_exp == 0 {
bin_exp += 1;
}
let dec_exp = compute_dec_exp(bin_exp, true);
data[raw_exp] =
compute_exp_shift(bin_exp, dec_exp + 1).wrapping_add(Self::EXTRA_SHIFT as u8);
raw_exp += 1;
}
ExpShiftTable { data }
}
}
// An optional table of precomputed exponent strings for exponential notation.
// Each entry packs "e+dd" or "e+ddd" into a u64 with the length in byte 7.
struct ExpStringTable {
data: [u64; if Self::ENABLE {
(f64::MAX_10_EXP - Self::MIN_DEC_EXP + 1) as usize
} else {
0
}],
}
impl ExpStringTable {
const ENABLE: bool = cfg!(not(opt_level = "s"));
const MIN_DEC_EXP: i32 = f64::MIN_10_EXP - f64::MAX_DIGITS10 as i32;
const OFFSET: i32 = -Self::MIN_DEC_EXP;
const fn new() -> Self {
let mut data = [0u64; if Self::ENABLE {
(f64::MAX_10_EXP - Self::MIN_DEC_EXP + 1) as usize
} else {
0
}];
let mut e = Self::MIN_DEC_EXP;
while e <= f64::MAX_10_EXP && Self::ENABLE {
let abs_e = e.unsigned_abs() as u64;
let mut val = abs_e % 10 + b'0' as u64;
if abs_e >= 10 {
val = (val << 8) | (abs_e / 10 % 10 + b'0' as u64);
}
if abs_e >= 100 {
val = (val << 8) | (abs_e / 100 + b'0' as u64);
}
let len = 3 + (abs_e >= 10) as u64 + (abs_e >= 100) as u64;
data[(e + Self::OFFSET) as usize] = (len << 48)
| (val << 16)
| (if e >= 0 { b'+' as u64 } else { b'-' as u64 } << 8)
| b'e' as u64;
e += 1;
}
ExpStringTable { data }
}
}
// Shuffle vectors to build strings for exponential notation.
//
// Byte positions in the source register assembled by write_exp_float_simd:
// bytes [0, exp_pos): BCD ASCII digits (reversed)
// bytes [exp_pos, exp_pos + 4): exponent string "e±NN"
// byte last_digit_pos: rounded last digit
// byte point_pos: '.'
//
// The shuffle length (max 14) is stored in byte 15; the corresponding output
// byte is past the string and ignored by the caller.
#[repr(C, align(16))]
struct ExpFloatShuffleTable {
data: [u8; if Self::ENABLE { 32 * 16 } else { 0 }],
}
struct ExpFloatShuffleTableEntry {
#[cfg_attr(
not(any(
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)),
allow(dead_code)
)]
shuffle: *const u8,
length: u8,
}
impl ExpFloatShuffleTable {
const ENABLE: bool = cfg!(any(
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)) && ExpStringTable::ENABLE;
const EXP_POS: u8 = 8;
const LAST_DIGIT_POS: u8 = 12;
const POINT_POS: u8 = 13;
unsafe fn get_entry(
&self,
num_digits: i32,
has_last_digit: bool,
has_extra_digit: bool,
) -> ExpFloatShuffleTableEntry {
let idx = (num_digits - 1) * 4 + i32::from(has_last_digit) * 2 + i32::from(has_extra_digit);
ExpFloatShuffleTableEntry {
shuffle: unsafe { self.data.as_ptr().add(idx as usize * 16) },
length: *unsafe { self.data.get_unchecked(idx as usize * 16 + 15) },
}
}
const fn new() -> Self {
let mut data = [0u8; if Self::ENABLE { 32 * 16 } else { 0 }];
let mut idx = 0;
while idx < 32 && Self::ENABLE {
let num_digits = (idx >> 2) + 1;
let has_last_digit = ((idx >> 1) & 1) != 0;
let has_extra_digit = (idx & 1) != 0;
let out = idx * 16;
let mut i = 0;
while i < 16 {
data[out + i] = 0x80; // shuffle high bit: output 0
i += 1;
}
let leading_digit_pos = if has_extra_digit { 7 } else { 6 };
let mut length = 0;
if has_last_digit {
// Always 8 BCD chars in the significand plus a last-digit char;
// for !has_extra_digit the leading '0' of the 8-digit padded
// BCD is shown.
data[out + length] = leading_digit_pos;
length += 1;
data[out + length] = Self::POINT_POS;
length += 1;
let mut i = leading_digit_pos - 1;
loop {
data[out + length] = i;
length += 1;
if i == 0 {
break;
}
i -= 1;
}
data[out + length] = Self::LAST_DIGIT_POS;
length += 1;
} else {
length = num_digits + has_extra_digit as usize;
// Drop the '.' for single-digit output: "5e+02", not "5.0e+02".
if length == 2 {
length = 1;
}
data[out] = leading_digit_pos;
data[out + 1] = Self::POINT_POS;
let mut i = 2;
while i < length {
data[out + i] = leading_digit_pos + 1 - i as u8;
i += 1;
}
}
let mut i = 0;
while i < 4 {
data[out + length] = Self::EXP_POS + i;
length += 1;
i += 1;
}
data[out + 15] = length as u8;
idx += 1;
}
ExpFloatShuffleTable { data }
}
}
#[cfg(any(
not(any(
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
)),
all(test, target_endian = "little"),
))]
#[cfg_attr(feature = "no-panic", no_panic)]
fn count_trailing_nonzeros(x: u64) -> usize {
// We count the number of bytes until there are only zeros left.
// The code is equivalent to
// 8 - x.leading_zeros() / 8
// but if the BSR instruction is emitted (as gcc on x64 does with default
// settings), subtracting the constant before dividing allows the compiler
// to combine it with the subtraction which it inserts due to BSR counting
// in the opposite direction.
//
// Additionally, the BSR instruction requires a zero check. Since the high
// bit is unused we can avoid the zero check by shifting the datum left by
// one and inserting a sentinel bit at the end. This can be faster than the
// automatically inserted range check.
(70 - ((x.to_le() << 1) | 1).leading_zeros() as usize) / 8
}
// Align data since unaligned access may be slower when crossing a
// hardware-specific boundary.
#[repr(C, align(2))]
struct Digits2([u8; 200]);
static DIGITS2: Digits2 = Digits2(
*b"0001020304050607080910111213141516171819\
2021222324252627282930313233343536373839\
4041424344454647484950515253545556575859\
6061626364656667686970717273747576777879\
8081828384858687888990919293949596979899",
);
// Converts value in the range [0, 100) to a string. GCC generates a bit better
// code when value is pointer-size (https://www.godbolt.org/z/5fEPMT1cc).
#[cfg_attr(feature = "no-panic", no_panic)]
unsafe fn digits2(value: usize) -> &'static u16 {
debug_assert!(value < 100);
#[allow(clippy::cast_ptr_alignment)]
unsafe {
&*DIGITS2.0.as_ptr().cast::().add(value)
}
}
const DIV10K_EXP: i32 = 40;
const DIV10K_SIG: u32 = ((1u64 << DIV10K_EXP) / 10000 + 1) as u32;
const NEG10K: u32 = ((1u64 << 32) - 10000) as u32;
const DIV100_EXP: i32 = 19;
const DIV100_SIG: u32 = (1 << DIV100_EXP) / 100 + 1;
#[cfg(not(all(
target_arch = "x86_64",
target_feature = "sse2",
not(target_feature = "sse4.1"),
not(miri)
)))]
const NEG100: u32 = (1 << 16) - 100;
#[cfg(not(any(
all(target_arch = "x86_64", target_feature = "sse2", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)))]
const DIV10_EXP: i32 = 10;
#[cfg(not(any(
all(target_arch = "x86_64", target_feature = "sse2", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)))]
const DIV10_SIG: u32 = (1 << DIV10_EXP) / 10 + 1;
#[cfg(not(all(target_arch = "x86_64", target_feature = "sse2", not(miri))))]
const NEG10: u32 = (1 << 8) - 10;
const ZEROS: u64 = 0x0101010101010101 * b'0' as u64;
#[repr(C, align(64))]
struct Data {
threshold: AArch64Mem<1_000_000_000_000_000>,
// +6 is needed for boundary cases found by verify.py.
biased_half: AArch64Mem<{ (1 << 63) + 6 }>,
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
mul_const: u64,
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
hundred_million: u64,
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
multipliers32: int32x4_t,
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
multipliers16: int16x8_t,
// Ordered so that the values used to format floats fit in a single cache
// line.
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
div100: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
div10: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
neg100: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
neg10: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
bswap: u128,
#[cfg(all(
target_arch = "x86_64",
target_feature = "sse2",
not(target_feature = "sse4.1"),
not(miri)
))]
hundred: u128,
#[cfg(all(
target_arch = "x86_64",
target_feature = "sse2",
not(target_feature = "sse4.1"),
not(miri)
))]
moddiv10: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
div10k: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
neg10k: u128,
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
zeros: u128,
exp_shifts: ExpShiftTable,
exp_strings: ExpStringTable,
pow10_significands: Pow10SignificandTable,
exp_float_shuffles: ExpFloatShuffleTable,
}
impl Data {
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
const fn splat64(x: u64) -> u128 {
((x as u128) << 64) | x as u128
}
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
const fn splat32(x: u32) -> u128 {
Self::splat64(((x as u64) << 32) | x as u64)
}
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
const fn splat16(x: u16) -> u128 {
Self::splat32(((x as u32) << 16) | x as u32)
}
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
const fn pack8(a: u8, b: u8, c: u8, d: u8, e: u8, f: u8, g: u8, h: u8) -> u64 {
((h as u64) << 56)
| ((g as u64) << 48)
| ((f as u64) << 40)
| ((e as u64) << 32)
| ((d as u64) << 24)
| ((c as u64) << 16)
| ((b as u64) << 8)
| a as u64
}
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
const NEG10K: i32 = 0x10000 - 10000;
}
static STATIC_DATA: Data = Data {
threshold: AArch64Mem::new(),
biased_half: AArch64Mem::new(),
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
mul_const: 0xabcc77118461cefd,
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
hundred_million: 100000000,
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
multipliers32: unsafe {
mem::transmute::<[i32; 4], int32x4_t>([
DIV10K_SIG as i32,
Data::NEG10K,
(DIV100_SIG << 12) as i32,
NEG100 as i32,
])
},
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
multipliers16: unsafe {
mem::transmute::<[i16; 8], int16x8_t>([0xce0, NEG10 as i16, 0, 0, 0, 0, 0, 0])
},
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
div100: Data::splat32(DIV100_SIG),
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
div10: Data::splat16(((1u32 << 16) / 10 + 1) as u16),
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
neg100: Data::splat32(NEG100),
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
neg10: Data::splat16((1 << 8) - 10),
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
bswap: Data::pack8(15, 14, 13, 12, 11, 10, 9, 8) as u128
| (Data::pack8(7, 6, 5, 4, 3, 2, 1, 0) as u128) << 64,
#[cfg(all(
target_arch = "x86_64",
target_feature = "sse2",
not(target_feature = "sse4.1"),
not(miri)
))]
hundred: Data::splat32(100),
#[cfg(all(
target_arch = "x86_64",
target_feature = "sse2",
not(target_feature = "sse4.1"),
not(miri)
))]
moddiv10: Data::splat16(10 * (1 << 8) - 1),
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
div10k: Data::splat64(DIV10K_SIG as u64),
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
neg10k: Data::splat64(NEG10K as u64),
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
zeros: Data::splat64(ZEROS),
exp_shifts: ExpShiftTable::new(),
exp_strings: ExpStringTable::new(),
pow10_significands: Pow10SignificandTable::new(),
exp_float_shuffles: ExpFloatShuffleTable::new(),
};
// Converts four numbers < 10000, one in each 32-bit lane, to BCD digits.
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
#[cfg_attr(feature = "no-panic", no_panic)]
fn to_bcd_4x4(mut efgh_abcd_mnop_ijkl: int32x4_t, d: &Data) -> uint8x16_t {
unsafe {
// Compiler barrier, or clang breaks the subsequent MLA into UADDW +
// MUL.
asm!("/*{:v}*/", inout(vreg) efgh_abcd_mnop_ijkl);
let ef_ab_mn_ij: int32x4_t = vqdmulhq_n_s32(
efgh_abcd_mnop_ijkl,
mem::transmute::(d.multipliers32)[2],
);
let gh_ef_cd_ab_op_mn_kl_ij: int16x8_t = vreinterpretq_s16_s32(vmlaq_n_s32(
efgh_abcd_mnop_ijkl,
ef_ab_mn_ij,
mem::transmute::(d.multipliers32)[3],
));
let high_10s: int16x8_t = vqdmulhq_n_s16(
gh_ef_cd_ab_op_mn_kl_ij,
mem::transmute::(d.multipliers16)[0],
);
vreinterpretq_u8_s16(vmlaq_n_s16(
gh_ef_cd_ab_op_mn_kl_ij,
high_10s,
mem::transmute::(d.multipliers16)[1],
))
}
}
// An optimized version for NEON by Dougall Johnson.
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
#[cfg_attr(feature = "no-panic", no_panic)]
#[inline]
fn to_unshuffled_digits(value: u64, d: &Data) -> uint8x16_t {
let mut hundred_million = d.hundred_million;
// Compiler barrier, or clang narrows the load to 32-bit and unpairs it.
unsafe {
asm!("/*{0}*/", inout(reg) hundred_million);
}
// abcdefgh = value / 100000000, ijklmnop = value % 100000000.
let abcdefgh = (umul128(value, d.mul_const) >> 90) as u64;
let ijklmnop = value - abcdefgh * hundred_million;
unsafe {
let ijklmnop_abcdefgh_64: uint64x1_t =
mem::transmute::((ijklmnop << 32) | abcdefgh);
let abcdefgh_ijklmnop: int32x2_t = vreinterpret_s32_u64(ijklmnop_abcdefgh_64);
let abcd_ijkl: int32x2_t = vreinterpret_s32_u32(vshr_n_u32(
vreinterpret_u32_s32(vqdmulh_n_s32(
abcdefgh_ijklmnop,
mem::transmute::(d.multipliers32)[0],
)),
9,
));
let efgh_abcd_mnop_ijkl_32: int32x2_t = vmla_n_s32(
abcdefgh_ijklmnop,
abcd_ijkl,
mem::transmute::(d.multipliers32)[1],
);
let efgh_abcd_mnop_ijkl: int32x4_t =
vreinterpretq_s32_u32(vshll_n_u16(vreinterpret_u16_s32(efgh_abcd_mnop_ijkl_32), 0));
to_bcd_4x4(efgh_abcd_mnop_ijkl, d)
}
}
// Converts four numbers < 10000, one in each 32-bit lane, to BCD digits.
// Digits in each 32-bit lane will be in order for SSE2, reversed for SSE4.1.
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
#[cfg_attr(feature = "no-panic", no_panic)]
fn to_bcd_4x4(y: __m128i, d: &Data) -> __m128i {
unsafe {
let div100 = _mm_load_si128(ptr::addr_of!(d.div100).cast::<__m128i>());
let div10 = _mm_load_si128(ptr::addr_of!(d.div10).cast::<__m128i>());
#[cfg(target_feature = "sse4.1")]
{
let neg100 = _mm_load_si128(ptr::addr_of!(d.neg100).cast::<__m128i>());
let neg10 = _mm_load_si128(ptr::addr_of!(d.neg10).cast::<__m128i>());
// _mm_mullo_epi32 is SSE 4.1
let z: __m128i = _mm_add_epi64(
y,
_mm_mullo_epi32(neg100, _mm_srli_epi32(_mm_mulhi_epu16(y, div100), 3)),
);
_mm_add_epi64(z, _mm_mullo_epi16(neg10, _mm_mulhi_epu16(z, div10)))
}
#[cfg(not(target_feature = "sse4.1"))]
{
let hundred = _mm_load_si128(ptr::addr_of!(d.hundred).cast::<__m128i>());
let moddiv10 = _mm_load_si128(ptr::addr_of!(d.moddiv10).cast::<__m128i>());
let y_div_100: __m128i = _mm_srli_epi16(_mm_mulhi_epu16(y, div100), 3);
let y_mod_100: __m128i = _mm_sub_epi16(y, _mm_mullo_epi16(y_div_100, hundred));
let z: __m128i = _mm_or_si128(_mm_slli_epi32(y_mod_100, 16), y_div_100);
_mm_sub_epi16(
_mm_slli_epi16(z, 8),
_mm_mullo_epi16(moddiv10, _mm_mulhi_epu16(z, div10)),
)
}
}
}
#[cfg(not(any(
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)))]
struct BcdResult {
bcd: u64,
len: usize,
}
#[cfg(not(any(
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)))]
#[cfg_attr(feature = "no-panic", no_panic)]
fn to_bcd8(abcdefgh: u64) -> BcdResult {
#[cfg(not(all(target_arch = "x86_64", target_feature = "sse2", not(miri))))]
let bcd = {
// An optimization from Xiang JunBo.
// Three steps BCD. Base 10000 -> base 100 -> base 10.
// div and mod are evaluated simultaneously as, e.g.
// (abcdefgh / 10000) << 32 + (abcdefgh % 10000)
// == abcdefgh + (2**32 - 10000) * (abcdefgh / 10000)))
// where the division on the RHS is implemented by the usual multiply + shift
// trick and the fractional bits are masked away.
let abcd_efgh =
abcdefgh + u64::from(NEG10K) * ((abcdefgh * u64::from(DIV10K_SIG)) >> DIV10K_EXP);
let ab_cd_ef_gh = abcd_efgh
+ u64::from(NEG100)
* (((abcd_efgh * u64::from(DIV100_SIG)) >> DIV100_EXP) & 0x7f0000007f);
let a_b_c_d_e_f_g_h = ab_cd_ef_gh
+ u64::from(NEG10)
* (((ab_cd_ef_gh * u64::from(DIV10_SIG)) >> DIV10_EXP) & 0xf000f000f000f);
a_b_c_d_e_f_g_h.to_be()
};
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
let bcd = {
// Load constants from memory.
let mut d = ptr::addr_of!(STATIC_DATA);
let d = unsafe {
asm!("/*{0}*/", inout(reg) d);
&*d
};
// Evaluate the 4-digit limbs and arrange them such that we get a
// result which is in the correct order.
let abcd_efgh = (abcdefgh << 32)
- ((10000u64 << 32) - 1) * ((abcdefgh * u64::from(DIV10K_SIG)) >> DIV10K_EXP);
let v: __m128i = to_bcd_4x4(_mm_set_epi64x(0, abcd_efgh as i64), d);
(unsafe { _mm_cvtsi128_si64(v) }) as u64
};
BcdResult {
bcd,
len: count_trailing_nonzeros(bcd),
}
}
struct DecDigits {
digits: Float::DecDigitsType,
// `unshuffled` is the byte-reversed BCD vector used by write_exp_float_simd.
#[cfg(any(
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
))]
unshuffled: Float::DecUnshuffledType,
num_digits: usize,
}
#[cfg_attr(feature = "no-panic", no_panic)]
#[inline]
fn to_digits_64(value: u64, #[allow(unused_variables)] d: &Data) -> DecDigits {
#[cfg(not(any(
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
all(target_arch = "x86_64", target_feature = "sse2", not(miri)),
)))]
{
let hi = (value / 100_000_000) as u32;
let lo = (value % 100_000_000) as u32;
let hi_bcd = to_bcd8(hi as u64);
if lo == 0 {
return DecDigits {
digits: [hi_bcd.bcd + ZEROS, ZEROS],
num_digits: hi_bcd.len,
};
}
let lo_bcd = to_bcd8(lo as u64);
DecDigits {
digits: [hi_bcd.bcd + ZEROS, lo_bcd.bcd + ZEROS],
num_digits: 8 + lo_bcd.len,
}
}
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
{
unsafe {
let unshuffled_digits = to_unshuffled_digits(value, d);
let digits: uint8x16_t = vrev64q_u8(unshuffled_digits);
let str: uint16x8_t = vaddq_u16(
vreinterpretq_u16_u8(digits),
vreinterpretq_u16_s8(vdupq_n_s8(b'0' as i8)),
);
let is_not_zero: uint16x8_t =
vreinterpretq_u16_u8(vcgtzq_s8(vreinterpretq_s8_u8(digits)));
let nonzero_mask: u64 =
vget_lane_u64(vreinterpret_u64_u8(vshrn_n_u16(is_not_zero, 4)), 0);
DecDigits {
digits: str,
unshuffled: (),
num_digits: 16 - (nonzero_mask.leading_zeros() as usize >> 2),
}
}
}
#[cfg(all(target_arch = "x86_64", target_feature = "sse2", not(miri)))]
{
let hi = (value / 100_000_000) as u32;
let lo = (value % 100_000_000) as u32;
unsafe {
let div10k = _mm_load_si128(ptr::addr_of!(d.div10k).cast::<__m128i>());
let neg10k = _mm_load_si128(ptr::addr_of!(d.neg10k).cast::<__m128i>());
let x: __m128i = _mm_set_epi64x(i64::from(hi), i64::from(lo));
#[cfg_attr(target_feature = "sse4.1", allow(unused_mut))]
let mut y: __m128i = _mm_add_epi64(
x,
_mm_mul_epu32(neg10k, _mm_srli_epi64(_mm_mul_epu32(x, div10k), DIV10K_EXP)),
);
// Shuffle to ensure correctly ordered result from SSE2 path.
#[cfg(not(target_feature = "sse4.1"))]
{
y = _mm_shuffle_epi32(y, _MM_SHUFFLE(0, 1, 2, 3));
}
#[cfg_attr(not(target_feature = "sse4.1"), allow(unused_mut))]
let mut bcd: __m128i = to_bcd_4x4(y, d);
let zeros = _mm_load_si128(ptr::addr_of!(d.zeros).cast::<__m128i>());
// Computed against current bcd (rather than the post-bswap bcd) so
// the mask is derived in parallel with the shuffle on the SSE4.1
// path.
let mask = _mm_movemask_epi8(_mm_cmpgt_epi8(bcd, _mm_setzero_si128())) as u64;
// Trailing zeros are in the low bits for SSE4.1, the high bits for
// SSE2.
let len = if cfg!(target_feature = "sse4.1") {
16 - mask.trailing_zeros()
} else {
64 - mask.leading_zeros()
};
#[cfg(target_feature = "sse4.1")]
{
bcd = _mm_shuffle_epi8(
bcd,
_mm_load_si128(ptr::addr_of!(d.bswap).cast::<__m128i>()),
); // SSSE3
}
DecDigits {
digits: _mm_or_si128(bcd, zeros),
#[cfg(target_feature = "sse4.1")]
unshuffled: (),
num_digits: len as usize,
}
}
}
}
#[cfg_attr(feature = "no-panic", no_panic)]
#[inline]
fn to_digits_32(value: u64, #[allow(unused_variables)] d: &Data) -> DecDigits {
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
{
// Inline to_bcd8's SSE4.1 body so we can return the unshuffled xmm too;
// the exponential-notation path uses it to skip the bswap-via-gpr.
let abcd_efgh = value + u64::from(NEG10K) * ((value * u64::from(DIV10K_SIG)) >> DIV10K_EXP);
let bcd_xmm = to_bcd_4x4(_mm_set_epi64x(0, abcd_efgh as i64), d);
let unshuffled_bcd = unsafe { _mm_cvtsi128_si64(bcd_xmm) } as u64;
let len = if unshuffled_bcd != 0 {
8 - unshuffled_bcd.trailing_zeros() / 8
} else {
0
};
DecDigits {
digits: unshuffled_bcd.swap_bytes() + ZEROS,
unshuffled: bcd_xmm,
num_digits: len as usize,
}
}
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
{
// Inline to_bcd8's NEON body so we can return the unshuffled vector
// too; the exponential-notation path uses it to skip the
// simd->gpr->bswap->simd roundtrip needed to materialize `digits`.
let abcd_efgh = value + u64::from(NEG10K) * ((value * u64::from(DIV10K_SIG)) >> DIV10K_EXP);
let unshuffled: uint8x16_t = unsafe {
let input: int32x4_t =
vcombine_s32(vreinterpret_s32_u64(vcreate_u64(abcd_efgh)), vdup_n_s32(0));
to_bcd_4x4(input, d)
};
let unshuffled_bcd =
unsafe { vget_lane_u64(vreinterpret_u64_u8(vget_low_u8(unshuffled)), 0) };
let len = if unshuffled_bcd != 0 {
8 - unshuffled_bcd.trailing_zeros() / 8
} else {
0
};
DecDigits {
digits: unshuffled_bcd.swap_bytes() + ZEROS,
unshuffled,
num_digits: len as usize,
}
}
#[cfg(not(any(
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)))]
{
let result = to_bcd8(value);
DecDigits {
digits: result.bcd + ZEROS,
num_digits: result.len,
}
}
}
#[cfg_attr(feature = "no-panic", no_panic)]
unsafe fn write_exp_float_simd_32(
buffer: *mut u8,
dig: &DecDigits,
last_digit: i32,
has_last_digit: bool,
has_extra_digit: bool,
exp_data: u64,
d: &Data,
) -> *mut u8 {
// Packed for insertion into lane 1: byte 0 of `tail` lands at register byte
// exp_pos (8), so the exp string fills exp_pos..exp_pos+3; the prefix
// shifts place '0'+last_digit at last_digit_pos (12) and '.' at point_pos
// (13).
let prefix = (u32::from(b'.') << 8) + u32::from(b'0') + last_digit as u32;
#[cfg_attr(
not(any(
all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)),
all(target_arch = "aarch64", target_feature = "neon", not(miri)),
)),
allow(unused_variables)
)]
let tail = exp_data | (u64::from(prefix) << 32);
let entry = unsafe {
d.exp_float_shuffles
.get_entry(dig.num_digits as i32, has_last_digit, has_extra_digit)
};
#[cfg(all(target_arch = "x86_64", target_feature = "sse4.1", not(miri)))]
unsafe {
let ascii: __m128i = _mm_or_si128(
dig.unshuffled,
_mm_load_si128(ptr::addr_of!(d.zeros).cast::<__m128i>()),
);
let src: __m128i = _mm_insert_epi64(ascii, tail as i64, 1);
let shuffle: __m128i = _mm_load_si128(entry.shuffle.cast::<__m128i>());
let out: __m128i = _mm_shuffle_epi8(src, shuffle);
_mm_storeu_si128(buffer.cast::<__m128i>(), out);
}
#[cfg(all(target_arch = "aarch64", target_feature = "neon", not(miri)))]
unsafe {
let ascii: uint8x16_t = vorrq_u8(dig.unshuffled, vdupq_n_u8(b'0'));
let src: uint8x16_t =
vreinterpretq_u8_u64(vsetq_lane_u64(tail, vreinterpretq_u64_u8(ascii), 1));
let shuffle: uint8x16_t = vld1q_u8(entry.shuffle);
let out: uint8x16_t = vqtbl1q_u8(src, shuffle);
vst1q_u8(buffer, out);
}
let length = entry.length as usize - usize::from((exp_data & 0xff000000) == 0);
unsafe { buffer.add(length) }
}
struct ToDecimalResult {
sig: i64,
exp: i32,
last_digit: u8,
has_last_digit: bool,
}
// Here be 🐉s.
// Converts a binary FP number bin_sig * 2**bin_exp to the shortest decimal
// representation, where bin_exp = raw_exp - exp_offset.
#[cfg_attr(feature = "no-panic", no_panic)]
#[inline]
fn to_decimal(bin_sig: UInt, raw_exp: i64, regular: bool, d: &Data) -> ToDecimalResult
where
Float: FloatTraits,
UInt: traits::UInt,
{
let bin_exp = raw_exp - i64::from(Float::EXP_OFFSET);
let num_bits = mem::size_of::() as i32 * 8;
const EXTRA_SHIFT: usize = ExpShiftTable::EXTRA_SHIFT;
if !regular {
let dec_exp = compute_dec_exp(bin_exp as i32, false);
let shift = compute_exp_shift(bin_exp as i32, dec_exp + 1).wrapping_add(EXTRA_SHIFT as u8);
let pow10 = unsafe { d.pow10_significands.get_unchecked(-dec_exp - 1) };
let p = umul192_hi128(pow10.hi, pow10.lo, (bin_sig << shift).into());
let mut integral = p.hi >> EXTRA_SHIFT;
let fractional = (p.hi << (64 - EXTRA_SHIFT)) | (p.lo >> EXTRA_SHIFT);
let half_ulp = pow10.hi >> (EXTRA_SHIFT + 1 - shift as usize);
let round_up = half_ulp > u64::MAX - fractional;
let round_down = (half_ulp >> 1) > fractional;
integral += u64::from(round_up);
let mut digit = umul128_add_hi64(fractional, 10, (1 << 63) - 1) as i32;
let lo = umul128_add_hi64(fractional.wrapping_sub(half_ulp >> 1), 10, !0) as i32;
if digit < lo {
digit = lo;
}
return ToDecimalResult {
sig: integral as i64,
exp: dec_exp,
last_digit: digit as u8,
has_last_digit: !(round_up || round_down),
};
}
const LOG10_2_SIG: u64 = 78_913;
const LOG10_2_EXP: i32 = 18;
#[allow(unused_mut)]
let mut dec_exp = if USE_UMUL128_HI64 {
umul128_hi64(bin_exp as u64, LOG10_2_SIG << (64 - LOG10_2_EXP)) as i32
} else {
compute_dec_exp(bin_exp as i32, true)
};
#[cfg(not(miri))]
#[allow(unused_unsafe)]
unsafe {
// Force 32-bit reg for sxtw addressing.
#[cfg(target_arch = "x86_64")]
asm!("/*{0:e}*/", inout(reg) dec_exp);
#[cfg(target_arch = "aarch64")]
asm!("/*{0:w}*/", inout(reg) dec_exp);
}
let mut shift = if ExpShiftTable::ENABLE {
*unsafe {
d.exp_shifts
.data
.get_unchecked((bin_exp + i64::from(f64::EXP_OFFSET)) as usize)
}
} else {
compute_exp_shift(bin_exp as i32, dec_exp + 1).wrapping_add(EXTRA_SHIFT as u8)
};
let even = UInt::from(1) - (bin_sig & UInt::from(1));
if num_bits == 32 {
const EXTRA_SHIFT: usize = 34;
shift += (EXTRA_SHIFT - ExpShiftTable::EXTRA_SHIFT) as u8;
let pow10_hi = unsafe { d.pow10_significands.get_unchecked(-dec_exp - 1) }.hi;
let p = umul128_hi64(pow10_hi + 1, bin_sig.into() << shift);
let mut integral = p >> EXTRA_SHIFT;
let fractional = p & ((1u64 << EXTRA_SHIFT) - 1);
let half_ulp = (pow10_hi >> (65 - shift as usize)) + even.into();
let round_up = ((fractional + half_ulp) >> EXTRA_SHIFT) != 0;
let round_down = half_ulp > fractional;
integral += u64::from(round_up);
let mut digit = ((fractional * 10 + (1u64 << (EXTRA_SHIFT - 1))) >> EXTRA_SHIFT) as i32;
if fractional == (1u64 << (EXTRA_SHIFT - 2)) {
digit = 2; // Round 2.5 to 2.
}
return ToDecimalResult {
sig: integral as i64,
exp: dec_exp,
last_digit: digit as u8,
has_last_digit: !(round_up || round_down),
};
}
// An optimization by Xiang JunBo:
// Scale by 10**(-dec_exp-1) to directly produce the shorter candidate
// (15-16 digits), deriving the extra digit from the fractional part.
// This eliminates div10 from the critical path.
//
// value = 5.0507837461e-27
// next = 5.0507837461000010e-27
//
// c = integral.fractional' = 5050783746100000.3153987... (value)
// 5050783746100001.0328635... (next)
// half_ulp = 0.3587324...
//
// fractional = fractional' * 2**64 = 5818079786399166407
//
// 5050783746100000.0 c upper 5050783746100001.0
// s l| L | S
// ──┬────┬────┼────┬────┬────┼*───┼────┬────┬───*┬────┬────┬────┼─*──┬───
// .8 .9 .0 .1 .2 .3 .4 .5 .6 .7 .8 .9 .0 | .1
// └─────────────────┼─────────────────┘ next
// 1ulp
//
// s - shorter underestimate, S - shorter overestimate
// l - longer underestimate, L - longer overestimate
let pow10 = unsafe { d.pow10_significands.get_unchecked(-dec_exp - 1) };
let p = umul192_hi128(pow10.hi, pow10.lo, (bin_sig << shift).into());
let mut integral = p.hi >> EXTRA_SHIFT;
let fractional = (p.hi << (64 - EXTRA_SHIFT)) | (p.lo >> EXTRA_SHIFT);
let half_ulp = (pow10.hi >> (EXTRA_SHIFT + 1 - shift as usize)) + even.into();
let round_up = fractional.wrapping_add(half_ulp) < fractional;
let round_down = half_ulp > fractional;
integral += u64::from(round_up); // Compute integral before digit.
// Derive the extra digit from the fractional part (parallel with rounding).
let mut digit = umul128_add_hi64(fractional, 10, d.biased_half.get()) as i32;
if fractional == (1u64 << 62) {
digit = 2; // Round 2.5 to 2.
}
ToDecimalResult {
sig: integral as i64,
exp: dec_exp,
last_digit: digit as u8,
has_last_digit: !(round_up || round_down),
}
}
/// Writes the shortest correctly rounded decimal representation of `value` to
/// `buffer`. `buffer` should point to a buffer of size `buffer_size` or larger.
#[cfg_attr(feature = "no-panic", no_panic)]
unsafe fn write(value: Float, mut buffer: *mut u8) -> *mut u8
where
Float: FloatTraits,
{
let bits = value.to_bits();
// It is beneficial to extract exponent and significand early.
let bin_exp = Float::get_exp(bits); // binary exponent
let bin_sig = Float::get_sig(bits); // binary significand
unsafe {
*buffer = b'-';
}
buffer = unsafe { buffer.add(usize::from(Float::is_negative(bits))) };
#[allow(unused_mut)]
let mut d = ptr::addr_of!(STATIC_DATA);
let d = unsafe {
// Load constants from memory.
#[cfg(all(any(target_arch = "aarch64", target_arch = "x86_64"), not(miri)))]
asm!("/*{0}*/", inout(reg) d);
&*d
};
let threshold = if Float::NUM_BITS == 64 {
d.threshold.get()
} else {
10_000_000
};
let mut dec;
if bin_exp == 0 {
if bin_sig == Float::SigType::from(0) {
return unsafe {
*buffer = b'0';
*buffer.add(1) = b'.';
*buffer.add(2) = b'0';
buffer.add(3)
};
}
dec = to_decimal::(bin_sig, 1, true, d);
let mut dec_sig =
dec.sig * 10 + (-i64::from(dec.has_last_digit) & i64::from(dec.last_digit));
let mut dec_exp = dec.exp;
while dec_sig < threshold as i64 {
dec_sig *= 10;
dec_exp -= 1;
}
let d = div10(dec_sig as u64);
let last_digit = dec_sig - d as i64 * 10;
dec = ToDecimalResult {
sig: d as i64,
exp: dec_exp,
last_digit: last_digit as u8,
has_last_digit: last_digit != 0,
};
} else {
dec = to_decimal::(
bin_sig | Float::IMPLICIT_BIT,
bin_exp,
bin_sig != Float::SigType::from(0),
d,
);
}
let mut has_last_digit = dec.has_last_digit;
let has_extra_digit = dec.sig >= threshold as i64;
let mut dec_exp = dec.exp + Float::MAX_DIGITS10 as i32 - 2 + i32::from(has_extra_digit);
if Float::NUM_BITS == 32 && dec.sig < 1_000_000 {
dec.sig = 10 * dec.sig + (-i64::from(has_last_digit) & i64::from(dec.last_digit));
has_last_digit = false;
dec_exp -= 1;
}
// Write significand.
let dig = Float::to_digits(dec.sig as u64, d);
if Float::NUM_BITS == 32
&& ExpFloatShuffleTable::ENABLE
&& !Float::FIXED_DEC_EXP.contains(&dec_exp)
{
unsafe {
let exp_data = *d
.exp_strings
.data
.get_unchecked((dec_exp + ExpStringTable::OFFSET) as usize);
return Float::write_exp_float_simd(
buffer,
&dig,
i32::from(dec.last_digit),
has_last_digit,
has_extra_digit,
exp_data,
d,
);
}
}
let bcd_size = if Float::NUM_BITS == 64 { 16 } else { 8 };
unsafe {
buffer
.add(usize::from(has_extra_digit))
.cast::()
.write_unaligned(dig.digits);
buffer
.add(usize::from(has_extra_digit) + bcd_size)
.write(b'0' + dec.last_digit);
}
let length = usize::from(has_extra_digit)
+ if has_last_digit {
bcd_size + 1
} else {
dig.num_digits
}
- 1;
if Float::FIXED_DEC_EXP.contains(&dec_exp) {
if length as i32 - 1 <= dec_exp {
// 1234e7 -> 12340000000.0
return unsafe {
ptr::copy(buffer.add(1), buffer, length);
ptr::write_bytes(buffer.add(length), b'0', dec_exp as usize + 3 - length);
*buffer.add(dec_exp as usize + 1) = b'.';
buffer.add(dec_exp as usize + 3)
};
} else if 0 <= dec_exp {
// 1234e-2 -> 12.34
return unsafe {
ptr::copy(buffer.add(1), buffer, dec_exp as usize + 1);
*buffer.add(dec_exp as usize + 1) = b'.';
buffer.add(length + 1)
};
} else {
// 1234e-6 -> 0.001234
return unsafe {
ptr::copy(buffer.add(1), buffer.add((1 - dec_exp) as usize), length);
ptr::write_bytes(buffer, b'0', (1 - dec_exp) as usize);
*buffer.add(1) = b'.';
buffer.add((1 - dec_exp) as usize + length)
};
}
}
unsafe {
// 1234e30 -> 1.234e33
*buffer = *buffer.add(1);
*buffer.add(1) = b'.';
}
buffer = unsafe { buffer.add(length + usize::from(length > 1)) };
// Write exponent.
if ExpStringTable::ENABLE {
let mut exp_data = unsafe {
*d.exp_strings
.data
.get_unchecked((dec_exp + ExpStringTable::OFFSET) as usize)
};
let len = (exp_data >> 48) as usize;
exp_data = exp_data.to_le();
unsafe {
ptr::copy_nonoverlapping(
ptr::addr_of!(exp_data).cast::(),
buffer,
if Float::MAX_10_EXP >= 100 { 5 } else { 4 },
);
return buffer.add(len);
}
}
let sign_ptr = buffer;
let e_sign = if dec_exp >= 0 {
(u16::from(b'+') << 8) | u16::from(b'e')
} else {
(u16::from(b'-') << 8) | u16::from(b'e')
};
buffer = unsafe { buffer.add(1) };
dec_exp = if dec_exp >= 0 { dec_exp } else { -dec_exp };
buffer = unsafe { buffer.add(usize::from(dec_exp >= 10)) };
if Float::MAX_10_EXP >= 100 {
// digit = dec_exp / 100
let digit = if USE_UMUL128_HI64 {
umul128_hi64(dec_exp as u64, 0x290000000000000) as u32
} else {
(dec_exp as u32 * DIV100_SIG) >> DIV100_EXP
};
unsafe {
*buffer = b'0' + digit as u8;
}
buffer = unsafe { buffer.add(usize::from(dec_exp >= 100)) };
dec_exp -= (digit * 100) as i32;
}
unsafe {
buffer
.cast::()
.write_unaligned(*digits2(dec_exp as usize));
sign_ptr.cast::().write_unaligned(e_sign.to_le());
buffer.add(2)
}
}
/// Safe API for formatting floating point numbers to text.
///
/// ## Example
///
/// ```
/// let mut buffer = zmij::Buffer::new();
/// let printed = buffer.format_finite(1.234);
/// assert_eq!(printed, "1.234");
/// ```
pub struct Buffer {
bytes: [MaybeUninit; BUFFER_SIZE],
}
impl Buffer {
/// This is a cheap operation; you don't need to worry about reusing buffers
/// for efficiency.
#[inline]
#[cfg_attr(feature = "no-panic", no_panic)]
pub fn new() -> Self {
let bytes = [MaybeUninit::::uninit(); BUFFER_SIZE];
Buffer { bytes }
}
/// Print a floating point number into this buffer and return a reference to
/// its string representation within the buffer.
///
/// # Special cases
///
/// This function formats NaN as the string "NaN", positive infinity as
/// "inf", and negative infinity as "-inf" to match std::fmt.
///
/// If your input is known to be finite, you may get better performance by
/// calling the `format_finite` method instead of `format` to avoid the
/// checks for special cases.
#[cfg_attr(feature = "no-panic", no_panic)]
pub fn format(&mut self, f: F) -> &str {
if f.is_nonfinite() {
f.format_nonfinite()
} else {
self.format_finite(f)
}
}
/// Print a floating point number into this buffer and return a reference to
/// its string representation within the buffer.
///
/// # Special cases
///
/// This function **does not** check for NaN or infinity. If the input
/// number is not a finite float, the printed representation will be some
/// correctly formatted but unspecified numerical value.
///
/// Please check [`is_finite`] yourself before calling this function, or
/// check [`is_nan`] and [`is_infinite`] and handle those cases yourself.
///
/// [`is_finite`]: f64::is_finite
/// [`is_nan`]: f64::is_nan
/// [`is_infinite`]: f64::is_infinite
#[cfg_attr(feature = "no-panic", no_panic)]
pub fn format_finite(&mut self, f: F) -> &str {
unsafe {
let end = f.write_to_zmij_buffer(self.bytes.as_mut_ptr().cast::());
let len = end.offset_from(self.bytes.as_ptr().cast::()) as usize;
let slice = slice::from_raw_parts(self.bytes.as_ptr().cast::(), len);
str::from_utf8_unchecked(slice)
}
}
}
/// A floating point number, f32 or f64, that can be written into a
/// [`zmij::Buffer`][Buffer].
///
/// This trait is sealed and cannot be implemented for types outside of the
/// `zmij` crate.
#[allow(unknown_lints)] // rustc older than 1.74
#[allow(private_bounds)]
pub trait Float: private::Sealed {}
impl Float for f32 {}
impl Float for f64 {}
mod private {
pub trait Sealed: crate::traits::Float {
fn is_nonfinite(self) -> bool;
fn format_nonfinite(self) -> &'static str;
unsafe fn write_to_zmij_buffer(self, buffer: *mut u8) -> *mut u8;
}
impl Sealed for f32 {
#[inline]
fn is_nonfinite(self) -> bool {
const EXP_MASK: u32 = 0x7f800000;
let bits = self.to_bits();
bits & EXP_MASK == EXP_MASK
}
#[cold]
#[cfg_attr(feature = "no-panic", inline)]
fn format_nonfinite(self) -> &'static str {
const MANTISSA_MASK: u32 = 0x007fffff;
const SIGN_MASK: u32 = 0x80000000;
let bits = self.to_bits();
if bits & MANTISSA_MASK != 0 {
crate::NAN
} else if bits & SIGN_MASK != 0 {
crate::NEG_INFINITY
} else {
crate::INFINITY
}
}
#[cfg_attr(feature = "no-panic", inline)]
unsafe fn write_to_zmij_buffer(self, buffer: *mut u8) -> *mut u8 {
unsafe { crate::write(self, buffer) }
}
}
impl Sealed for f64 {
#[inline]
fn is_nonfinite(self) -> bool {
const EXP_MASK: u64 = 0x7ff0000000000000;
let bits = self.to_bits();
bits & EXP_MASK == EXP_MASK
}
#[cold]
#[cfg_attr(feature = "no-panic", inline)]
fn format_nonfinite(self) -> &'static str {
const MANTISSA_MASK: u64 = 0x000fffffffffffff;
const SIGN_MASK: u64 = 0x8000000000000000;
let bits = self.to_bits();
if bits & MANTISSA_MASK != 0 {
crate::NAN
} else if bits & SIGN_MASK != 0 {
crate::NEG_INFINITY
} else {
crate::INFINITY
}
}
#[cfg_attr(feature = "no-panic", inline)]
unsafe fn write_to_zmij_buffer(self, buffer: *mut u8) -> *mut u8 {
unsafe { crate::write(self, buffer) }
}
}
}
impl Default for Buffer {
#[inline]
#[cfg_attr(feature = "no-panic", no_panic)]
fn default() -> Self {
Buffer::new()
}
}